








Introduction
This is the second blog post in a two-part series on Multi-Agent Multimodal Data Analysis. In Part 1, we established the data foundation by ingesting multimodal data into AWS purpose-built healthcare and life sciences (HCLS) services and generating a unified, governed data catalog using Amazon SageMaker Unified Studio. We also created interactive dashboards to visualize multimodal data across individual patients and cohorts using Amazon Quick.
In this post, we build on that foundation by constructing specialized AI agents for each data modality along with a supervisor agent that orchestrates cross-modal analysis using Amazon Bedrock AgentCore and Strands Agents SDK. We also train predictive AI models with Amazon SageMaker AI to predict patient outcomes from multimodal features. To further explore the implementation details and get hands-on experience, refer to the accompanying code repository.
Multi-agent orchestration
While HCLS data continues to grow across modalities, existing pipelines for multimodal data analysis are often rigid, difficult to adapt for ad-hoc cross-modality queries and require domain expertise for each modality. A multi-agent approach can address these limitations by building specialized AI agents for each data modality with domain-specific knowledge and tools. A supervisor agent orchestrates these specialized agents, determining which agents to invoke and how to synthesize their outputs based on the context of the user’s question.
Build specialized agents with Bedrock AgentCore and Strands SDK
Amazon Bedrock AgentCore is a managed platform for building, deploying, and operating AI agents at scale, handling compute, session management, security isolation, and observability. It natively integrates with Bedrock Guardrails, handles memory management for multi-turn conversations and tracing for auditing agent reasoning, which are particularly relevant for HCLS workloads. Strands Agents SDK is an open-source Software Development Kit (SDK) for building and running AI agents using a model-driven approach that can reason, plan, and invoke actions based on a defined prompt and set of tools. We leverage this service to build a multi-agent system where each specialized agent incorporates its specific domain knowledge and connects to its respective data store via Model Context Protocol (MCP) servers, as shown in Figure 1.
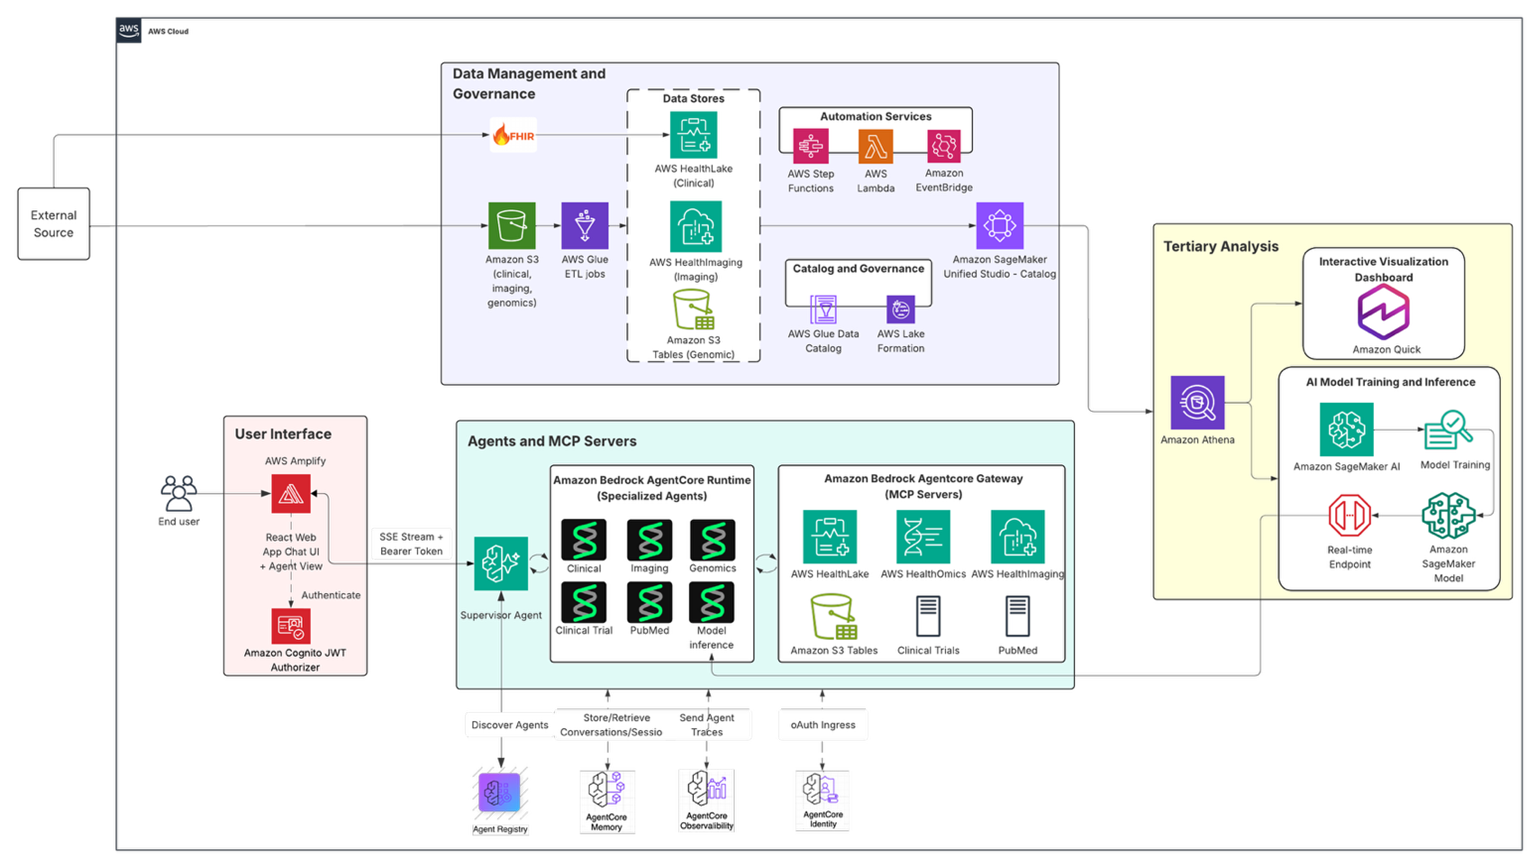
Figure 1: End-to-end architecture showing multi-agent multimodal data analysis on AWS. Clinical, imaging, and genomic data are stored in purpose-built services (HealthLake, HealthImaging, S3 Tables) and governed via Amazon SageMaker Unified Studio. Specialized agents built with Amazon Bedrock AgentCore perform cross-modal synthesis via MCP Servers, coordinated by a supervisor agent. Downstream tertiary analysis leverages Amazon Athena, QuickSight, and SageMaker AI for querying, visualization, and model training and inference.
Clinical trials agent
The clinical trials agent helps researchers and clinicians discover relevant studies that may inform patient care or recruitment decisions. We surface ClinicalTrials.gov as a tool through Amazon Bedrock AgentCore Gateway, which converts the v2 REST API into an MCP-compatible endpoint without requiring a custom integration layer. Gateway manages authentication and rate limiting, so the agent can directly query for studies in RECRUITING status and receive structured fields it reasons over: study title, sponsoring organization, start and completion dates, eligibility criteria, primary outcomes, and a summary. Because the tool is served through a single managed endpoint, it remains independently versioned and reusable by other agents in the system without duplicating integration logic.
We build the agent with the Strands Agents SDK, scope its system prompt to clinical trial discovery, and attach a short-term memory hook backed by Amazon Bedrock AgentCore Memory so that follow-up questions stay grounded in prior context. We wrap the agent in an A2A (Agent-to-Agent) server for discovery and invocation by the supervisor agent, as described in the Supervisor Agent section.
PubMed agent
The PubMed agent searches the PubMed database (38+ million citations from MEDLINE, life sciences journals, and online books) and returns titles, publication dates, abstracts, and direct links to source articles, enabling the supervisor to ground its answers in peer-reviewed evidence. We expose NCBI’s E-utilities (esearch and efetch) through Amazon Bedrock AgentCore Gateway, which converts the REST API into an MCP-compatible endpoint and handles rate limiting automatically. It parses the returned XML and normalizes results into compact dictionaries. The agent is intentionally thin, consisting of a scoped system prompt, the MCP-discovered search_pubmed tool, and the same short-term memory hook used by the other specialized agents. Separating PubMed and clinical trials into distinct agents gives us clearer responsibilities, independent scaling, and parallel querying when a question spans both sources.
Clinical agent
The clinical agent provides the supervisor with access to clinical data stored in AWS HealthLake in FHIR R4 format. We connect this agent to the AWS HealthLake MCP server, an open-source MCP server that exposes tools for searching FHIR resources and performing operations across resource types, including patient, condition, encounter, observation, and medication request. For example, when a user asks about a patient’s medication history or active diagnoses, the supervisor invokes the clinical agent, which queries HealthLake through the MCP server and returns a structured summary of the relevant clinical data. We build this agent with the Strands Agents SDK, configure its system prompt with clinical informatics domain knowledge, and register it as an A2A server so the supervisor can discover and invoke it at runtime.
Genomic agent
The genomic agent enables the supervisor to query patient-level variant data and genomic annotations stored in Amazon S3 Tables in Apache Iceberg format. It connects to the S3 Tables MCP server, which provides tools to query managed Iceberg tables using natural language, retrieve table metadata, and execute filtered reads against the variant and annotation tables. When the supervisor routes a genomic question, such as looking up gene-disease associations from ClinVar annotations, the genomic agent invokes the appropriate S3 Tables MCP server tools, retrieves the relevant records, and returns a structured interpretation of the variant data. We build this with the Strands Agents SDK, give a system prompt scoped to genomic variant interpretation, and wrap in an A2A server. To extend this pattern for omics workflow management, execution, and analysis, you can create an omics agent that connects to the AWS HealthOmics MCP server using the same approach.
Imaging agent
The imaging agent gives the supervisor access to medical imaging data stored in AWS HealthImaging, a purpose-built service for storing, accessing, and analyzing DICOM data at petabyte scale. We connect it to the AWS HealthImaging MCP server, which provides tools for searching image sets, retrieving DICOM metadata and pixel data frames, and listing imaging data stores. We build this agent using the same Strands Agents SDK and A2A registration pattern, with a system prompt tailored to medical imaging terminology and DICOM data interpretation.
Supervisor agent for multi-agent orchestration
The supervisor agent is the entry point for end-user interaction. Rather than querying data sources directly, it interprets the user’s intent, routes queries to appropriate specialized agents, and synthesizes their outputs into a coherent answer, keeping domain expertise encapsulated in each agent while concentrating cross-modality reasoning in one place. We build it with the Strands Agents SDK and give it one async tool per specialized agent (e.g., send_pubmed_a2a_message, send_healthlake_a2a_message) that communicates over A2A protocol. For each call, the supervisor authenticates with Amazon Cognito and communicates over A2A protocol, using cached agent cards, a shared HTTP/2 client, and asyncio.timeout to minimize latency and prevent stalls.
The supervisor is hosted on Amazon Bedrock AgentCore using the BedrockAgentCoreApp entrypoint, which supports streaming responses, session management, and integrated tracing. To add a new specialized agent, deploy it as a separate AgentCore runtime with A2A enabled, register a new tool on the supervisor pointing to its Amazon Resource Name (ARN), and update the system prompt.
Deploy agents on Amazon Bedrock AgentCore
We package and deploy each agent using agentcore-cli, specifying the agent’s entry point, IAM role, protocol (A2A for specialized agents, MCP for tool servers), and a Cognito User Pool as the JSON web token (JWT) authorizer to authenticate every invocation. AgentCore handles compute, container builds, autoscaling, session isolation, and observability, so you can focus on agent logic rather than operational overhead. Environment variables wire each agent to its dependencies at deploy time (MCP server ARNs, memory IDs, Cognito credentials), keeping secrets out of source code and enabling environment promotion through configuration alone. Each MCP server is deployed as a separate AgentCore runtime, giving us isolated, independently scalable tool endpoints that any agent can connect to over standard MCP transport. The result is a fleet of single-purpose runtimes, each independently deployable, observable through Amazon CloudWatch, and protected behind Cognito-issued JWTs.
User interface to interact with agents
We build a React-based web application hosted on AWS Amplify that gives end users a conversational chat interface to the multi-agent system. They can ask natural-language questions about patients, literature, clinical trials, disease predictions, and see the supervisor agent’s reasoning in real time as it delegates to specialized agents. The application also includes an agent architecture view that visualizes the multi-agent hierarchy and data source connections, giving users a clear mental model of how their queries are decomposed across agents. As shown in Figure 2, users authenticate through Amazon Cognito via the Amplify Authenticator component, ensuring that only authorized healthcare professionals can access the system.
For deeper observability and debugging beyond the UI’s inline tool display, AgentCore provides built-in tracing and OpenTelemetry support that captures comprehensive agent reasoning, tool invocations, and multi-agent call chains for developers. Since the application communicates directly with the AgentCore runtime endpoint using the Cognito-issued bearer token, no additional backend API layer is required between the browser and the agents, which simplifies the architecture and reduces latency.
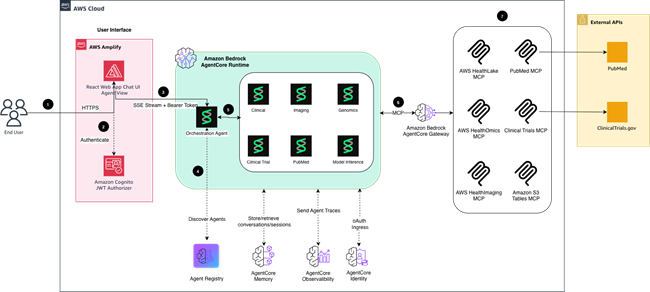
Figure 2: Architecture of multi-agent orchestration with specialized agents. End users connect via AWS Amplify (React) and authenticate through Amazon Cognito. An Orchestration Agent within Amazon Bedrock AgentCore Runtime routes user queries to specialized agents (clinical, genomics, imaging, clinical trial, PubMed, and model inference), which connect to corresponding MCP Servers via the AgentCore Gateway. AgentCore services (memory, observability, identity, agent registry) manage agent lifecycle, while external APIs (PubMed, ClinicalTrials.gov) provide supplementary research data.
Predictive Analytics
Predictive analytics extends the multi-agent system by identifying patients at elevated risk for specific diseases. In this section, we add a model inference agent that serves a predictive model as a tool the supervisor can invoke. The model is trained on combined clinical, imaging, and genomic features following the approach described in our previous blog, where we show that combining modalities improves predictive performance over any single modality alone.
Model inference agent with Amazon SageMaker AI
The model inference agent takes the multi-agent system beyond data retrieval into predictive analytics, giving the supervisor agent access to disease-risk predictions for patients in the cardiovascular cohort. It exposes a prediction tool backed by an Amazon SageMaker AI real-time endpoint. Given a disease and patient ID, the tool assembles that patient’s multimodal feature vector, invokes the endpoint, and returns the predicted probability, the top contributing features, and a disclaimer that the predictions use synthetic data and are not for clinical use. For example, when a user asks whether a patient is at elevated risk of stroke, the supervisor routes the question to the model inference agent, which returns the risk estimate along with the features driving it so the finding can be interpreted alongside the patient’s clinical, imaging, and genomic context.
For each disease, we train a single AutoGluon tabular model, an AutoML ensemble offered by Amazon SageMaker AI, that stacks classical learners and handles mixed clinical, imaging, and genomic features without manual tuning. We package the trained model as a SageMaker bring-your-own-container image, build it with AWS CodeBuild, and deploy it as a real-time endpoint that loads its per-disease artifact from Amazon S3 on first request. Following the principle of least privilege, the agent’s IAM role grants sagemaker:InvokeEndpoint only on the deployed endpoint ARNs and read-only access to the preprocessed feature data in Amazon S3 from Part 1.
We build the agent with the Strands Agents SDK, scope its system prompt to disease-risk prediction and the safe communication of probabilistic results, and register it as an A2A server so the supervisor can discover and invoke it at runtime, following the same pattern as the other specialized agents. Because the prediction tool is decoupled from the underlying endpoints, we can retrain models or add new disease targets without changing the interface the supervisor depends on.
Conclusion and next steps
In this two-part series, we showed how to build an end-to-end multimodal data analysis framework on AWS, from ingesting and governing HCLS data across clinical, imaging, and genomic modalities, to constructing specialized AI agents, orchestrating them through a supervisor agent on Amazon Bedrock AgentCore, and serving predictive models with Amazon SageMaker AI. This enables natural-language querying across data silos, cross-modal synthesis, and disease risk prediction, all within a governed, scalable architecture. To get started, explore the accompanying code repository and adapt the patterns to your own multimodal data analysis workflows.