


Modular is growing! We've opened offices in two cities with deep ties to the work we do.
Our new Edinburgh office is based at the Bayes Centre, the University of Edinburgh's hub for data science and AI. Researchers, students, and businesses share the building, working to turn AI and data science into practical solutions for industry and society.
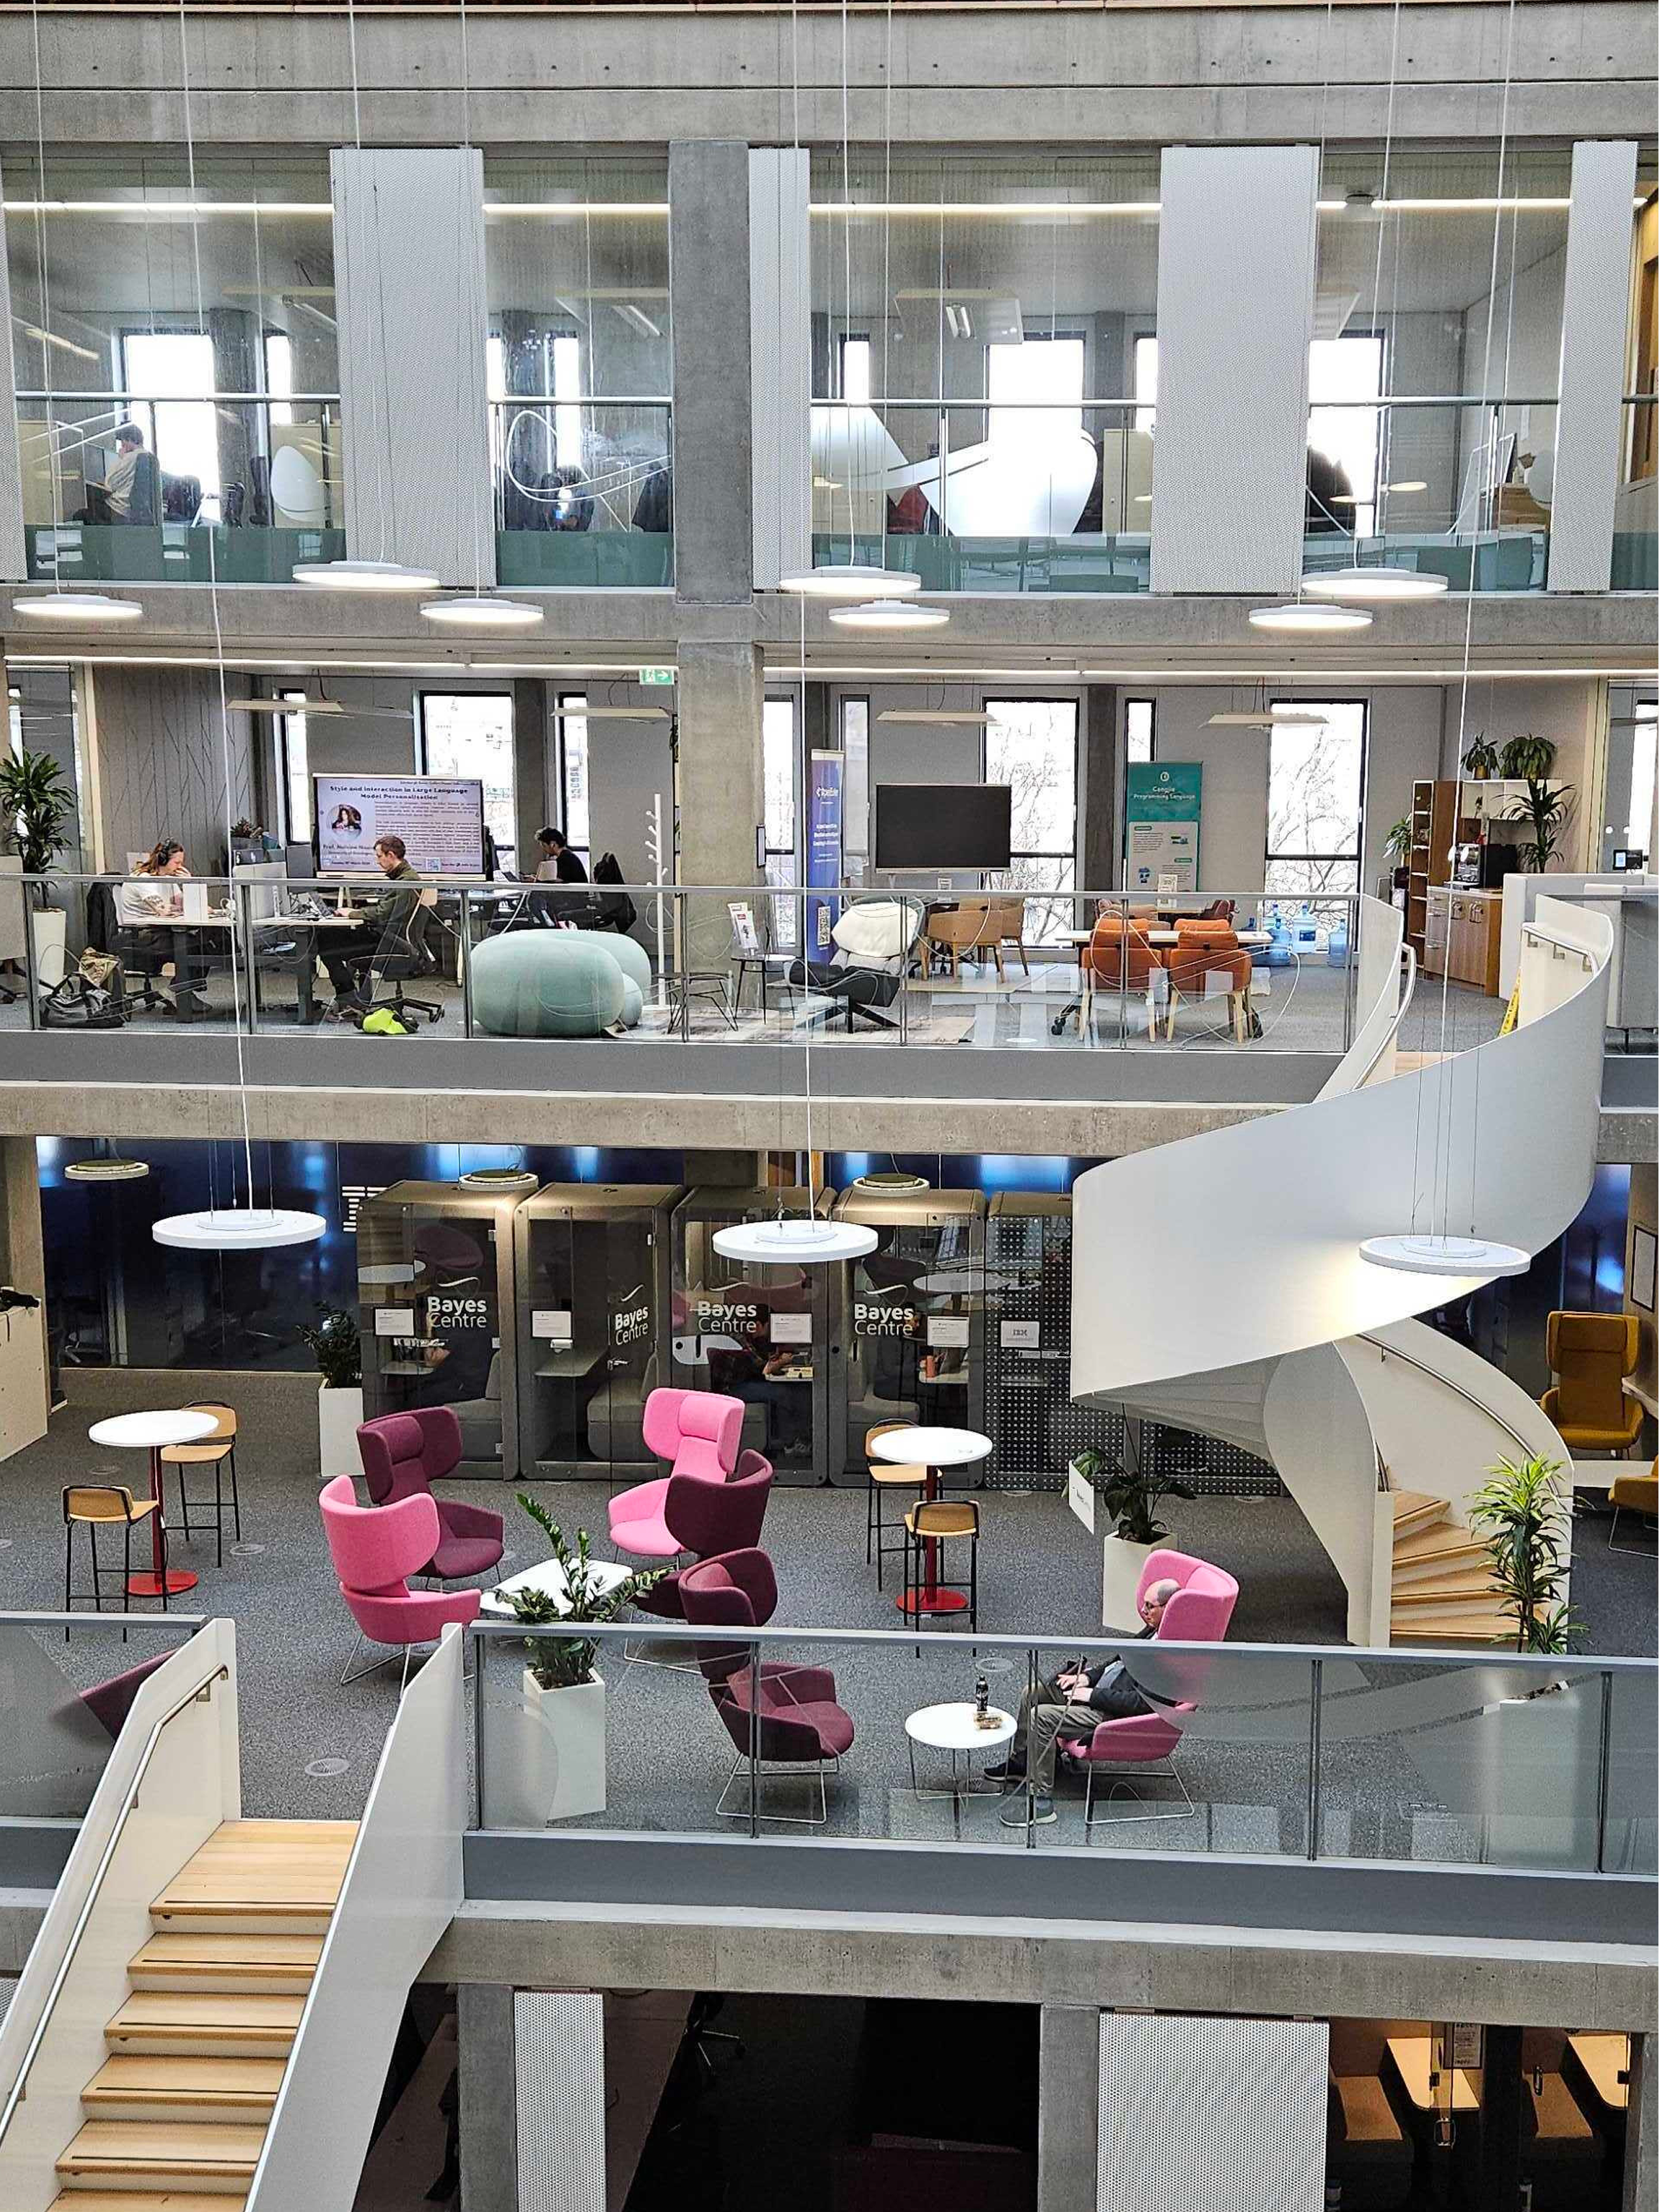
Edinburgh is a natural home for Modular. The city has deep roots in computer science, compilers, and programming language research, the disciplines that define what we build. The University of Edinburgh's School of Informatics is one of the largest and most respected CS departments in Europe, and the broader Scottish AI community has produced foundational work in machine learning, natural language processing, and systems engineering.
The Bayes Centre puts us in the middle of that community. It houses AI-focused companies alongside researchers and programs like the AI Accelerator and Venture Builder Incubator, all in one building. That proximity to active research and emerging talent is why we chose it.
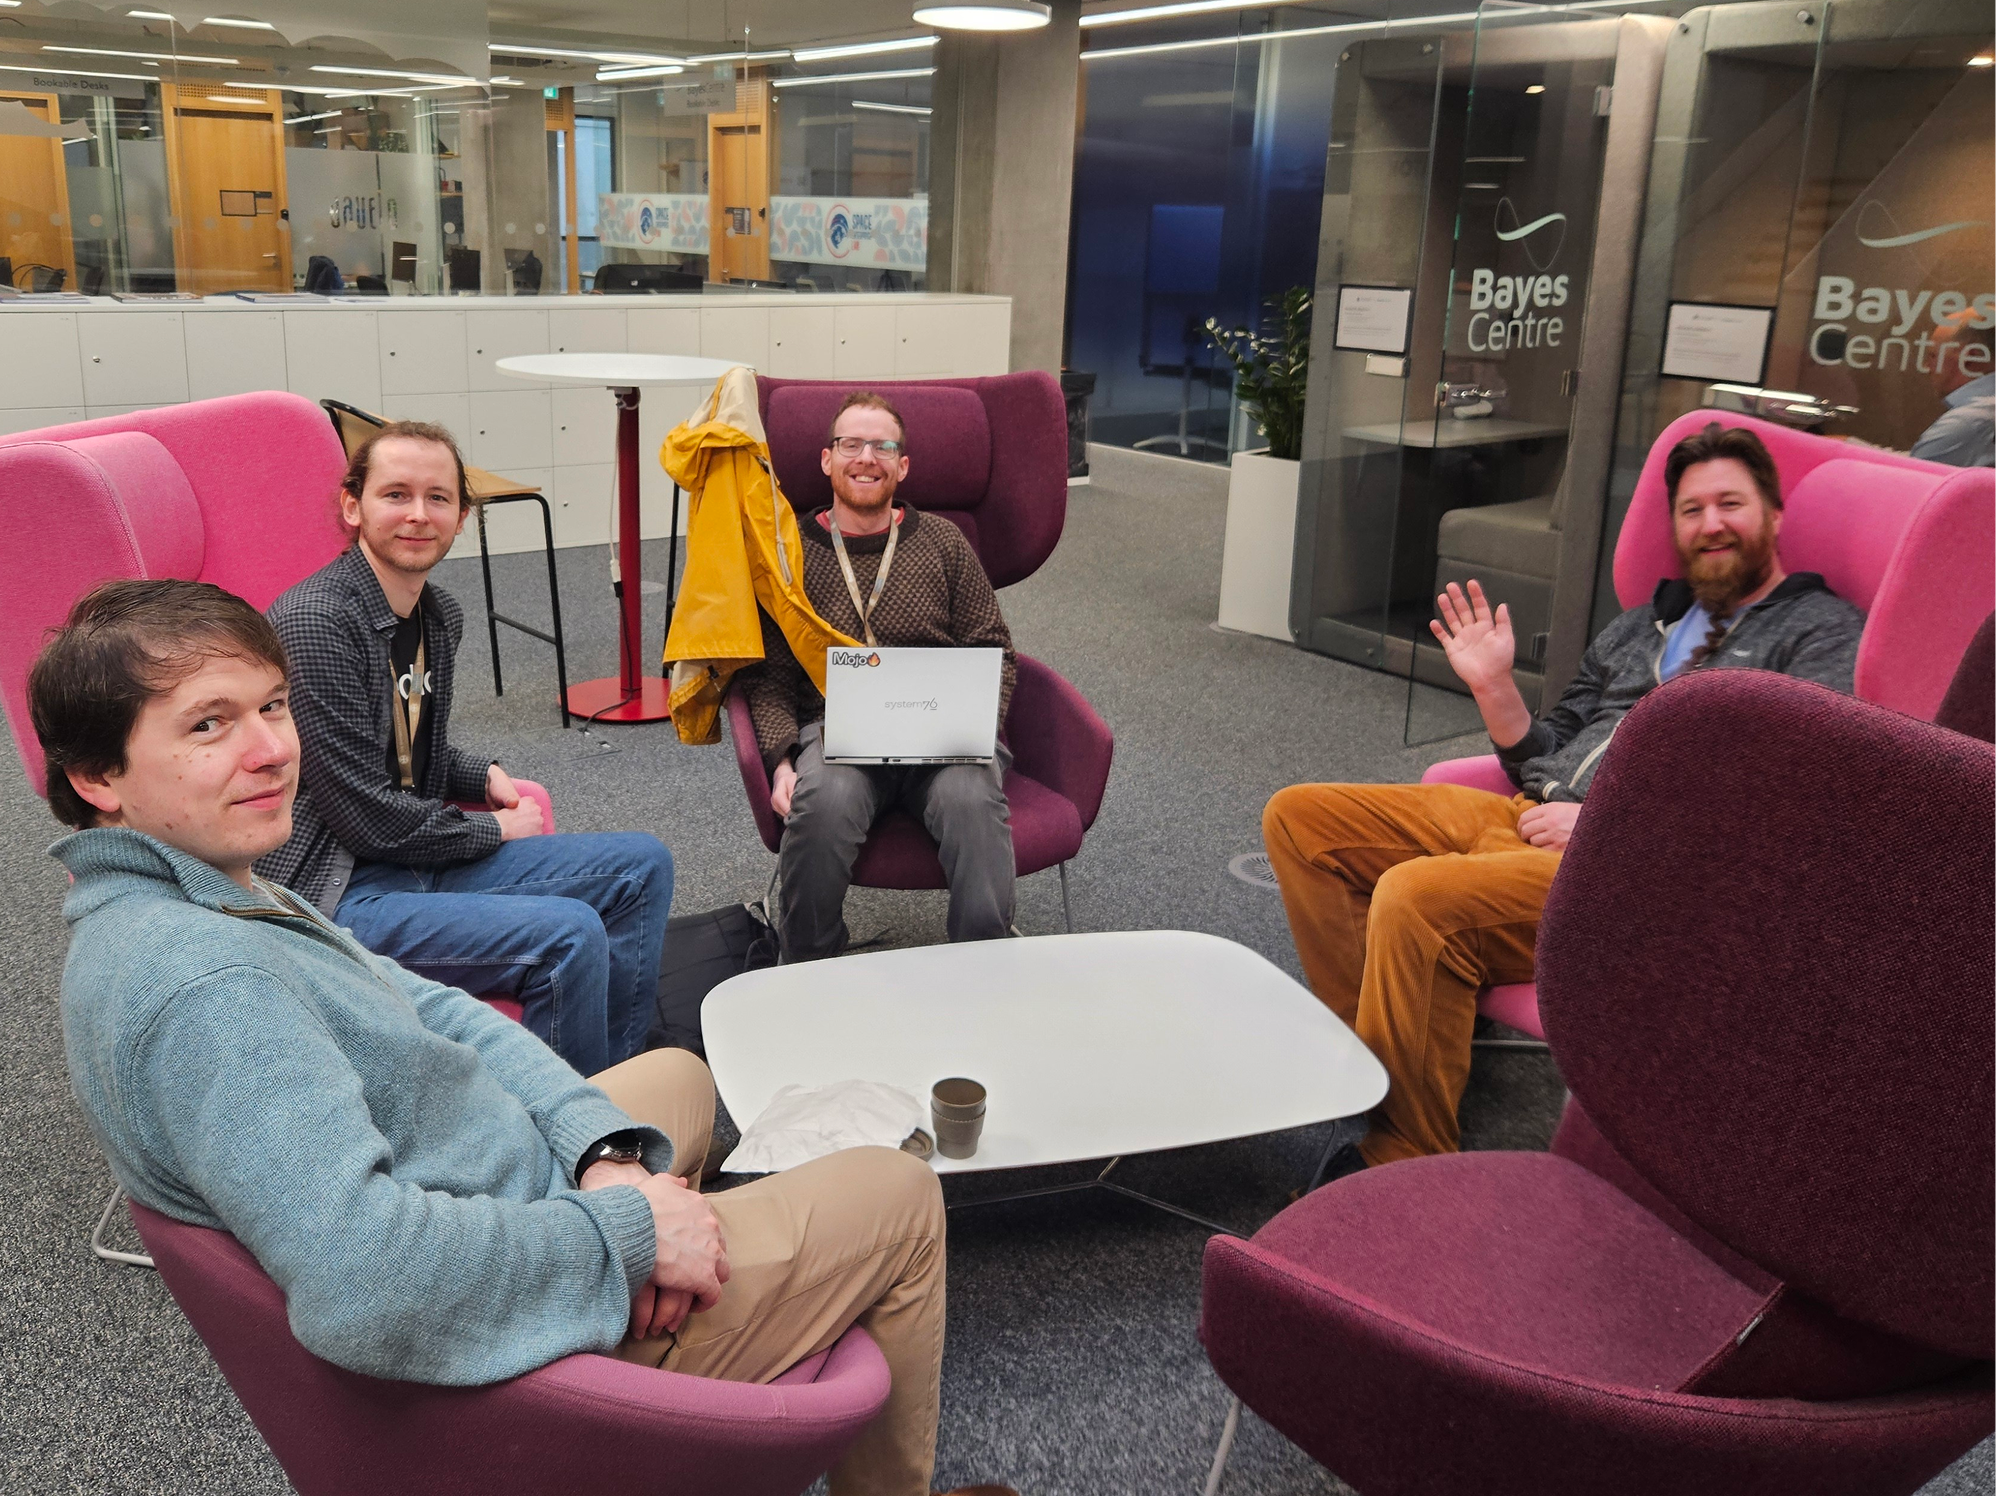
Our Edinburgh team is already growing. Within our first week at the Bayes Centre, we were onboarding new hires and holding cross-team working sessions in person. We're looking forward to being part of the Bayes Centre community: events, collaboration, and the kind of conversations that happen when you share a building with people solving hard, adjacent problems.
We've also opened a new office in San Francisco's Jackson Square neighborhood, joining our Los Altos headquarters as our second Bay Area location. SF puts us closer to AI talent, frontier model providers, and the infrastructure companies building what comes next. The space includes room for events and customer meetings. Expect to see us hosting more in the city soon.
Every AI team hits the same wall. You prototype in Python because it's fast to write, then spend months rewriting in C++ and CUDA to get the performance you need in production. You get locked into one hardware vendor. Scaling means buying more GPUs instead of using the ones you have more efficiently.
Modular was founded by Chris Lattner (the engineer behind LLVM, Clang, Swift, and MLIR) and Tim Davis (who led AI infrastructure at Google Brain, building TensorFlow and the compiler and runtime stack behind it) to solve this problem at the infrastructure layer.
Mojo is our programming language: Python's readability with compiled, bare-metal performance. If you can write Python, you can write Mojo, and your code runs orders of magnitude faster. Mojo is free to use, with hundreds of thousands of lines of open-source code and a community of over 50,000 developers.
MAX is our AI inference platform. It supports hundreds of models out of the box (Llama, DeepSeek, Mistral, FLUX for image generation) with an OpenAI-compatible API. Because MAX uses a compiler-first approach rather than hand-tuned kernels, it runs on NVIDIA, AMD, and CPU hardware without rewriting a single line of code. Teams use MAX to serve billions of tokens in production today.
Hardware is diversifying fast. New GPU architectures, custom accelerators, edge devices. Most AI frameworks still assume you're running NVIDIA GPUs with CUDA, and porting to anything else takes months of engineering.
Modular's compiler infrastructure does that porting for you. As new hardware arrives, the stack adapts. Developers focus on their models and applications instead of low-level hardware plumbing. It's a problem that sits at the intersection of compilers, systems engineering, and AI, exactly the kind of work Edinburgh has been producing top talent for.
Mojo and MAX are free to get started with. Our community forum and Discord are open to everyone. If you're working on GPU programming, AI model serving, or hardware-portable computing, we'd love to hear from you.
We're hiring across engineering, infrastructure, and go-to-market roles, including in Edinburgh. Check our careers page for open positions.
Come find us at modular.com, or say hello at the Bayes Centre.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。