








 We’re currently setting up our own hardware server where we want to run self-hosted models. But we can’t just switch client traffic to them right away – first we need to see how these self-hosted LLMs will actually perform.
So the general idea for now is to keep sending traffic to the primary provider, OpenAI and the 5.6 models, while in parallel setting up a kind of “hidden traffic mirroring” – sending the requests we get from clients to our Gemma-4 as well (that’s what we’re testing with for now).
And then, once we have responses from both models – set up comparison and evaluation of the answers, but that’s for the next part.
LiteLLM has its own mechanisms for this kind of request parallelization, but as I covered in the previous post LiteLLM: Traffic Mirroring and Batch Completions, and traffic to two providers – none of them worked for us.
So – we’ll write our own “dirty hack” with blackjack and traces, and the main “feature” of this solution is that we’ll set up creation of our own OTel span with our own attributes.
Note: the solution described in this post is fully working, we used it, but later I reworked it a bit and added Redis – the Custom Callback writes a task to a Redis stream, a separate Mirror Worker reads tasks from there, and then it actually sends the request to our server. I’ll cover this in more detail in the next post about LLM Evaluations.
We deploy LiteLLM with Helm, I wrote about it in LiteLLM: AI Gateway in Kubernetes and metrics to VictoriaMetrics, so we’ll do the Custom Callback with it as well.
Contents
The idea is this:
trace_id, and in our span attributes we store the original request plus the responses from the primary model and oursAs a result, in VictoriaTraces we’ll have a trace with roughly this structure:
POST /v1/chat/completions
├── chat primary-model
└── our-custom-span
    ├── original prompt
    ├── primary model response
    └── our model response
Our own server has the hostname “Matrix” – so throughout the text, whenever I refer to our self-hosted server, you’ll see this name.
LiteLLM documentation – Custom Callbacks.
So, let’s start writing the script.
At first it will only write to the log, and we’ll connect it through Helm and a ConfigMap.
Add the helm/files/traffic_mirror_callback.py file:
"""LiteLLM success callback used as the entry point for traffic mirroring.

The first PoC step only confirms that LiteLLM invokes the callback and exposes
the primary model and response ID. The Matrix request and OTEL span will be
added after the callback is wired into the Helm deployment.
"""

from datetime import datetime
from typing import Any

from litellm._logging import verbose_proxy_logger
from litellm.integrations.custom_logger import CustomLogger


class TrafficMirrorCallback(CustomLogger):
    async def async_log_success_event(
        self,
        kwargs: dict[str, Any],
        response_obj: Any,
        start_time: datetime,
        end_time: datetime,
    ) -> None:
        verbose_proxy_logger.info(
            "TRAFFIC_MIRROR_CALLBACK primary_model=%s response_id=%s",
            kwargs.get("model"),
            getattr(response_obj, "id", None),
        )


traffic_mirror_callback = TrafficMirrorCallback()
Here we:
TrafficMirrorCallback class, which inherits LiteLLM’s own CustomLoggerasync def async_log_success_event(), define our own implementation of the method from the CustomLogger classasync_log_success_event(), add a call to verbose_proxy_logger.info() – LiteLLM’s standard loggerThen, when processing a client request, LiteLLM sends that request to the primary provider and model, after which it calls the callbacks one by one, passing all request parameters in kwargs – for now, we only use them to write the model name to the log with kwargs.get("model").
At the same time, our callback only fires for successful requests to the primary model – because we only implemented the async_log_success_event() method. If we also need to log failed requests, CustomLogger has the async_log_failure_event() method (see Custom Callback Class [Async]).
Create the helm/templates/traffic-mirror-callback-configmap.yaml file, where we define a ConfigMap that stores the contents of the traffic_mirror_callback.py file in data:
apiVersion: v1
kind: ConfigMap
metadata:
  name: litellm-traffic-mirror-callback
data:
  traffic_mirror_callback.py: |
{{ .Files.Get "files/traffic_mirror_callback.py" | indent 4 }}
In the chart values files, add a new volume from this ConfigMap:
...
volumes:

  - name: traffic-mirror-callback
    configMap:
      name: litellm-traffic-mirror-callback
...
And add volumeMounts from this volume as a file in the LiteLLM Pods:
...

volumeMounts:

  - name: traffic-mirror-callback
    mountPath: /etc/litellm/traffic_mirror_callback.py
    subPath: traffic_mirror_callback.py

...
Deploy it and check that the file was created:
$ kubectl -n test-litellm-ns exec deploy/litellm -- \
  ls -l /etc/litellm/traffic_mirror_callback.py
-rw-r--r--    1 root     root           938 Aug 21 12:15 /etc/litellm/traffic_mirror_callback.py
But at this point it isn’t called yet – it’s only added to the containers.
In the config, add our traffic_mirror_callback call to litellm_settings.callbacks:
...

litellm_settings:
  callbacks:
    - prometheus
    - arize_phoenix
    - traffic_mirror_callback.traffic_mirror_callback

...
Now when LiteLLM starts, it will:
/etc/litellm/traffic_mirror_callback.pytraffic_mirror_callback – the instance of our TrafficMirrorCallback() classcallbacks listasync_log_success_event() after successful requests to the primary model passed by the clientRun the test script (it’s in the Configuring silent_model section of the previous post):
$ ./test_single.py
request_id: chatcmpl-EFIYxl58uvTqnygPeYFjjSRBuQ6yU
model: gpt-4.1
Check the logs in VictoriaLogs – search for “TRAFFIC_MIRROR_CALLBACK“, which we set in the script – verbose_proxy_logger.info( "TRAFFIC_MIRROR_CALLBACK primary_model=%s response_id=%s"):
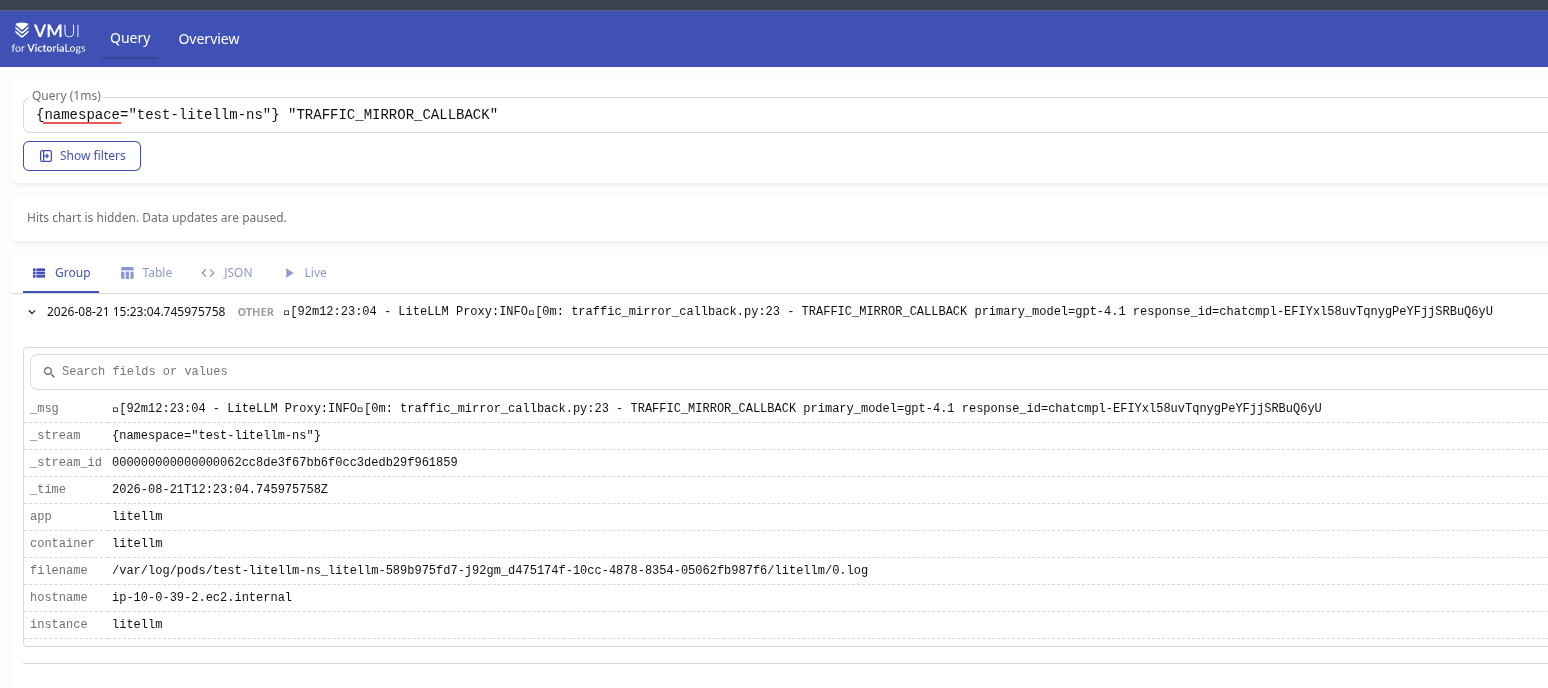
Everything works.
Right now we only write the model name and response_id to the log – but to pass the request to our Matrix, we need the actual request text itself.
For this, we need to pass the prompt data from kwargs to verbose_proxy_logger.info(), and then parse response_obj, which contains the text of the primary model response.
Update the traffic_mirror_callback.py script:
"""LiteLLM success callback used as the entry point for traffic mirroring.

The callback currently logs the primary request and response. The Matrix
request and OTEL span will be added in the next PoC steps.
"""

import json
from datetime import datetime
from typing import Any

from litellm._logging import verbose_proxy_logger
from litellm.integrations.custom_logger import CustomLogger


def _json(value: Any) -> str:
    """Serialize callback data into a single log line."""
    if hasattr(value, "model_dump"):
        value = value.model_dump()

    return json.dumps(
        value,
        ensure_ascii=False,
        default=str,
    )


def _primary_input(kwargs: dict[str, Any]) -> Any:
    """Read input from either Chat Completions or Responses API kwargs."""
    return kwargs.get("messages") or kwargs.get("input")


def _primary_output(response_obj: Any) -> Any:
    """Read assistant output from either Chat Completions or Responses API."""
    choices = getattr(response_obj, "choices", None)

    if choices:
        message = getattr(choices[0], "message", None)
        return getattr(message, "content", None)

    output_text = getattr(response_obj, "output_text", None)

    if output_text:
        return output_text

    return getattr(response_obj, "output", None)


class TrafficMirrorCallback(CustomLogger):
    async def async_log_success_event(
        self,
        kwargs: dict[str, Any],
        response_obj: Any,
        start_time: datetime,
        end_time: datetime,
    ) -> None:
        verbose_proxy_logger.info(
            "TRAFFIC_MIRROR_CALLBACK primary_model=%s response_id=%s "
            "input=%s primary_response=%s",
            kwargs.get("model"),
            getattr(response_obj, "id", None),
            _json(_primary_input(kwargs)),
            _json(_primary_output(response_obj)),
        )


traffic_mirror_callback = TrafficMirrorCallback()
Here:
_primary_input(), which parses the request text – both for the Response API and for Chat Completions, because our clients use both
_primary_output() we parse the response from the primary modelDeploy it, make a test request, and now we have all the data we need in the logs:
{
    "_msg": "\u001b[92m13:00:46 - LiteLLM Proxy:INFO\u001b[0m: traffic_mirror_callback.py:49 - TRAFFIC_MIRROR_CALLBACK primary_model=gpt-4.1 response_id=chatcmpl-EFJ9Rio82fSnlf6PpkeUXYuxEWyGa input=[{\"role\": \"user\", \"content\": \"Test #1: this is a test request, write a short poem\"}] primary_response=\"A whisper drifts upon the air,  \\nSoft as dawn’s first gentle light—  \\nA silent hope, a quiet dare,  \\nBorn within the heart of night.  \\n\\nEven in this fleeting rhyme,  \\nA test becomes a start—  \\nWords that mark the stretch of time,  \\nAnd poetry that stirs the heart.\"",
    "_stream": "{namespace=\"test-litellm-ns\"}",
    ...
}
Now that we have the request message text itself – we can add sending it to our own model, and actually start implementing that “traffic mirroring”.
The variables with parameters for our server use the MATRIX_ prefix – to clearly show that they relate to our server named Matrix, and there are three of them here – the server URL and the llama.cpp port on it, the name of the model we send the request to, and the response timeout:
"""LiteLLM callback that mirrors successful requests to Matrix."""

import json
from datetime import datetime
from typing import Any

import httpx
from litellm._logging import verbose_proxy_logger
from litellm.integrations.custom_logger import CustomLogger


MATRIX_URL = "http://matrix.neoc.vpn.ops.example.co:31000/v1/chat/completions"
MATRIX_MODEL = "gemma-4-26b-a4b-it-q8"
MATRIX_TIMEOUT_SECONDS = 120.0


def _json(value: Any) -> str:
    """Serialize callback data into a single log line."""
    if hasattr(value, "model_dump"):
        value = value.model_dump()
    return json.dumps(value, ensure_ascii=False, default=str)


def _primary_input(kwargs: dict[str, Any]) -> Any:
    """Read input from either Chat Completions or Responses API kwargs."""
    return kwargs.get("messages") or kwargs.get("input")


def _primary_output(response_obj: Any) -> Any:
    """Read assistant output from either Chat Completions or Responses API."""
    choices = getattr(response_obj, "choices", None)
    if choices:
        message = getattr(choices[0], "message", None)
        return getattr(message, "content", None)

    output_text = getattr(response_obj, "output_text", None)
    if output_text:
        return output_text

    return getattr(response_obj, "output", None)


async def _request_matrix(messages: Any) -> dict[str, Any]:
    """Send a copy of the primary request directly to Matrix."""
    async with httpx.AsyncClient(timeout=MATRIX_TIMEOUT_SECONDS) as client:
        response = await client.post(
            MATRIX_URL,
            json={
                "model": MATRIX_MODEL,
                "messages": messages,
                "temperature": 0,
                "max_tokens": 1024,
            },
        )
        response.raise_for_status()
        return response.json()


class TrafficMirrorCallback(CustomLogger):
    async def async_log_success_event(
        self,
        kwargs: dict[str, Any],
        response_obj: Any,
        start_time: datetime,
        end_time: datetime,
    ) -> None:
        primary_input = _primary_input(kwargs)

        verbose_proxy_logger.info(
            "TRAFFIC_MIRROR_CALLBACK primary_model=%s response_id=%s "
            "input=%s primary_response=%s",
            kwargs.get("model"),
            getattr(response_obj, "id", None),
            _json(primary_input),
            _json(_primary_output(response_obj)),
        )

        try:
            matrix_response = await _request_matrix(primary_input)
            matrix_choice = matrix_response["choices"][0]
            matrix_message = matrix_choice["message"]

            verbose_proxy_logger.info(
                "TRAFFIC_MIRROR_MATRIX primary_response_id=%s "
                "matrix_model=%s matrix_response_id=%s finish_reason=%s "
                "matrix_response=%s matrix_reasoning=%s",
                getattr(response_obj, "id", None),
                MATRIX_MODEL,
                matrix_response.get("id"),
                matrix_choice.get("finish_reason"),
                _json(matrix_message.get("content")),
                _json(matrix_message.get("reasoning_content")),
            )
        except Exception:
            verbose_proxy_logger.exception(
                "TRAFFIC_MIRROR_MATRIX_FAILED primary_response_id=%s",
                getattr(response_obj, "id", None),
            )


traffic_mirror_callback = TrafficMirrorCallback()
The main change here is the new _request_matrix() function, where we use httpx.AsyncClient() to make a request to the llama.cpp API endpoint.
We could also do it with the OpenAI client – but here I kept everything as simple as possible.
In async_log_success_event(), we first add a call to _request_matrix(), passing it the original client request, and then write the response from Matrix.
Run it and search the logs for “TRAFFIC_MIRROR_MATRIX“:
{
    "_msg": "\u001b[92m13:11:39 - LiteLLM Proxy:INFO\u001b[0m: traffic_mirror_callback.py:82 - TRAFFIC_MIRROR_MATRIX primary_response_id=chatcmpl-EFJJuVK9gz6N2OAvV2ffBmyELU5Ku matrix_model=gemma-4-26b-a4b-it-q8 matrix_response_id=chatcmpl-96X4DynEjuuPcrx21elAZjhq8uirB8Vw finish_reason=stop matrix_response=\"A spark of thought, a line of code,\\nA journey on a digital road.\\nThe test is sent, the signal flies,\\nBeneath the glow of virtual skies.\" matrix_reasoning=\"*   Input: \\\"Test #1: this is a test request, write a short poem\\\"\\n    *   Intent: The user is testing the system's ability to follow a simple instruction (writing a short poem).\\n    *   Constraint: \\\"short poem\\\".\\n\\n    *   Topic: Since it's a \\\"test,\\\" I could write about testing, or just a generic pleasant poem. A poem about the act of testing or a simple nature poem works well.\\n    *   Structure: A few lines, maybe a rhyme scheme (AABB or ABAB).\\n\\n    *   *Option 1 (Meta/Testing):*\\n        A spark of thought, a line of code,\\n        A journey on a digital road.\\n        The test is sent, the signal flies,\\n        Beneath the glow of virtual skies.\\n\\n    *   *Option 2 (Nature/Generic):*\\n        The sun dips low behind the hill,\\n        The evening air is calm and still.\\n        A single star begins to peep,\\n        As all the world prepares for sleep.\\n\\n    Option 1 is more clever given the context of \\\"Test #1\\\".\\n\\n    A spark of thought, a line of code,\\n    A journey on a digital road.\\n    The test is sent, the signal flies,\\n    Beneath the glow of virtual skies.\\n\\n    *   Is it short? Yes.\\n    *   Is it a poem? Yes.\\n    *   Does it address the prompt? Yes.\"",
    "_stream": "{namespace=\"test-litellm-ns\"}",
    ...
}
Now we have:
primary_response_idmatrix_response_idBut all of this is only in the logs for now, and we’d rather have it nicely in traces together with the rest of the telemetry.
In this version, _primary_input() has a bug – input from the Responses API does not necessarily have the same format as messages from the Chat Completions API.
primary_input is passed to Matrix, and it contains the value of kwargs.get("messages") for the Chat Completions API, or kwargs.get("input") for the Responses API
_request_matrix(primary_input), while primary_input is created by _primary_input(), which executes return kwargs.get("messages") or kwargs.get("input")MATRIX_URL = "[...]/v1/chat/completions"_request_matrix() we simply pass _request_matrix(primary_input), which creates the "messages" fieldI noticed this later and fixed it in the next callback version – added a function that checks the format and converts it to the Chat Completions API format.
I won’t change it here anymore, but once I finish the next post – I’ll add a link to that fix here.
The main idea here is that we create our own span – but it is added to the parent span that LiteLLM creates when it receives a client request.
This way we get all the data in one trace – about the request itself, the request to the primary model, and our request to Matrix.
Update the code:
"""LiteLLM callback that mirrors successful requests to Matrix."""

import json
from datetime import datetime
from typing import Any

import httpx
from litellm._logging import verbose_proxy_logger
from litellm.integrations.custom_logger import CustomLogger
from opentelemetry import trace
from opentelemetry.trace import SpanKind, Status, StatusCode


MATRIX_URL = "http://matrix.neoc.vpn.ops.example.co:31000/v1/chat/completions"
MATRIX_MODEL = "gemma-4-26b-a4b-it-q8"
MATRIX_TIMEOUT_SECONDS = 120.0
tracer = trace.get_tracer("litellm.traffic_mirror")


def _json(value: Any) -> str:
    """Serialize callback data into a single log line."""
    if hasattr(value, "model_dump"):
        value = value.model_dump()
    return json.dumps(value, ensure_ascii=False, default=str)


def _primary_input(kwargs: dict[str, Any]) -> Any:
    """Read input from either Chat Completions or Responses API kwargs."""
    return kwargs.get("messages") or kwargs.get("input")


def _primary_output(response_obj: Any) -> Any:
    """Read assistant output from either Chat Completions or Responses API."""
    choices = getattr(response_obj, "choices", None)
    if choices:
        message = getattr(choices[0], "message", None)
        return getattr(message, "content", None)

    output_text = getattr(response_obj, "output_text", None)
    if output_text:
        return output_text

    return getattr(response_obj, "output", None)


async def _request_matrix(messages: Any) -> dict[str, Any]:
    """Send a copy of the primary request directly to Matrix."""
    async with httpx.AsyncClient(timeout=MATRIX_TIMEOUT_SECONDS) as client:
        response = await client.post(
            MATRIX_URL,
            json={
                "model": MATRIX_MODEL,
                "messages": messages,
                "temperature": 0,
                "max_tokens": 1024,
            },
        )
        response.raise_for_status()
        return response.json()


class TrafficMirrorCallback(CustomLogger):
    async def async_log_success_event(
        self,
        kwargs: dict[str, Any],
        response_obj: Any,
        start_time: datetime,
        end_time: datetime,
    ) -> None:
        primary_input = _primary_input(kwargs)

        verbose_proxy_logger.info(
            "TRAFFIC_MIRROR_CALLBACK primary_model=%s response_id=%s "
            "input=%s primary_response=%s",
            kwargs.get("model"),
            getattr(response_obj, "id", None),
            _json(primary_input),
            _json(_primary_output(response_obj)),
        )

        try:
            with tracer.start_as_current_span(
                f"traffic_mirror {MATRIX_MODEL}",
                kind=SpanKind.CLIENT,
            ) as span:
                span.set_attribute("gen_ai.operation.name", "chat")
                span.set_attribute("gen_ai.provider.name", "llama.cpp")
                span.set_attribute("gen_ai.request.model", MATRIX_MODEL)
                span.set_attribute("gen_ai.request.max_tokens", 1024)
                span.set_attribute("gen_ai.request.temperature", 0.0)
                span.set_attribute("gen_ai.input.messages", _json(primary_input))
                span.set_attribute(
                    "traffic_mirror.primary.model",
                    str(kwargs.get("model")),
                )
                span.set_attribute(
                    "traffic_mirror.primary.response_id",
                    str(getattr(response_obj, "id", None)),
                )
                span.set_attribute(
                    "traffic_mirror.primary.response",
                    _json(_primary_output(response_obj)),
                )

                matrix_response = await _request_matrix(primary_input)
                matrix_choice = matrix_response["choices"][0]
                matrix_message = matrix_choice["message"]

                span.set_attribute(
                    "gen_ai.response.id",
                    str(matrix_response.get("id")),
                )
                span.set_attribute(
                    "gen_ai.response.model",
                    str(matrix_response.get("model", MATRIX_MODEL)),
                )
                span.set_attribute(
                    "gen_ai.response.finish_reasons",
                    _json([matrix_choice.get("finish_reason")]),
                )
                span.set_attribute(
                    "gen_ai.output.messages",
                    _json([matrix_message]),
                )
                span.set_attribute(
                    "traffic_mirror.matrix.response",
                    _json(matrix_message.get("content")),
                )
                span.set_attribute(
                    "traffic_mirror.matrix.reasoning",
                    _json(matrix_message.get("reasoning_content")),
                )
                span.set_status(Status(StatusCode.OK))

                verbose_proxy_logger.info(
                    "TRAFFIC_MIRROR_MATRIX primary_response_id=%s "
                    "matrix_model=%s matrix_response_id=%s finish_reason=%s "
                    "matrix_response=%s matrix_reasoning=%s",
                    getattr(response_obj, "id", None),
                    MATRIX_MODEL,
                    matrix_response.get("id"),
                    matrix_choice.get("finish_reason"),
                    _json(matrix_message.get("content")),
                    _json(matrix_message.get("reasoning_content")),
                )
        except Exception:
            verbose_proxy_logger.exception(
                "TRAFFIC_MIRROR_MATRIX_FAILED primary_response_id=%s",
                getattr(response_obj, "id", None),
            )


traffic_mirror_callback = TrafficMirrorCallback()
Here:
opentelemetry importstrace.get_tracer – named “litellm.traffic_mirror“tracer.start_as_current_span()span.set_attribute(), set all the attributes we want to see, and the gen_ai names follow the standard OTel semantic convention, see GenAI AttributesDeploy it and check the traces with name:~"traffic_mirror":
{resource_attr:service.name="litellm"} "span_attr:litellm.metadata.user_api_key_alias":="ops-testing"
| name:~"traffic_mirror"
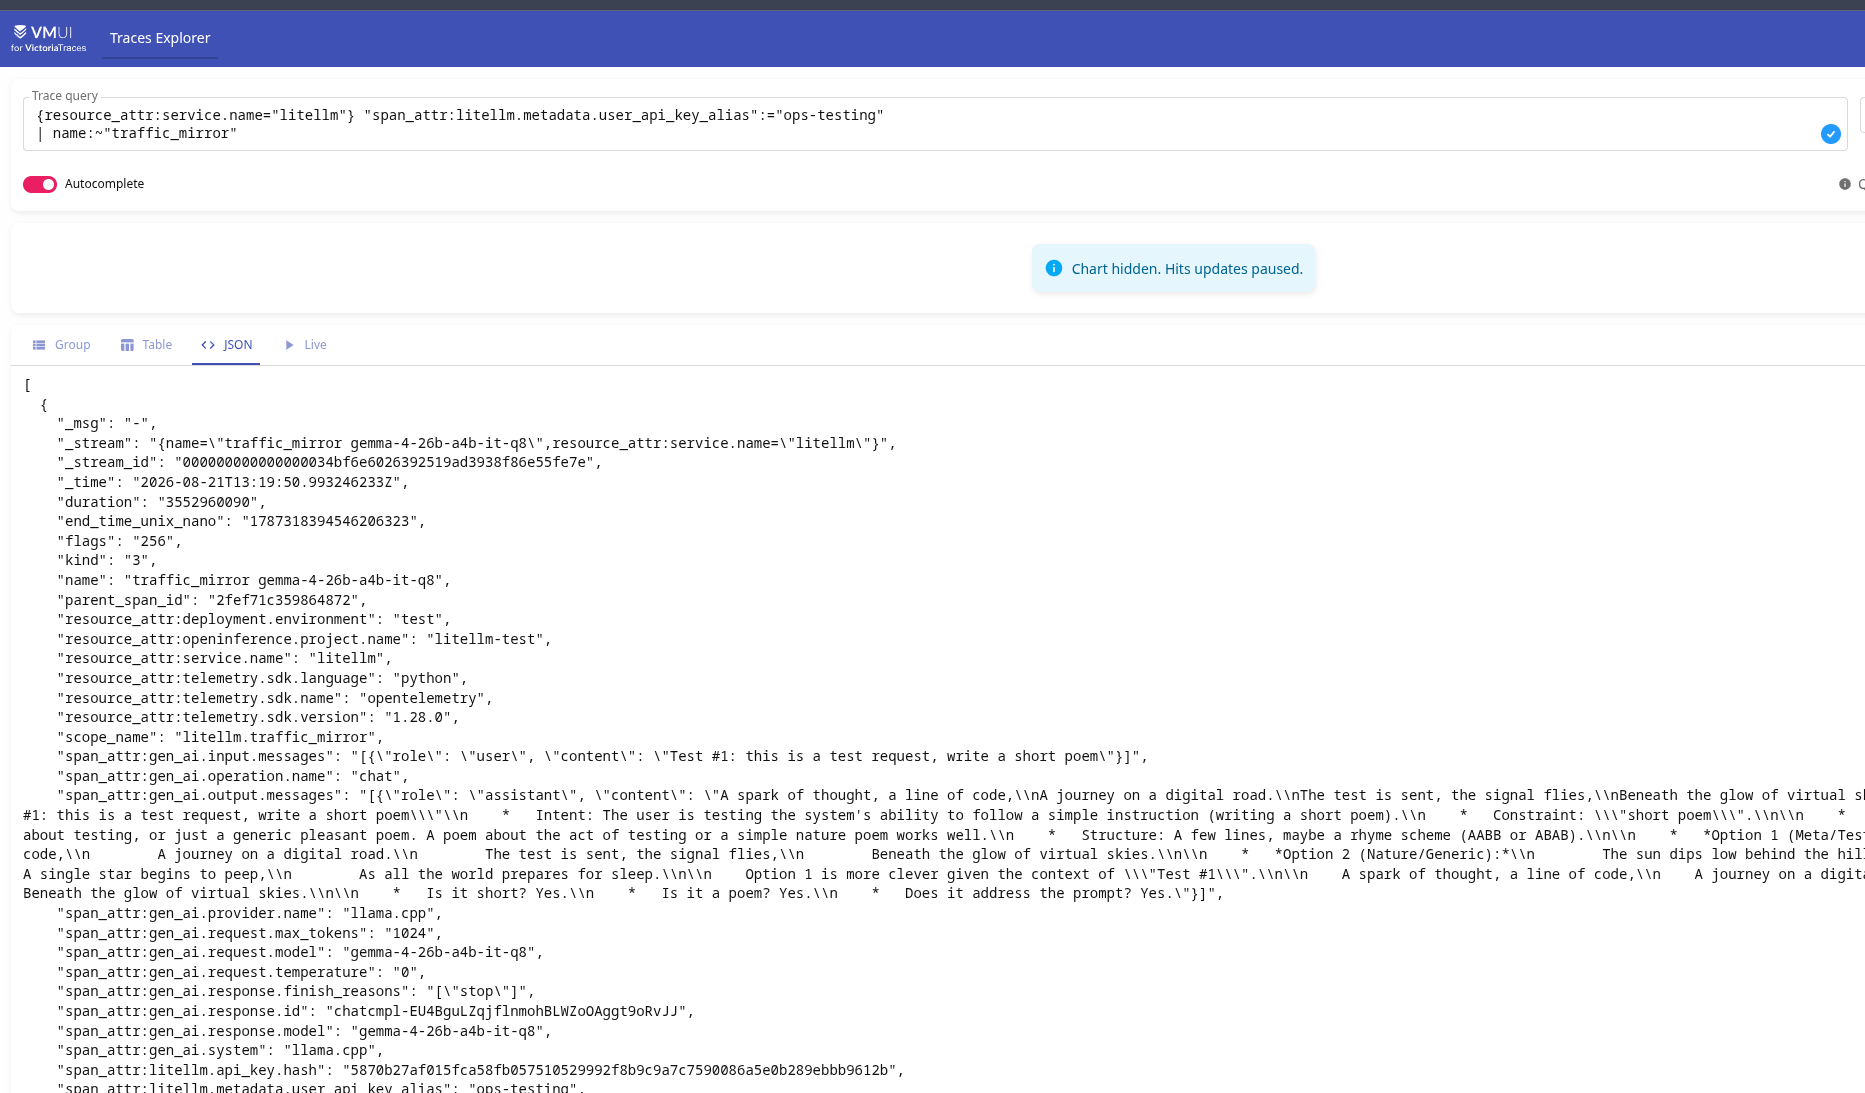
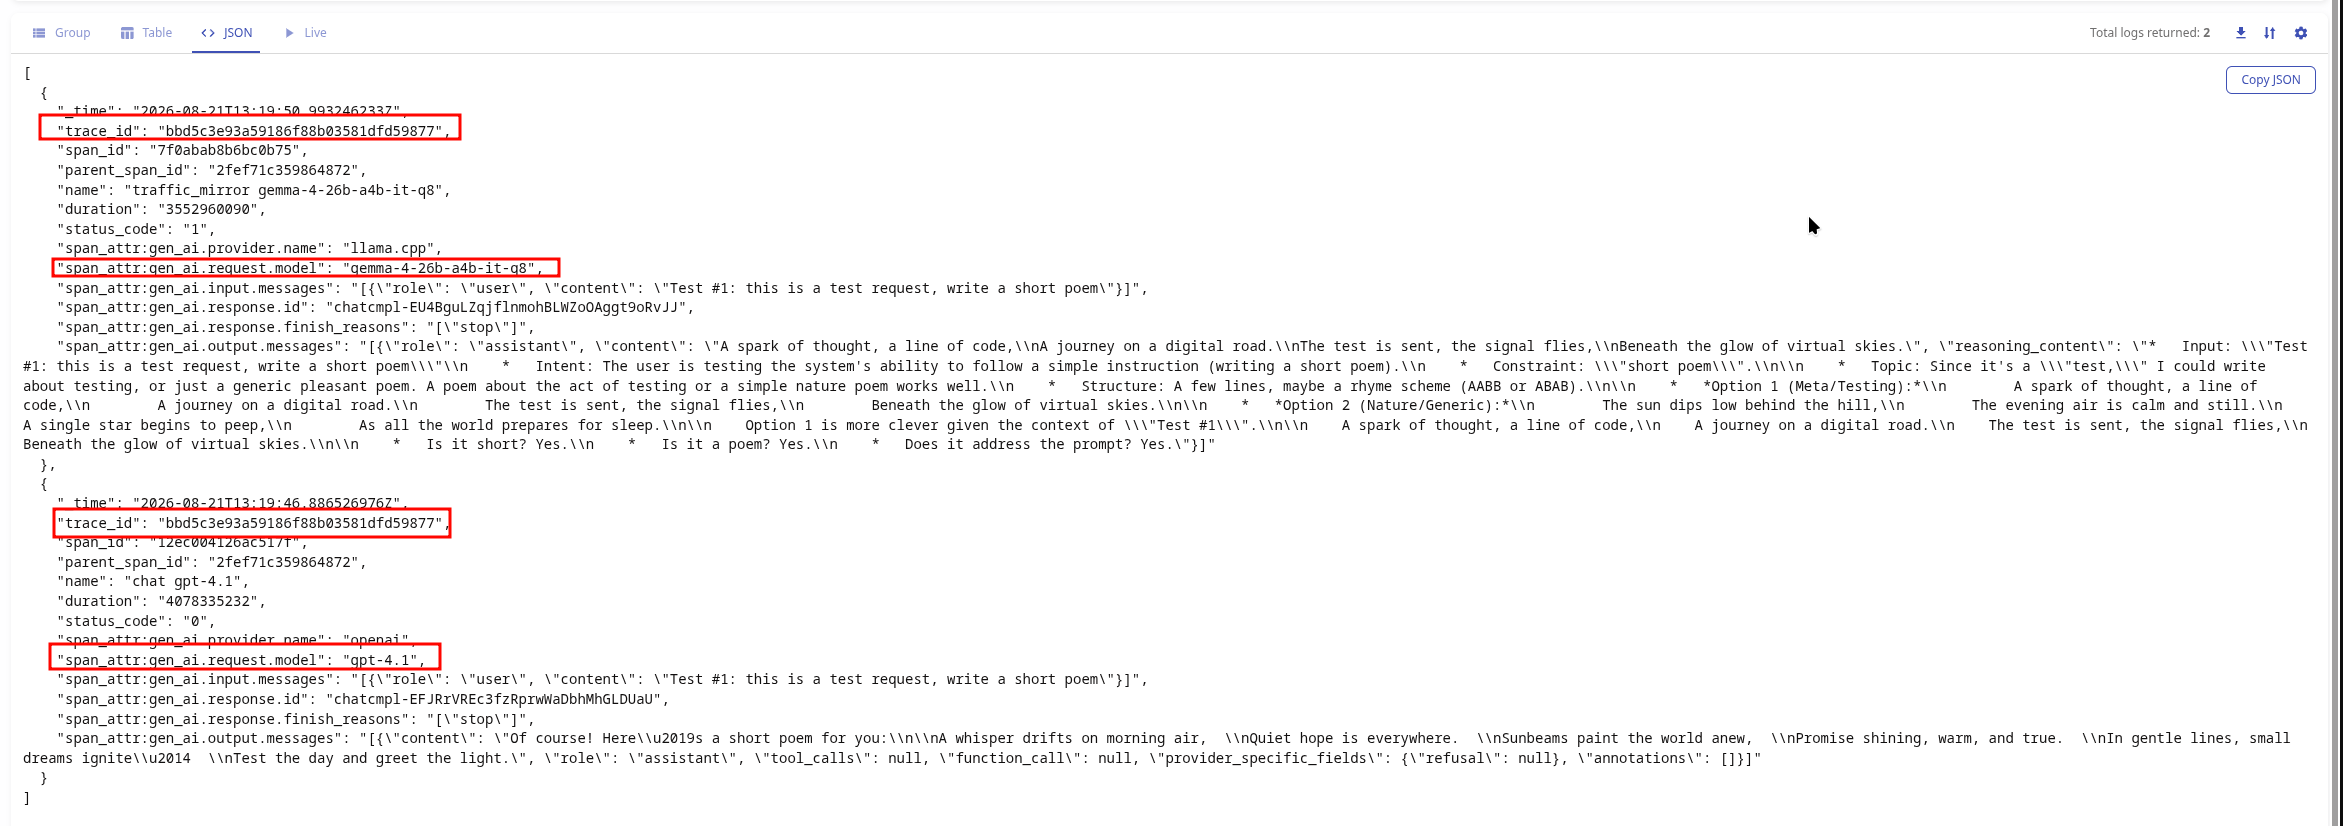
Find its trace_id, and with the (name:="chat gpt-4.1" OR name:="traffic_mirror gemma-4-26b-a4b-it-q8") filter, look at the spans for both the primary model and ours:
{resource_attr:service.name="litellm"}
trace_id:="bbd5c3e93a59186f88b03581dfd59877"
(name:="chat gpt-4.1" OR name:="traffic_mirror gemma-4-26b-a4b-it-q8")
| fields
    _time,
    trace_id,
    span_id,
    parent_span_id,
    name,
    duration,
    status_code,
    "span_attr:gen_ai.provider.name",
    "span_attr:gen_ai.request.model",
    "span_attr:gen_ai.input.messages",
    "span_attr:gen_ai.response.id",
    "span_attr:gen_ai.response.finish_reasons",
    "span_attr:gen_ai.output.messages"
 That’s pretty much it – everything is ready.
The next task, using all this data, is to send the request text and both responses to a “judge” – a third LLM. It will evaluate both responses, assign its score, and we’ll write that as metrics to VictoriaMetrics.
This is already done and working, and I have a draft of the post – hopefully I’ll finish it, because it turned out to be quite a lot of text.

此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。