






May 7, 2026

Modular Team
Surprise: Mojo 1.0 is officially in beta! Modular’s 26.3 release includes new features and modalities, but the headline is that we’ve officially hit beta for Mojo 1.0, with a clear plan to finalize Mojo 1.0 in the coming months. We share details below, alongside other key announcements in our 26.3 release including video generation in MAX with Wan 2.2 and MAX framework updates.
Mojo is the foundation for everything we do at Modular, from pushing the state-of-the-art in kernel performance, to running on new and novel accelerator hardware. Back in December, we provided a roadmap to 1.0 for the Mojo language, and we’re now excited to announce that a beta for Mojo 1.0 is available today!
Mojo 1.0 will be finalized later this year, along with opening the compiler and providing language stability. This marks the start of a new era for the language. You can now build your projects against known versions of Mojo and they won’t break on you tomorrow. The beta provides what we believe is a “feature complete” Mojo 1.0 language, but there’s a lot to be polished before final release.
The 1.0 beta ships several features we've been working toward for a long time. Those include:
We’re also introducing the successor to LayoutTensor, called TileTensor, that makes it even easier to write high-performance kernels. TileTensor makes memory layout a compile-time property of the tensor itself, so the swizzles, strides, and indexing that GPU kernels require are checked by the type system rather than maintained by hand. We’ve started a dedicated blog post series on this neat new type, and it underpins the new paradigm of structured kernels we write about in our ongoing series.
But that’s not all! We felt that with how far Mojo has come, it was time to give it a proper new home.
That’s right, Mojo now has its own website at mojolang.org!
Along with the Mojo 1.0 beta release, launching this website represents a significant milestone; Mojo is nearly ready for widespread adoption. Mojolang.org is an important step towards opening up Mojo to the world with a full 1.0 release, which we aim to complete by the fall.
Whether you’re new to Mojo or an experienced contributor, it’s now more clear than ever where to get everything you need.
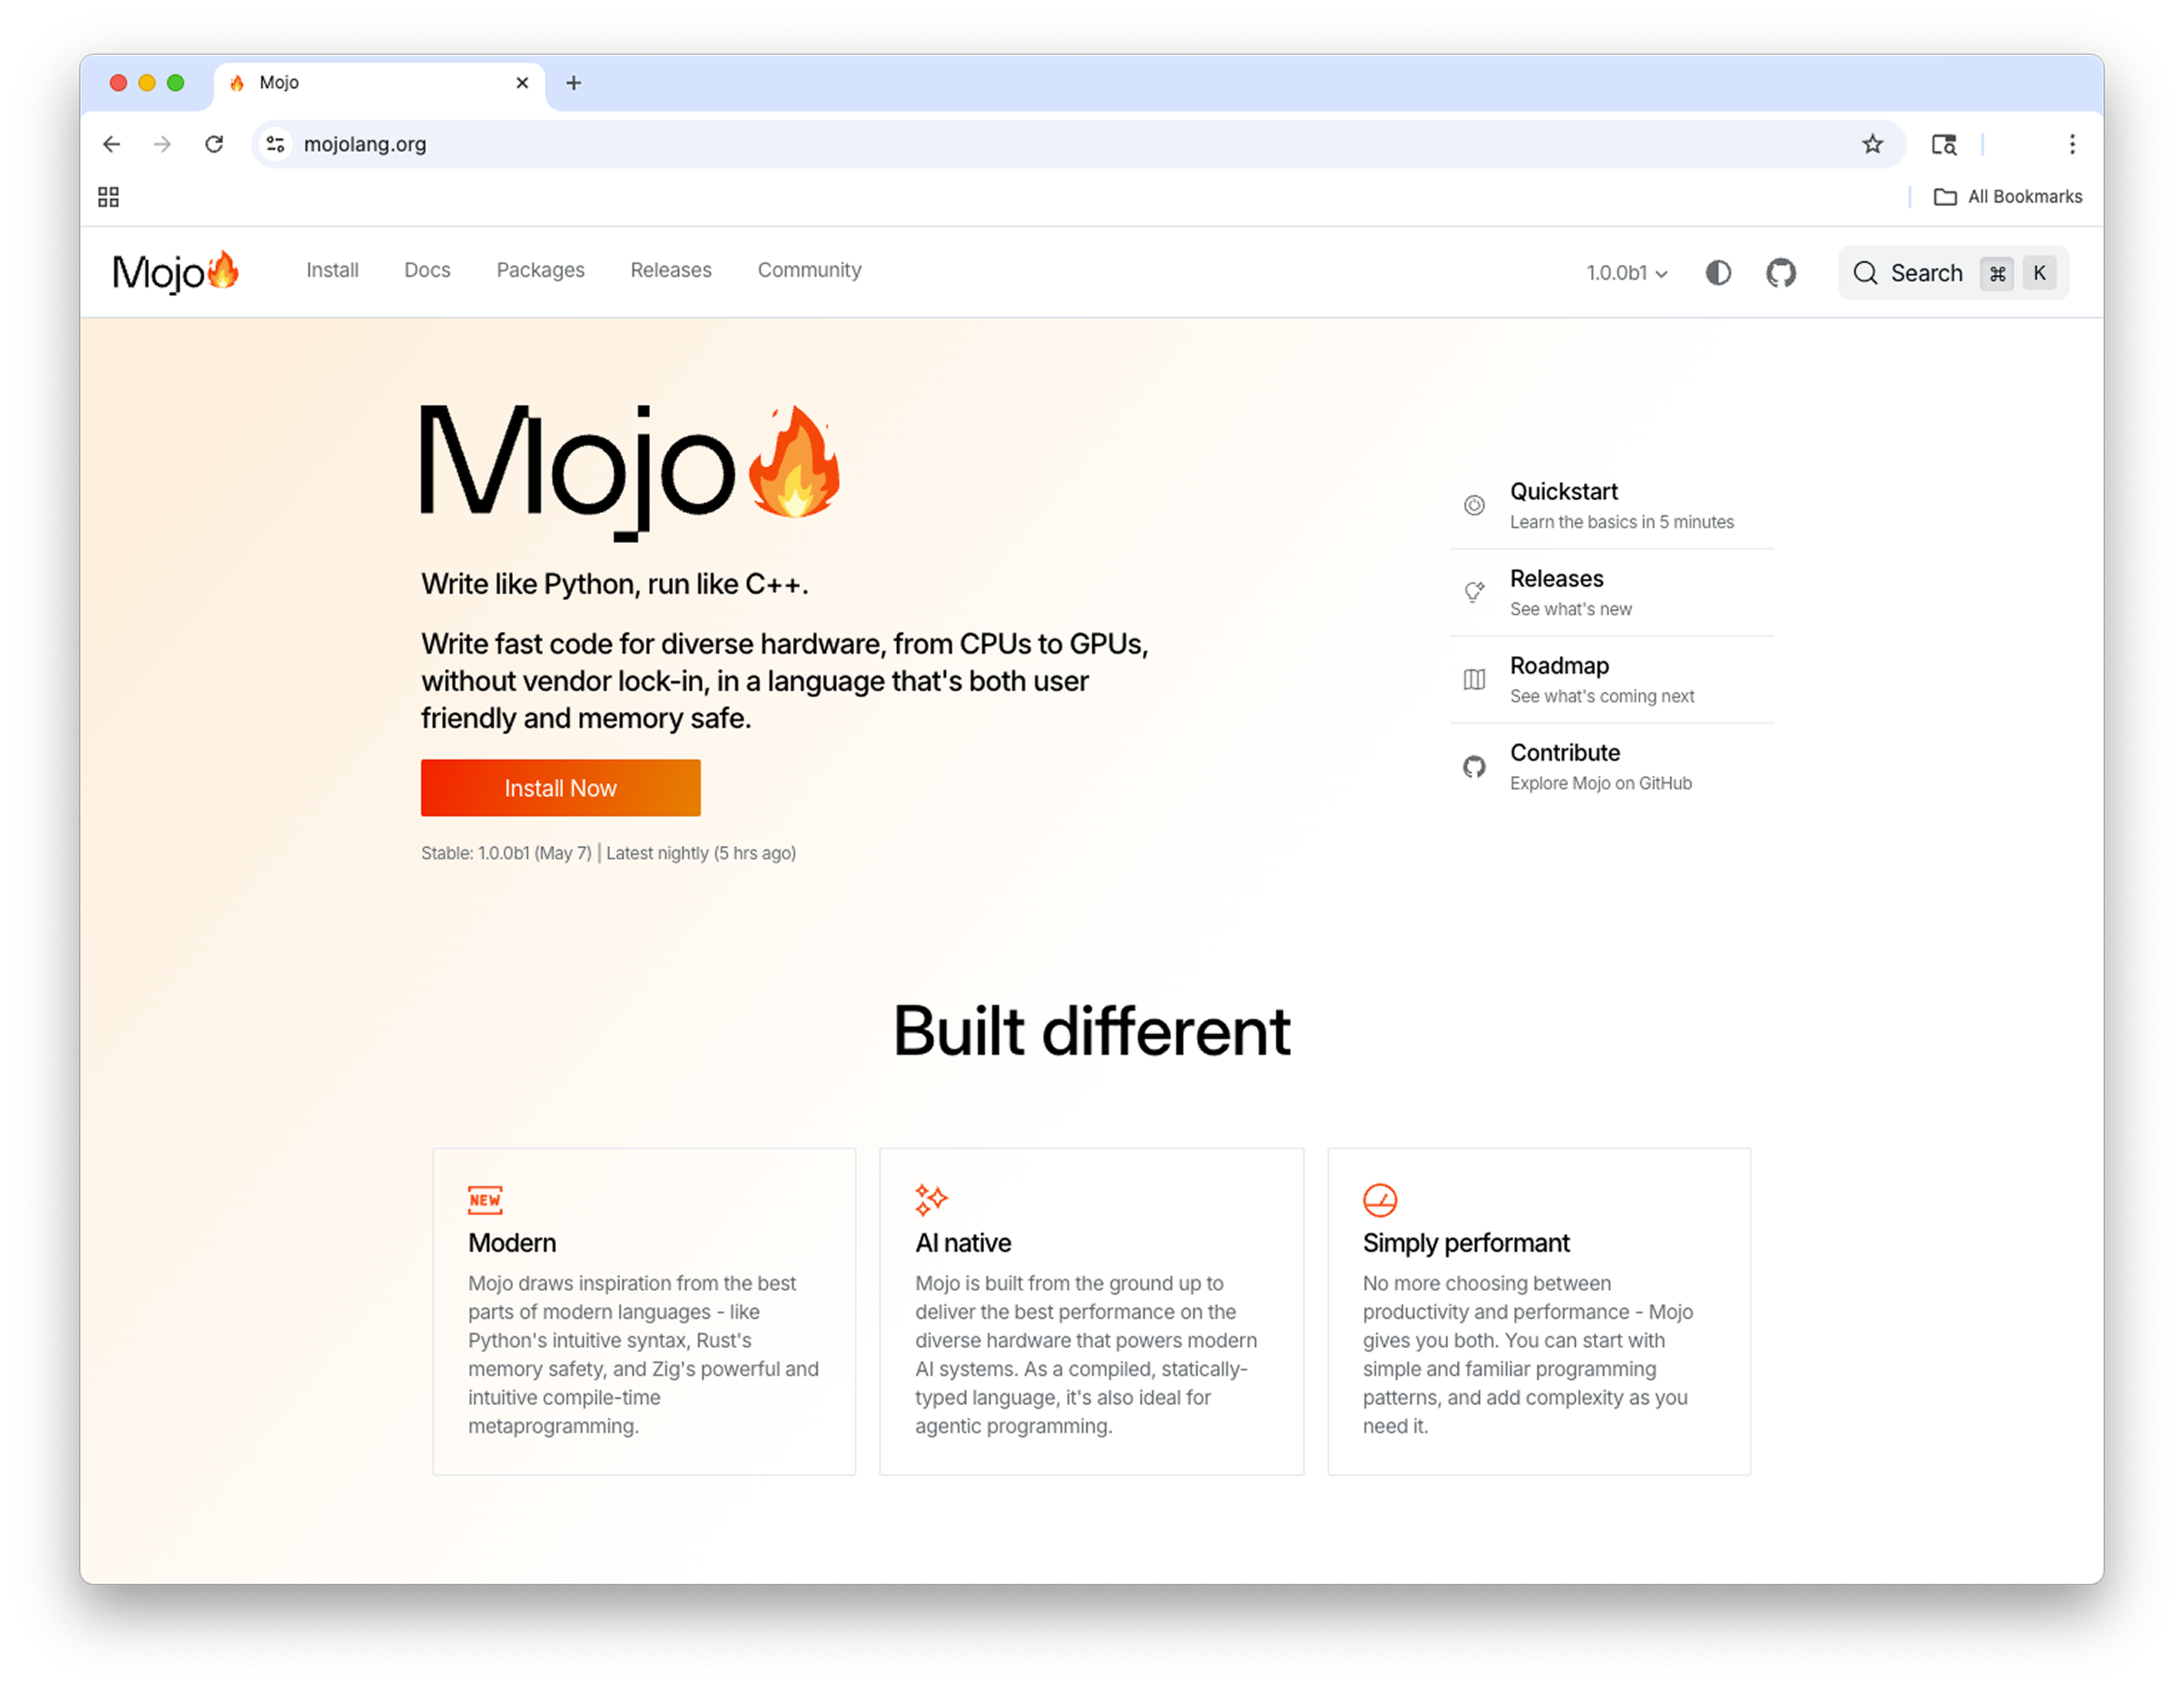
With all the Mojo documentation on its own site, docs.modular.com is now focused on what you need to build and serve models with MAX. You only need Mojo with MAX if you’re extending or building custom kernels, which is why the MAX AI kernels library is still at docs.modular.com. For a full look at all the new Mojo updates that accompany the beta, see the mojolang.org changelog.
It’s not just Mojo that has major updates. We’re adding a new modality to the unified Modular platform: video generation.
We started with text, expanded to audio, added image generation / editing, and with the addition of video generation, if your application needs to move from a static image to a living scene, you no longer need to step outside the Modular Platform to do it.
Today's release brings support for Wan 2.2, one of the leading open video generation models, with many more coming very soon, alongside multiple improvements. Video generation with MAX is available today and will be coming soon to Modular Cloud. If you're building video into your workflow and want to discuss what this means for your infrastructure, contact us.
Real-world models now routinely span multiple GPUs. In 26.3 we've expanded multi-GPU support in max.experimental: a distributed-aware Tensor type, multi-device compilation, and the collective ops you need for tensor-parallel code.
PyTorch's DTensor established that placement metadata on a tensor is the right abstraction for reasoning about distribution. JAX's jax.Array showed how readable a single tensor type plus named mesh axes can be. MAX borrows from both and adds one thing neither has: the same .to(...) call accepts both a NamedMapping (JAX-style "this tensor axis maps to that mesh axis") and a PlacementMapping (DTensor-style Replicated / Sharded / Partial). You pick whichever fits the problem; both lower to the same representation.

The practical result: Tensor is the same type whether it lives on one device or is sharded across a mesh. Sharding is metadata, not a separate code path.
max.experimental a 10-20x faster path for eager execution. In 26.3, we've completed the remaining operator coverage: gather/scatter (embedding lookups, sparse updates), convolution and pooling (ConvOp, MaxPoolOp, AvgPoolOp), arg/search ops (ArgMaxOp, ArgMinOp, TopKOp), data rearrangement (SplitOp, TileOp), and all other previously missing handlers. We’ll further improve this in 26.4.layer_norm, topk, argsort, concat, and pad_constant GPU kernels were tuned; Mojo implementation of the Programming Massively Parallel Processors(PMPP) textbook examples now ship.max benchmark gained a sweep mode (concurrency x request-rate, JSON output), KV connector flags moved into -kv-connector-config, -model-override enables mixed-quant diffusion pipelines, and Float8Config is now QuantConfig (FP8 + NVFP4 + MXFP4).For a full list of changes see the MAX and Mojo changelogs
Modular 26.3 is available now, launching Mojo 1.0 Beta, bringing high-performance video generation to MAX, improving MAX’s developer experience, and simplifying Mojo syntax for closures and memory tiling. Install or upgrade to get started in minutes:
Install or upgrade to get started in minutes:
shell
uv pip install --upgrade modularFor a deeper look at everything included in this release, check out:
If you’re building with Modular, join us on:
We’re excited to hear about what you build with 26.3, and with the Mojo beta.
Share your feedback on the Mojo 1.0 beta:

Sign up today
Signup to our Cloud Platform today to get started easily.
Sign Up

Browse open models
Browse our model catalog, or deploy your own custom model
Browse models
Get all our latest news, announcements and updates delivered directly to your inbox. Unsubscribe at anytime.
Thanks for signing up to our newsletter! 🚀
Thank you,
Modular Sales Team
Oops! Something went wrong while submitting the form.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。