








Probability density function must integrate to 1, and so if you know a density function up to a constant, the constant is determined.
When you’re looking at a probability density f(x) for the first time, it helps to ignore the normalizing constant. Concentrate on the part of the function involving x and know that the normalizing constant is whatever it has to be. For example, about half of the ink that it takes to write down a beta or chi-squared density is devoted to the normalization constant; the rest of the expression is easier to understand.
This post will do the opposite of the advice above and focus on normalization constants because this ties into the previous post on modified Bessel functions.
The von Mises probability distribution on a circle has two parameters, μ and κ, and its density function is
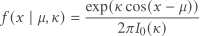
The normalizing constant is 2π I0(κ). The factor of 2π is unsurprising for anything defined on a circle. The more interesting part is I0, the modified Bessel function of order 0.
The von Mises-Fisher distribution is the generalization of the von Mises distribution to a sphere in p dimensions. The density function is
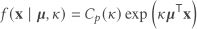
where the normalization constant Cp(κ) is
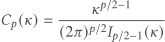
where Ip/2 − 1 is the modified Bessel function of order p/2 − 1. The values of x and μ are in bold face because they are now vectors, points on the unit sphere.
When p = 2, we have the “sphere” in two dimensions, i.e. the circle, and the von Mises-Fisher distribution reduces to the von Mises distribution. But where did the cosine go? The inner product of x and μ is the cosine of the angle between the two vectors.
When p = 3, obviously an important special case, the von Mises-Fisher distribution is known as the Fisher distribution. In that case the normalizing constant C3(κ) can be written without using modified Bessel functions because when ν = ½ + n for an integer n, Iν(x) is an elementary function.