








You tell your AI “Polish my email and send it.”
Same sentence, three outcomes. The gap between Large Action Models (LAMs) and agentic LLMs is one of the most practically important distinctions in AI today, and also one of the least clearly explained.
In this article, we cut through the confusion through a simple breakdown of how each system is built, and a clear guide on when to use which.
An LLM like ChatGPT, Claude, or Gemini is fundamentally a word predictor. It reads context and produces the most useful next token. Its power comes from doing that at a massive scale.
An agentic LLM is the same model placed inside a reasoning loop with tools. It reads a goal, chooses a tool, reads the result, and decides what to do next until the task is complete or something fails. This loop is often called ReAct: reason, act, observe.
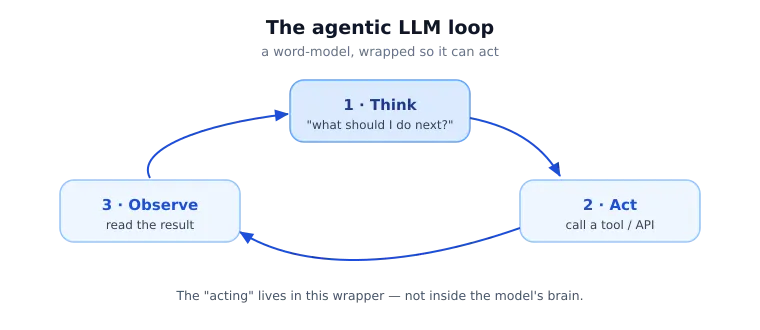
The critical thing to understand is that the model itself hasn’t changed. Strip away the loop, tool definitions, prompts, and orchestration code, and you’re back to a chatbot. The action-taking ability lives in the scaffolding.
That makes the repurposing powerful: the same model can write copy, debug code, or call an API without retraining. But reliability suffers. It can choose the wrong tool, invent parameters, or get stuck in loops. In production, these failures aren’t edge cases. They’re the 2 AM incidents.
Take away the loop and the tools, and an agentic LLM goes right back to being a chatbot. The “doing” lives in the wrapper, not the model.
A LAM approaches the problem differently. Rather than taking a language model and coaxing action-taking out of it, you train a model where producing correct, executable actions is the primary objective from day one.
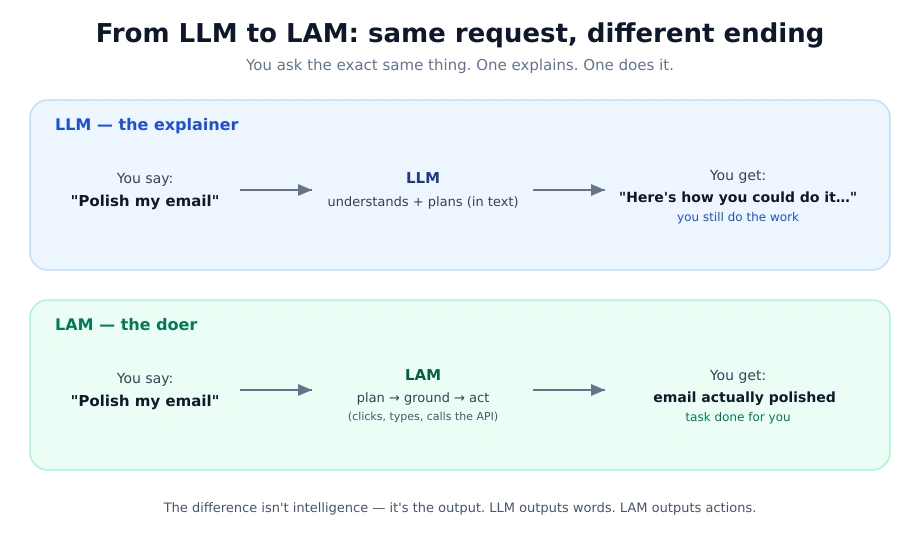
The training data is different. A standard LLM is trained on web-scale text. A LAM is trained on action trajectories: clicks, API calls, UI interactions, and multi-step task completions. Salesforce’s AgentOhana pipeline was built to unify this kind of action data into one training format. The model learns what a good action sequence looks like, not just a good sentence.
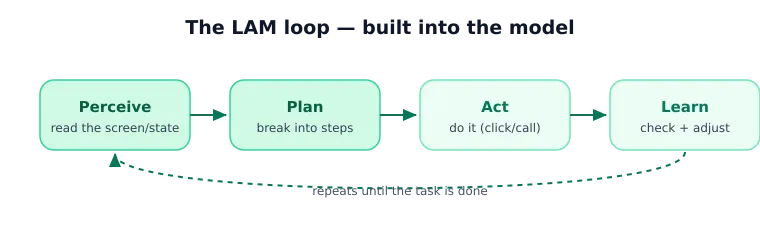
The architecture follows the same goal. Most LAMs use a perceive, plan, act, learn cycle: read the environment, break down the goal, take an action, and update the plan. It resembles the agentic LLM loop, but the behavior is trained into the model rather than bolted on through orchestration code.
Specialization produces surprising efficiency. Salesforce’s xLAM-1B, a 1-billion-parameter model nicknamed the “Tiny Giant,” outperforms GPT-3.5 on function-calling benchmarks while being roughly 175 times smaller. When the training objective matches the deployment task, you don’t need scale to win.
It’s a fair question, and the line genuinely blurs at the edges. An agentic LLM with heavy function-calling fine-tuning can look a lot like a LAM. Some products use “LAM” as a marketing term for what is plainly a wrapped GPT with a few tool definitions.
The meaningful distinction sits in where the action capability originates:
| Agentic LLM | Large Action Model | |
|---|---|---|
| Action capability source | Borrowed from the scaffolding | Trained into the model |
| Remove the wrapper | Get a chatbot | Still an action model |
| The point | Flexibility | Reliability on defined tasks |
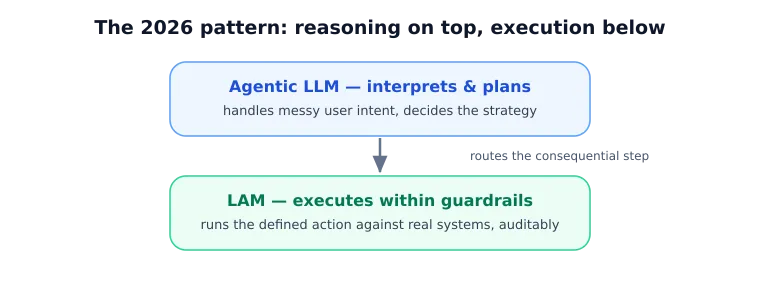
The strongest production systems in 2026 won’t choose between the two. They’ll use an agentic LLM for reasoning and open-ended interpretation, then route high-stakes actions like payments, data changes, or API calls through a guarded LAM.
| Dimension | Agentic LLM | Large Action Model |
|---|---|---|
| Core output | Text (actions extracted from it) | Structured actions, natively |
| Where action capability lives | The orchestration wrapper | The model weights |
| Training data | Web-scale text | Action trajectories + text |
| Typical model size | Large generalist (70B to 1T+) | Often small and specialized (1B to 70B) |
| Strength | Flexibility, reasoning, open tasks | Reliability on bounded action tasks |
| Common failure mode | Wrong tool, hallucinated args, infinite loop | Breaks outside defined action space |
| Real examples | GPT-4o + LangGraph, Claude + CrewAI | Salesforce xLAM, Rabbit R1, Adept ACT-1 |
The practical question is whether the action space is open or closed. If the system’s actions are bounded and known in advance, such as fixed APIs, UI workflows, or business processes, a LAM-style model is usually more reliable, faster, and cheaper per operation.
If the task is open-ended, or needs rich language understanding inside the loop, an agentic LLM gives you more flexibility.
Reach for an Agentic LLM when:
Reach for a LAM when:
Q1. Is a LAM just a fine-tuned LLM?
A. No. A LAM is trained primarily for action generation using trajectory data, with different data formats, objectives, and optimization targets.
Q2. Can I build a working agent without a LAM?
A. Yes. Most production agents use general LLMs with orchestration. LAMs help when reliability, cost, latency, or constrained deployment becomes a problem.
Q3. Are LAMs always smaller than LLMs?
A. No. Some small LAMs outperform larger LLMs on action tasks, but LAMs can also be large, like xLAM-70B.
Q4. Which should a team new to agents start with?
A. Start with an agentic LLM. The tooling is mature, iteration is faster, and the same agent-building patterns still apply later.
Q5. Do LAMs make agentic LLMs obsolete?
A. No. Strong production systems often use both: LAMs for reliable bounded execution and agentic LLMs for broader reasoning.
Hi , I am Sree Vamsi a passionate Data Science enthusiast currently working at Analytics Vidhya. My journey into data science began with a curiosity for uncovering insights from complex data and has evolved into building end-to-end Generative AI applications, RAG pipelines, agentic AI workflows, and multi-agent systems that solve real-world business problems.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。