







Your cloud security posture is decided in code long before anything is deployed. Whether a storage bucket is public, an IAM role has wildcard permissions, or a production database is properly encrypted and isolated l is defined in Terraform, OpenTofu, CloudFormation, or Kubernetes manifests days before the resources actually exist. Infrastructure-as-code (IaC) governance is how you control what those files are allowed to say.
Most security teams still spend their energy on the running environment, scanning what’s already deployed, and filing tickets after the fact.
By the time one of those findings lands, the misconfiguration has shipped, and the offending module may have been copied into multiple other projects because it worked. Rather than fixing one public bucket, you end up chasing a pattern that keeps reproducing itself.
If you own whether the cloud is safe, you own the code that builds it, so governing that code is part of your job now.
This playbook covers how to manage that deliberately: the four pillars to stand up, how to sequence them when everything feels urgent, the metrics that prove it’s working, and the mistakes that are easy to make the first time through.
What we’ll cover:
Infrastructure-as-code governance is the set of controls that ensure the code your team writes produces infrastructure that’s secure, compliant, and matches what you intended, both before it deploys and after:
Infrastructure-as-code governance is the set of controls that ensure the code your team writes produces infrastructure that’s secure, compliant, and matches what you intended, both before it deploys and after:
The reason this belongs to security rather than sitting with the platform team alone comes down to where the risk is created.
When infrastructure was provisioned by hand, security could inspect the result and catch problems in the environment. Now the risky decision, the wildcard IAM policy or the disabled logging, could have been made in a text file that a developer merged on a random afternoon.
A review process that only looks at running infrastructure is inspecting too late. Everything you care about, least privilege, encryption, network segmentation, data residency, is expressed in that code first.
There’s a practical reason too. Developers move fast with IaC, which is the whole point of it.
I remember building VM templates and golden images back in the VMware days, sure that pre-baking a machine was going to make deployments quick. It helped, but you were still cloning a template and then hand-tweaking each one afterward. IaC is at a different level. A single module can stand up a whole environment, network and all, in the time it used to take to configure one server, and then get reused across dozens of projects.
That same speed applies to mistakes. A bad pattern written once and shared through a module registry becomes a bad pattern in every environment that pulls it. Catching it in the code, one time, is worth far more than catching it in 50 running environments later.
The playbook has four pillars. They build on each other, so the order matters, but you’ll end up running all four on an ongoing basis rather than finishing one and moving on.
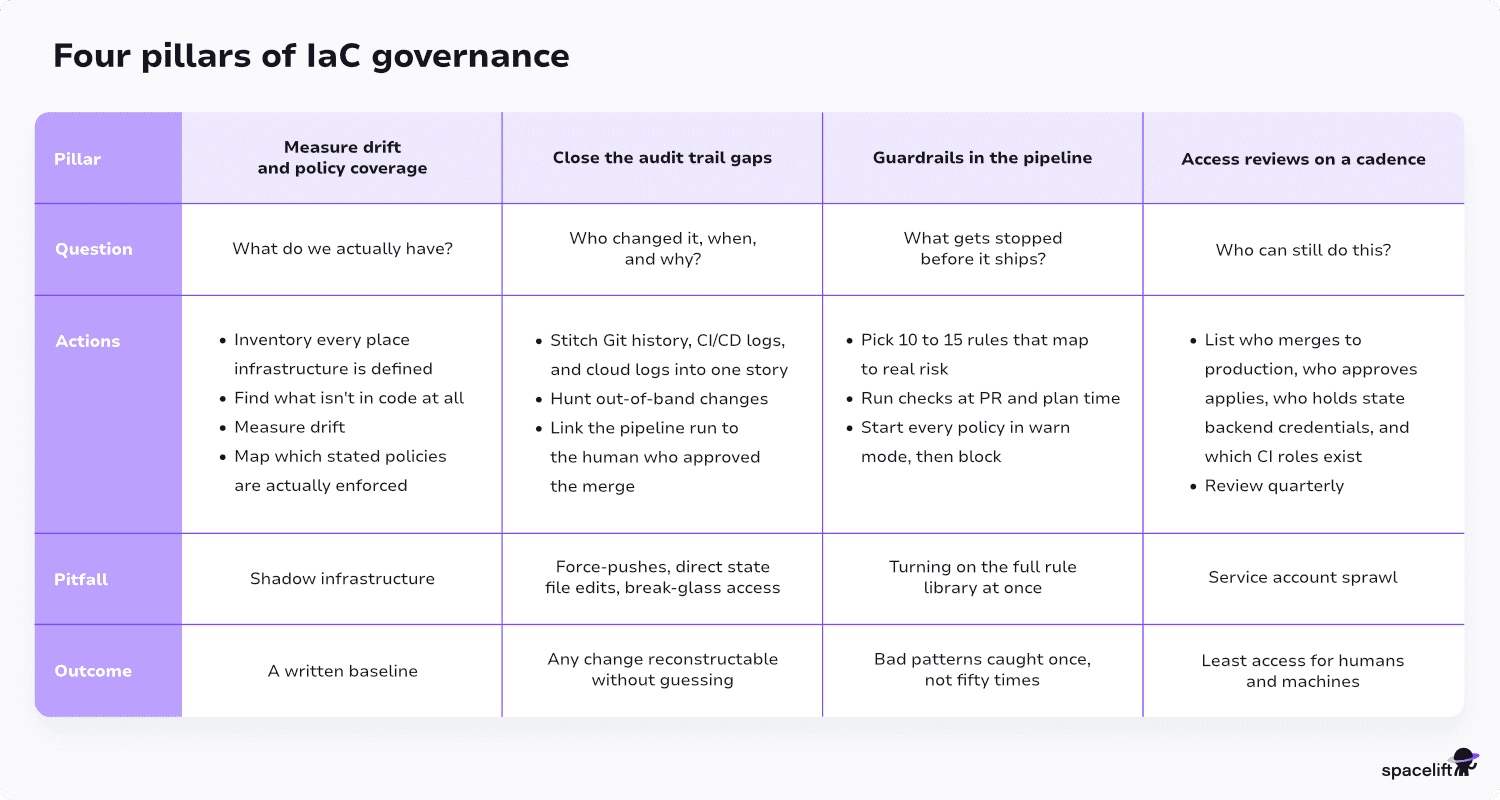
You can’t govern infrastructure you can’t see, and most environments have more of it than the team thinks. Start with an honest inventory.
First, find every place infrastructure gets defined. That means the obvious Terraform and CloudFormation repos, but also the Helm charts, the Kubernetes manifests, the Pulumi projects someone on the data team started, and the CDK app that only one person understands.
Then find the infrastructure that isn’t in code at all. That includes the resources someone spun up in the console during an incident and never backported, the account a contractor set up two years ago, and the S3 bucket attached to a demo that quietly went to production. This shadow infrastructure is where a lot of the real risk hides because none of your governance touches it.
Second, measure drift. Drift is the gap between what your code says should exist and what actually exists in the cloud right now. Someone may have edited a security group by hand to unblock a deploy, forgot to update the Terraform, and now the code lies about reality.
Run a plan or a drift detection pass across your managed infrastructure and see how far off you are. The number is usually worse than people expect, and it tells you how much you can actually trust your code as a source of truth.
Third, map your policy coverage. Take the security rules your organization already claims to follow, encryption at rest, no public data stores, mandatory tagging, approved regions only, and check which of them any tool is actually enforcing on your IaC today.
Most teams find that a handful of rules are covered by some scanner and the rest live in a wiki page nobody reads. That gap is your backlog.
Write all of this down. The point of the assessment is a concrete picture: Here’s what’s in code, here’s what isn’t, here’s how much drift we’re carrying, here’s which policies we enforce and which we only wish we did. Every later decision gets easier once you have that picture.
Once you know what exists, the next question an auditor or an incident responder will ask is who changed it, when, and why.
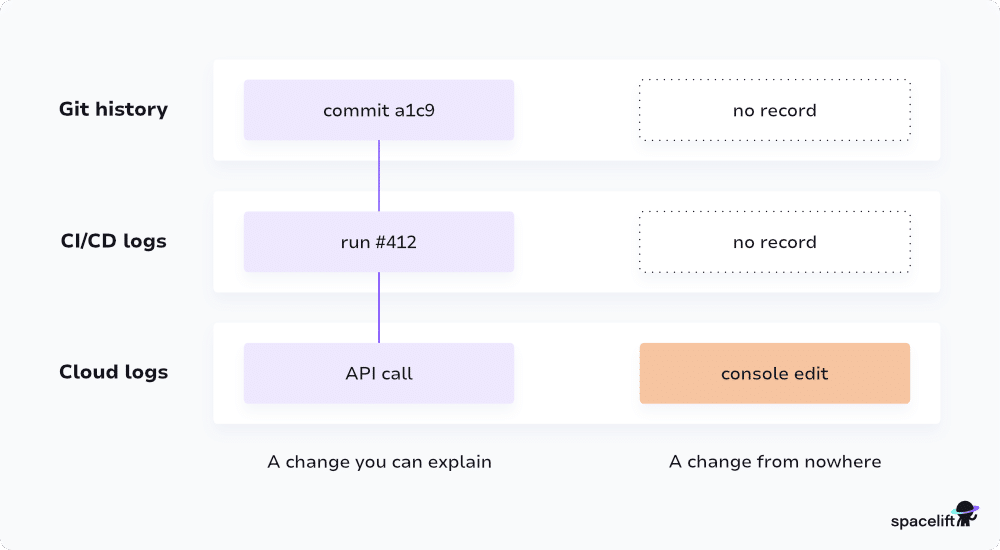
In a mature IaC setup, you can answer that from three sources stitched together: the Git history of the code, the CI/CD logs that show what was applied and by whom, and the cloud provider’s own record, such as CloudTrail or Azure Activity Log. When those line up, you have a clean story for every change.
The gaps are where they don’t line up. The most common one is the out-of-band change: someone with console access modifies a resource directly, so there’s a CloudTrail entry but no matching Git commit and no pipeline run.
From an audit standpoint, that change came from nowhere. Track these down and either bring them into code or take away the access that allowed them.
Then there’s the attribution problem. Pipelines usually apply changes through a service account or a CI role, which means your cloud logs show “terraform-ci made 400 changes” with no link back to the person who approved the merge.
Closing that gap means correlating the pipeline run to the pull request to the person who clicked approve. Some teams pass commit metadata through to the apply step so the trail stays connected; at minimum, make sure the pipeline logs are retained as long as the cloud logs and that you can join them on a run ID.
A few more holes are worth a look:
For each, decide what a complete record looks like and close the distance between that and what you have now. Don’t worry about forensic perfection. You need to be able to reconstruct any change without guessing.
This is the pillar people jump to first, and it works better once the first two are done because now you know which policies to write and you can trust your code enough to enforce them.
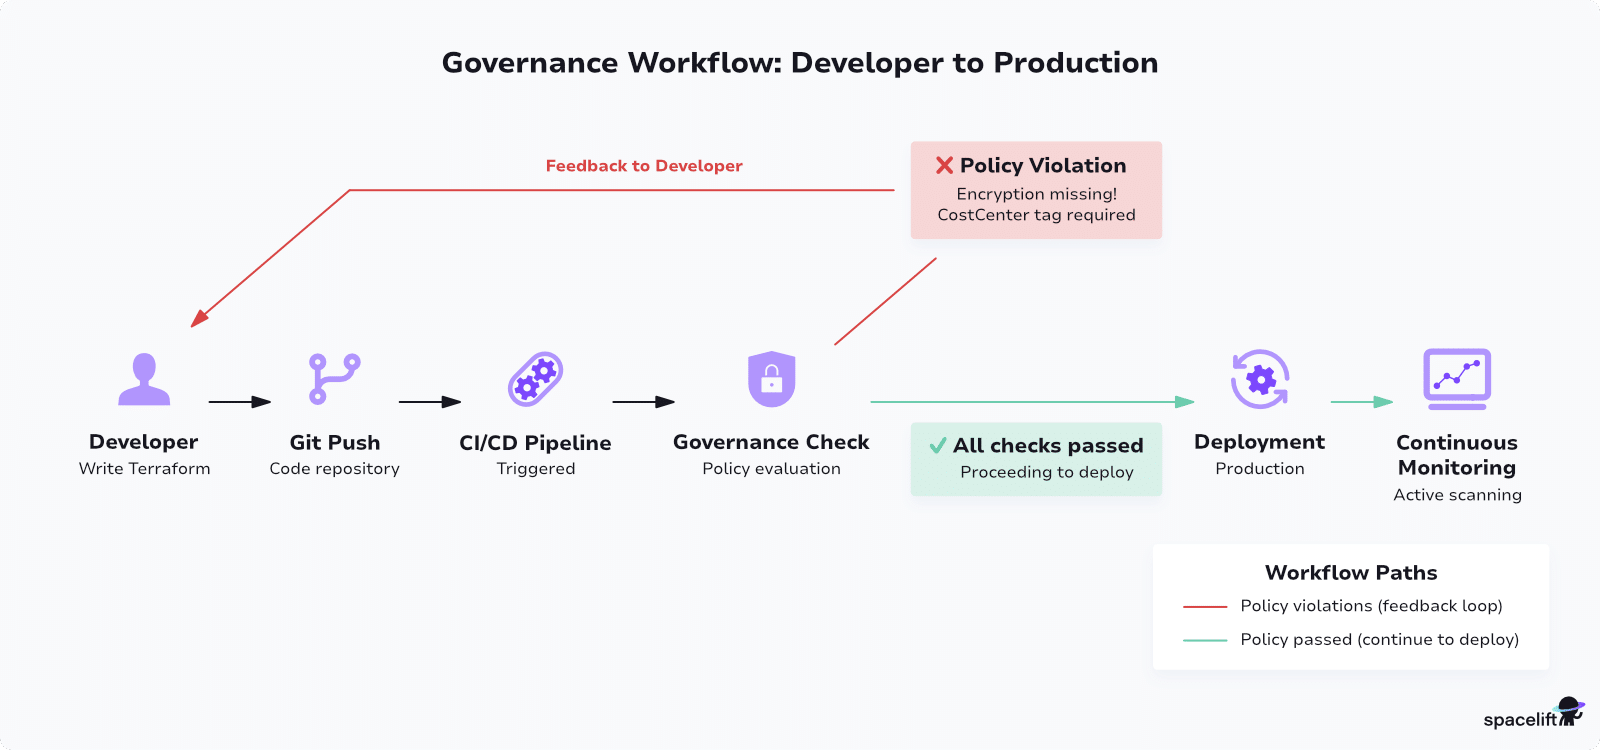
Policy as code means your security rules live in a machine-readable form that runs automatically against your infrastructure code.
The tooling splits roughly into:
Two decisions shape how this actually works.
The first is where in the flow the check runs. You can run scanners at pre-commit for fast feedback on the developer’s machine, as a required status check on every pull request, at plan time so you’re evaluating the real change set, and as a hard gate on the apply step. Earlier catches problems sooner; later is harder to bypass. Most teams end up running checks at more than one of these points.
The second decision is preventive versus detective, meaning whether a failed policy blocks the change or just records it. Blocking is stronger, and it’s also how you turn your developers against the whole program if you get it wrong. My recommendation is to start every new policy in warn mode.
Let it run for a few weeks, see what it flags, fix the false positives and the legitimate existing violations, and only then flip it to blocking. A policy that blocks a deploy at 5 pm on a Friday over something the developer considers a non-issue is a policy that gets an exception carved out by Monday.
Resist the urge to turn on the scanner’s entire rule library at once. A tool that fires two hundred findings on the first run teaches everyone to ignore it. Pick the ten or 15 rules that map to the risks you actually care about, the ones from your coverage gap in pillar one, get those clean and enforced, then expand from there once the team trusts the checks.
The first three pillars govern the code and the infrastructure. This one governs the people, and it’s the pillar that quietly rots if you leave it alone, because access only ever accumulates.
Make a list of who can do what across the whole IaC supply chain:
Service account sprawl deserves special attention because it’s invisible in day-to-day work. A pipeline role created for one project gets reused for the next, picks up a few more permissions each time, and a year later, it can do almost anything with no human attached to it.
These are exactly the identities an attacker wants, and they rarely show up in a normal access review aimed at employees.
Set a real cadence, quarterly is a reasonable default, and treat it as a recurring commitment rather than a project. In each review, confirm that every person and every machine identity still needs the access it has, and pull back anything that’s grown past what’s needed. Where your tooling supports it, lean on just-in-time access for the high-privilege paths so that standing admin access shrinks toward zero and elevation becomes a logged, temporary event.
The goal is that no individual or machine carries more power than their current work requires.
Run the assessment from pillar one and you’ll surface more problems than you can fix this quarter. Public buckets, over-permissive roles, missing encryption, unmanaged accounts, stale service credentials, all competing for the same attention. The instinct to fix everything at once is how programs stall.
Rank by two things: how much damage an issue could do, and how easy it is to exploit right now.
Blast radius times likelihood is a crude formula, and it’s good enough to sort a messy backlog into an order you can defend.
The pillars have their own sequence:
Don’t forget to weight anything that gets reused. A bad pattern in a shared module or a base image propagates, so fixing it once removes risk everywhere it’s been pulled in. A one-off misconfiguration in a single environment is contained by definition. Given two issues of similar severity, fix the reusable one first. Its blast radius is still growing.
You’ll need to show progress, to yourself and to whoever funds this work. A few numbers track the health of the program better than others, and they’re worth building into a dashboard early.
Policy coverage is the percentage of your defined security rules that a tool actually enforces on IaC. This is the direct measure of pillar one’s gap closing over time. Watch it climb as you convert wiki-page rules into enforced checks.
Drift is worth two numbers:
If both trend down, your code is becoming a trustworthy source of truth. If they’re flat or rising, changes are still happening outside your pipeline, and that sends you back to the audit and access pillars.
The share of infrastructure changes that flow through IaC, rather than through the console, tells you whether people are actually using the governed path. If a large fraction of change still happens by hand, every other control has a hole in it, because your guardrails only apply to code. Getting this number up is often more valuable than adding another policy.
On the pipeline itself, track two more:
One caution. The total number of findings is a vanity number that mostly reflects how many rules you turned on, so it’s easy to make it look good or bad without changing anything real. Focus on coverage, drift, and the percentage of change that goes through the governed path. Those move only when the program actually improves.
A handful of mistakes show up again and again for people taking this on for the first time. Knowing them ahead of time is cheaper than learning them live:
Spacelift is the infrastructure orchestration platform that manages the full lifecycle for both traditional infrastructure as code and AI-provisioned infrastructure, supporting tools like OpenTofu, Terraform, Ansible, Pulumi, Kubernetes, and CloudFormation.
Security is one of Spacelift’s top priorities, with features such as policy as code, encryption, Single Sign-On (SSO), MFA, and private worker pools built into the product. Spacelift is SOC 2 Type II audited and provides compliance and security artifacts, including GDPR resources and its DPA, through the Spacelift Trust Center.
It is also the first IaC orchestration platform to receive FedRAMP authorization, delivering flexible, policy-driven automation to federal agencies and contractors seeking secure, compliant infrastructure workflows.
The power of Spacelift lies in its fully automated approach. Once you’ve created a Spacelift stack for your project, changes to the infrastructure as code files in your repository are automatically applied to your infrastructure.
For non-critical workloads like tests, POCs, and demos, Spacelift Intelligence adds an AI-powered layer that enables natural language provisioning, diagnostics, and operational insight, so developers can request infrastructure without writing configuration code while platform teams retain full governance and visibility.
Spacelift’s pull request integrations keep everyone informed of what will change by displaying which resources are going to be affected by new merges. Spacelift also allows you to enforce policies and automated compliance checks that prevent dangerous oversights from occurring.
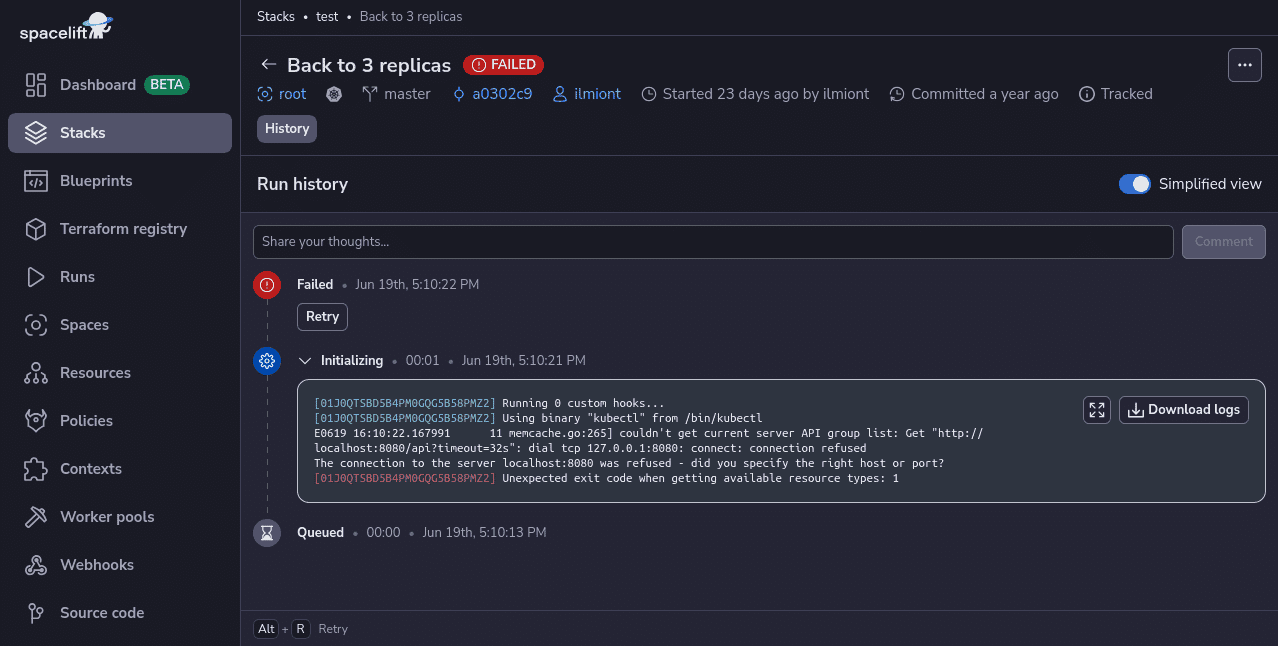
Spacelift includes drift detection capabilities that periodically check your infrastructure for discrepancies compared to your repository’s state. It can then launch reconciliation jobs to restore the correct state, ensuring your infrastructure operates predictably and reliably.
With Spacelift, you also get:
If you want to learn more about Spacelift, create a free account today or book a demo with one of our engineers.
If you take one thing from this, it’s that the security decisions you care about now get made in code, so that’s where your controls have to live. See what you actually have before you buy anything, enforce a small set of rules well before you reach for a big set, restrict people and machines to the least access they need, and track coverage and drift instead of raw finding counts. Every pillar in the playbook is a version of that same move.
The part that’s easy to forget is that none of this is a finish line. Infrastructure code changes every day, so governance is something you run continuously rather than complete.
The teams that make it stick are the ones who turn the governed path into the easiest path, so that for the developer shipping at 5 pm on a Friday, the secure choice is also the low-effort one. Get that right and most of the rest takes care of itself.
IaC governance is the framework of policies, controls, and processes that keep infrastructure code aligned with security, compliance, and operational standards across its lifecycle. It typically combines policy as code, access controls, peer reviews, and automated scanning to enforce guardrails before changes reach production.
Most teams run drift detection daily or continuously in production, with weekly scans as a minimum baseline for lower-risk environments. Regulated or high-change infrastructure benefits from near real-time monitoring through platforms like Spacelift.
Not explicitly. SOC 2 requires periodic access reviews under CC6.2 and CC6.3, but leaves the cadence to the organization based on risk. Quarterly reviews are the industry standard for privileged access, while semi-annual or annual reviews are still accepted for lower-risk populations.
Retention depends on the applicable framework: PCI DSS 4.0 requires 12 months (with 3 months immediately queryable), HIPAA effectively 6 years, and SOX 7 years. Most organizations default to at least 12 months, extending further for regulated workloads.
Policy as code defines organizational rules (naming conventions, approved regions, tagging, cost limits) as executable logic enforced during infrastructure changes. IaC scanning analyzes Terraform, CloudFormation, or similar templates for known security misconfigurations and vulnerabilities, typically against benchmarks like CIS or NIST.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。