惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

G
Google Developers Blog
F
Fortinet All Blogs
Microsoft Azure Blog
腾讯CDC
Vercel News
Vercel News
Recent Announcements
博客园 - Franky
小众软件
小众软件
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
The Cloudflare Blog
宝玉的分享
宝玉的分享
I
InfoQ
博客园 - 聂微东
Jina AI
Jina AI
J
Java Code Geeks
V
V2EX
U
Unit 42
Stack Overflow Blog
Stack Overflow Blog
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
Cyber Security Advisories - MS-ISAC
阮一峰的网络日志
阮一峰的网络日志
L
LangChain Blog
T
The Blog of Author Tim Ferriss
量子位

ByteByteGo Newsletter

Why An LLM’s Memory Gets Expensive and How to Fix It LLM Security Basics: The Full Threat Model Hiring: Part Time Instructor, Write Production Grade Code with AI A Detailed Guide to Idempotency, Delivery Semantics, and Deduplication How ChatGPT Optimizes its Agent Loop: Harness, API, and Inference Why DoorDash, Instacart, and Uber Eats Integrated LLMs Into Search Three Different Ways How NVIDIA Builds Open Models for the Age of AI A Beginner’s Guide to Clocks, Causality, and Ordering in Distributed Systems Best Practices for Building AI Agents That Work in Production Inside Roblox’s Bet on World Models MCP vs A2A vs ACP: How AI Agents Actually Talk to Each Other A Guide to Multi-Tenancy: Benefits and Challenges AI Customer Support at Scale: The Travel Industry’s $Billion Bet How LLMs Learn to Be Helpful (RLHF vs DPO) How Microsoft Ships AI Agents at Enterprise Scale EP221: How Docker Works Under the Hood LAST CALL FOR ENROLLMENT: Become an AI Engineer - Cohort 7 The Agent Loop: How AI Goes From Answering Questions to Doing Things ChatGPT vs Gemini vs Claude: How They Differ LAST CALL FOR ENROLLMENT: Become an AI Engineer - Cohort 7 Proof of Human: How to Verify a Person Is Real and Unique Multi-Region Architecture: Going Global Without Going Broke How OpenAI Delivers Low-Latency Voice AI for 900M Users Inside Thinking Machines’ Interaction Models How AI Agents Manage Memory and Avoid Forgetfulness EP220: RAG vs Graph RAG vs Agentic RAG Top Anti-Patterns to Avoid in Service Architecture Large Language Models vs Small Language Models An Ex-Meta L8’s Agentic Engineering Setup AI-Native Leaders: The Organizational Playbook for Engineering Transformation at Scale
Streaming vs Batch: Two Philosophies of Data Processing
ByteByteGo · 2026-07-09 · via ByteByteGo Newsletter

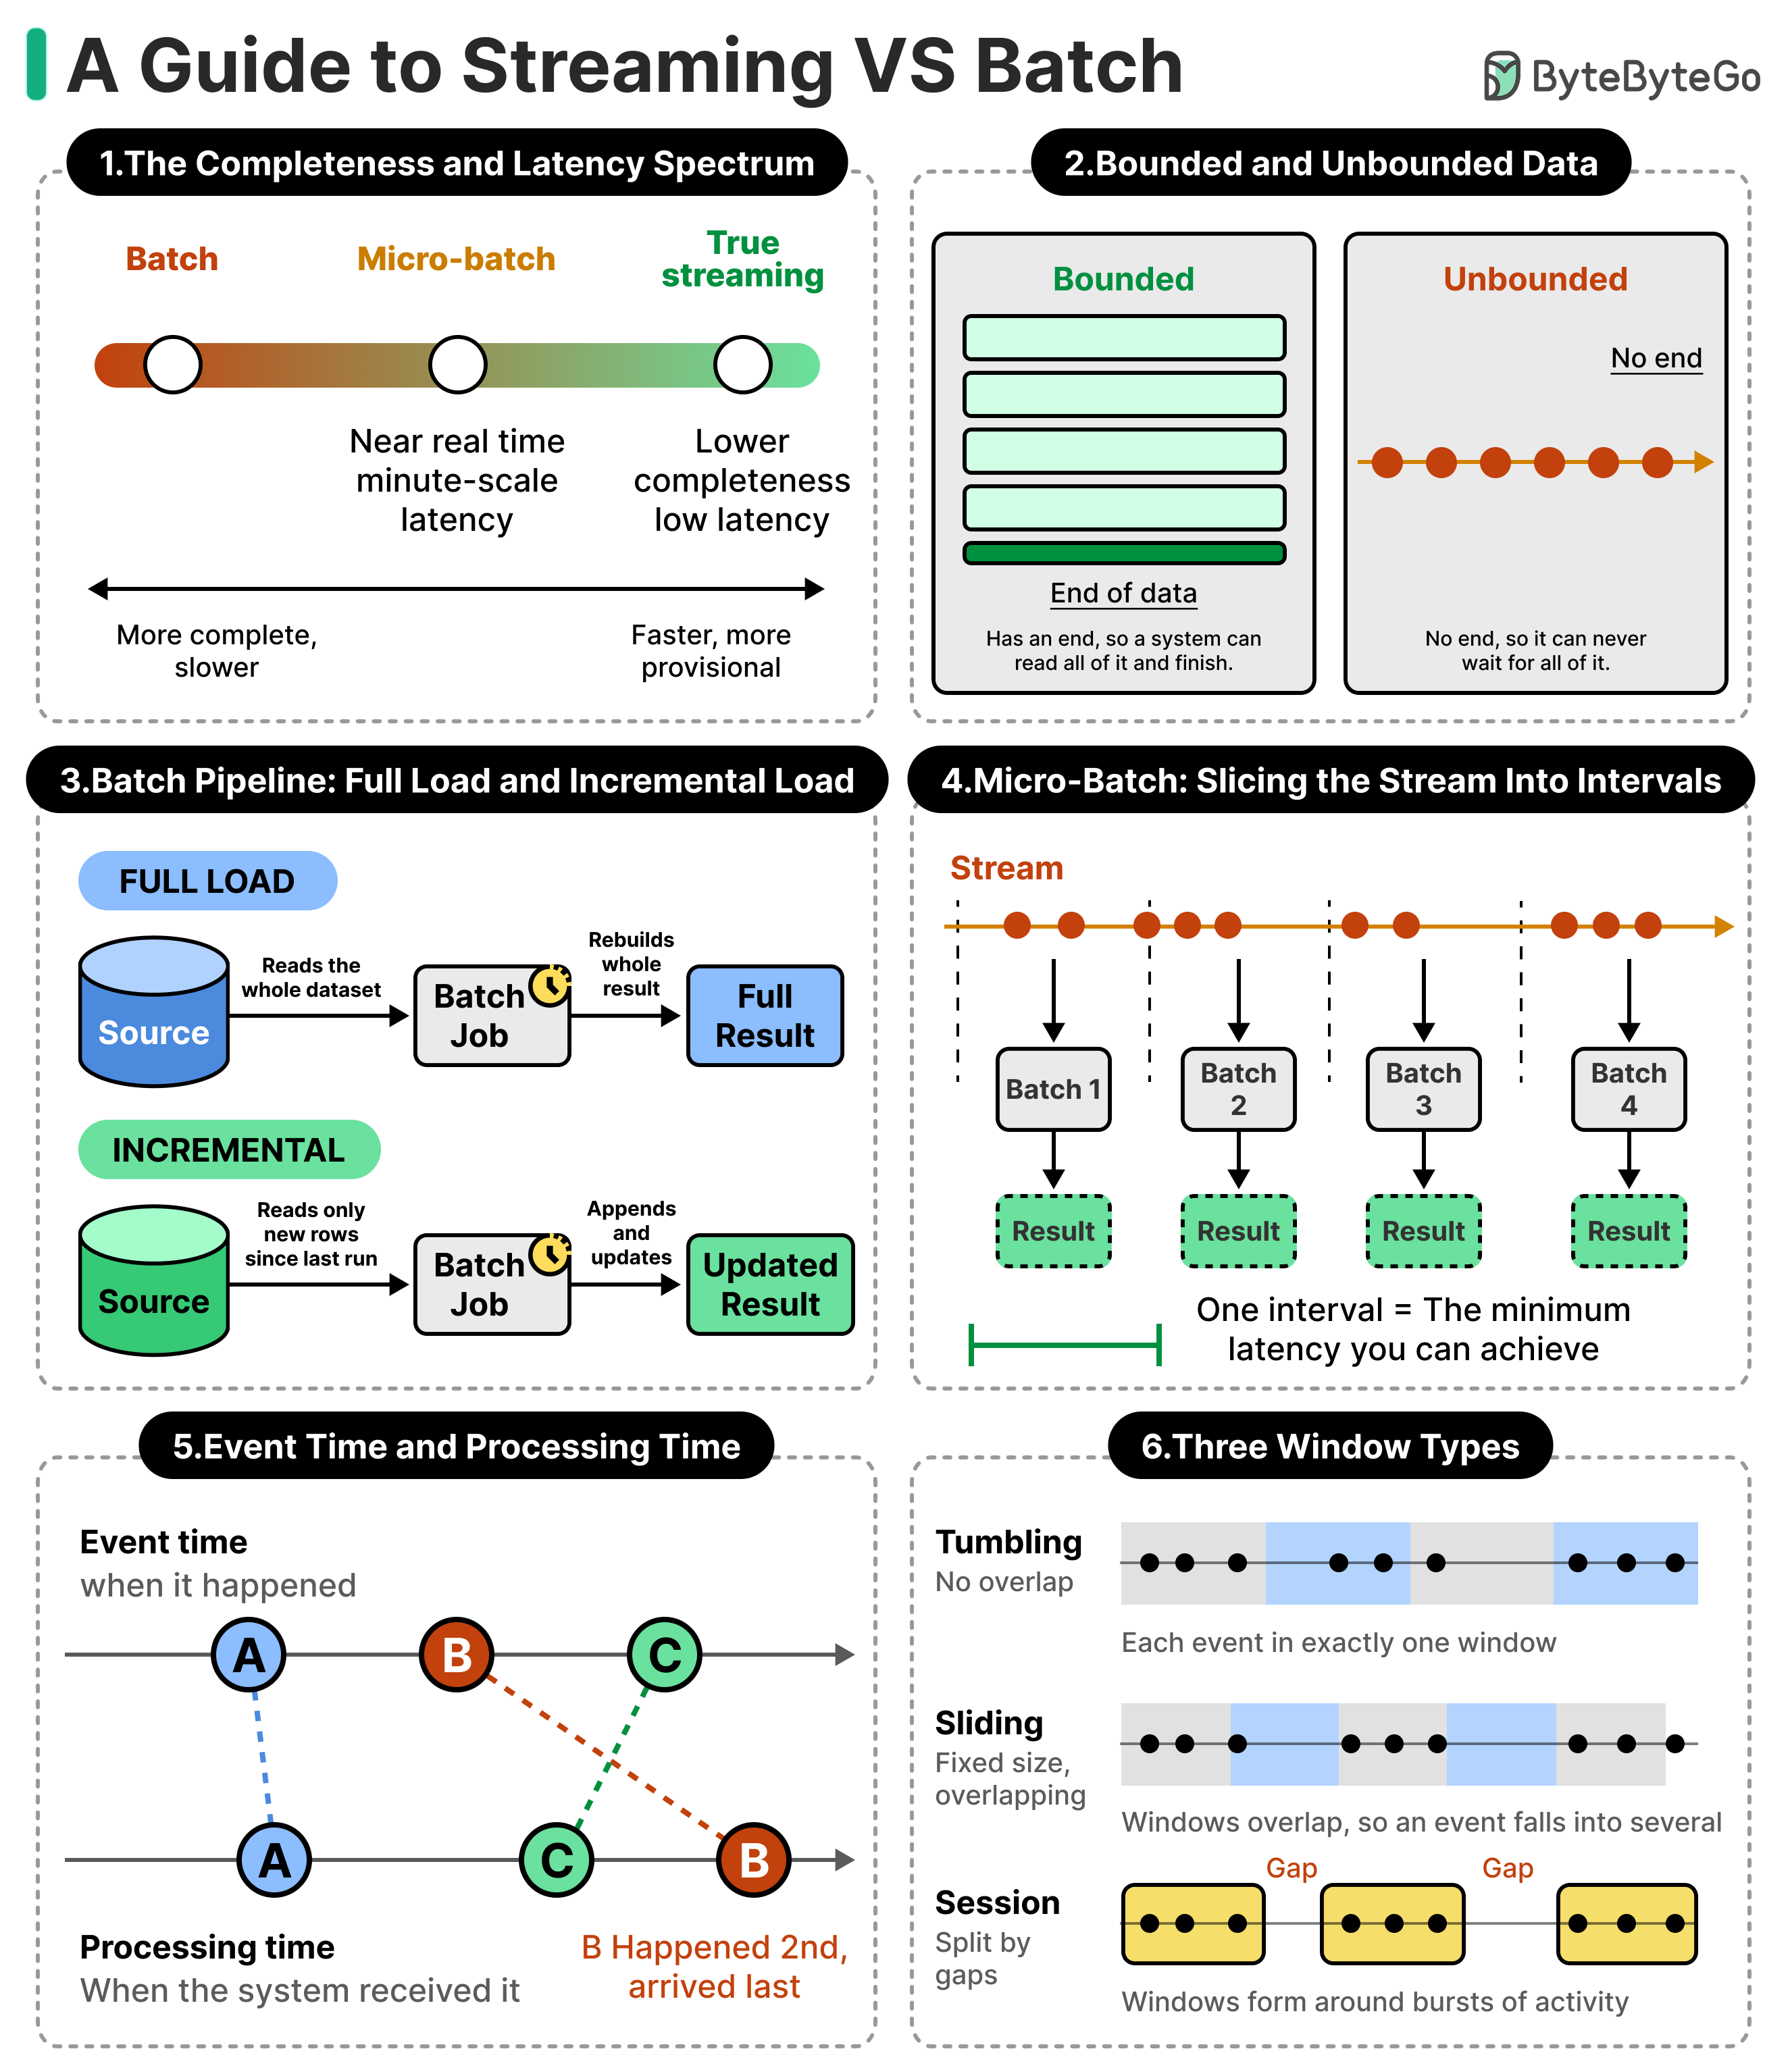
Every system that processes data eventually has to answer one question. When is the data complete enough to be moved to the compute stage?

A program adding up a day’s sales needs to know whether all of today’s sales have actually arrived. For data stored in a file, the answer is trivial because the file has an end. However, for data that arrives continuously and never stops, there is no clean answer, and how a system resolves that gap is the difference between batch processing and streaming.

Batch processing waits for completeness. It collects data up to a natural boundary, a closing time, or a finished file, and then computes over the whole set at once. Streaming prioritizes completeness for speed. It produces answers continuously from data that is still arriving, which means it has to estimate when enough data has come in and handle the cases where that estimate is wrong. This trade-off between completeness and latency is the key consideration when dealing with streaming and batch.
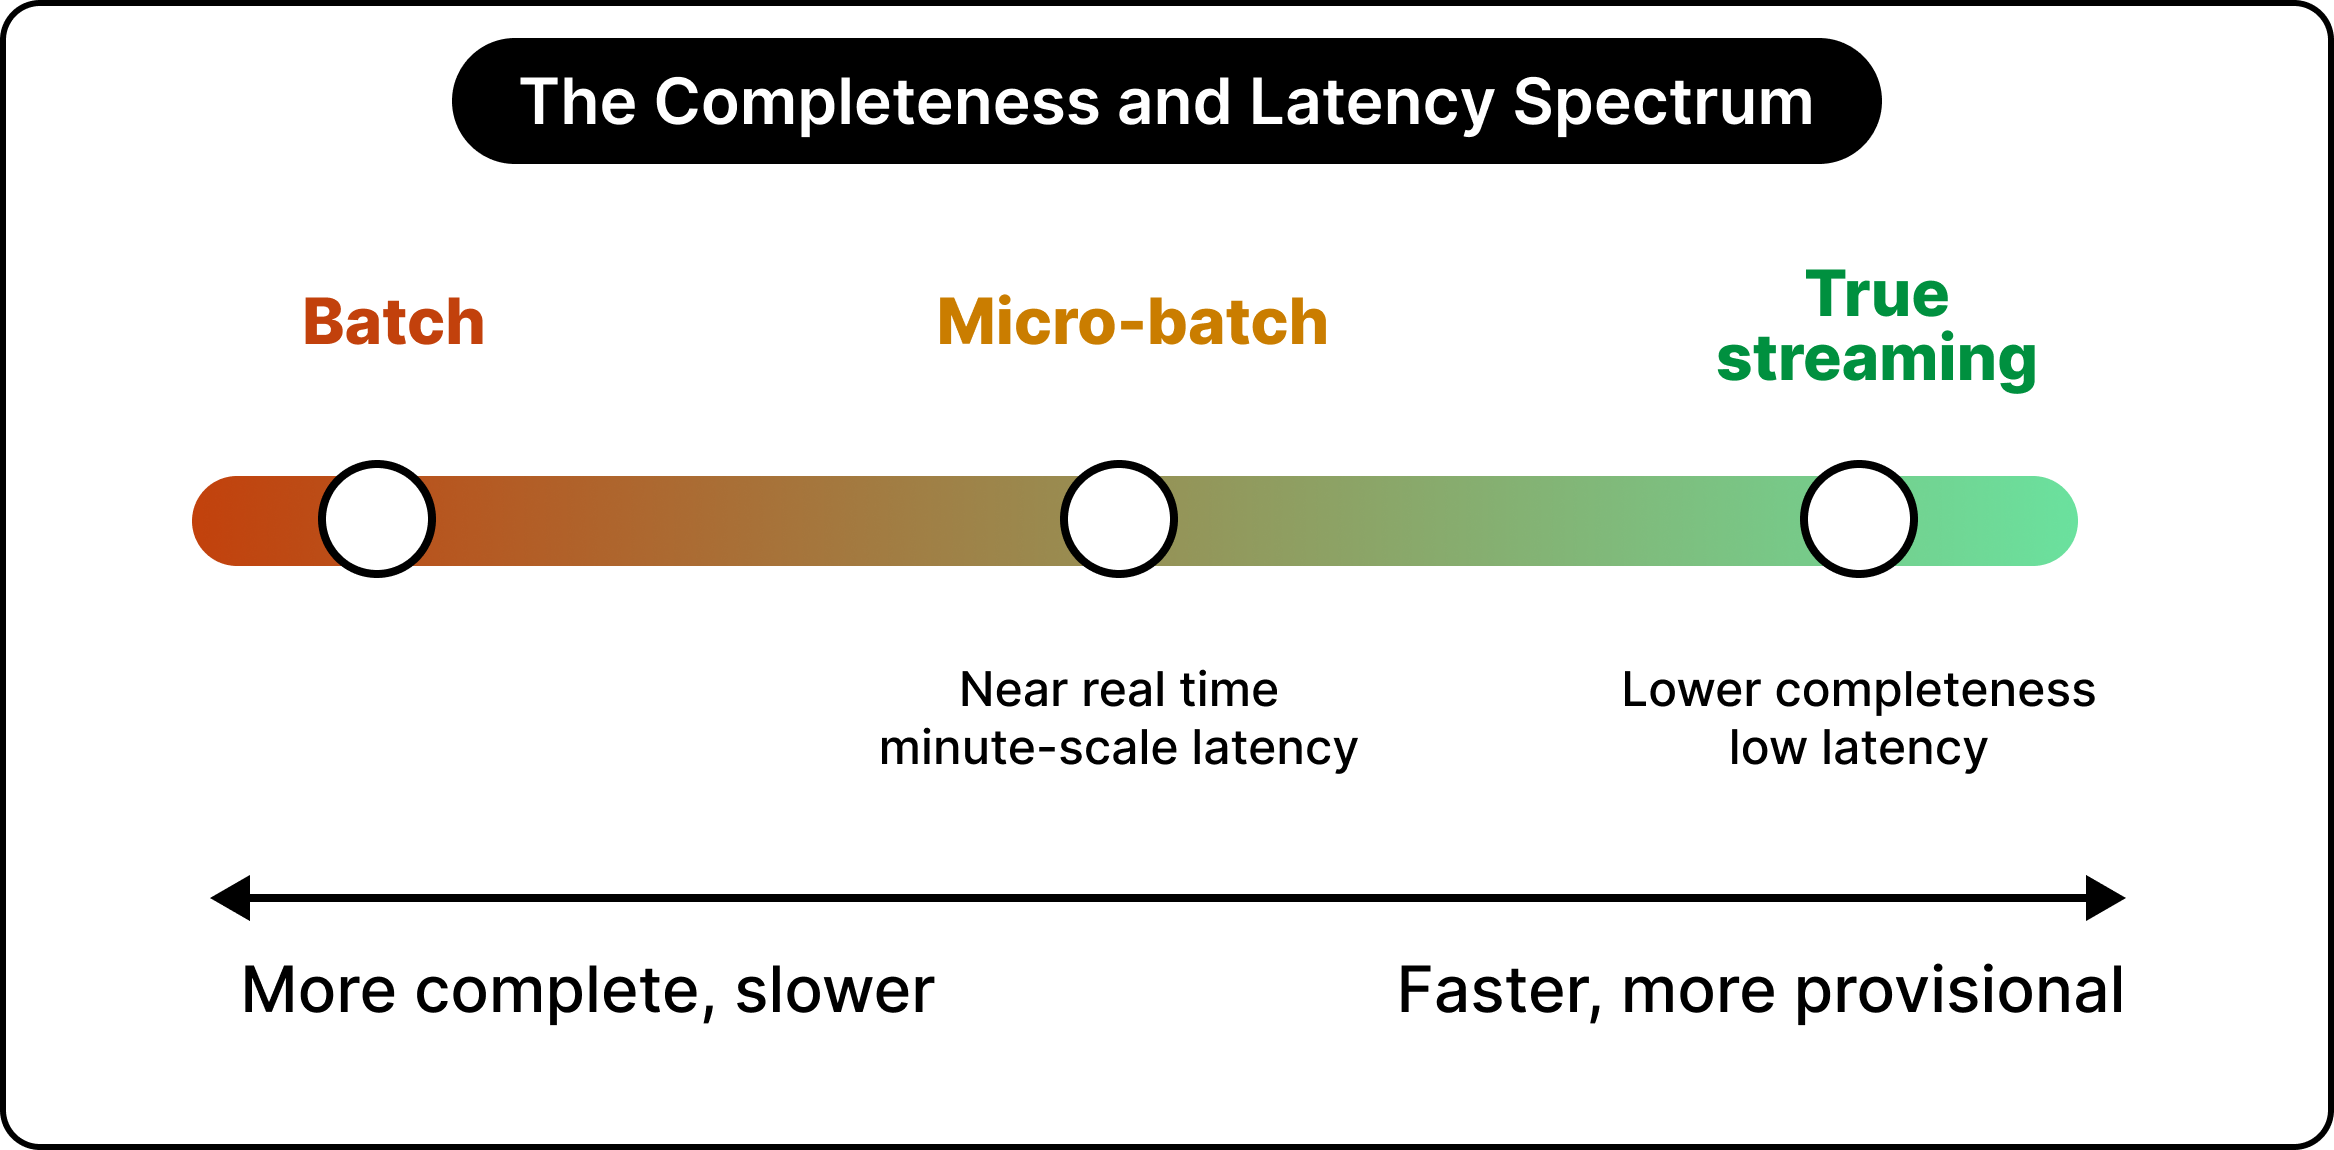
In this article, we will cover the strategies on each side and what each one costs.

  • On the batch side, that means full and incremental loads and large-window aggregation, with micro-batch sitting in between.

  • On the streaming side, the territory runs through tumbling, sliding, and session windows, watermarks and late data, the lambda and kappa architectures, and the often-misunderstood meaning of exactly-once processing.