惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

L
LangChain Blog
博客园 - 司徒正美
美团技术团队
Martin Fowler
Martin Fowler
雷峰网
雷峰网
aimingoo的专栏
aimingoo的专栏
博客园 - 三生石上(FineUI控件)
Vercel News
Vercel News
酷 壳 – CoolShell
酷 壳 – CoolShell
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
爱范儿
爱范儿
U
Unit 42
Y
Y Combinator Blog
月光博客
月光博客
Hugging Face - Blog
Hugging Face - Blog
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
有赞技术团队
有赞技术团队
GbyAI
GbyAI
H
Help Net Security
量子位
Last Week in AI
Last Week in AI
博客园_首页
腾讯CDC
小众软件
小众软件

ByteByteGo Newsletter

Why An LLM’s Memory Gets Expensive and How to Fix It LLM Security Basics: The Full Threat Model Hiring: Part Time Instructor, Write Production Grade Code with AI A Detailed Guide to Idempotency, Delivery Semantics, and Deduplication How ChatGPT Optimizes its Agent Loop: Harness, API, and Inference Why DoorDash, Instacart, and Uber Eats Integrated LLMs Into Search Three Different Ways How NVIDIA Builds Open Models for the Age of AI A Beginner’s Guide to Clocks, Causality, and Ordering in Distributed Systems Best Practices for Building AI Agents That Work in Production Inside Roblox’s Bet on World Models MCP vs A2A vs ACP: How AI Agents Actually Talk to Each Other A Guide to Multi-Tenancy: Benefits and Challenges AI Customer Support at Scale: The Travel Industry’s $Billion Bet How LLMs Learn to Be Helpful (RLHF vs DPO) How Microsoft Ships AI Agents at Enterprise Scale EP221: How Docker Works Under the Hood LAST CALL FOR ENROLLMENT: Become an AI Engineer - Cohort 7 Streaming vs Batch: Two Philosophies of Data Processing The Agent Loop: How AI Goes From Answering Questions to Doing Things ChatGPT vs Gemini vs Claude: How They Differ LAST CALL FOR ENROLLMENT: Become an AI Engineer - Cohort 7 Proof of Human: How to Verify a Person Is Real and Unique How OpenAI Delivers Low-Latency Voice AI for 900M Users Inside Thinking Machines’ Interaction Models How AI Agents Manage Memory and Avoid Forgetfulness EP220: RAG vs Graph RAG vs Agentic RAG Top Anti-Patterns to Avoid in Service Architecture Large Language Models vs Small Language Models An Ex-Meta L8’s Agentic Engineering Setup AI-Native Leaders: The Organizational Playbook for Engineering Transformation at Scale
Multi-Region Architecture: Going Global Without Going Broke
ByteByteGo · 2026-07-02 · via ByteByteGo Newsletter

When an application grows geographically, it is logical to start serving it from a second region to improve latency and availability. However, adding a second region to an application can make it slower and less reliable than it was with one.

That runs against the instinct, which says more locations should mean faster service and steadier uptime, which is often the case. But once the same data lives in two places at once, a new class of problem appears that can nullify the advantages of multi-region deployments.

Let’s look at a short example. Picture two edits to the same piece of data, made at nearly the same instant, one handled by a server on the US East Coast and one by a server in Frankfurt, right as the network link between those regions drops. Both edits are saved locally. Each region now holds a different version of that data, with no shared record of which one came first. When the link comes back, one of the two versions has to be chosen over the other. The way a system handles that question has a large effect on what a global footprint costs to build and to run.

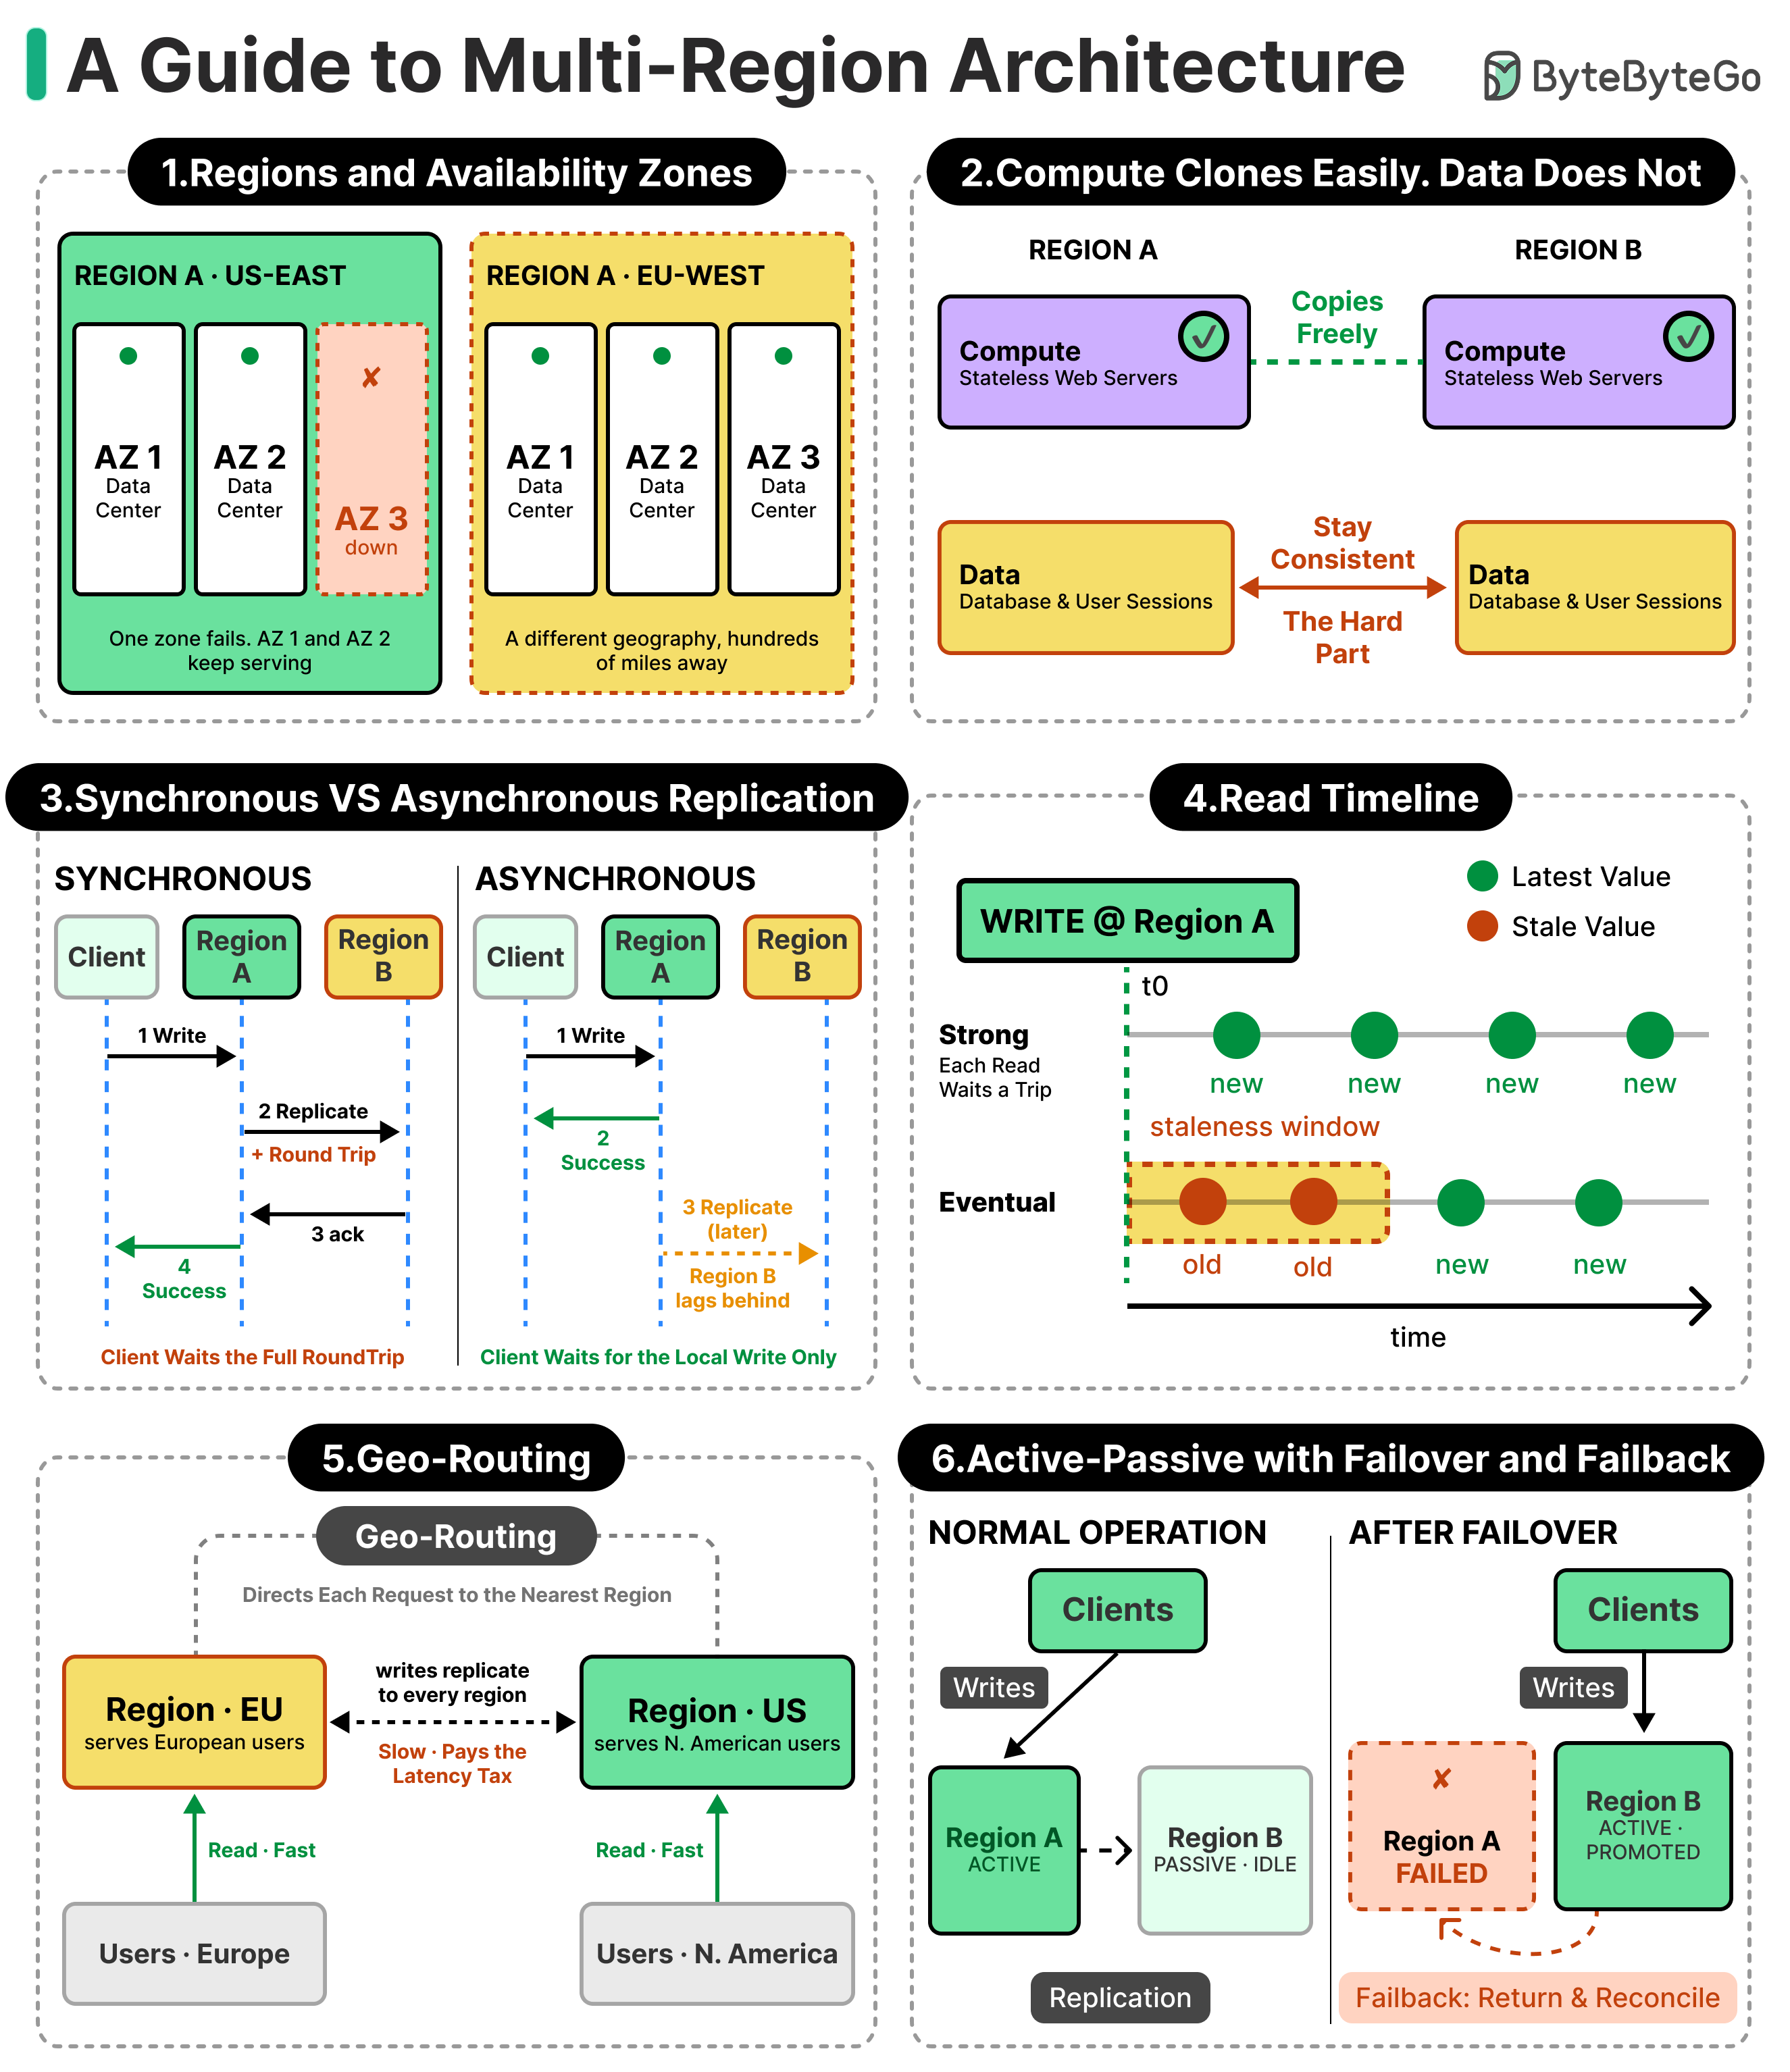
Going global is better understood as a progression than as a single decision. In this article, we will start with the building blocks, the small set of concepts every regional design rests on, then work through the common setups in order, from a single region with backups up to running every region at once. Each step buys something concrete: lower latency, higher availability, or the ability to keep data inside a country’s borders. Each one also has a price, in money and in the consistency tradeoffs it introduces.