





This week’s system design refresher:
AI for Engineering Leaders: Course Direction Survey
What is a Data Lakehouse? (Youtube video)
How the JVM Works
Figma Design to Code, Code to Design: Clearly Explained
12 AI Papers that Changed Everything
How Load Balancers Work?
Optimistic locking vs pessimistic locking
We are working on a course, AI for Engineering Leaders, and would appreciate your help with a quick survey.
Before we build it, we want to get it right, so we’re asking the people who would actually take it. If you’re an EM, Tech Lead, Director, or VP of Engineering, I’d love 3 minutes of your time. This quick survey covers questions like: how do you evaluate engineers when AI writes most of the code? What metrics still matter? Where do AI tools actually help versus just add noise?
Your answers will directly shape what we cover. Thank you!
We compile, run, and debug Java code all the time. But what exactly does the JVM do between compile and run?
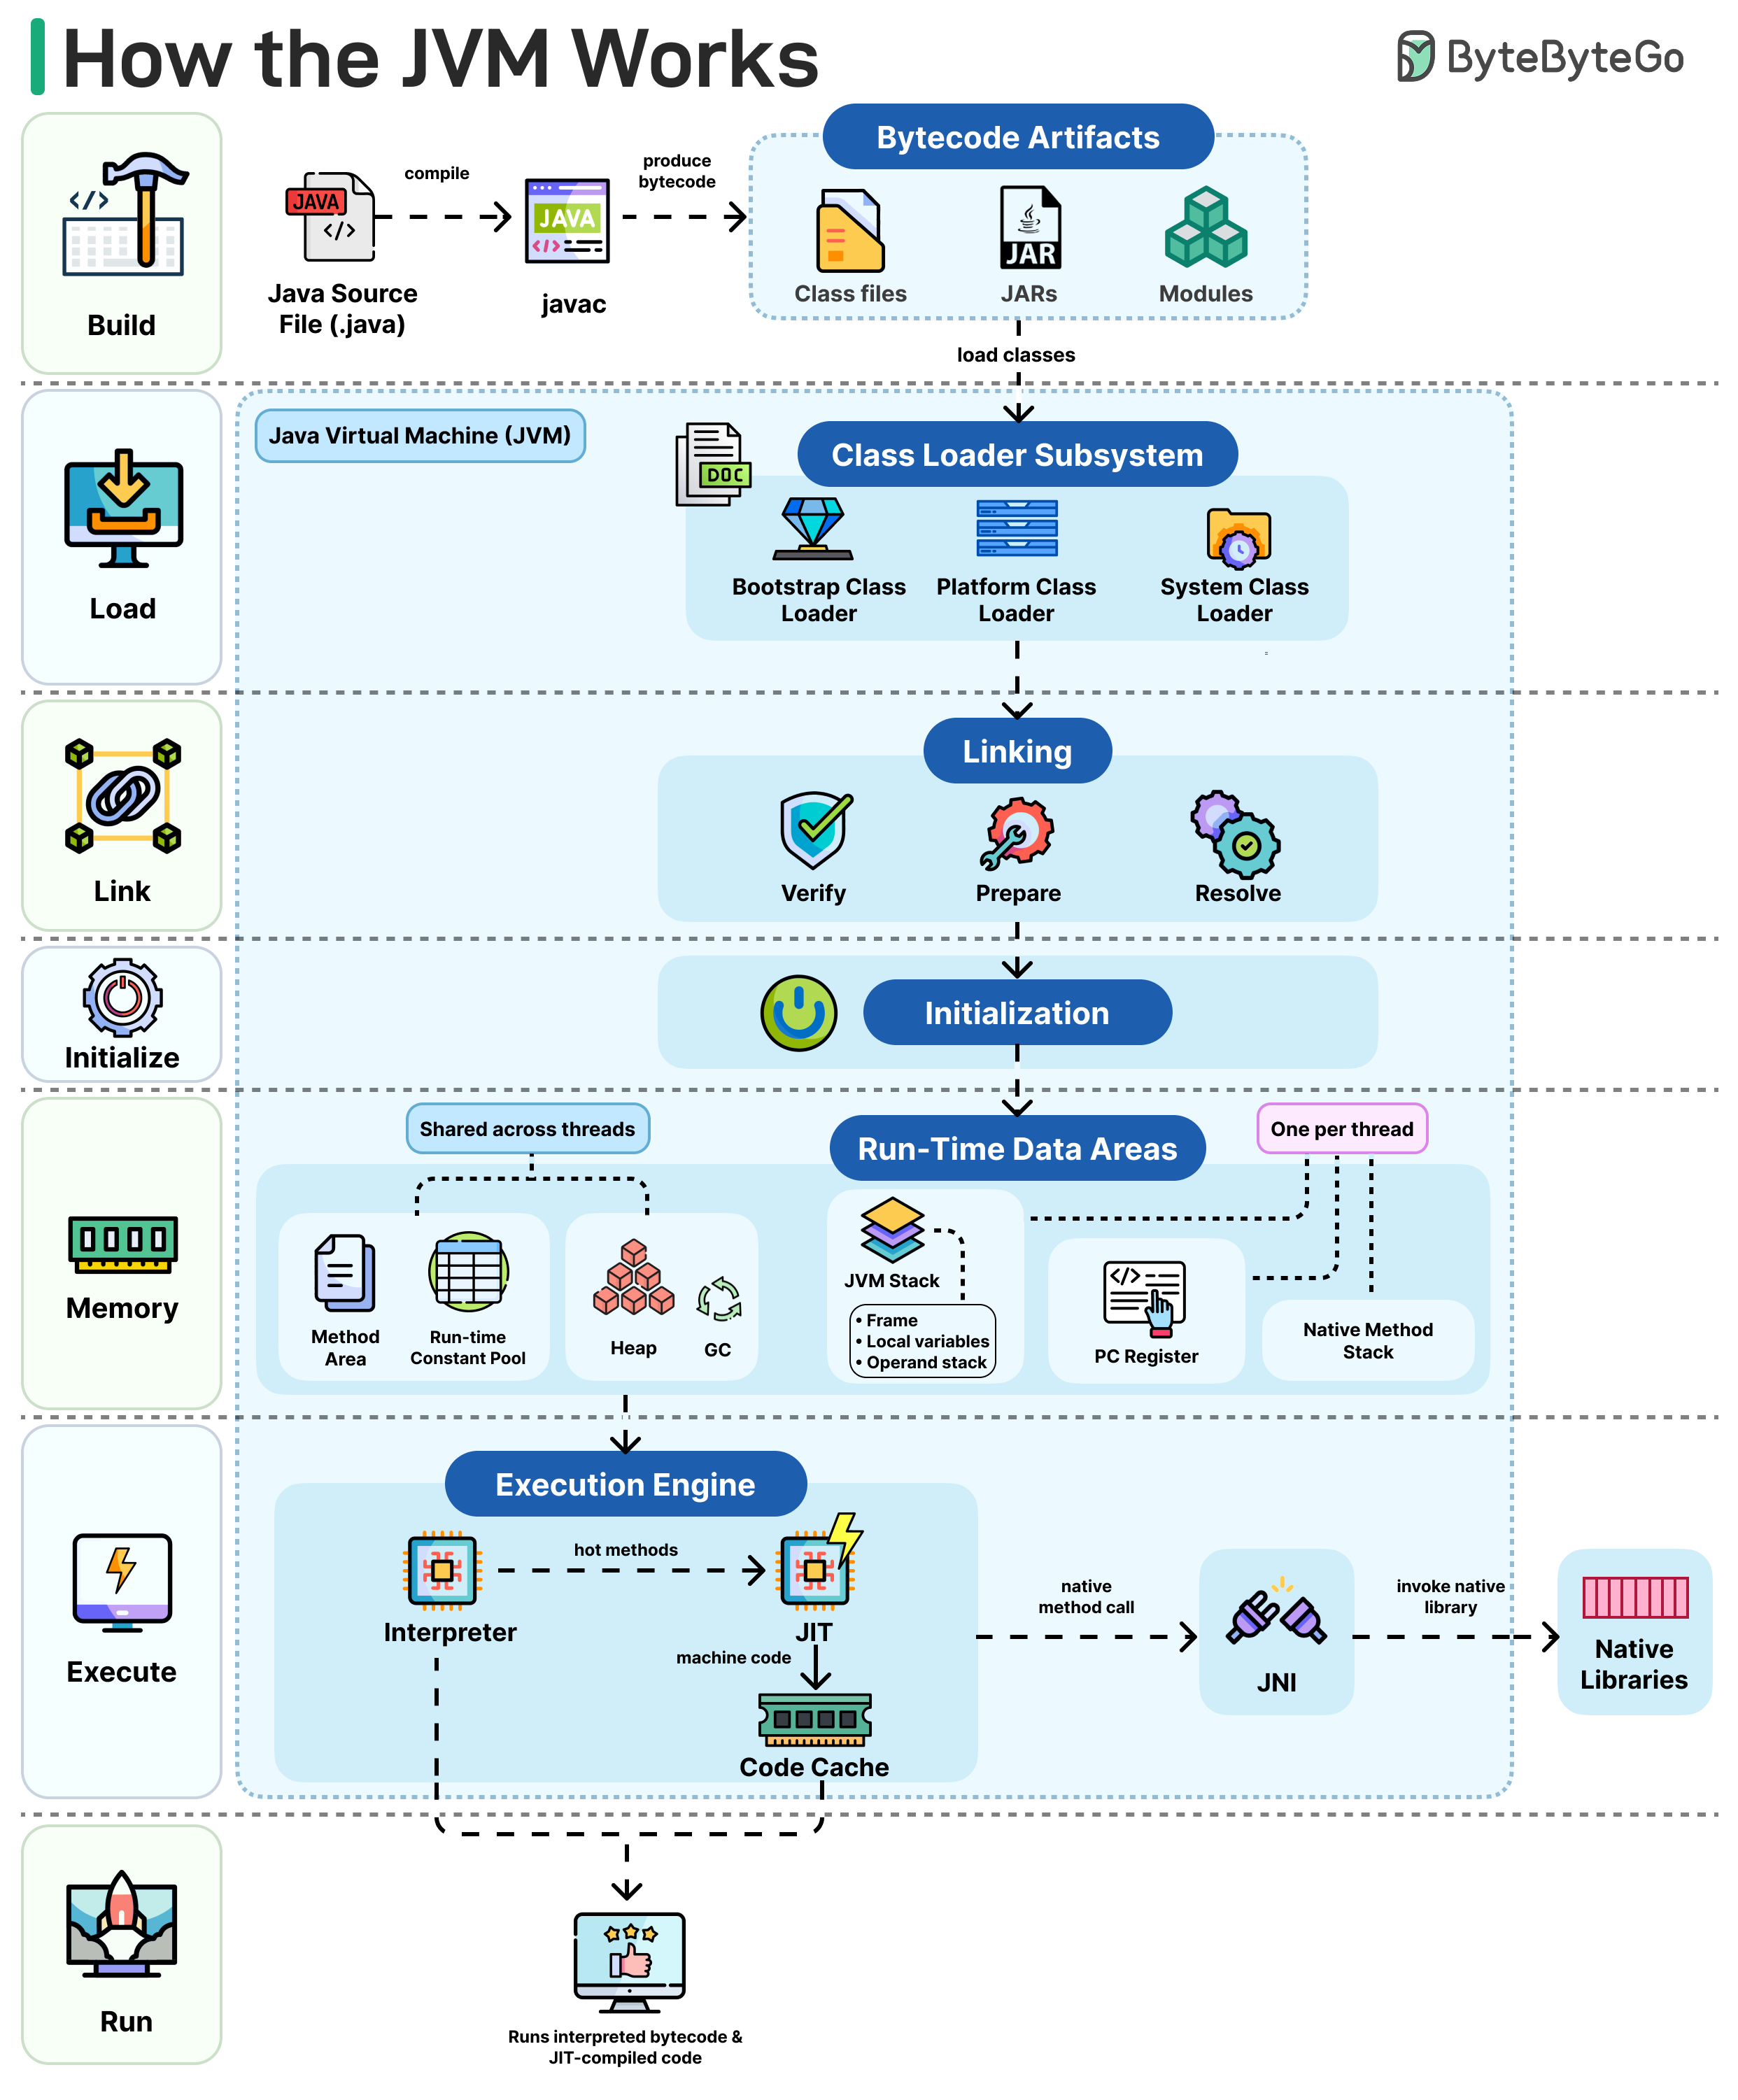
Here's the flow:
Build: javac compiles your source code into platform-independent bytecode, stored as .class files, JARs, or modules.
Load: The class loader subsystem brings in classes as needed using parent delegation. Bootstrap handles core JDK classes, Platform covers extensions, and System loads your application code.
Link: The Verify step checks bytecode safety. Prepare allocates static fields with default values, and Resolve turns symbolic references into direct memory addresses.
Initialize: Static variables are assigned their actual values, and static initializer blocks execute. This happens only the first time the class is used.
Memory: Heap and Method Area are shared across threads. The JVM stack, PC register, and native method stack are created per thread. The garbage collector reclaims unused heap memory.
Execute: The interpreter runs bytecode directly. When a method gets called multiple times, the JIT compiler converts it to native machine code and stores it in the code cache. Native calls go through JNI to reach C/C++ libraries.
Run: Your program runs on a mix of interpreted and JIT-compiled code. Fast startup, peak performance over time.
We spoke with the Figma team behind these releases to better understand the details and engineering challenges. This article covers how Figma’s design-to-code and code-to-design workflows actually work, starting with why the obvious approaches fail, how MCP solves them, and the engineering challenges that remain.
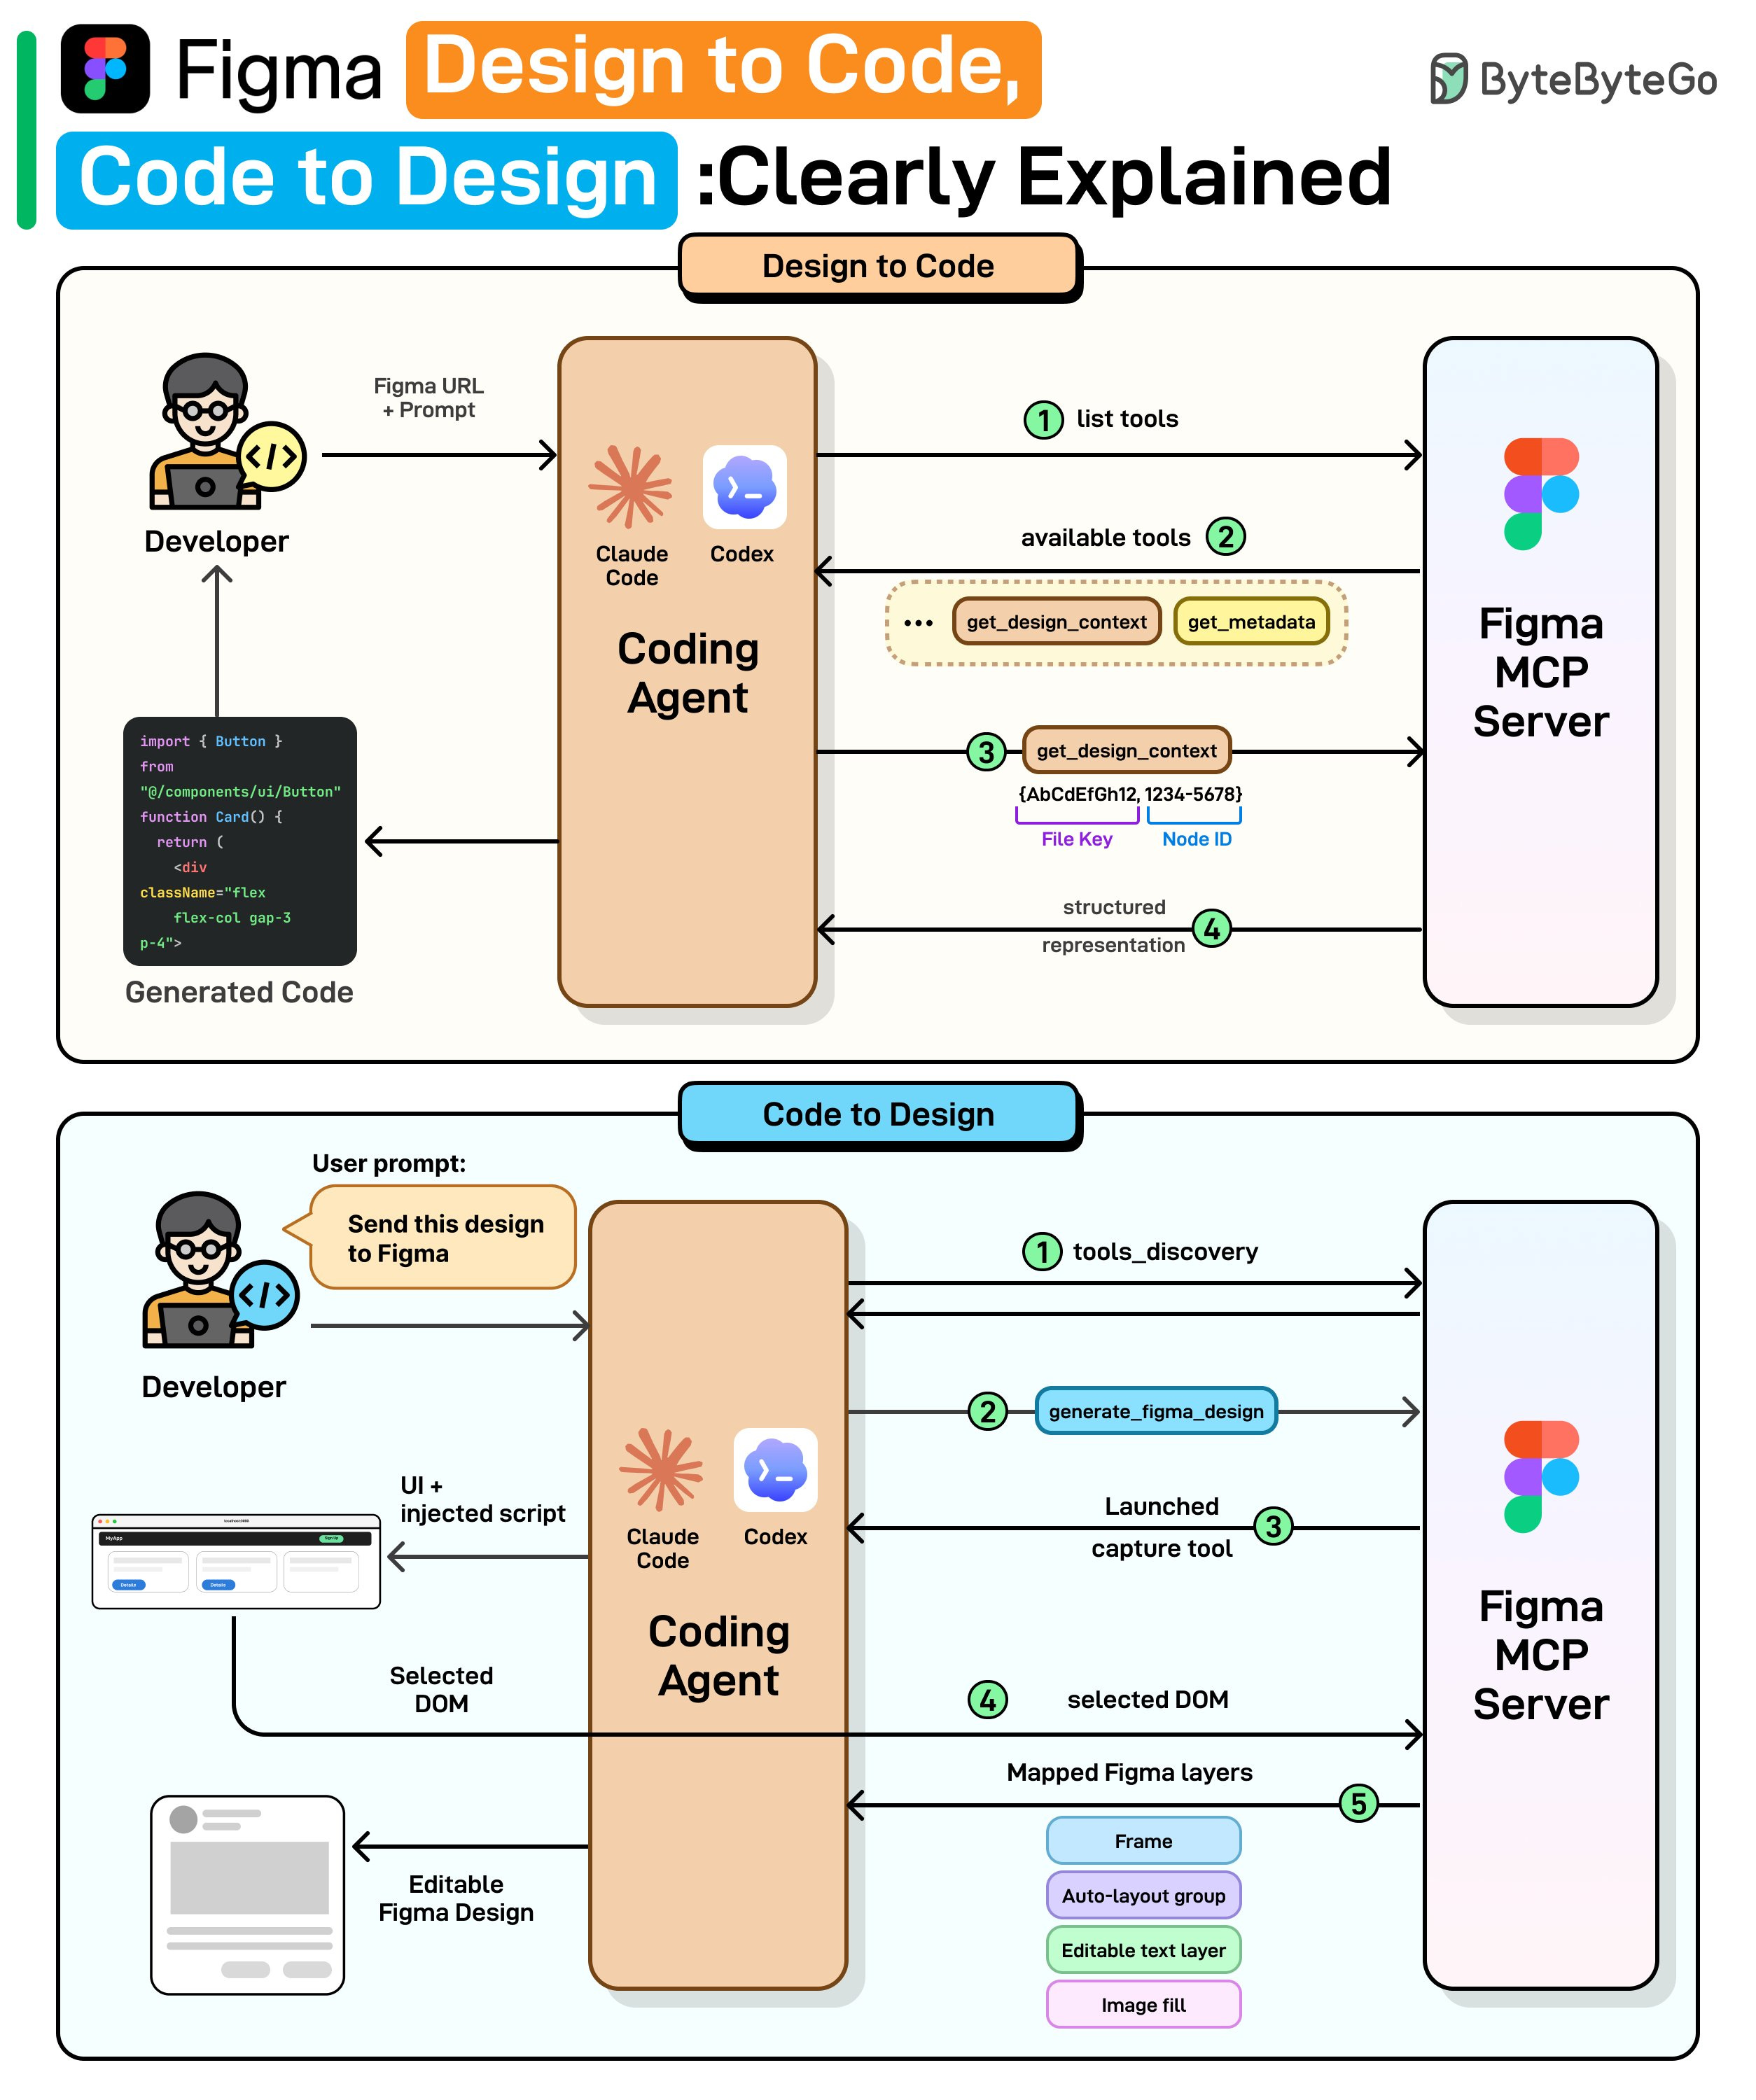
At the high level:
Design to Code:
Step 1: Once the user provides a Figma link and prompt, the coding agent requests the list of available tools from Figma’s MCP server.
Step 2: The server returns its tools: get_design_context, get_metadata, and more.
Step 3: The agent calls get_design_context with the file key and node ID parsed from the URL.
Step 4: The MCP server returns a structured representation including layout and styles. The agent then generates working code (React, Vue, Swift, etc.) using that structured context.
Code to Design:
Step 1: Once the user provides the desired UI code, the agent discovers available tools from the MCP server.
Step 2: The agent calls generate_figma_design with the current UI code.
Step 3: The MCP tool opens the running UI in a browser and injects a capture script.
Step 4: The user selects the desired component, and the script sends the selected DOM data to the server.
Step 5: The server maps the DOM to native Figma layers: frames, auto-layout groups, and editable text layers. The result is fully editable Figma layers shown to the user.
Read the full newsletter here.
A handful of research papers shaped the entire AI landscape we see today.
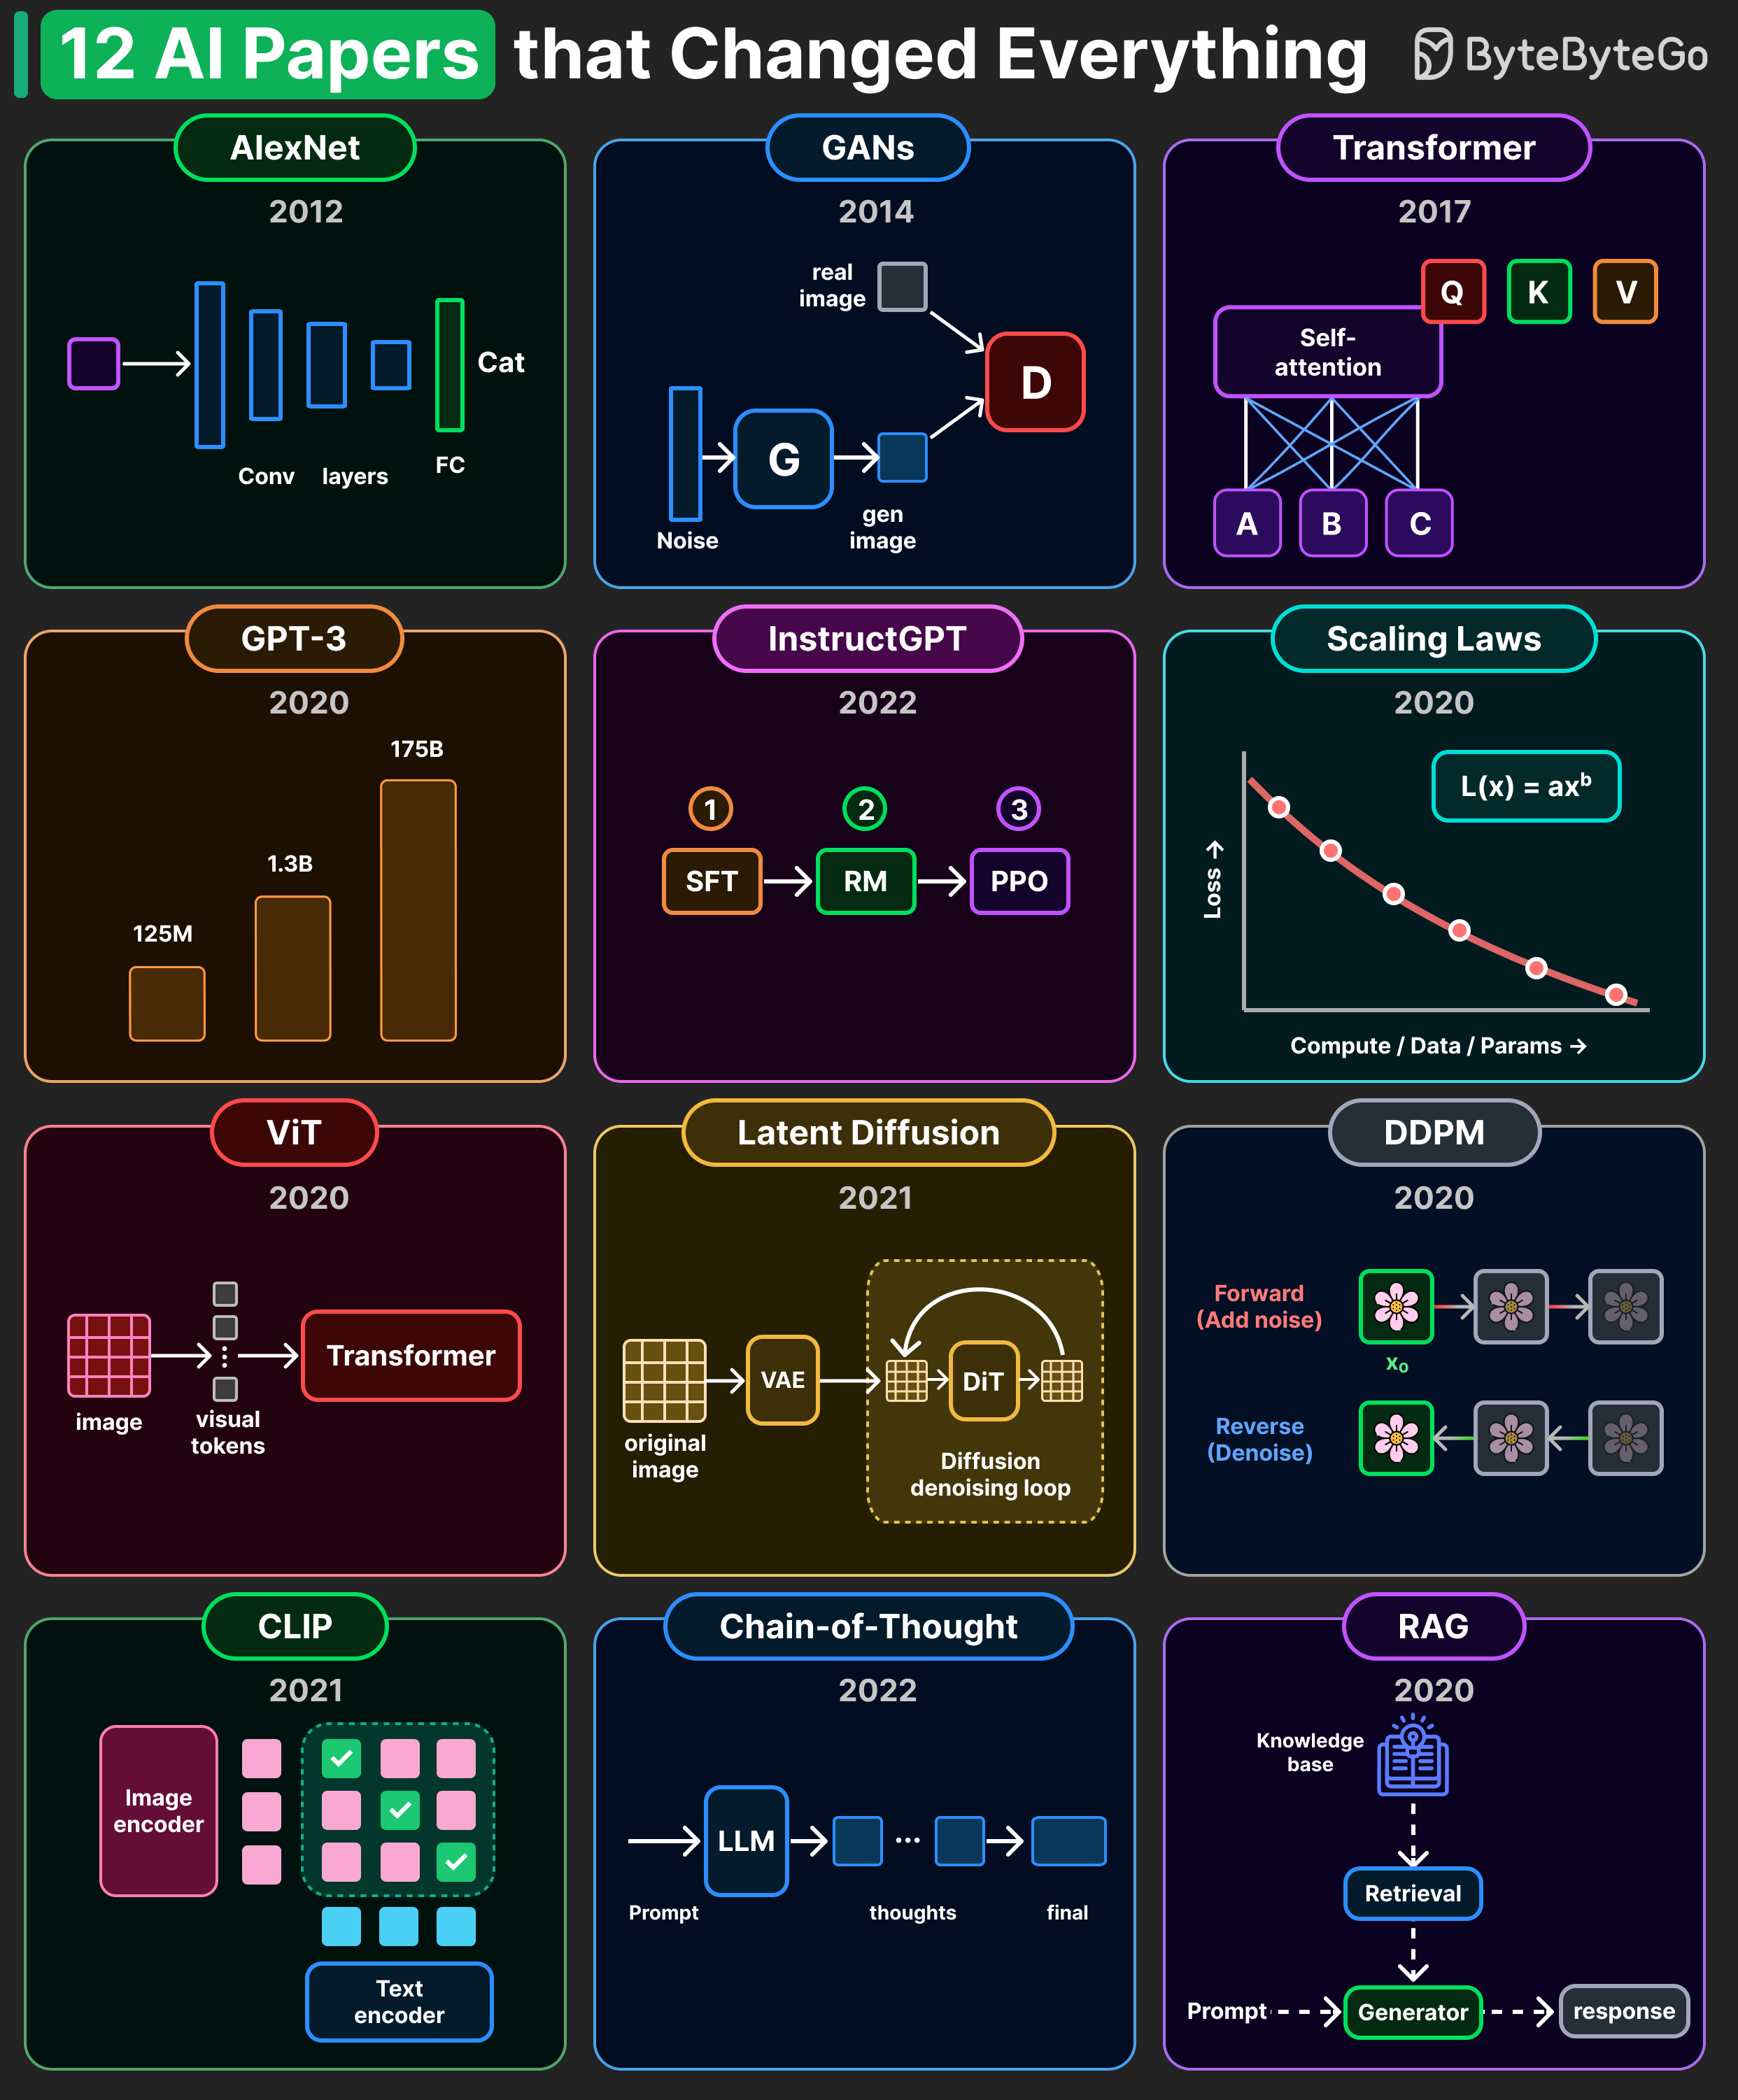
The diagram below highlights 12 that we consider especially influential.
AlexNet (2012): Showed deep neural nets can see. Ignited the deep learning era
GANs (2014): Generate realistic image by having two networks compete
Transformer (2017): Google's "Attention Is All You Need." The architecture behind everything
GPT-3 (2020): OpenAI showed scale unlocks emergent abilities.
InstructGPT (2022): OpenAI introduced RLHF. Turned raw LLMs into useful assistants.
Scaling Laws (2020): Loss follows a clean power law
ViT (2020): Split images into patches and use a Transformer for vision tasks.
Latent Diffusion (2021): Denoising in compressed space. The design behind DALL·E.
DDPM (2020): Add noise, then learn to reverse it. The foundation behind diffusion models.
CLIP (2021): OpenAI connected images and text in one shared space.
Chain-of-Thought (2022): A simple prompt that unlocked complex reasoning.
RAG (2020): Retrieve real documents, then generate. Grounded LLMs in facts.
Over to you: What paper is missing from this list?
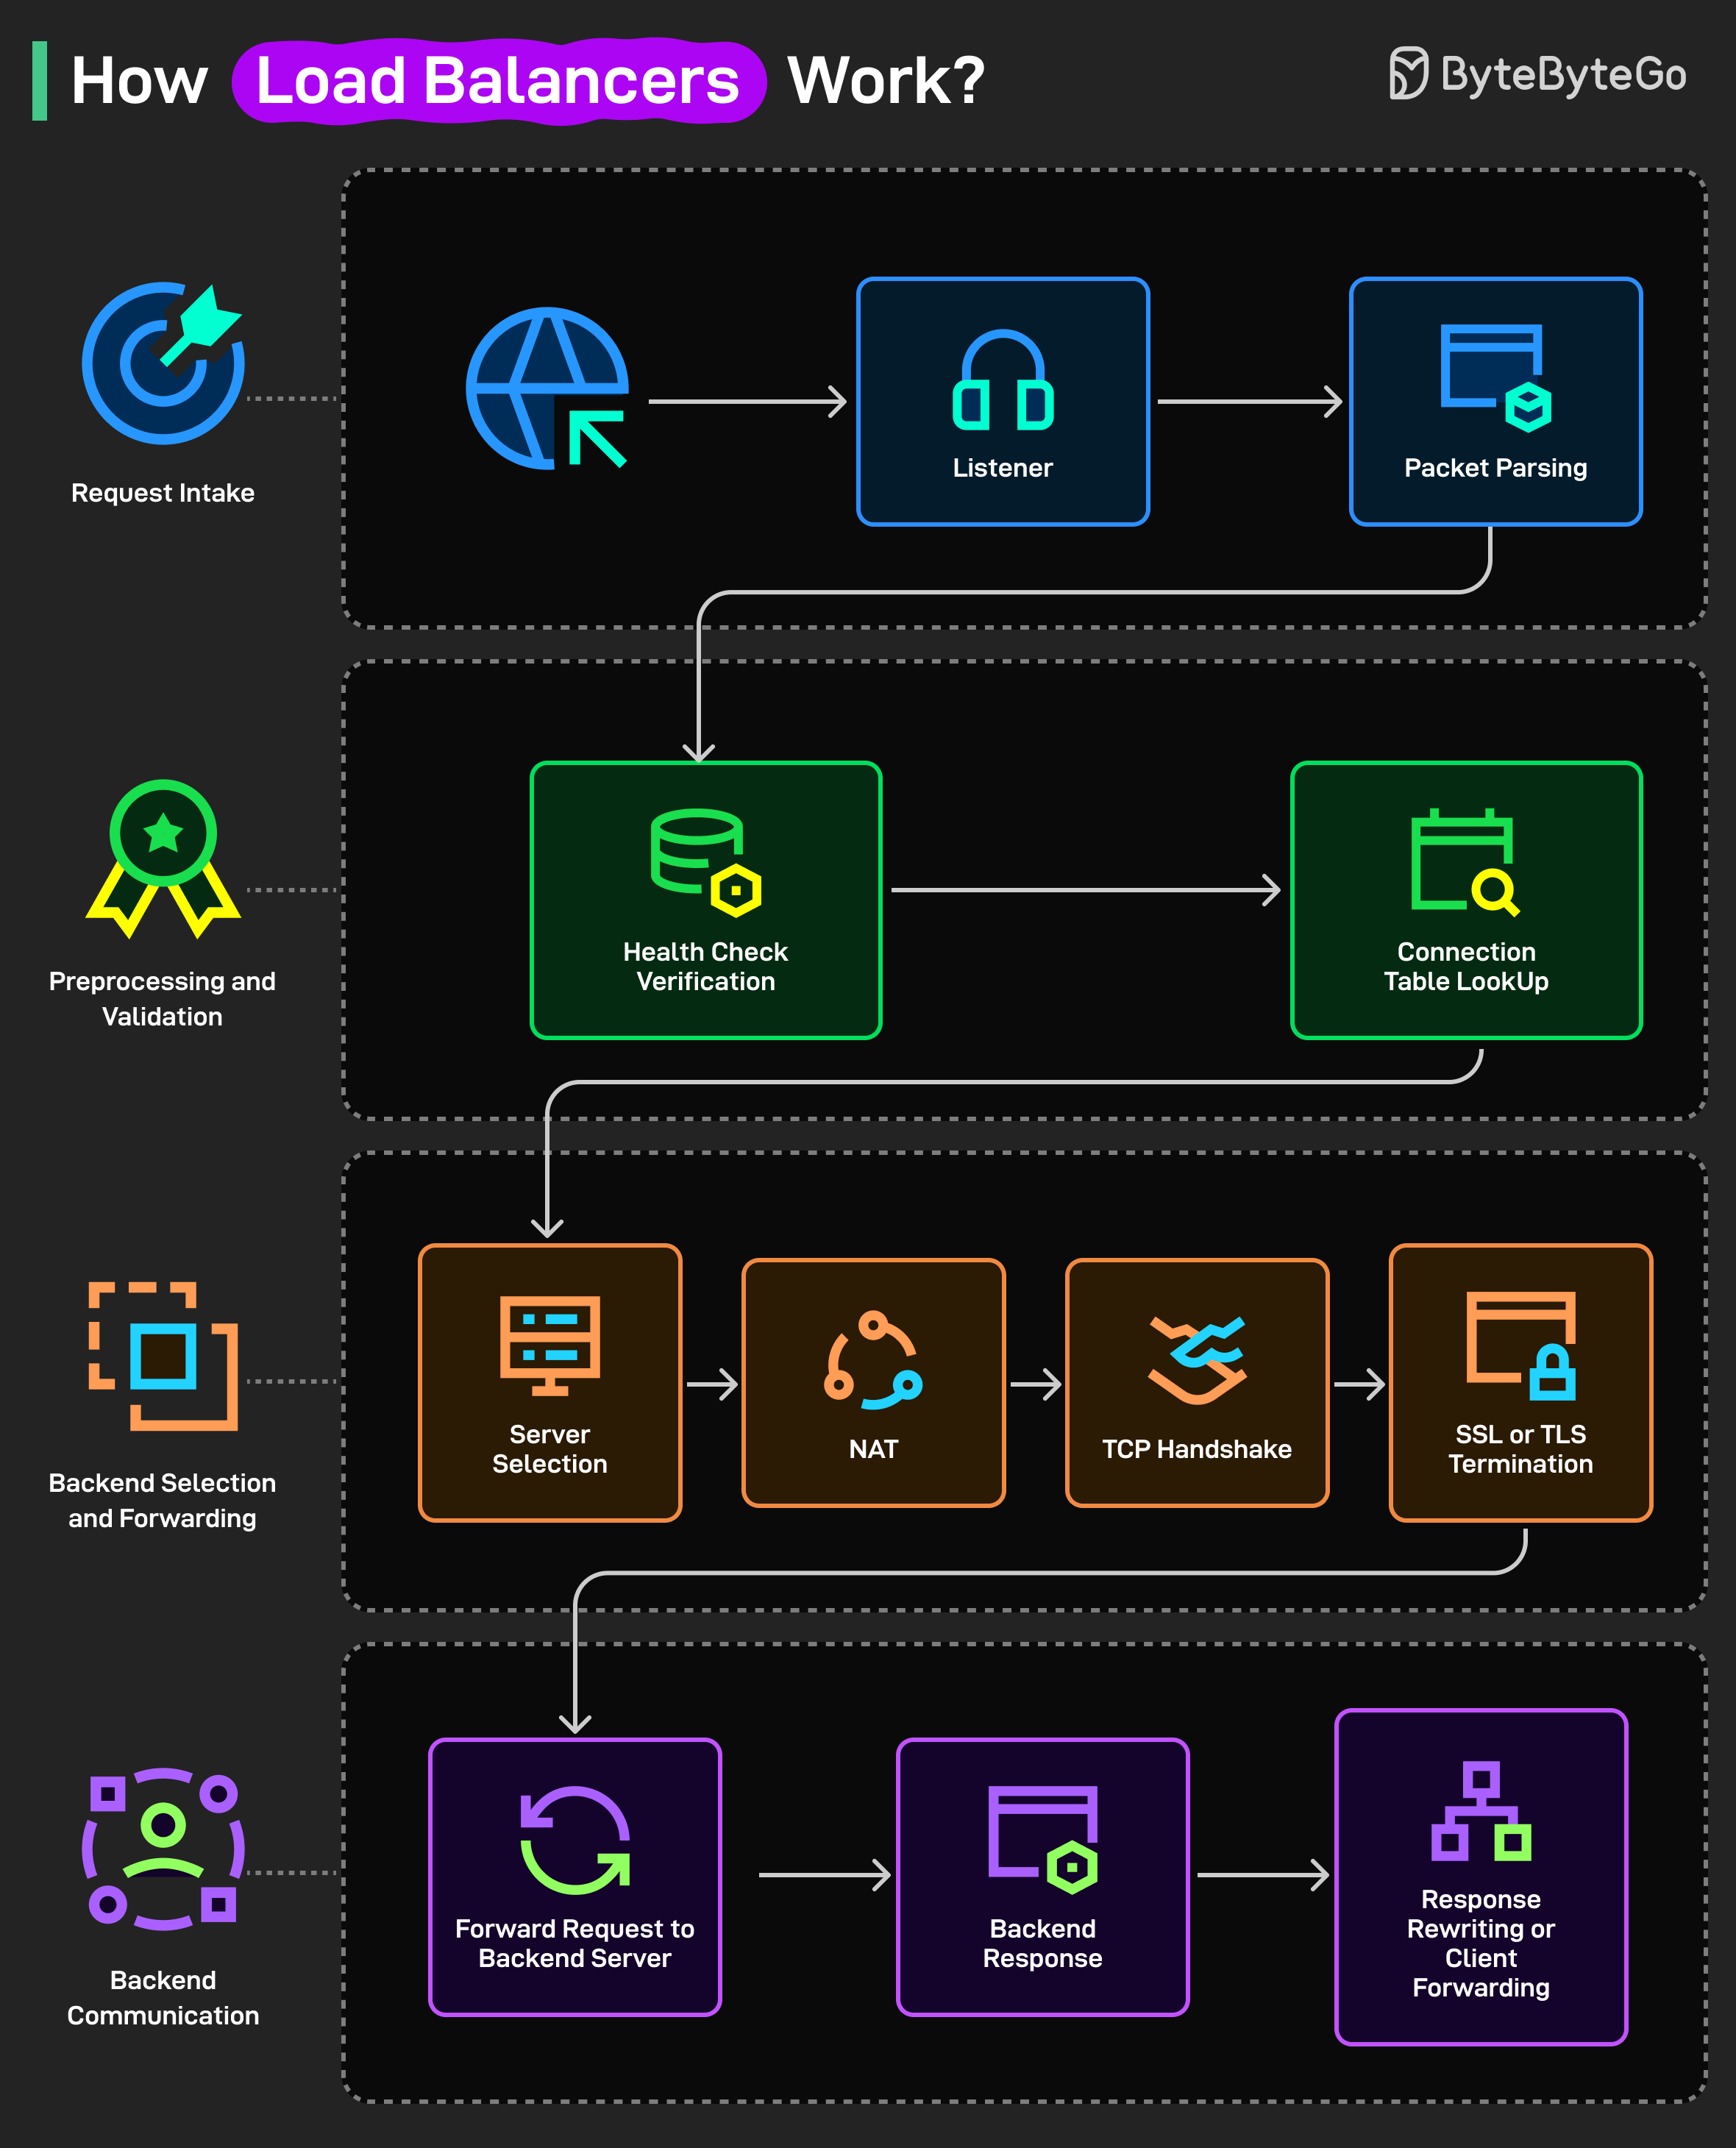
A load balancer is a system that distributes incoming traffic across multiple servers to ensure no single server gets overloaded. Here’s how it works under the hood:
The client sends a request to the load balancer.
A listener receives it on the right port/protocol (HTTP/HTTPS, TCP).
The load balancer parses the packet to understand headers and intent.
It checks recent health checks to know which backend servers are up.
It looks in the connection table to reuse any existing client-to-server mapping.
Using its rules, it picks a healthy target server for this request.
It rewrites addresses so traffic can reach that chosen server.
It completes the TCP handshake to open a reliable connection.
If HTTPS is used, it decrypts (or passes through) via SSL/TLS as configured.
The request is forwarded to the selected backend server.
The backend processes it and sends a response back to the load balancer.
The load balancer may tweak headers, then forwards the response to the client.
Over to you: Which other step will you add to the working of a load balancer?
Imagine two developers updating the same database row at the same time. One of them will have their update rejected. How should the system handle this?
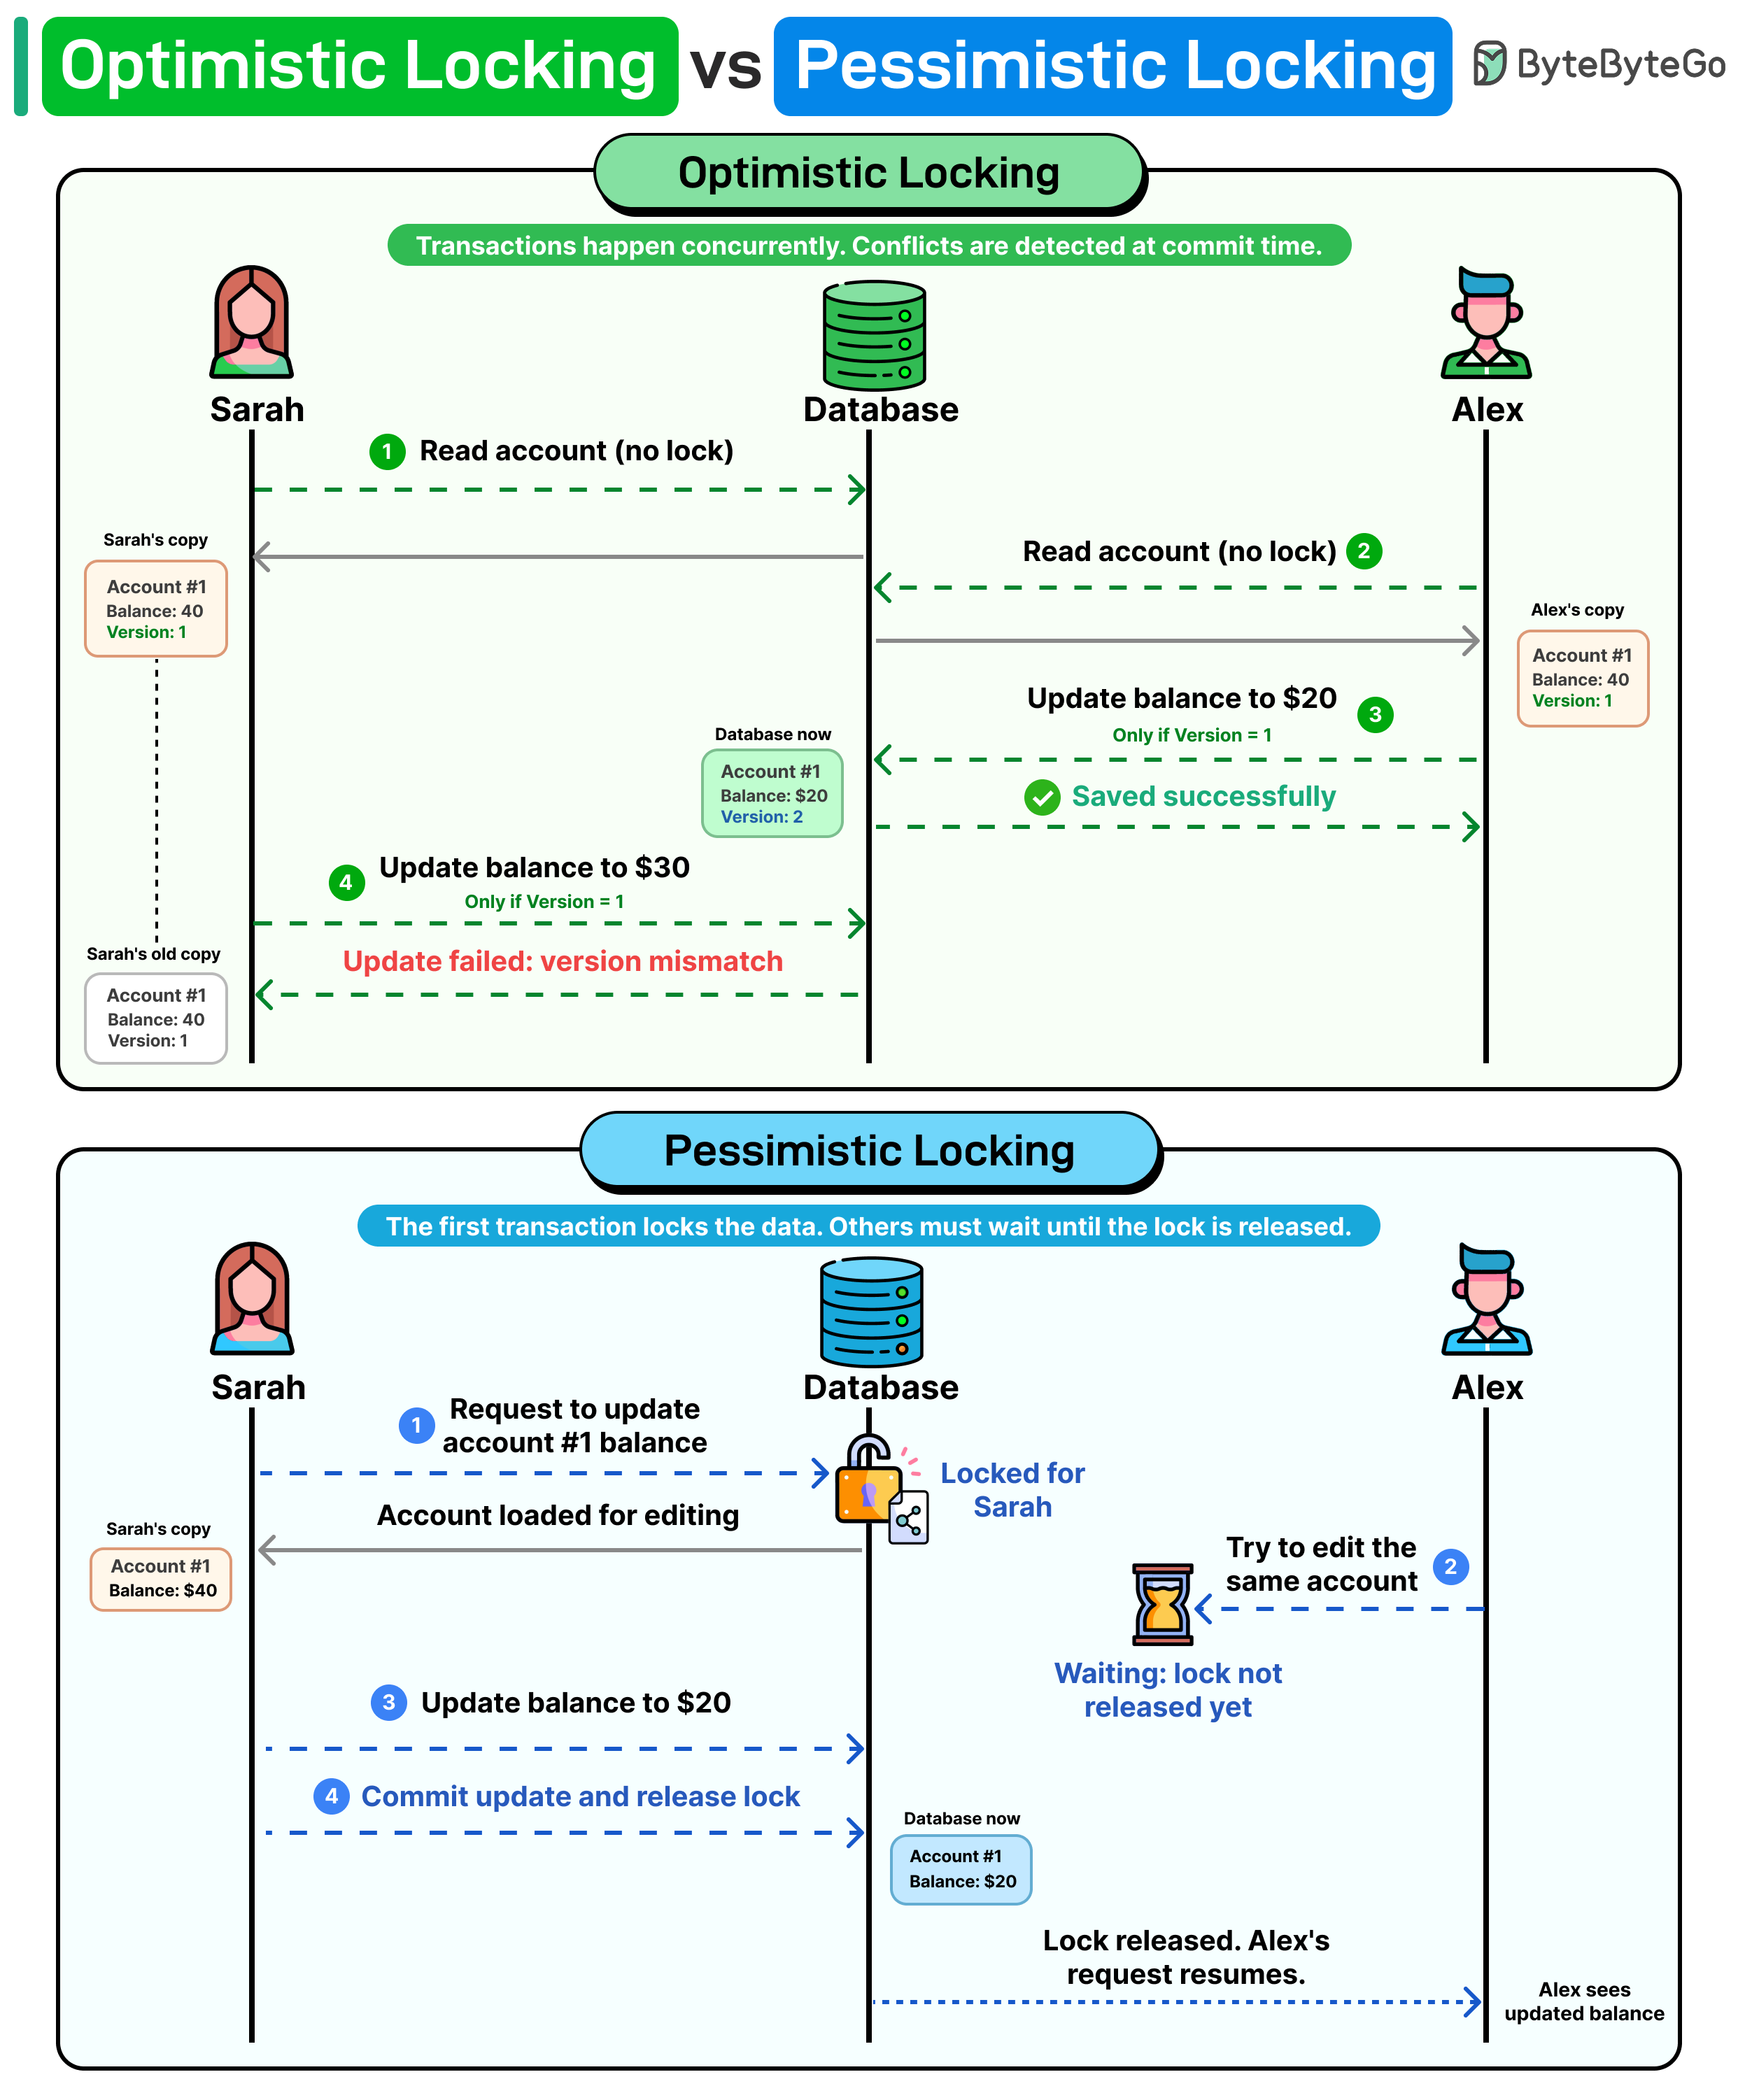
There are two common approaches.
Optimistic locking assumes conflicts are rare. Both users read the data without acquiring any lock. Each record carries a version number. When a user attempts to write, the database checks: does the version in your update match the current version in the database? If another transaction already incremented the version from 1 to 2, your update still references version 1. The write is rejected.
Pessimistic locking takes the opposite approach. It assumes conflicts are likely, so it blocks them before they happen. The first transaction locks the row, and every other transaction waits until that lock is released. No version checks needed.
If your system is read-heavy with occasional writes, optimistic locking is the best option. When concurrent writes occur frequently and the cost of a conflict is high, pessimistic locking is the safer choice.
Over to you: Have you ever run into a deadlock in production because of a locking strategy? How did you fix it?