



惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

D
DataBreaches.Net
有赞技术团队
有赞技术团队
Jina AI
Jina AI
H
Help Net Security
D
Docker
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
Blog — PlanetScale
Blog — PlanetScale
Hugging Face - Blog
Hugging Face - Blog
罗磊的独立博客
MyScale Blog
MyScale Blog
N
Netflix TechBlog - Medium
B
Blog RSS Feed
Martin Fowler
Martin Fowler
WordPress大学
WordPress大学
T
The Blog of Author Tim Ferriss
U
Unit 42
Cyber Security Advisories - MS-ISAC
MongoDB | Blog
MongoDB | Blog
美团技术团队
M
MIT News - Artificial intelligence
阮一峰的网络日志
阮一峰的网络日志
博客园 - 司徒正美
Microsoft Security Blog
IT之家
IT之家

Keep the gradient flowing

Policy Gradients Part 1: The REINFORCE Estimator On the Link Between Optimization and Polynomials, Part 6. Optimization Nuggets: Stochastic Polyak Step-size, Part 2 Optimization Nuggets: Stochastic Polyak Step-size On the Convergence of the Unadjusted Langevin Algorithm The Russian Roulette: An Unbiased Estimator of the Limit Notes on the Frank-Wolfe Algorithm, Part III: backtracking line-search On the Link Between Optimization and Polynomials, Part 5 Optimization Nuggets: Implicit Bias of Gradient-based Methods Optimization Nuggets: Exponential Convergence of SGD On the Link Between Optimization and Polynomials, Part 4 On the Link Between Optimization and Polynomials, Part 3 On the Link Between Optimization and Polynomials, Part 2 On the Link Between Polynomials and Optimization, Part 1 How to Evaluate the Logistic Loss and not NaN trying Notes on the Frank-Wolfe Algorithm, Part II: A Primal-dual Analysis Three Operator Splitting Notes on the Frank-Wolfe Algorithm, Part I Optimization inequalities cheatsheet A fully asynchronous variant of the SAGA algorithm Hyperparameter optimization with approximate gradient Lightning v0.1 scikit-learn-contrib, an umbrella for scikit-learn related projects. SAGA algorithm in the lightning library On the consistency of ordinal regression methods Holdout cross-validation generator IPython/Jupyter notebook gallery PyData Paris - April 2015 Data-driven hemodynamic response function estimation Plot memory usage as a function of time
Isotonic Regression
Fabian Pedregosa · 2013-04-16 · via Keep the gradient flowing

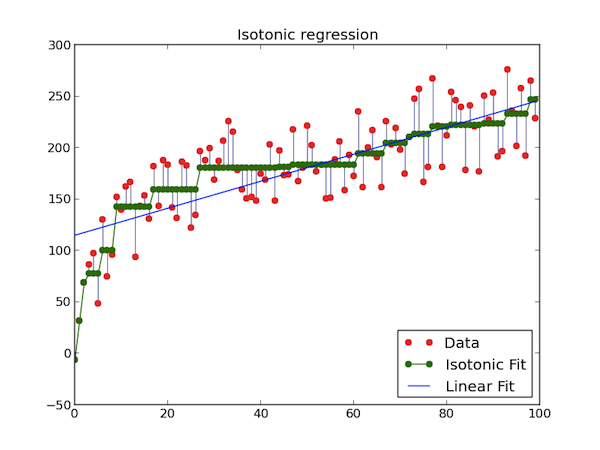
My latest contribution for scikit-learn is an implementation of the isotonic regression model that I coded with Nelle Varoquaux and Alexandre Gramfort. This model finds the best least squares fit to a set of points, given the constraint that the fit must be a non-decreasing function. The example on the scikit-learn website gives an intuition on this model.
isotonic regression

The original points are in red, and the estimated ones are in green. As you can see, there is one estimation (green point) for each data sample (red point). Calling $y \in \mathbb{R}^n$ the input data, the model can be written concisely as an optimization problem over $x$

$$ \text{argmin}_x |y - x |^2 \\ \text{subject to } x_0 \leq x_1 \leq \cdots \leq x_n $$

The algorithm implemented in scikit-learn 3 is the pool adjacent violators algorithm 1, which is an efficient linear time $\mathcal{O}(n)$ algorithm. The algorithm sweeps through the data looking for violations of the monotonicity constraint. When it finds one, it adjusts the estimate to the best possible fit with constraints. Sometimes it also needs to modify previous points to make sure the new estimate does not violate the constraints. The following picture shows how it proceeds at each iteration
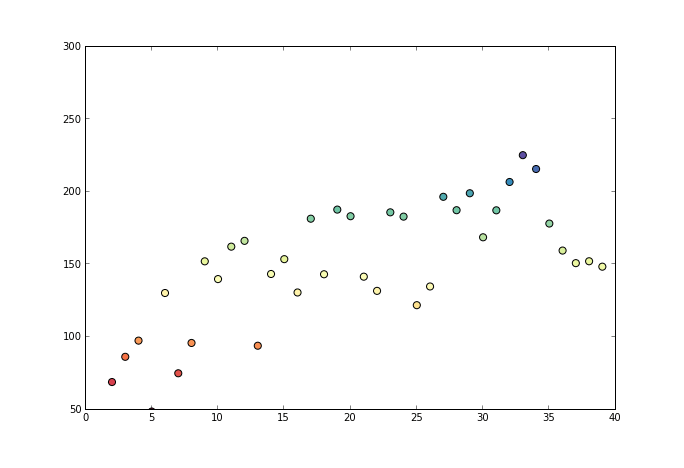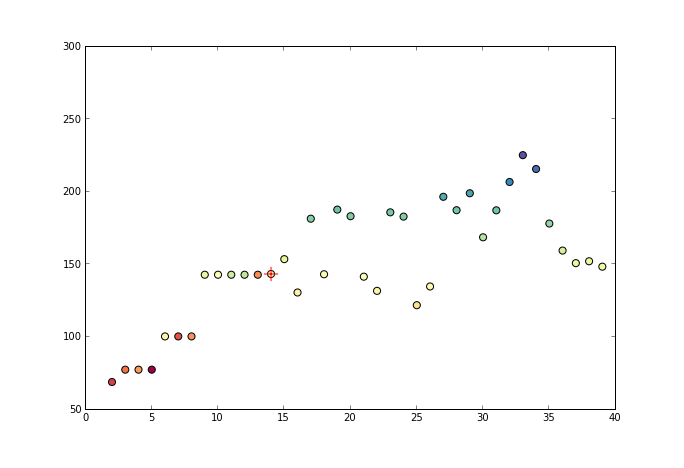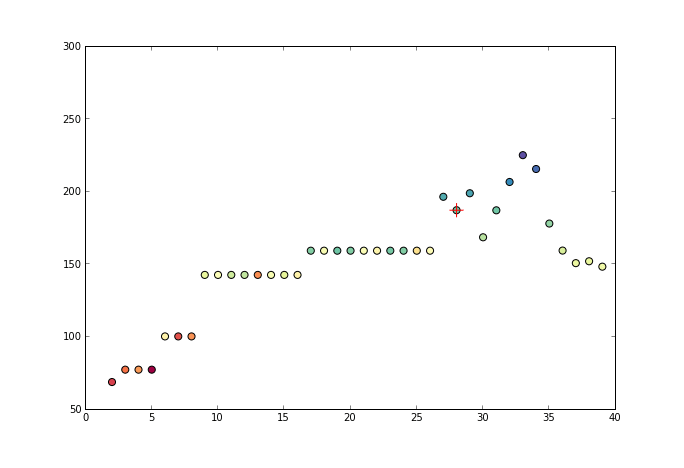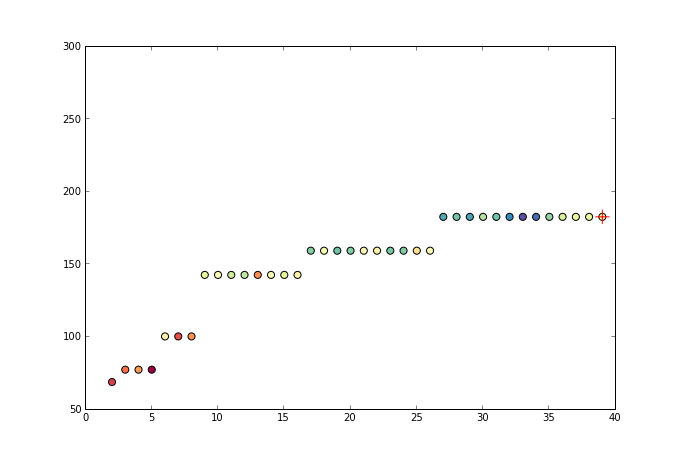
isotonic regression