




If test loss flatlines after 1.5B parameters while training loss continues to drop as you scale, that tells you that your model is limited by the amount of information in your data.
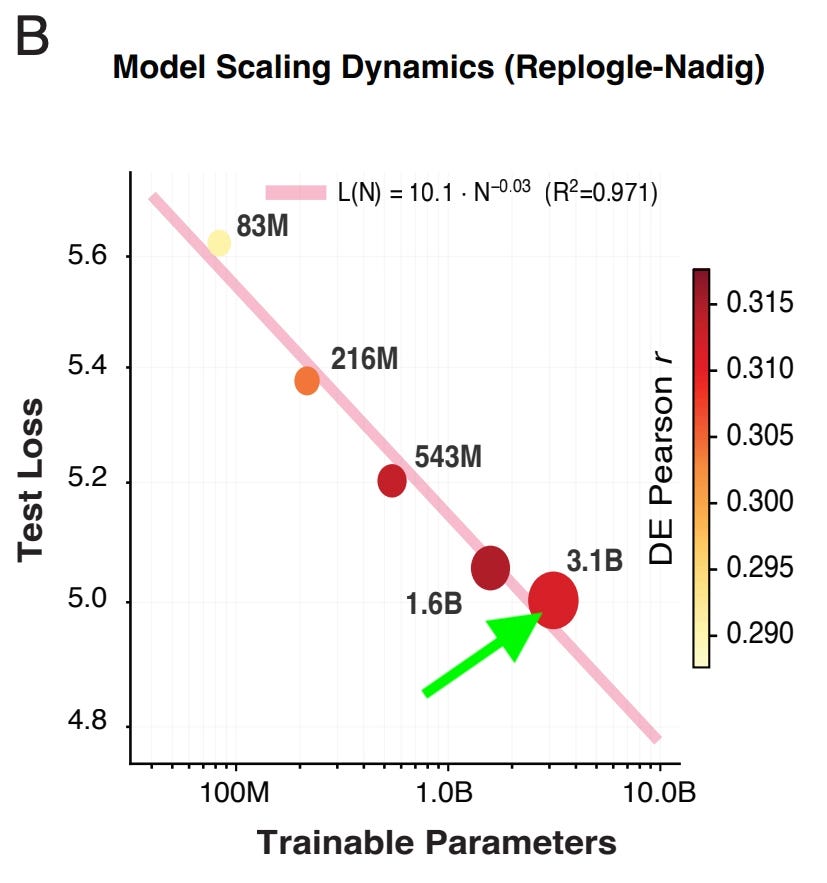
Training on a single, smallish data set exposed an information gap: the 3.1B model falls off the scaling trend. Neither parameters nor compute will improve performance past this wall. For predicting changes to gene expression, you need more information rich data.
This is what Chu and Bo’s teams have done, and here is what ~30x the information buys you:
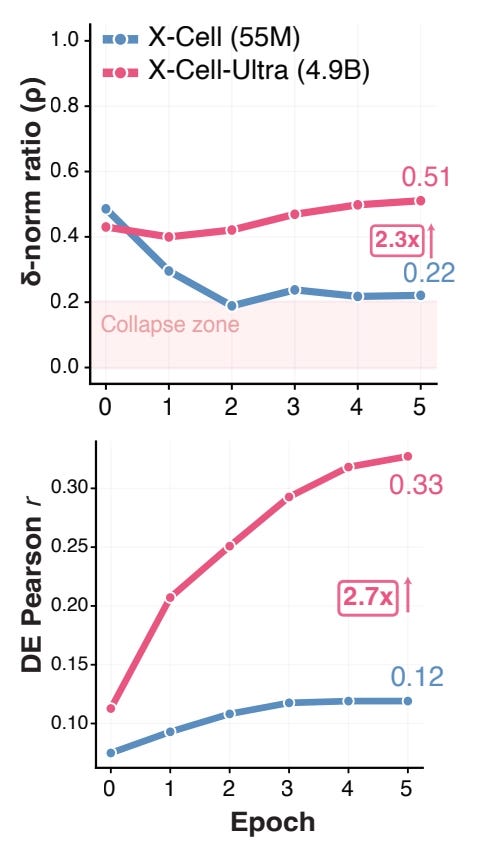
Now we can scale with parameters and training compute! We don’t know how much this effort costed, but we can guess that data collection experiments and infrastructure was a few tens of millions, and compute + headcount + research was a few million. The budget looks like a RL rollout budget, rather than a data rich pre-training one.
We were lucky enough to have the two central figures in this story on our podcast. Taking the lead from Ci Chu and Bo Wang, Xaira Therapeutics is betting that information rich data is the key to AI-driven drug development. Chu was recently promoted to Chief Discovery Officer and Bo to Chief AI Scientist1, underscoring just how strategic Xaira considers this bet.
If you had to figure out how a human cell works, what would you do? A good place to start might be by documenting what genes are expressed (e.g. what RNA is floating around) in different kinds of cells, in different circumstances.
That is CELLxGENE, a database of 168M cells built by Chan Zuckerberg Institute that maps each cell to a count of how many times 20K-30K genes were detected in that cell, plus detailed metadata about every cell. A ~4 trillion-entry matrix.
If the Protein Data Bank (PDB) unlocked structural biology models (Boltz Episode, ESM/BioHub Episode), CELLxGENE has done the same thing for Virtual Cell models. Like PDB, CELLxGENE has inspired a zoo of AI models of RNA expression; so much so that RNA expression models have become synonymous with Virtual Cell models. Bo Wang built one of the most influential, scGPT, that became the starting point for Xaira’s new model.
Models trained on CELLxGENE describe the relationship between cell types and cell states, but they are not good at predicting what will happen if we make changes to RNA expression. Changes in gene expression are highly correlated, and its is difficult (impossible) to figure out what causes what in most cases.
If you could “turn the dial down” on one gene at a time, however, then you would be able to observe what is upstream and downstream of a given gene2. You could tell if A → B & C or B → A & C or B → A, C → B → … If you did this for all of the genes, then maybe you could train a model that could predict what would happen to a cell if you change a gene (e.g. with a drug or a gene edit). Or maybe you could figure out the least invasive way to change a particular gene’s expression.
This is exactly what Chu and Bo’s teams have done. The data set is called X-Atlas and the model is called X-Cell.
In this episode, we discuss:
Why the team abandoned autoregression for diffusion
The CRISPR-based experiments that run millions of tests in parallel, and generate the raw data for X-Atlas and X-cell
Generalization to real lab experiments in real human cells
Beating the linear baseline that has outperformed previous models
Justifying a kitchen-sink of priors, and how that stacks up vs. data and architecture
Bo also shared with us some of the (major) advantages he has as an academic vs. industry leader, and how his labs keep up with the breakneck pace of AI innovation.
Check out the full episode on YouTube, or your favorite podcasting platform!
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。