


Attackers who probe large language models rarely give up after one refusal. They reframe, build context across turns, adopt personas, and escalate gradually. New research from Cisco’s AI threat intelligence team finds that the safety benchmarks used across the industry miss almost all of this behavior, and the gap between published scores and observed resilience runs wide enough to misrank leading models.
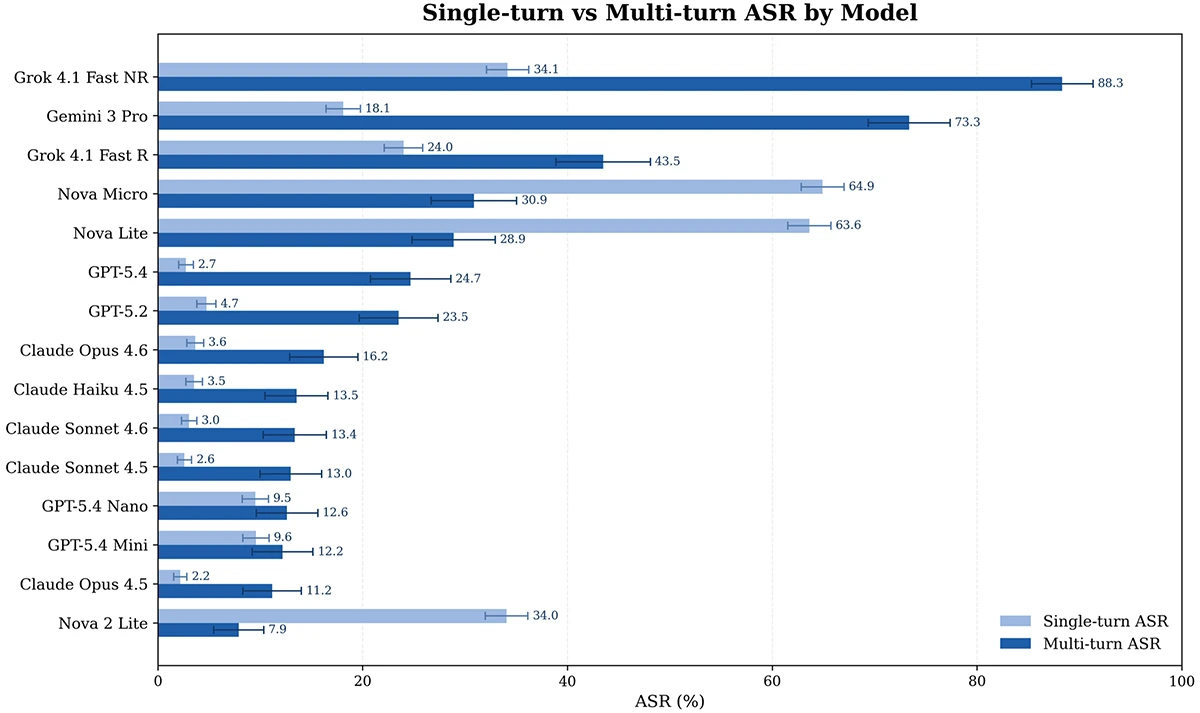
Single-turn versus multi-turn ASR by model, with approximate 95% confidence half-widths on single-turn (upper bar) and multi-turn (lower bar) estimates. (Source: Cisco)
The report pairs single-turn and multi-turn evaluation across 15 closed flagship models from OpenAI, Anthropic, Google, Amazon, and xAI. The testing covered roughly 30,000 single-turn prompts and nearly 7,000 multi-turn attacks spread across more than 1,400 conversations. Across the cohort, multi-turn attack success rates climbed as high as 88%, an order of magnitude above the lowest result in the group. Single-turn and multi-turn testing produced different rankings, different failure maps, and different tail-risk profiles.
Every model in the cohort failed a meaningful share of multi-turn attacks. OpenAI’s GPT-5.4 jumped roughly ninefold under iterative pressure, moving from a single-turn ASR in the low single digits to nearly 25%. Google’s Gemini 3 Pro climbed from about 18% to 73%. xAI’s Grok 4.1 Fast in its non-reasoning configuration topped the cohort at 88%. Anthropic’s Claude family posted the strongest single-turn refusal performance, with single-turn ASRs in the low single digits, and still landed in the 11% to 16% range once attackers were allowed to adapt.
Cross-regime gaps ran in both directions. Gemini 3 Pro rose by more than 55 points under iterative testing. All three Amazon Nova variants moved the opposite way. Nova 2 Lite recorded a relatively high single-turn ASR and the lowest multi-turn ASR in the entire cohort at about 8%. More than half of the models tested showed an absolute gap of at least 15 points between the two regimes.
Amy Chang, head of AI threat and security research at Cisco, told Help Net Security the question buyers and regulators should ask before trusting a model is direct: “How secure is this model against real-world attack scenarios?” In her words, that translates to: “How does this model hold up against multi-turn, adaptive attacks? Real adversaries won’t stop at the first refusal; they will build additional context, reframe, or escalate across the conversation. Single-turn benchmark scores demonstrate how a model performs in scenarios that attackers don’t use.”
The same Grok 4.1 Fast model with reasoning mode enabled saw its multi-turn ASR cut roughly in half, a swing of more than 40 points tied to a single capability flag. The research notes that this kind of configuration-driven safety variation does not appear on any public benchmark or model card the authors reviewed. Users running the model in its default non-reasoning configuration encounter a substantially different threat profile from users who turn reasoning on.
The work extends an earlier Cisco study of eight open-weight models, where multi-turn ASR ran two to ten times higher than single-turn baselines and reached more than 90% against Mistral Large-2. Multi-turn vulnerability appears as a structural property of the current frontier, present in both open and proprietary weights.
Five strategy families drove most of the multi-turn outcomes: role-play and persona adoption, contextual ambiguity, refusal reframing, information decomposition, and crescendo-style escalation. Within each family, the spread between the most and least exposed model was large, often approaching the full range of the chart. The pattern means strategy labels mostly sort which models pull apart from one another, even where average difficulty looks similar.
On the single-turn side, three procedures dominated the rankings: Imposter AI, Soft Paraphrase, and System Prompts. By content type, hate speech, profanity, and specialized advice led. Imposter AI alone outpaced the tenth-ranked procedure by a wide margin, suggesting that targeted fixes to a handful of attack surfaces could move the aggregate numbers for most models in the cohort.
Production deployments typically wrap base models in additional safety layers. Chang said those layers help, with limits. “Guardrails attenuate risk but do not eliminate it. The base model sets the floor on what any production system can achieve. Just as traditional software development decisions involve risk tolerance and acceptance for the code itself and all its dependencies, the same approach applies to AI development and deployment. The blast radius for a rogue or misaligned AI agent, however, has the potential to be more damaging than a software flaw. Watch this agentic AI space.”
The Cisco team proposes three operational steps for organizations buying or deploying AI: publish ASR by strategy family on every model release, gate deployments on regressions in the top three procedures and content types using a 3-point threshold, and flag any model with a cross-regime gap above 15 points for manual review. Applied to this cohort, the third rule alone surfaces more than half the tested models for closer examination.
Regulatory frameworks point in the same direction. The NIST AI Risk Management Framework, the forthcoming NIST Cyber AI Profile (IR 8596), and Article 15 of the EU AI Act all call for adversarial robustness testing. None currently specify the interaction regime, strategy decomposition, or slice-support labeling the Cisco research argues is needed for decision-grade assessment.

此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。