








Security operations centers are running into the same wall everywhere. Detection tools generate more alerts than analysts can work through, and the early stages of any investigation involve pulling together logs from several sources to decide whether something is worth escalating. Vendors have spent the past two years pitching LLMs as the answer, with a steady stream of copilots and AI assistants aimed at alert triage.
A new paper from researchers at the University of Oslo and the Norwegian Defence Research Establishment offers a useful corrective to that pitch. One finding stands out. When the same language model is handed the same alert and the same data, the difference between useless and accurate output comes down almost entirely to the structure built around it.
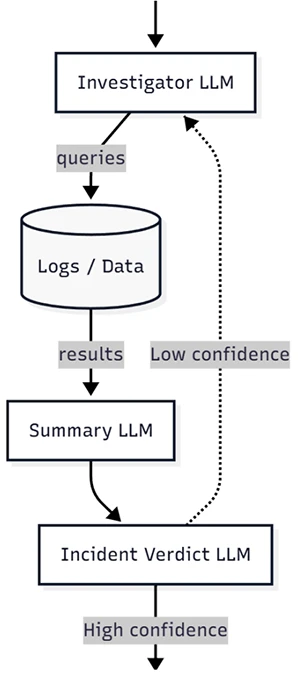
Agentic security investigation loop (Source: Research paper)
The researchers set up two versions of the same task. In the first, four popular language models (GPT-5-mini, Claude 3 Haiku, Qwen3:30B, and Gemma 3:27B) received an alert description and a summary of network logs, then were asked for a verdict. Every model failed to identify the malicious activity. Across all four, zero percent of true-positive cases were correctly flagged. Gemma classified everything it saw as benign, regardless of input.
The malicious activity in question was a sequence familiar to any analyst: reconnaissance, brute-force login attempts, and an initial access attempt against a web server, drawn from the AIT Log Data Set V1.1. The signal was present in the logs. The models, given only a high-level summary, missed it.
The second version wrapped the same models in a workflow. One language model planned an investigation by selecting from a small set of predefined SQL queries against Suricata logs, with the option to add one custom query and a grep search across unstructured text. A second model summarized the evidence returned. A third issued a verdict, with the option to send the case back for another round of evidence gathering.
Accuracy on malicious cases jumped to an average of 93 percent. Three of the four models cleared 90 percent. GPT-5-mini correctly identified every malicious case across 100 runs.
The models did not change. The prompts did not get larger. What changed was the addition of constrained tools, a defined set of steps, and guardrails on what the model could query and how. The language model went from a passive recipient of summarized data to something closer to how a junior analyst works: pulling specific evidence, looking at the results, and deciding what to ask next.
The benign side of the evaluation is messier. GPT-5-mini, the strongest performer on malicious detection, classified every benign case as uncertain, which would push every false alarm to a human reviewer in production use. Other models showed similar conservatism in varying amounts. The authors argue that erring toward uncertainty is preferable to missing real threats, which is a defensible position for a triage tool, with implications for how much analyst time such a system would actually save.
The evaluation also covers one attack scenario in one dataset, with a synthetic alert standing in for a real detection. It is a proof-of-concept, and testing against more diverse data and real intrusion detection output is flagged as a needed next step.
The lesson generalizes beyond SOC work. A capable model handed unstructured context will guess. The same model given a small, well-defined toolkit and a process for using it will reason through the problem. For any AI security product, the question worth asking is what the system around the model can do.

Download: Automating Pentest Delivery Guide
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。