





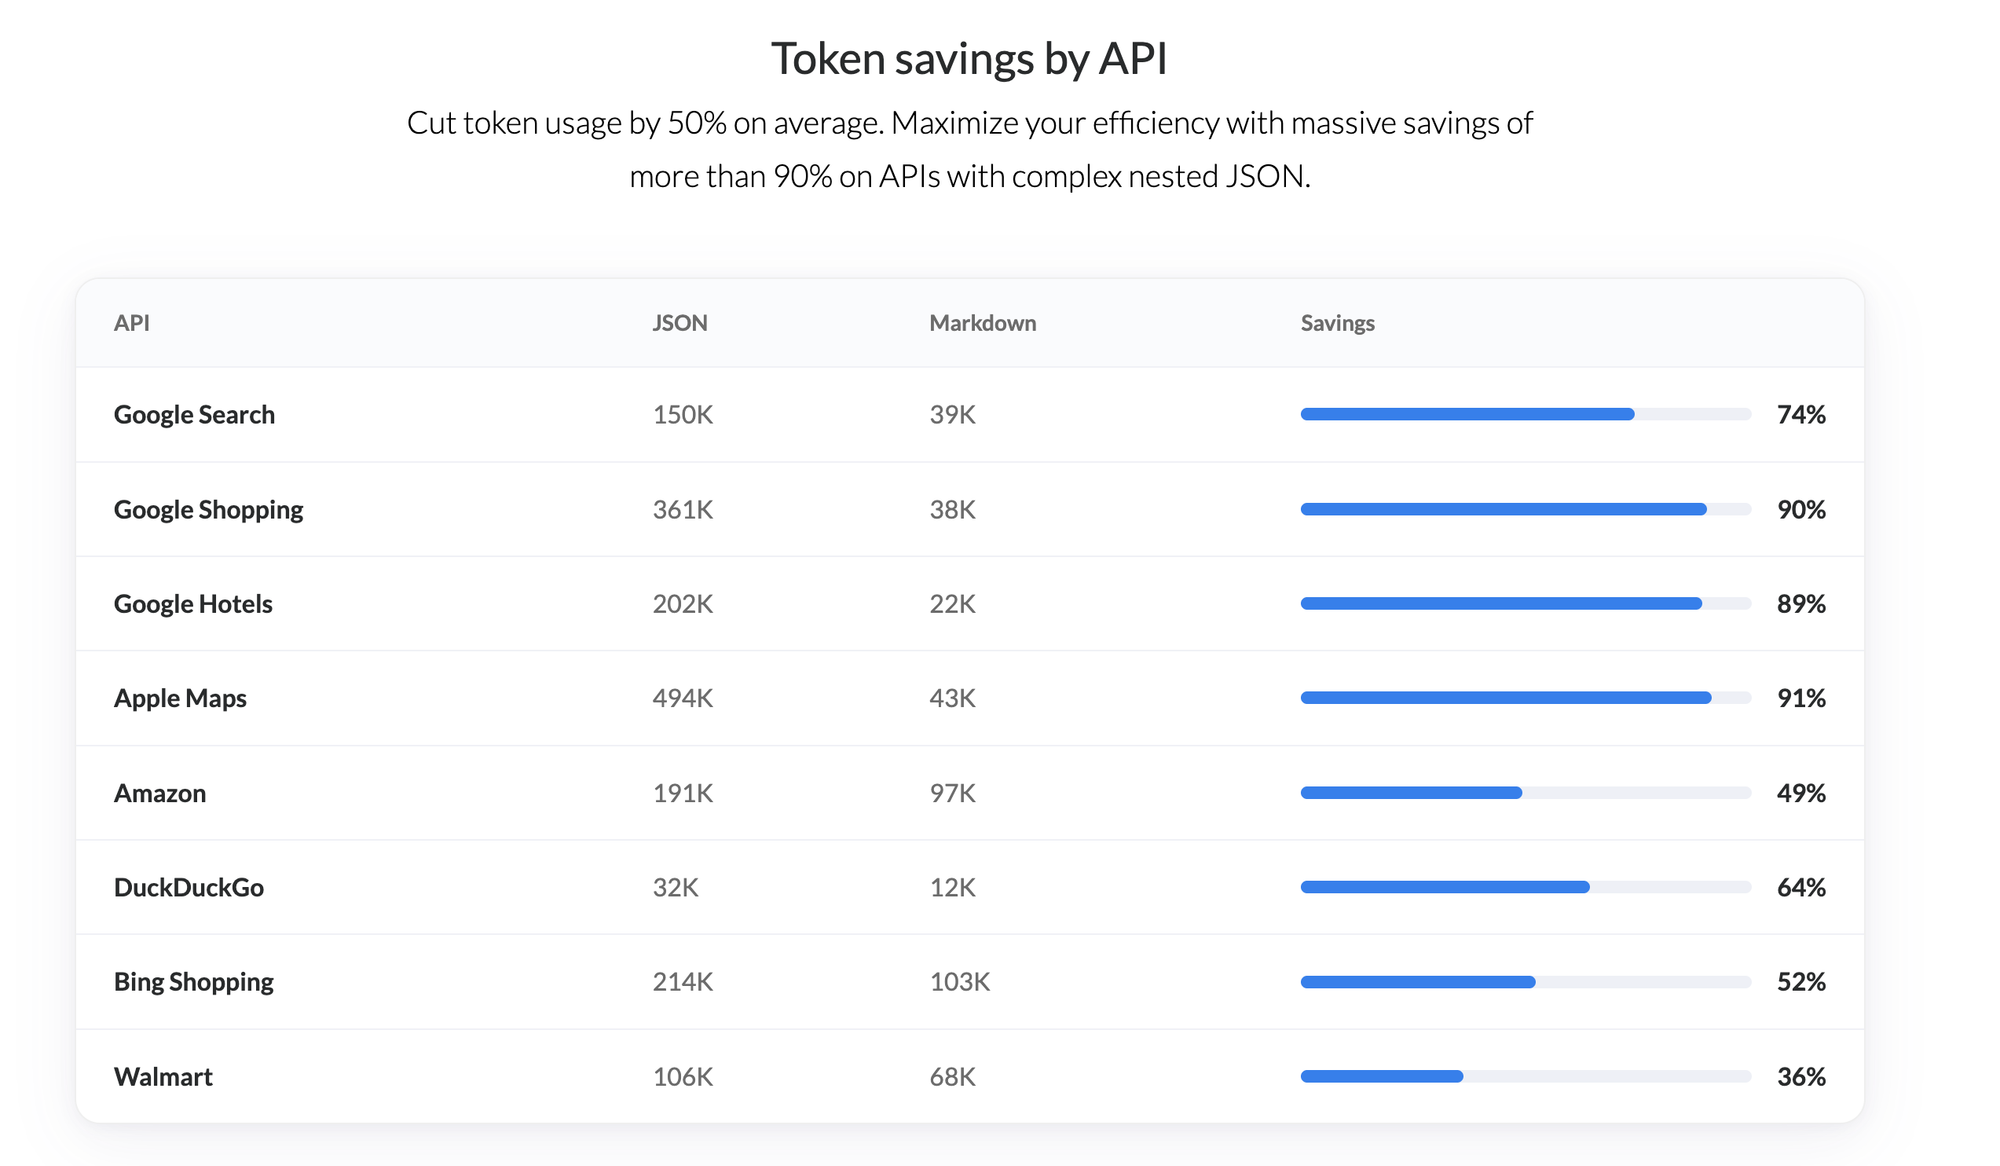
We’re proud to announce the launch of Markdown Output, a new feature designed to deliver real-time search data in a format optimized for LLMs and AI agents. It is available on every search, on every API, and it comes back from the same structured search that JSON does. This is SerpApi’s effort to adapt and improve our product for LLMs and AI agents. Based on our benchmarks, the new output gives you roughly half the tokens of JSON on average and up to 90% for some APIs. If you already use our APIs, you can implement it right away; no configuration is needed, and it works automatically across our 100+ APIs.
SerpApi: Markdown Output for AI Agents
Get search results as clean, token-efficient markdown instead of JSON. Built for LLMs, AI agents, and agentic workflows.
 SerpApi
In this post, we’ll show what the new Markdown Output looks like on a real search and explain when to use it and when to stay on JSON.
Getting Markdown results does not require a new endpoint. Any existing search can return it in three ways:
# Query parameter
curl "https://serpapi.com/search?engine=google&q=coffee&api_key=YOUR_KEY&output=md"

# Route extension
curl "https://serpapi.com/search.md?engine=google&q=coffee&api_key=YOUR_KEY"

# Accept header
curl -H "Accept: text/markdown" "https://serpapi.com/search?engine=google&q=coffee&api_key=YOUR_KEY"Markdown is a plain-text format with headers, tables, links, and lists that you can read raw or render as structure. In the last few years, it also became the default language of LLMs. Models are trained on enormous amounts of it (documentation, READMEs, forums); chat interfaces render their answers from it, and OpenAI's own prompt engineering guide recommends Markdown headers and lists to communicate hierarchy to the models.
We took that signal from our users and from the industry, everyone converging on Markdown as the common input and output format for LLMs and agents, and adapted our product to it. Every design choice in the new output serves one goal, to fit more useful data in your model's context window. Let's see each one with a real search for coffee on Google.
SerpApi Playground - SerpApi
Test SerpApi’s Google Search, Google Maps, YouTube, Bing, Walmart, eBay, Baidu, Yandex and more APIs for free in the interactive playground!
 SerpApiSerpApi
Take the first organic result from a coffee search on Google. This is everything JSON carries for it:
{
  "position": 1,
  "title": "Coffee",
  "link": "https://en.wikipedia.org/wiki/Coffee",
  "redirect_link": "https://www.google.com/url?sa=t&source=web&rct=j&opi=89978449&url=https://en.wikipedia.org/wiki/Coffee&ved=2ahUKEwiOsKzK96uWAxXmQjABHecdCtsQFnoECCcQAQ",
  "displayed_link": "https://en.wikipedia.org › wiki › Coffee",
  "thumbnail": "https://encrypted-tbn0.gstatic.com/images?q=tbn:ANd9GcQs1E6FVWWD12JBVWlsho0fGc7GxAR50Pf030IPyxJNl5A9xYPmgt_1&usqp=CAE&s",
  "favicon": "https://serpapi.com/images/i/iVBORw0KGgoAAAANSUhEUgAAABwAAAAcCAAAAABXZoBIAAAAnklEQVR4AeTNIQiDQABG4b-u17X1aF6PK3YEO9iMJqPVau82y4FgMezS0oVLhqsHtrcqeqzDXv3CEz_6L4yTtZM3dnHmPTtjzXZAXKYVo4agkU2GI2Lloc6JDez1-flswMu1EQZ3xlE7lK8eKDkjtwE-crBMV-wesKmCiisGGepZIfQJpMj9SNb2MYWrChjVkULuCyCfRvsdmBieyQQAsoDk_9ryhFMAAAAASUVORK5CYII.png",
  "snippet": "Coffee is a beverage brewed from roasted ground coffee beans. Dark-colored and bitter, coffee has a stimulating effect on humans due to its caffeine content;",
  "snippet_highlighted_words": [
    "a beverage brewed from roasted ground coffee beans"
  ],
  "about_this_result": {
    "source": {
      "description": "Coffee is a beverage brewed from roasted ground coffee beans. Dark-colored and bitter, coffee has a stimulating effect on humans due to its caffeine content;",
      "source_info_link": "https://en.wikipedia.org/wiki/Coffee",
      "icon": "https://serpapi.com/images/i/iVBORw0KGgoAAAANSUhEUgAAABwAAAAcCAAAAABXZoBIAAAAnklEQVR4AeTNIQiDQABG4b-u17X1aF6PK3YEO9iMJqPVau82y4FgMezS0oVLhqsHtrcqeqzDXv3CEz_6L4yTtZM3dnHmPTtjzXZAXKYVo4agkU2GI2Lloc6JDez1-flswMu1EQZ3xlE7lK8eKDkjtwE-crBMV-wesKmCiisGGepZIfQJpMj9SNb2MYWrChjVkULuCyCfRvsdmBieyQQAsoDk_9ryhFMAAAAASUVORK5CYII.png"
    },
    "languages": [
      "en"
    ],
    "regions": [
      "US"
    ]
  },
  "about_page_link": "https://www.google.com/search?q=About+https://en.wikipedia.org/wiki/Coffee&tbm=ilp",
  "about_page_serpapi_link": "https://serpapi.com/search.json?engine=google_about_this_result&google_domain=google.com&q=About+https%3A%2F%2Fen.wikipedia.org%2Fwiki%2FCoffee",
  "source": "Wikipedia"
}
And the same result as a Markdown table row:
## Organic Results
| Position | Title | Thumbnail | Snippet | About Page Link | Source | Read More Link | Date |
| --- | --- | --- | --- | --- | --- | --- | --- |
| 1 | [Coffee](https://en.wikipedia.org/wiki/Coffee) |  | Coffee is a beverage brewed from roasted ground coffee beans. Dark-colored and bitter, coffee has a stimulating effect on humans due to its caffeine content; | https://www.google.com/search?q=About+https://en.wikipedia.org/wiki/Coffee&tbm=ilp | Wikipedia | | |Nothing the model needs is missing. The position, title, thumbnail, snippet, and source are all kept in the output, and the row costs a fraction of the tokens the object did. Across the full coffee response, the JSON weighs 24,723 tokens and the markdown 6,435, a 74% cut.
Here are some examples:
In JSON a result splits its data across separate fields:
"title": "Coffee",
"link": "https://en.wikipedia.org/wiki/Coffee",
"displayed_link": "https://en.wikipedia.org › wiki › Coffee"
In Markdown that is one cell:
[Coffee](https://en.wikipedia.org/wiki/Coffee)The model gets the title and the URL already bound together.
The same JSON result also carries a redirect_link (a 150-character Google tracking URL), a 320-character favicon URL, and internal metadata objects:
"redirect_link": "https://www.google.com/url?sa=t&source=web&rct=j&opi=89978449&url=https://en.wikipedia.org/wiki/Coffee&ved=2ahUKEwiOsKzK96uWAxXmQjABHecdCtsQFnoECCcQAQ",
"favicon": "https://serpapi.com/images/i/iVBORw0KGgoAAAANSUhEUgAAABwAAAAcCAAAAABXZoBIAAAAnklEQVR4AeTNIQiDQABG4b-u17X1aF6PK3YEO9iMJqPVau82y4FgMezS0oVLhqsHtrcqeqzDXv3CEz_6L4yTtZM3dnHmPTtjzXZAXKYVo4agkU2GI2Lloc6JDez1-flswMu1EQZ3xlE7lK8eKDkjtwE-crBMV-wesKmCiisGGepZIfQJpMj9SNb2MYWrChjVkULuCyCfRvsdmBieyQQAsoDk_9ryhFMAAAAASUVORK5CYII.png"
None of that helps a model answer a question about coffee. The Markdown Output strips them automatically, and you can check the table row above; none of these fields made it in. The title, link, snippet, and source remain.
Markdown does not flatten the response into prose. Each result array becomes a table, and the nine organic results of our coffee search arrive as nine rows under one header:
## Organic Results
| Position | Title | Thumbnail | Snippet | About Page Link | Source | Read More Link | Date |
| --- | --- | --- | --- | --- | --- | --- | --- |
| 1 | [Coffee](https://en.wikipedia.org/wiki/Coffee) |  | Coffee is a beverage brewed from roasted ground coffee beans. Dark-colored and bitter, coffee has a stimulating effect on humans due to its caffeine content; | https://www.google.com/search?q=About+https://en.wikipedia.org/wiki/Coffee&tbm=ilp | Wikipedia | | |
| 2 | [Fresh Roasted, Single Origin Coffee Beans](https://creaturecoffee.co/collections/coffee?srsltid=AfmBOoo5rAxqBgQmreq6MaHX-U_rw-P5UI-90YLvKI1oRGTosk_eXwMU) | | Creature Coffee roasts single origin coffee beans from around the globe right here in Austin, Texas. | https://www.google.com/search?q=About+https://creaturecoffee.co/collections/coffee?srsltid=AfmBOoo5rAxqBgQmreq6MaHX-U_rw-P5UI-90YLvKI1oRGTosk_eXwMU&tbm=ilp | Creature Coffee Co | | |
| 3 | [Coffee Shops Austin, TX - Last Updated August 2026](https://www.yelp.com/search?find_desc=Coffee+Shops&find_loc=Austin%2C+TX) | | Coffee Shops Austin, TX · 1. Mazúr Coffee · 2. Palomino Coffee · 3. Idlewild Coffee · 4. Desnudo Coffee · 5. Flora Coffee · 6. Daydreamer Coffee. 3.9 ... | https://www.google.com/search?q=About+https://www.yelp.com/search?find_desc=Coffee+Shops&find_loc=Austin%2C+TX&tbm=ilp | Yelp | https://www.yelp.com/search?find_desc=Coffee+Shops&find_loc=Austin,+TX#:~:text=Coffee%20Shops%20Austin%2C%20TX&text=1.%20Maz%C3%BAr%20Coffee&text=2.%20Palomino%20Coffee&text=3.%20Idlewild%20Coffee&text=4.%20Desnudo%20Coffee&text=5.%20Flora%20Coffee&text=6.%20Daydreamer%20Coffee,3.9%20(25%20reviews) | |
| 4 | [r/Coffee](https://www.reddit.com/r/Coffee/) | | This is a place to share and talk about your favorite coffee roasters or beans. recommendations, reviews, etc. | https://www.google.com/search?q=About+https://www.reddit.com/r/Coffee/&tbm=ilp | Reddit · r/Coffee | | |
| 5 | [Cuvée Coffee: Always Something Brewing. Austin, TX](https://cuveecoffee.com/?srsltid=AfmBOorjX3_f5tAt5zldI8Vqr4pNmmfh2FRWlZcVVMEGXhowAfzLZ_Jt) | | At Cuvée, coffee isn't a job, it's a passion. Since 1998, we've become known for roasting exceptional, ethically sourced, sustainable coffee. | https://www.google.com/search?q=About+https://cuveecoffee.com/?srsltid=AfmBOorjX3_f5tAt5zldI8Vqr4pNmmfh2FRWlZcVVMEGXhowAfzLZ_Jt&tbm=ilp | Cuvée Coffee | | |
| 6 | [Coffee - The Nutrition Source](https://nutritionsource.hsph.harvard.edu/food-features/coffee/) | | Various polyphenols in coffee have been shown to prevent cancer cell growth in animal studies. Coffee has also been associated with decreased estrogen levels, a ... | https://www.google.com/search?q=About+https://nutritionsource.hsph.harvard.edu/food-features/coffee/&tbm=ilp | The Nutrition Source | https://nutritionsource.hsph.harvard.edu/food-features/coffee/#:~:text=Type%202%20Diabetes | |
| 7 | [Texas Coffee Traders](https://texascoffeetraders.com/) | | No information is available for this page. | https://www.google.com/search?q=About+https://texascoffeetraders.com/&tbm=ilp | Texas Coffee Traders | | |
| 8 | [33 Best Coffee Shops In Austin, Sorted By Neighborhood](https://www.atasteofkoko.com/visit-austin/coffee-shops-in-austin) | | Best Coffee Shops in Central Austin · Hank's · Civil Goat Coffee Roasters (Central) · Merit Coffee (Central) · Bennu Coffee · Terrible Love. | https://www.google.com/search?q=About+https://www.atasteofkoko.com/visit-austin/coffee-shops-in-austin&tbm=ilp | A Taste of Koko | https://www.atasteofkoko.com/visit-austin/coffee-shops-in-austin#:~:text=Best%20Coffee%20Shops%20in%20Central,Austin&text=Hank's&text=Civil%20Goat%20Coffee%20Roasters%20(Central)&text=Merit%20Coffee%20(Central)&text=Bennu%20Coffee&text=Terrible%20Love | Apr 22, 2026 |
| 9 | [Try the new gold standard of coffee at home!](https://icoffee.co/) | | At Industry Coffee, we take great care in every step of our coffee making process. From selecting the best beans, to roasting, brewing, and blending our ... | https://www.google.com/search?q=About+https://icoffee.co/&tbm=ilp | Industry Coffee | https://icoffee.co/#:~:text=At%20Industry%20Coffee%2C%20we%20take,committed%20to%20quality%20and%20consistency. | |The same happens for shopping results, hotel listings, and any other result array.
The response also opens with a YAML frontmatter block carrying the search parameters and metadata:
---
search_metadata:
  id: 6a853ba34c437ff2e1aa1265
  status: Success
  json_endpoint: "https://serpapi.com/searches/cPnrW0xTHlgDT2yVVjFSmg/6a853ba34c437ff2e1aa1265.json"
  markdown_endpoint: "https://serpapi.com/searches/cPnrW0xTHlgDT2yVVjFSmg/6a853ba34c437ff2e1aa1265.md"
  pixel_position_endpoint: "https://serpapi.com/searches/cPnrW0xTHlgDT2yVVjFSmg/6a853ba34c437ff2e1aa1265.json_with_pixel_position"
  created_at: "2026-08-19T05:14:11.488Z"
  processed_at: "2026-08-19T05:14:11.497Z"
  google_url: "https://www.google.com/search?q=Coffee&oq=Coffee&uule=w+CAIQICIaQXVzdGluLFRleGFzLFVuaXRlZCBTdGF0ZXM&hl=en&gl=us&sourceid=chrome&ie=UTF-8"
  raw_html_file: "https://serpapi.com/searches/cPnrW0xTHlgDT2yVVjFSmg/6a853ba34c437ff2e1aa1265.html"
  total_time_taken: 1.91
search_parameters:
  engine: google
  q: Coffee
  location_requested: Austin, Texas, United States
  location_used: Austin,Texas,United States
  google_domain: google.com
  hl: en
  gl: us
  device: desktop
---
So even in text form you still have the search id, status, and the endpoints to fetch the same search again in either format.
Both formats come from the same search, so this is not a migration. It is a per-call choice.
Markdown fits when:
JSON fits when:
Simply put: if a model reads it, use Markdown. If code reads it, use JSON.
Before Markdown Output, the tool for cutting response size was the JSON Restrictor, and it is still the right tool when you stay on JSON. You pass a field selector with the request, and SerpApi filters the response server-side before sending it back. We have used it for exactly this purpose in earlier posts, like connecting a local LLM to web search data, where trimming the JSON was the difference between fitting the context window or not.
SerpApi: JSON Restrictor
Restrict the SERP JSON to the fields you need.
 SerpApi
If your pipeline needs structured fields but not all of them, the restrictor alone gets you most of the way. We'll request only the two fields an agent might rank on, position and title:
curl "https://serpapi.com/search?engine=google&q=Coffee&location=Austin,+Texas,+United+States&api_key=YOUR_KEY&json_restrictor=organic_results[].position,organic_results[].title"The response is the whole search reduced to this:
{
  "organic_results": [
    {
      "position": 1,
      "title": "Coffee"
    },
    {
      "position": 2,
      "title": "Cuvée Coffee: Always Something Brewing. Austin, TX"
    },
    {
      "position": 3,
      "title": "Coffee Shops Austin, TX - Last Updated August 2026"
    },
    {
      "position": 4,
      "title": "r/Coffee"
    },
    {
      "position": 5,
      "title": "Coffee - The Nutrition Source"
    },
    {
      "position": 6,
      "title": "Texas Coffee Traders"
    },
    {
      "position": 7,
      "title": "50 Best Austin Coffee Shops You Should Try"
    },
    {
      "position": 8,
      "title": "Buy Coffee, Tea, Powders Online | The Coffee Bean & Tea ..."
    },
    {
      "position": 9,
      "title": "History of coffee - NCA"
    }
  ]
}
You keep exact types and programmatic access, and drop every section your code never touches. The difference with Markdown Output is what each one removes. The restrictor cuts entire fields and sections you name, while Markdown keeps every section but re-renders it in a lighter format. One subtracts data, the other changes its shape.
You don't have to pick one. Pass json_restrictor on a Markdown request, and SerpApi first filters the sections, then renders only what is left as Markdown:
curl "https://serpapi.com/search.md?engine=google&q=Coffee&location=Austin,+Texas,+United+States&api_key=YOUR_KEY&json_restrictor=organic_results"The response is just the Organic Results table from earlier, nothing else. On our coffee search, the four levels look like this:
| Request | Tokens |
|---|---|
| Full JSON | 24,723 |
JSON + json_restrictor=organic_results |
8,486 |
| Full markdown | 6,435 |
Markdown + json_restrictor=organic_results |
1,298 |
That is a 95% reduction from the original JSON, and you chose exactly which part of the search enters the model's context. For an agent that only reasons over organic results, everything else was noise anyway.
Markdown Output is live today on every SerpApi plan, at no extra cost, across all 100+ APIs. Same searches, same credits, and around 50% fewer tokens on average and up to 90% for some APIs.
The fastest way to see what it does for you is to take an API you already use, add output=md to one request, and count the tokens before and after.
SerpApi: Markdown Output for AI Agents
Get search results as clean, token-efficient markdown instead of JSON. Built for LLMs, AI agents, and agentic workflows.
 SerpApi
SerpApi: JSON Restrictor
Restrict the SERP JSON to the fields you need.
 SerpApi
Introducing SerpApi Search Tools: Real-Time Web Search for Python AI Agents
The `serpapi-search-tools` package gives Python agents real-time access to the web, news, maps, images, shopping, YouTube, hotels, flights, and travel search, powered by SerpApi. It natively supports popular SDKs including LangChain, Agno, CrewAI, OpenAI Agents, Pydantic AI, Google ADK, and more.
 SerpApiAdarsh Divakaran
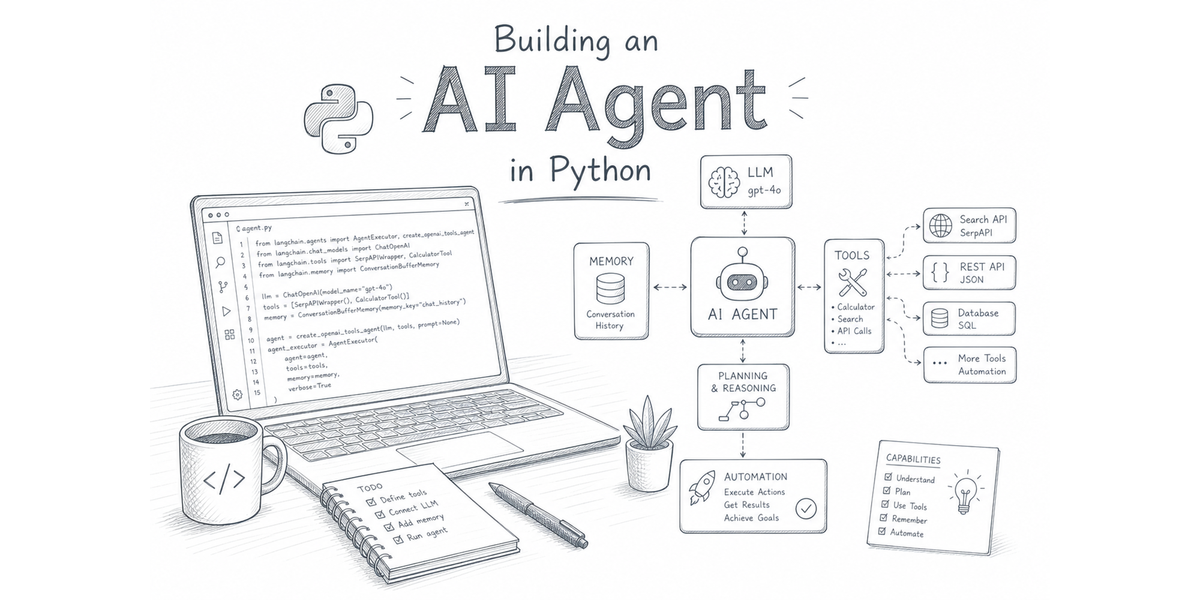
Building an AI Agent in Python
Learn to build AI agents in Python by understanding the core pieces behind them: LLMs, tools, memory, context, and the agent loop.
 SerpApiAdarsh Divakaran
How to Connect Your Local LLM with Web Search Data
Give your local LLM real-time web data. Build a TypeScript chat app that calls SerpApi and keeps every response inside a small context window.
 SerpApiTomás Murúa
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。