


Take the 2026 AI Engineering Survey and get >$2k in credits and AIE WF tickets!
Congrats to all our past guests who reached huge milestones this week:
Turbopuffer: $100M ARR and profitable (our podcast)
Exa: $250M@$2.2B Series C (our podcast)
Modal: $355M@$4.7B Series C (our podcast)
We really need to be raising that Latent Space fund soon… but meanwhile.. help us out by taking the 2026 AI Engineering Survey and get >$2k in Notion and Vercel credits and AIE WF tickets!
AI News for 5/20/2026-5/21/2026. We checked 12 subreddits, 544 Twitters and no further Discords. AINews’ website lets you search all past issues. As a reminder, AINews is now a section of Latent Space. You can opt in/out of email frequencies!
Model, Benchmark, and Research Updates: RAEv2, Gated DeltaNet-2, Data Filtering, and Open Math
RAEv2 and representation-first tokenization: Several researchers highlighted RAEv2 as a meaningful follow-on to Representation Autoencoders for unified vision understanding and generation. @1jaskiratsingh says the update yields >10x faster convergence, better reconstruction, and better generation, with tests extending to text-to-image and world models. A Chinese summary from @recatm usefully extracts the three main findings: summing the last K encoder layers instead of only the final layer improves both reconstruction and generation without added inference cost; RAE and REPA are complementary across semantics vs. spatial structure; and REPA can be reformulated as an internal self-guidance mechanism, avoiding extra weak-model guidance passes. @sainingxi`e also points to new evaluation views beyond FID, arguing there is still underexplored headroom in representation-powered pixel decoders.
Alternatives to standard attention and tokenizer assumptions: NVIDIA’s Gated DeltaNet-2 decouples erase and write operations in linear attention with channel-wise gates, outperforming KDA and Mamba-3 at 1.3B parameters on language modeling and commonsense reasoning, with notable long-context retrieval gains on RULER; @rasbt called it one of the more interesting hybrid-attention directions. On tokenization, @NousResearch released a controlled study of why subword tokenization helps, simulating seven hypothesized benefits inside a 1.7B byte-level pipeline; only three of seven interventions moved validation loss at that scale. Separately, @tatsu_hashimoto reported a surprising scaling result on DCLM: with enough compute, the best data filter may be no filter, with projections suggesting the crossover for internet-scale pools lands around 1e30 FLOPs; downstream evals appear noisy but directionally consistent (follow-up).
Mechanistic interpretability and geometry: @GoodfireAI argues the dominant “models think in curved manifolds, SAEs use straight-line features” critique is only partly right. Their proposed fix is to cluster SAE features by joint firing patterns, recovering geometry through feature groups rather than isolated atoms (thread continuation, post). This is a useful update to the current SAE discourse: not a rejection of sparse features, but a warning that interpretation should move from single features to structured ensembles.
Math as an AI research domain: The biggest scientific discussion centered on OpenAI’s reported result on an Erdős unit-distance problem. @markchen90 framed it as evidence that mathematics is currently the domain most amenable to AI-assisted research breakthroughs, while @wtgowers noted that if the reported low human interaction level holds, the result is genuinely interesting. The discourse was immediately shaped by skepticism and benchmark/gameability concerns, with @memecrashes joking that the result was “outdated not even 3 hours later by a human,” and @cloneofsimo pointing out the predictable “goalpost moving” around what counts as legitimate AI mathematics. The interesting technical meta-point is that math continues to function as a relatively legible frontier for AI co-research because outputs can be checked, debated, and extended.
Agents, Harnesses, and Developer Tooling: Codex, Gemini, Devin, and Agent Infrastructure
Harnesses are still a major source of capability gains: @lvwerra released physics-intern, a science-problem harness that boosts models like Gemini 3.1 Pro from 17.7 to 31.4, surpassing GPT 5.5 Pro in that setup. The notable nuance is that GPT 5.5 Pro itself did not benefit from the harness, suggesting model-specific absorption of scaffolding tricks. In the same spirit, @KLieret made mini-swe-agent runnable on ProgramBench, explicitly aiming to improve harness innovation around software engineering agents.
Agent design patterns are maturing from “single agent first” to explicit subagent orchestration: @cwolferesearch gives a practical synthesis: start with single-agent systems, and only move to manager/sub-agent or decentralized multi-agent topologies when tool sprawl or prompt bloat becomes unmanageable. That advice lines up with more operational observations from users of subagents: @andrew_locke describes Cognition’s sub-Devin workflow as a step change, compressing what previously looked like 2+ engineer-weeks into a couple of hours.
Codex shipped a substantial product layer on top of the model: OpenAI’s “Codex Thursday” updates matter less as standalone features than as signs of where coding agents are going. @OpenAIDevs launched Appshots, which capture both screenshot and text from Mac app windows for richer working context; they also added team plugin sharing (link) and more detailed org analytics (link). The more important systems shift is remote computer use: @OpenAIDevs says Codex can now securely use apps on your Mac from your phone even when the Mac is locked. This is a strong signal that the agent product surface is moving from chat IDEs to persistent cross-device operator workflows.
Gemini’s agent/tool story is broadening quickly: @OfficialLoganK highlighted that Gemini 3.5 Flash ranks #1 on APEX-Agents-AA, outperforming larger models. On the applied side, @_philschmid shows a GitHub issue triage agent built with a single Gemini API call and no orchestration framework, while @skalskip92 demonstrates Gemini 3.5 Flash replacing a custom vision pipeline for lane/car reasoning with one multimodal API call. Google also expanded action surfaces: Daily Brief (announcement) and connected-app actions with OpenTable, Canva, and Instacart (announcement) are essentially consumer-facing agent workflows.
Developer infra is converging around retrieval, streaming, sandboxes, and security boundaries: Weaviate shipped a built-in MCP server inside the database so coding agents can ingest a repo and use hybrid BM25 + vector retrieval without extra processes (announcement). LangChain introduced both a sandbox Auth Proxy for controlling agent-world boundaries (announcement) and a new typed streaming protocol for rendering tools, subagents, media, and interrupts as first-class projections rather than token streams (overview). vLLM’s Elastic Expert Parallelism is also notable systems work: @vllm_project describes live resizing of MoE DP/EP topology without full restarts, using direct GPU-to-GPU transfers over NVLink/RDMA—important not just for scaling but for future fault-tolerant serving.
Infrastructure, Compute, and AI Business Signals: Modal, Turbopuffer, Hark, and the Compute Race
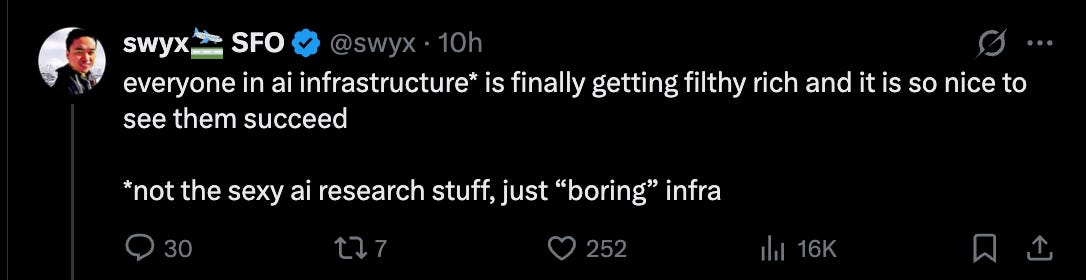
The infra layer had one of its clearest “this is where the money is” days: @Sirupsen said turbopuffer crossed $100M run-rate in March, just 19 months after $1M, while being profitable and raising < $1M. The company’s positioning is straightforward and timely: frontier teams know “the magic happens with AI when it draws in just the right context,” which turns a lot of product differentiation into a search/retrieval problem (follow-up). That aligns with broader sentiment from @swyx that “boring” AI infrastructure, not only glamorous frontier research, is where wealth creation is accruing.
Modal raised big and continues to look like a core AI cloud winner: @bernhardsson announced a $355M Series C at a $4.65B valuation. Investors and users emphasized the same thesis: rebuilding the cloud stack for AI workloads from the ground up, with strong performance and developer experience (Redpoint, user endorsement). This sits alongside other signals that agent-native compute is emerging as its own category; @latentspacepod summarized Daytona’s pitch around 60ms sandboxes, 50K startups in 75 seconds, and RL/evals workloads now representing roughly half of usage.
Compute remains the strategic bottleneck, and the market appears tiered: @AymericRoucher sketched a useful compute taxonomy: US leaders (OpenAI, Anthropic, Google, with Meta/xAI joining) in the multi-gigawatt class; Chinese giants scaling from hundreds of MW toward multi-GW, increasingly on domestic stacks; and European contenders such as Mistral at around 90 MW today aiming for 1 GW by 2029. The exact numbers are debatable, but the framing is consistent with @EpochAIResearch, which notes that even if OpenAI kicked off the recent compute buildout, frontier labs still use well under all global compute capacity, leaving open the question of how much further the buildout can accelerate. Component economics also continue to shift toward memory: @EpochAIResearch reports HBM grew from 52% to 63% of total AI chip component spending from Q1 2024 to Q4 2025.
Capital is flowing to interface/hardware bets as well as infra: @adcock_brett announced Hark raised $700M at a $6B valuation, aimed at GPU infrastructure, future model development, hardware, and multimodal/personal intelligence products. The details are sparse beyond hiring areas—foundation models, infra, speech, computer-use agents, hardware—but the size of the raise shows investor appetite for vertically integrated AI-device bets. Hark also reported a 200-hour uninterrupted autonomous run for F.03 (announcement), though without enough technical detail yet to evaluate the underlying robotics stack.
Multimodal, Video, Biology, and Robotics: Runway, Carbon, Earth Models, and Open Humanoids
Video editing and generation are getting more compositional: Runway launched Aleph 2.0 and the new Edit Studio, letting users edit a single frame and propagate that edit through the rest of the video (Runway, product lead). This is a practical productization of the “reference-guided edit propagation” problem that multimodal builders care about. Separately, Alibaba researchers’ MIGA was flagged by @HuggingPapers as a train-free method for infinite-frame video generation with a two-stage alignment mechanism for temporal consistency. On the open-source avatar side, Meituan released LongCat-Video-Avatar 1.5 with Whisper-Large replacing Wav2Vec2, 8-step inference, long-video identity consistency, and broader stylized-domain generalization (announcement).
Foundation models for biology and Earth observation continue to become more usable: Hugging Face Bio’s Carbon DNA model family got follow-on demos and infra validation. @LoubnaBenAllal1 highlighted applications in sequence design, variant effect prediction, and learned representations, while @Shekswess showed Carbon-500M, 3B, and 8B compiling and running on a single Trainium2 trn2.3xlarge with NxD Inference on day one. For geospatial modeling, @cgeorgiaw reported OlmoEarth v1.1 is 3x cheaper/faster by changing the tokenization of multi-resolution Sentinel-2 inputs into 3x fewer tokens, exploiting the quadratic compute savings.
Open robotics is getting more buildable: Hugging Face’s LeRobot Humanoid drew attention as a genuinely full-stack open release rather than a showcase demo. @robotsdigest and @lukas_m_ziegler both emphasize the same package: roughly $2.5k, 3D-printed, complete hardware/CAD, calibration/runtime, simulation, identification tools, and training pipelines. The key point is not just affordability; it’s repairability and iteration speed for real robot learning workflows.
Top tweets (by engagement)
OpenAI / Codex product expansion: Codex can securely use apps on your Mac from your phone, even when the Mac is locked, plus Appshots for richer app context.
Infrastructure winners: turbopuffer at $100M run-rate, profitable, < $1M raised; Modal raises $355M Series C at $4.65B; Hark raises $700M at $6B.
Research discussions with broad technical resonance: OpenAI’s Erdős-related math result discussion; RAEv2 release; “no filter” scaling result for LM data curation.
Agent capability trendlines: Gemini 3.5 Flash tops APEX-Agents-AA; Gemma 4 E4B driving an iOS simulator on-device via Argent; Devin for Windows.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。