





Stolen CPU is a metric that’s often looked at but can be hard to understand. It implies some malevolent intent from your virtual neighbors. In reality, it is a relative measure of the cycles a CPU should have been able to run but could not due to the hypervisor diverting cycles away from the instance. From the point of view of your application, stolen CPU cycles are cycles that your application could have used.
Some of these diverted cycles stem from the hypervisor enforcing a quota based on the ECU you have purchased. In other cases, such as the one shown below, the amount of diverted or stolen CPU cycles varies over time, presumably due to other instances on the same physical hardware also requesting CPU cycles from the underlying hardware.
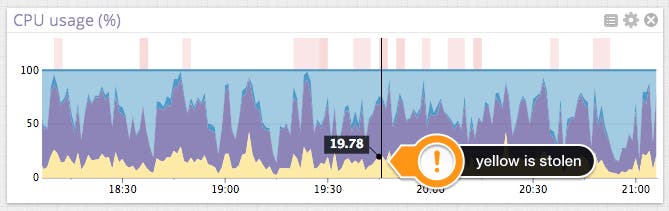
Here is a graph of CPU usage on a host with stolen CPU in yellow. Light blue denotes “idle” or available cycles, purple denotes “user” or cycles spent executing application code, and dark blue denotes “system” or cycles spent executing kernel code. In this case we can see that the amount of “stolen” CPU is clearly visible.

Let us now find out whether other tenants on the same machine can affect the amount of stolen CPU. The following graphs show the amount of stolen CPU (top) and the amount of idle CPU (bottom), both measured in percent of all CPU cycles for the same machine at the same time. CPU usage is sampled from the operating system of the instance every 15 seconds.

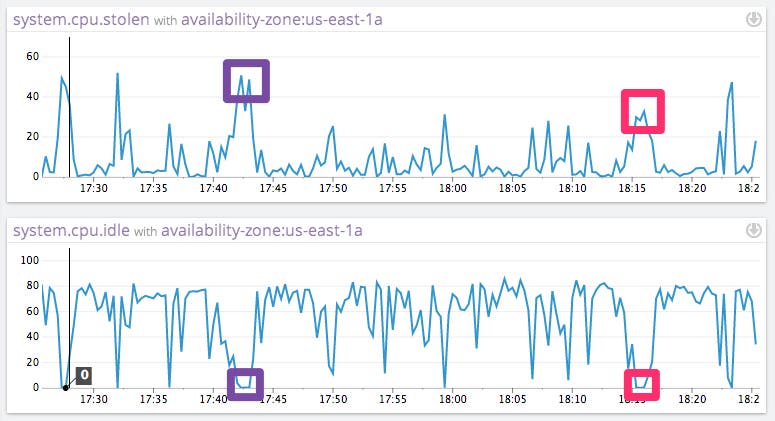
The interesting part occurs when idle CPU reaches zero. All cycles have been accounted for, either doing useful work (not represented here) or being taken away by the hypervisor (the stolen CPU graph).
Notice that at in the highlighted sections, the amount of stolen CPU differs from 30% (red) to 50% (purple). If the ECU quota were the only thing causing CPU to be stolen, we should expect the stolen CPU to be equal at these two points in time.
Stolen CPU is particularly problematic for CPU intensive applications which will more frequently attempt to run at or near the threshold for ECUs you’ve purchased. These applications use more cycles and have idle CPU at zero more often.
If the hypervisor is simply enforcing a quota based on ECUs you’ve purchased, you would expect consistent values of stolen CPU when idle CPU approaches zero. If this is case, the limitation set by your instance quota would slow down your application in a consistent and predictable way. You are getting the ECUs you purchased and can increase application performance by upgrading your instance.
If instead you’re seeing varying values for stolen CPU it’s likely that you and other tenants are requesting more CPU cycles than are available on your hardware. Because you have no insight into other tenants CPU usage behavior, it can be difficult or impossible to predict the amount of stolen CPU you will see as your application approaches idle CPU of zero. In this case, you are not consistently getting the ECUs you purchased and the changing CPU availability means you can’t predictably forecast performance for your application.
Buy more powerful EC2 instances
Baseline your application compute needs
Profile your app on an EC2 instance before finalizing a deploy decision
Re-deploy your application in another instance
For more information on this and other AWS EBS Performance issues, check out our free eBook: The Top 5 Ways to Improve Your AWS EC2 Performance
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。