










Let’s be honest, sometimes you don’t care about all of your metrics. Maybe you just want to keep tabs on outliers such as the biggest memory hogs or the most overworked hosts. But, cutting through the metrics clutter can be tough when you have a dashboard graph that looks like this:
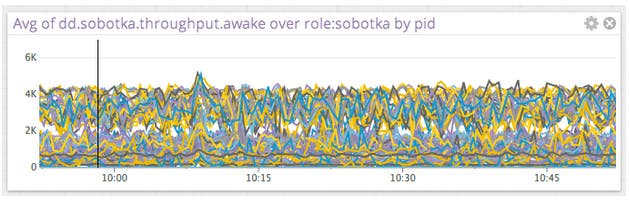
This graph is a measure of Datadog’s input throughput broken down by process and is nearly impossible to interpret. Alternatively, you could visualize these metrics as a heatmap, which buckets and aggregates the individual timeseries to produce something like this:
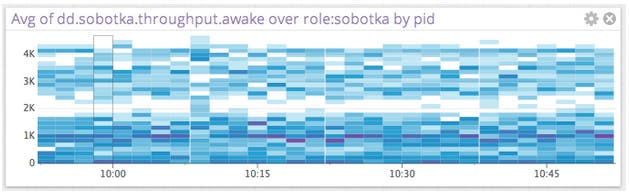
While this visualization gives you a good sense of how work is distributed at each moment in time, it takes a bit more effort to track the role of a single process. At the same time, the dozens of lines in the first graph aren’t exactly easy to trace through either.
top() FunctionsThis inability to easily cut through the metrics clutter is why we have introduced the top() family of functions. The top() family of functions gives you the power to rank, filter and visualize your performance metrics so you can focus on the metrics that are most important to you at any given time.
For instance, by looking at the five metrics with the highest average over the past hour, you can create something like this:
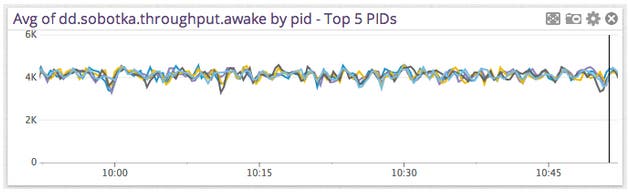
At a glance, this gives a much simpler and clearer view of the hardest-working intake processes.
top() Family of FunctionsThe top() function supports several ways of “ranking” timeseries against each other. We’ve designed the function this way because sometimes different features in a timeseries are important. For example, you might want to find the metrics with:
The highest peak values
The largest sustained average values, or
The highest most recent values
The top() function provides the flexibility to perform the above analyses, plus a few others. Here are a few examples to illustrate the power of ranking and filtering with the top() functions.
Here’s a look at system load by host in our production environment that was generated by the query system.load.1{*} by {host}:
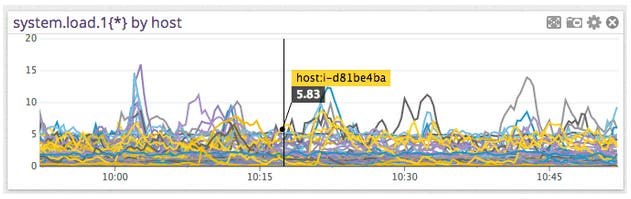
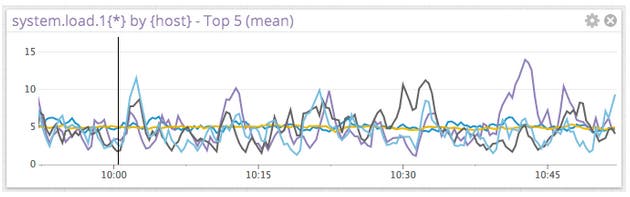
This query produces a lot of series that, at a glance, does not provide much value. However, by using smart filtering and changing the query from system.load.1{} by {host} to top5(system.load.1{} by {host}), we can filter out the “clutter” and only view the five series with the highest average value over the window of time.
Or we can look for peaks by using the top5_max function and run the query top5_max(system.load.1{*} by {host}).
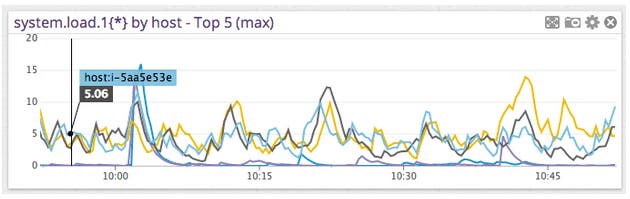
Notice how this view shows hosts with choppier behavior and higher peak values than the basic “top5” example.
If you’re interested in ranking by the latest reported value you can try the query top5_last(system.load.1{*} by {host}).
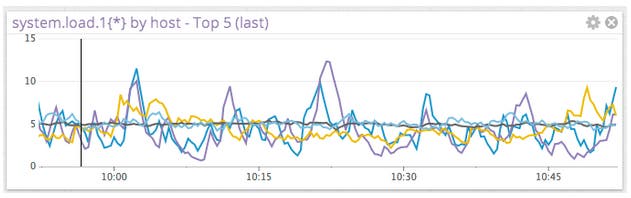
Compared to the previous examples, this graph selects from a few series with recent upward trends, such as the hosts indicated by the blue and purple lines.
You can also reverse the sort order to look at the lowest ranked series by querying for bottom5(system.load.1{*} by {host}).
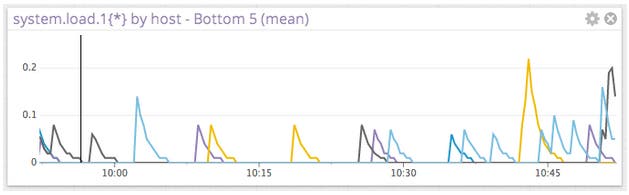
This graph displays the least loaded hosts over a given timeframe which is useful if you’re trying to quickly find places in your infrastructure where you can safely spawn new resources.
top_offset FunctionLet’s say you have a set of metrics that has one huge outlier that makes it difficult to view all of the metrics sets clearly. For instance, take the following query avg:dd.sobotka.payload.reads{role:sobotka} by {pid}:
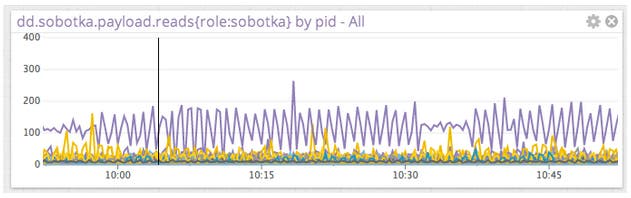
This is another metric from our intake pipeline and displays a large number of overlapping series with a clear outlier. Because of the effect of the outlier, the lower valued series are compressed together and hard to understand.
With the top_offset function, we can skip the outlier and concentrate on the next few series, giving a more granular look into how the metric values are distributed across processes. We can see the next two series by executing the query top_offset(avg:dd.sobotka.payload.reads{role:sobotka} by {pid}, 3, 'area', 'desc', 1) to get a graph that looks like this:
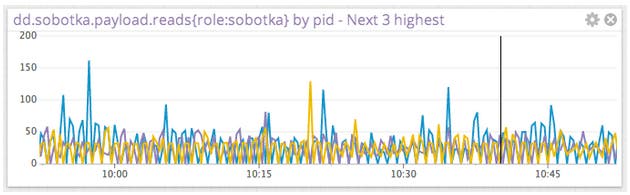
While there’s still some noise, the processes on this graph exhibit peaks across the window of time that are much easier to see than on the first graph. You can find the full syntax for the top_offset function at the end of this post.
At Datadog, we’re constantly thinking about better ways to use your metrics to help you understand your infrastructure better. We’ve found the top() family of functions are a powerful tool to gain insight into our infrastructure, and hope you find it useful as well. If you’d like to cut through the clutter and get the power to look at your most important metrics the way you want with Datadog’s top() family of functions, you can try Datadog for free for 14 days.
The top() function has the following syntax: top(series_list, num_series, rank_method, order), where:
series_list is a metric query string that will return one or more series, e.g., sum:system.mem.usable by {role}
num_series is an integer, giving the number of series to take from the whole set
rank_method will be described in more detail below, and
order is either desc or asc, where desc ranks the series highest-to-lowest and asc lowest-to-highest
To rank the series, we calculate a number, sort the series in ascending or descending order by that number, and then take the first numseries series from that list. The method used to calculate the number is given by the rank_method parameter. Currently, we support the following methodologies:
max: Rank by the maximum value the series take over the query window.
min: Rank by the minimum value the series take over the query window.
mean: Rank by the average value of the series.
area: Rank by the area traced out by the series over time, using zero as a reference point.
norm: Similar to area, except ”˜norm’ squares each series point first, ensuring that the result is positive. This is useful when you’re interested in how much a series is varying around zero.
last: Rank by the last reported value in the series.
The top_offset() function has similar parameters: top(series_list, num_series, rank_method, order, offset). The first four parameters are identical to those given to top(), while the last parameter gives the “offset,” or the number of elements in the ranked list to skip before graphing.
The top() function has a number of shortcuts, which are summarized in this chart below. As suggested by the chart, the number N in the topN functions can take a value of 5, 10, 15, or 20.
| Shortcut | num_series (= N) | method | asc / desc |
|---|---|---|---|
| topN | 5, 10, 15, 20 | mean | desc |
| topN_max | 5, 10, 15, 20 | max | desc |
| topN_min | 5, 10, 15, 20 | min | desc |
| topN_last | 5, 10, 15, 20 | last | desc |
| topN_area | 5, 10, 15, 20 | area | desc |
| topN_norm | 5, 10, 15, 20 | norm | desc |
| bottomN | 5, 10, 15, 20 | mean | asc |
| bottomN_max | 5, 10, 15, 20 | max | asc |
| bottomN_min | 5, 10, 15, 20 | min | asc |
| bottomN_last | 5, 10, 15, 20 | last | asc |
| bottomN_area | 5, 10, 15, 20 | area | asc |
| bottomN_norm | 5, 10, 15, 20 | norm | asc |
For more graphing functions and documentation, visit our docs site.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。