





Alexis Lê-Quôc
Last week we were glad to take part and sponsor two of the greatest WebOps/DevOps events in their Silicon Valley editions: Velocity and DevOpsDays. We learned a great deal from the customers we saw and all the devs and ops we met. If you missed these events, here’s a curated list of talks that made the strongest impression on the team and had a great reception from the audience.
Johan Bergstram, Associate Professor at Lund University, delivered one of Velocity’s keynote sessions on risk in System Design when applied to Web Operations. The notion of risk is intuitively and very acutely felt by all in our industry with uptime hailed as one of our key metrics and outages publicly discussed. Johan gave a short and illustrated overview of what risk really means once we get out of the trenches: how we formalize risk, how we measure it and how we (try to) control it.
He went on to give 5 key properties that he has observed at organizations that manage risk well:
They keep the discussion about risk alive.
They invite dissenting opinions to be heard.
They openly discuss the boundaries between being functional and utterly failing (e.g. running out of cash, crashing the site, etc.).
They closely monitor the gap between work being prescribed and work being performed.
They focus on understanding how people make trade-offs in order to guarantee safety (instead of treating people as a constant source of errors)
The video runs for 25 minutes; time well invested if you want a good overview into how they solve the risk equation.
Anomaly detection is certainly the hot topic of the year. Abe Stanway and Joe Cowie presented 2 new open source projects used internally at Etsy to detect anomalous metrics (Skyline) and correlate them with similar metrics (Oculus).
The premise of their work is the explosion of metrics that call for more than dashboarding to find the proverbial needle in the haystack. Skyline, the anomaly detection module, uses a collection of algorithms to score metrics and decide whether they should be flagged as anomalous. Oculus answers the other question: once I have an anomalous metric, how do I find others that exhibit the same pattern? The answer: by fingerprinting timeseries and storing the fingerprint in Elasticsearch.
More than the algorithms that are used, Skyline (Python) and Oculus (Ruby) provide a testbed for new ideas to the open source community. We have been working on similar ideas of metric ranking and anomaly detection,and we believe strongly that this is the way to go, so we are happy to see that the industry is moving in this direction.
<script class=”speakerdeck-embed” src=”//speakerdeck.com/assets/embed.js” async data-id=”14a43db08598013030a91231381d8bac” data-ratio=”1.77777777777778”></script>
The most math-heavy of the whole show, Baron Schwartz’ talk on abnormal behavior, born from his recent research into how to apply statistical process control to Web Ops gave a few insights and a blueprint to quantify abnormal behavior (spoiler alert: use an index of dispersion on exponentially weighted moving averages).
Probably the most important insight Baron gave us is the crucial distinction in computing between resource and work. He argued that a lot of metrics we capture and obsess about are measuring resources, not work. Work is what gets the business forward. Work consumes resources and only work metrics should be obsessed about. In other words, CPU utilization and system load are nice measures of resource consumption but are inoperative to tell us whether our systems are doing (useful) work.
Baron devoted a fair number of slides to the dangers of assuming normal distributions when there are none to be found. Normal distributions come with a lot of nice properties that make differentiating normal from abnormal, easy. Yet metrics from Web Ops are anything but normally distributed.
He has been using a workaround (often used in other industries) that is computationally cheap enough to run often, statistically sound and yields good results in practice. The recipe: Compute exponentially weighted moving averages (EWMA) of work metrics. And then control its variance (i.e. 99.7% of values will fall within 3 standard deviations from the mean).
Why is the EWMA usable? Owing to the central limit theorem, the moving average itself will tend to a normal distribution so the traditional control methods will apply reasonably well. The exponential decay built in the moving average will cause sudden spikes to not throw off the controls.
If you use Datadog, you can already compute the EWMA of your metrics on the fly.
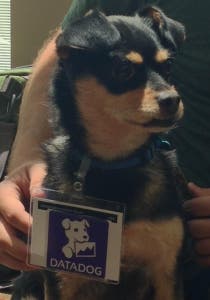
We were also excited and honored to meet the Data dog at DevOpsDays:
Stay tuned to see breakdowns from other enlightening Velocity and DevOpsDays sessions in part II of this blog.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。