





A simple but non-obvious one-line change (ANY(ARRAY[...]) to ANY(VALUES(...))) in a (bad) PostgreSQL 9.0 query cuts query time from 20s to 0.2s. Starting with low-level metrics we make our way to your best friend: EXPLAIN ANALYZE. The amount of time invested will pay off a hundred times over. The Postgres community is your second best friend.
Earlier this week the performance of one of our (many) databases was plagued by a few pathologically large, primary-key queries in a smallish table (10 GB, 15 million rows) used to feed our graph editor.
In 99.9% of accounts these queries would be zippy. In a few cases where the number of tags used to annotate metrics is large, these queries would take up to 20 seconds. That much time spent in a database meant that someone was waiting in front of their browser for the graph editor to respond. This is obviously not the best experience for the unlucky 0.1%.
Here is the surprisingly simple culprit:
Table X contains a few thousand rows, Table C contains 15 millions rows. Both “key” columns are primary keys with proper indexing. Pretty straightforward, it’s a simple primary key lookup. Where things get interesting is when you increase the number of keys. At 11,000 keys we get the following plan, by prefixing EXPLAIN (ANALYZE, BUFFERS) to the query:
As you can see at the bottom of the plan, the query took 22 seconds to execute. These 22 seconds can be visualized on the following graph as pure CPU execution split 90/10 between Postgres and the OS; very little disk I/O.
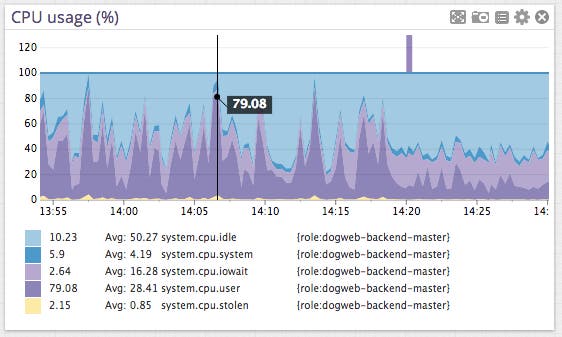
At the lowest level these queries would look like these spikes of CPU utilization. CPU graphs are seldom useful but in this case it confirmed a crucial point: the database was not waiting for the disks to read data. It was doing things like sorting, hashing and comparing rows.
The second interesting metric that tracks the spikes very closely is the number of rows that are “fetched” by Postgres (in this case not returned, just looked at and discarded).
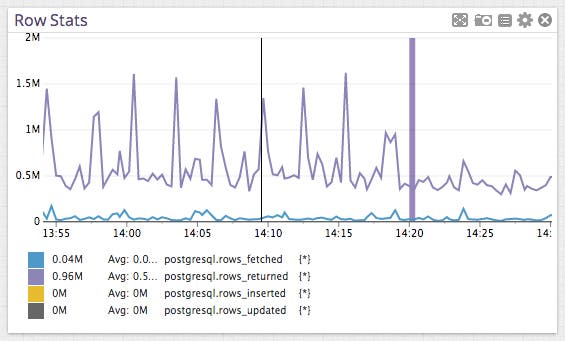
Clearly something is regularly and methodically going through a lot of rows: our query.
The rows_fetched metric is consistent with the following part of the plan:
Postgres is reading Table C using a Bitmap Heap Scan. When the number of keys to check stays small, it can efficiently use the index to build the bitmap in memory. If the bitmap gets too large, the query optimizer changes the way it looks up data. In our case it has a large number of keys to check so it uses the more approximative way to retrieve the candidate rows and checks each row individually for a match on x_key and tags. All this “loading in memory” and “checking individual row” takes time (the Recheck Cond in the plan). Luckily for us the table is 30% loaded in RAM so it is not as bad as retrieving the rows from disk. It still has a very noticeable impact on Postgres performance. Remember that the query is quite simple. It’s a primary key lookup so there aren’t many obvious ways to fix it without dramatically re-architecting the database or the application. We turned to the community for help via the PGSQL-Performance mailing list.
This is yet another reason why we love open source and its culture of helping users. Tom Lane), one of the most prolific open source authors around, suggested to try this instead:
Can you spot the difference? ARRAY has been changed to VALUES.
The query optimizer is fooled by the use of ARRAY[...] to list all the primary keys to look up. VALUES (...), (...) lets the optimizer make full use of the primary key index instead. It is literally a one-line change, which makes no semantic difference.
Here is the plan of the new query. The 2 major differences are on lines 3 and 14.
From 22,000ms to 200ms. That’s a 100x speedup for a simple one-line change.
A short code deploy later:
And the database looks much happier.
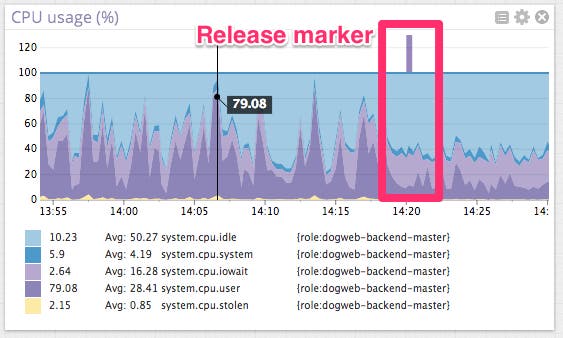
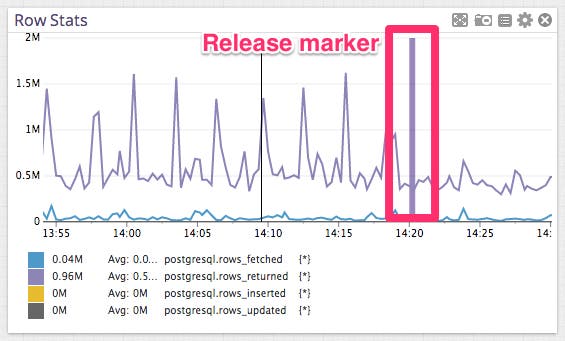
The slow Postgres query is gone. The 0.1% unlucky few who would have been affected by the issue are happy too. Seeing the impact of the change using Datadog allowed us to instantly validate that altering that part of the query was the right thing to do.
Update: this change need only be applied on 9.0. As of Postgres 9.3, ANY(ARRAY[...]) is performing properly again.
You can get that visibility set up in minutes by signing up for a free Datadog account if you’re looking to try out this change to your Postgres queries.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。