



Neal Kemp
This is a guest post from Neal Kemp, CTO of GovPredict.
GovPredict is a platform that provides unique data and insights to a wide variety of enterprise and government clients. To our clients, having the right data in hand can make a difference in whether you pass a law, elect a candidate, or close a large business deal. Therefore, it’s extremely important that we get our data right every time.
GovPredict serves up more than 50 types of data from thousands of different sources. To complicate things further, the data is collected in a variety of different ways—APIs, scraping, streaming, you name it! Needless to say, data accuracy is a difficult problem to solve.
Before using Datadog, we had a very manual and developer-intensive data monitoring stack. We were running a combination of various open source and system-specific monitoring tools. While this setup may work for some companies, it was pulling our developers off of building our product. We decided that we wanted to focus more on our core business and offload the monitoring responsibility to a hosted service.
Our primary goals with the switchover were to ease problem diagnosis, optimize system performance, ensure data quality, and reduce the developer burden of maintaining a monitoring stack.
Datadog nailed all of our problems after we set it up. We were able to integrate Datadog into most systems within the first day, and the rest within the first week. We now monitor all of our systems using Datadog and don’t plan on turning back.
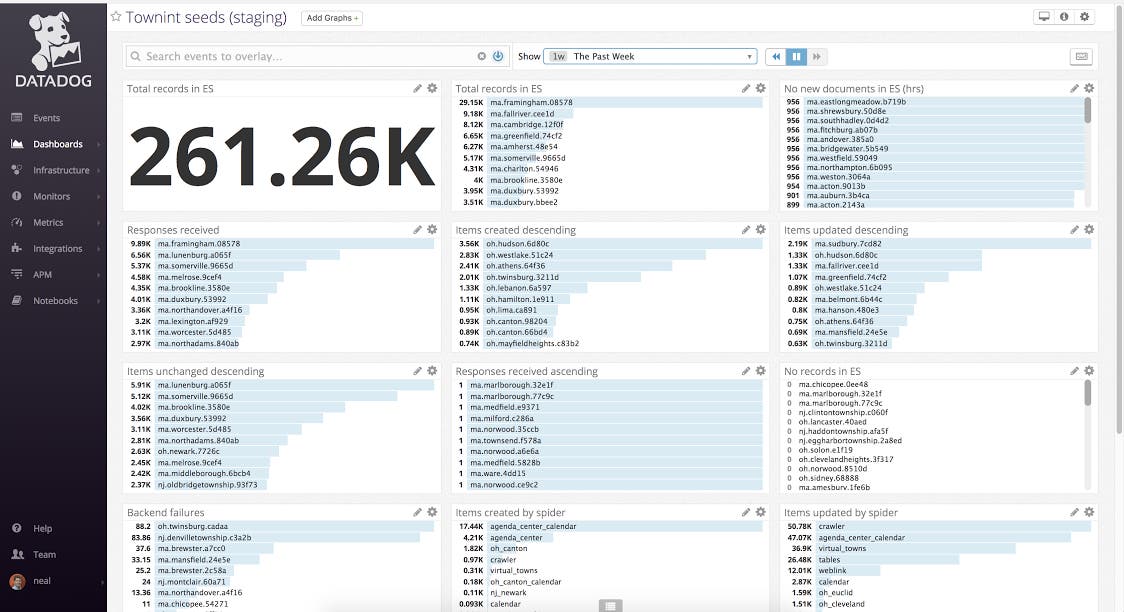
We set up a dashboard for each of our major importing systems. By superimposing import successes on failures, we can get quick insights into our error counts relative to the volume of successes. We can also filter by data type and source to dial in on source-specific data errors. Diagnosis of data quality issues now takes minutes rather than hours. These quick, visual insights allow us to jump in and fix errors without delay.
In terms of data quality, we were able to reduce diagnosis time significantly. We were also able to reduce the number of errors by identifying problems we would not have detected with our old monitoring systems. Overall, we have seen higher data consistency thanks to implementing and analyzing with Datadog.
It doesn’t stop with data quality, either—we also use Datadog to monitor all of our production applications and databases. It has been helpful in diagnosing downtime and finding opportunities to optimize database loads.
We discovered one unexpected benefit of Datadog while building a new piece of software. This new software analyzes more than 10,000 different data sources every day. We were a bit worried about performance, so we first built a prototype system that analyzed 200 sources per day. Using Datadog, we were able to benchmark performance and make improvements before building out the rest of the system. Using our old stack, it would have been very difficult or impossible to achieve the same results.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。