








Monitoring is built around the system a team understands at a point in time. Engineers add endpoints, move dependencies, and change user flows every day. Over time, that creates coverage drift as monitors keep reflecting the system as it used to behave, while changing paths introduce failure modes that teams didn’t yet know to watch for.
Bits Detection automatically creates, tunes, and maintains monitors for your services. It draws on the telemetry, ownership, and deployment history Datadog already tracks, and on your source code when connected. From there, it identifies what needs coverage, sets detection rules for each endpoint, and adjusts them as systems change.
In this post, you’ll learn how Bits Detection helps you:
Identify which service paths need detection
Set detection logic from production behavior
Update coverage as services change
Connect detections to investigation and remediation
Not every degradation has the same level of risk. A slow internal endpoint might be tolerable for several minutes, while a failing checkout, signup, or authentication path can affect customers almost immediately. Aggregate service health metrics do not make that distinction. A service may appear fine at the top level while one critical path is failing.
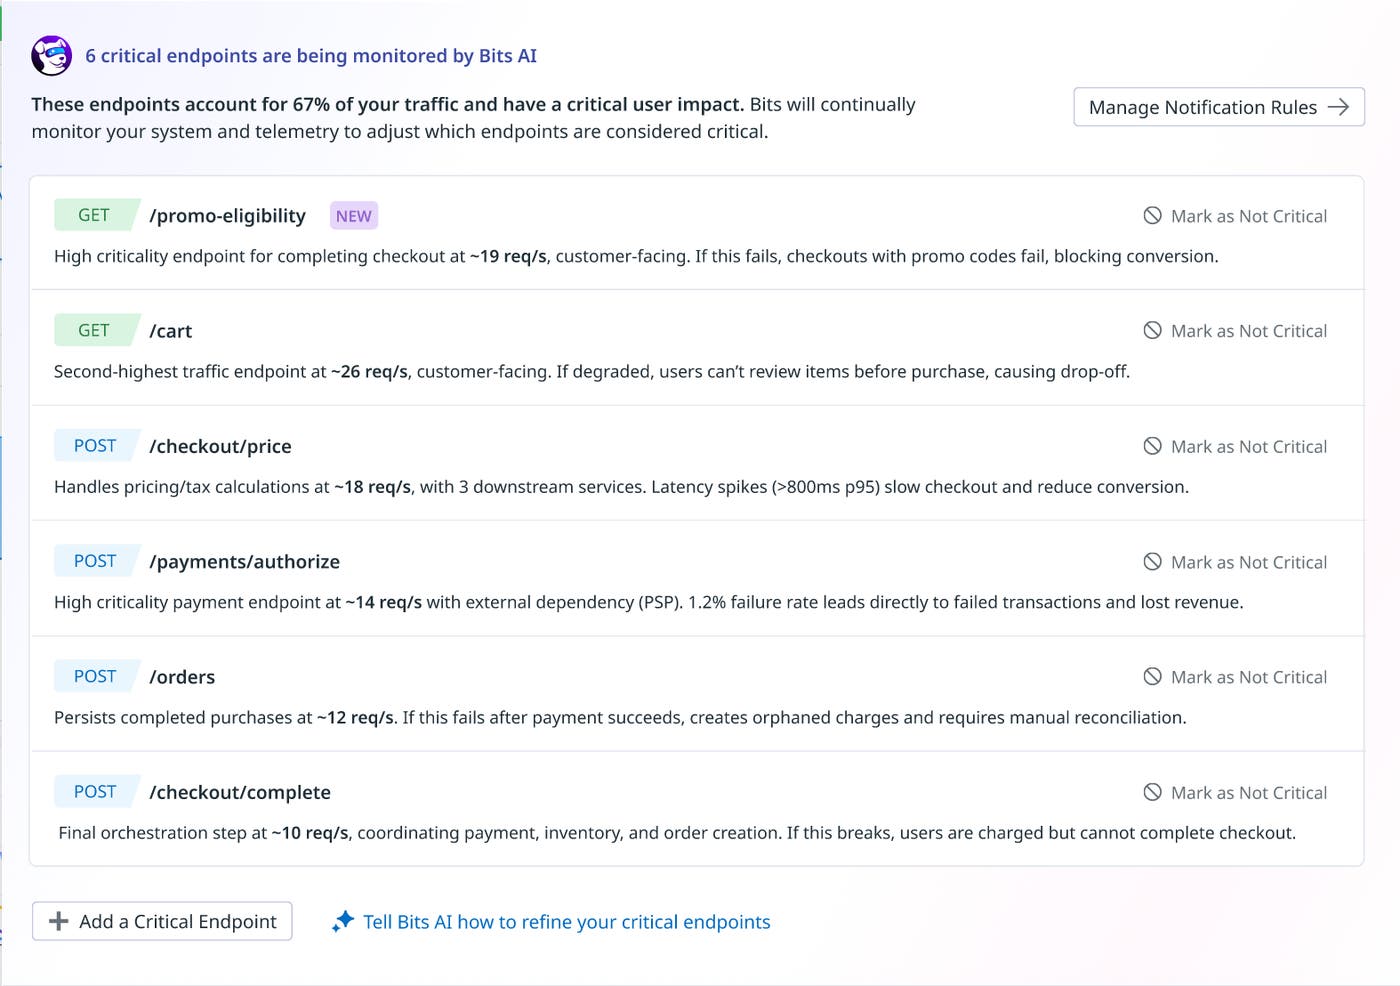
Bits Detection uses the context already in Datadog to determine which parts of a service require detection coverage. It draws on service behavior, historical telemetry, dependency topology, team ownership metadata, recent deployments, and user impact signals to focus coverage on the endpoints and dependencies where a degradation is most likely to affect customers.
Endpoint-level monitoring can reveal degradations that service-level averages might hide. But maintaining that coverage manually doesn’t scale. A single service can expose dozens or hundreds of endpoints, each with different traffic patterns, customer impact, and failure modes. Those endpoints also change as engineers add routes, modify user flows, or shift traffic through small frontend or API changes. Low-traffic endpoints can make static thresholds harder to tune because normal behavior may be inconsistent. Bits Detection helps address this challenge by determining which endpoints need coverage, setting detection logic from observed behavior, and keeping coverage current.
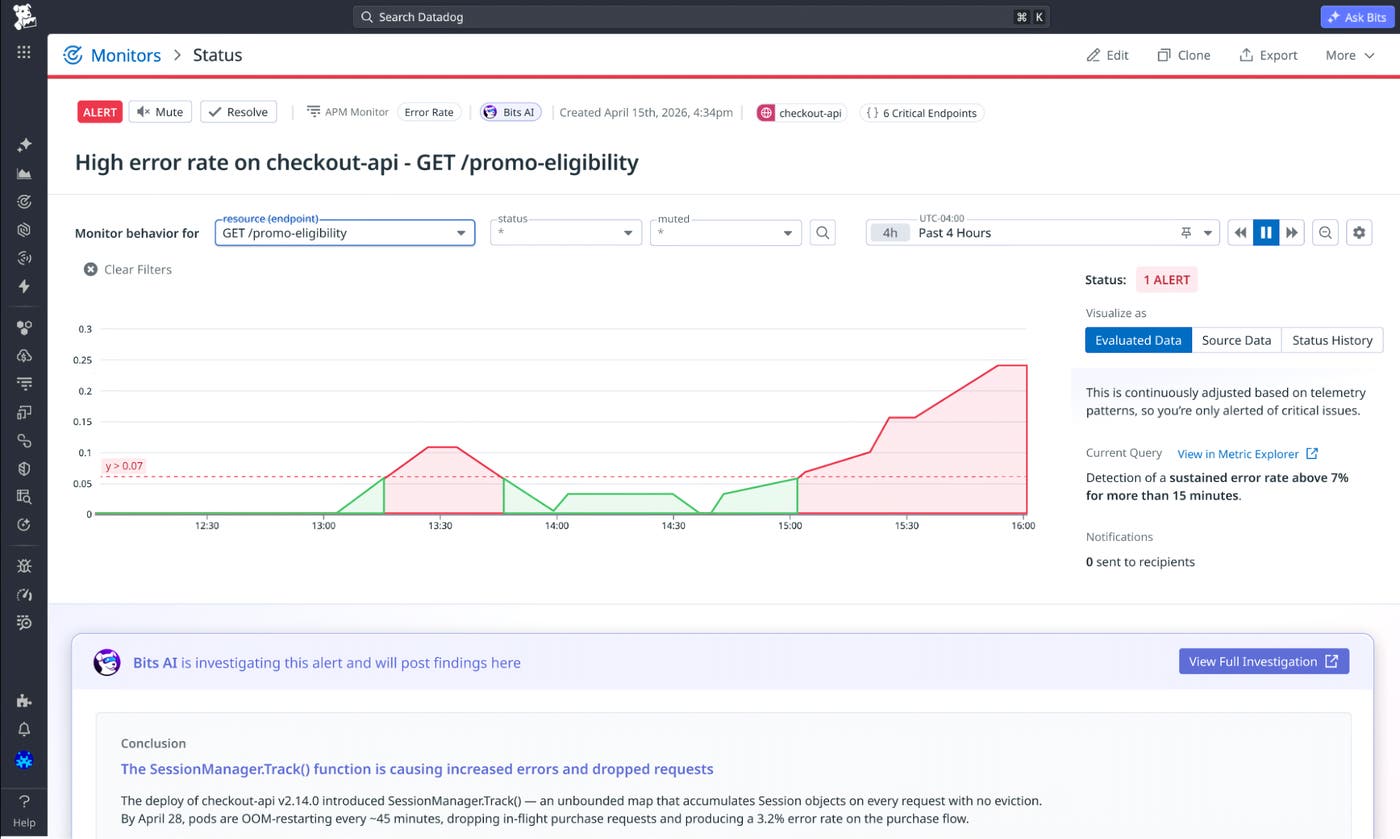
Knowing which endpoints to watch is only part of the problem. Unlike traditional monitoring, which relies on static thresholds, Bits Detection determines what unhealthy behavior looks like for each service and endpoint by evaluating changes against observed production behavior and actual customer impact.
Production metrics are not static. Normal baseline behavior changes as services evolve. Bits Detection accounts for that when evaluating whether a change is worth alerting on, rather than firing on metrics that move outside a static preset range.
You can shape that logic over time through feedback. When you tell Bits Detection which alerts are useful and which ones create noise, you tune detection for your environment. Providing this information keeps operational judgment within your team while reducing the manual work of tuning and maintaining every rule.
Without someone actively managing it, traditional monitoring coverage can drift away from production. That gap is rarely obvious until something breaks. AI-assisted development accelerates this challenge. As teams write and ship code faster, they introduce more change into production than manual monitoring processes were designed to keep up with.
Bits Detection treats monitoring as an ongoing process rather than a one-time setup. As services evolve, coverage and alerting logic update to match without having your team manually revisit every threshold, routing rule, and endpoint.
Your team’s existing monitors can stay in place. The coverage your team has built for known failure modes, service level objectives, and compliance requirements continues to work as configured. Bits Detection works alongside them, adding adaptive coverage for the parts of your system that change too quickly to model by hand.
Detection is where the response process starts. After an issue surfaces, you still need to find out what changed, understand the blast radius, identify the likely cause, decide what to do, and confirm the service recovered. For many organizations, each step requires pulling information from different tools.
When Bits Detection flags an issue, it points to the affected endpoint and the related telemetry, so you know where to start.
This is the first step in the Bits workflow that moves from detection to investigation to remediation. Bits Detection reduces mean time to detection (MTTD) by identifying issues earlier. Autonomous investigation begins triage, while autonomous remediation helps you move from likely cause to recovery by recommending or taking action within defined guardrails.
Bits Detection keeps monitoring aligned with production by automatically identifying which endpoints and dependencies need coverage, determining what healthy behavior looks like for each, and updating that coverage as services change. It enables you to spend less time writing and tuning monitors, and helps you catch issues on critical paths before they show up in aggregate service-level health.
To start using Bits Detection, sign up for the Preview today.
If you’re not already a Datadog customer, start a 14-day free Datadog trial.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。