


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

J
Java Code Geeks
aimingoo的专栏
aimingoo的专栏
Martin Fowler
Martin Fowler
C
Check Point Blog
G
Google Developers Blog
V
Visual Studio Blog
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
Google DeepMind News
人人都是产品经理
人人都是产品经理
有赞技术团队
有赞技术团队
MongoDB | Blog
MongoDB | Blog
月光博客
月光博客
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
大猫的无限游戏
大猫的无限游戏
D
Docker
Hugging Face - Blog
Hugging Face - Blog
The GitHub Blog
The GitHub Blog
博客园 - 三生石上(FineUI控件)
A
About on SuperTechFans
Recent Announcements
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
阮一峰的网络日志
阮一峰的网络日志
Stack Overflow Blog
Stack Overflow Blog
Vercel News
Vercel News

Datadog | The Monitor blog

Introducing our open source AI-native SAST Instrument and monitor Boomi integration flows with OpenTelemetry and Datadog Not all index scans are equal: How we cut query latency by over 99% Platform engineering metrics: What to measure and what to ignore Integrate Recorded Future threat intelligence with Datadog Cloud SIEM CI/CD security: threat modeling using a MITRE-style threat matrix CI/CD security: How to secure your GitHub ecosystem Ingress NGINX is EOL: A practical guide for migrating to Kubernetes Gateway API Operating agentic AI with Amazon Bedrock AgentCore and Datadog LLM Observability: Lessons from NTT DATA Introducing the Datadog Code Security MCP Capture and analyze custom heatmaps in Session Replay Understand session replays faster with AI summaries and smart chapters Monitor ClickHouse query performance with Datadog Database Monitoring How we designed empathetic alert sounds for on-call engineers Search and act across Datadog to resolve issues faster with Bits Assistant Measure the business impact of every product change with Datadog Experiments Analyzing round trip query latency Configuring JavaScript caches for better performance Introducing Bits AI Dev Agent for Code Security Datadog achieves ISO 42001 certification for responsible AI Monitor Nutanix clusters, hosts, and VMs with Datadog Monitor Juniper Mist in Datadog A new Host Map for modern infrastructure Annotate traces to improve LLM quality with Datadog LLM Observability What’s new in Cloud SIEM: AI-powered investigations, enhanced threat intelligence, and scalable security operations Explore Kubernetes with native OpenTelemetry data Monitor Oracle Fusion Cloud Applications with Datadog Announcing the Datadog Terraform provider v4.0.0 Scaling Kubernetes workloads on custom metrics How to design cloud environments for AI-powered threat analysis
Monitor your Mesos cluster with Datadog
John Matson · 2016-06-14 · via Datadog | The Monitor blog
John Matson

John Matson

Editor’s note: Mesos uses the term “master” to describe its architecture and certain metrics. When possible, Datadog does not use this term, so in this post we will use “leader” instead.

Apache Mesos is an open source cluster manager for scheduling and managing distributed applications. Mesos allocates resources such as CPU and RAM almost as if the entire cluster were a single machine.

Mesos was built to run high-scale distributed applications such as Spark, Hadoop, and Kafka. And although it predates the explosion of container technologies over the past few years, it is often used to launch and orchestrate clusters of Docker containers.

See the whole cluster

Mesos can help you efficiently allocate resources from your cluster to the applications that need them, but seeing what’s happening across the entire cluster can be a challenge. That’s why we added Mesos to the list of 1,000+ technologies that Datadog natively monitors.
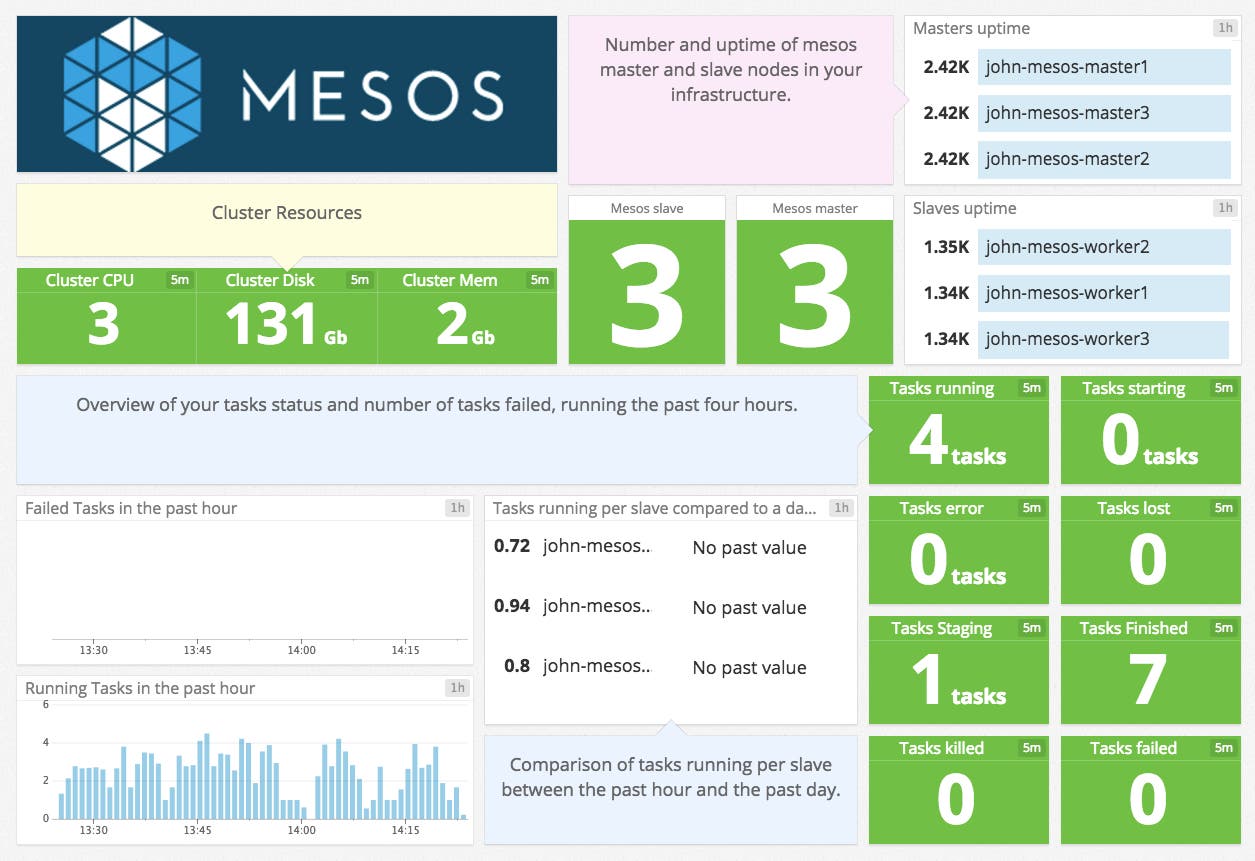
Mesos dashboard

Datadog makes it simple to aggregate metrics from all your Mesos nodes so that you can see, for example, whether the cluster has enough capacity to support your workload or whether it should be scaled out. You can then dive in to see real-time and historical metrics from any node or subset of nodes in your cluster, as well as from any of the services running on those nodes.

Our integration with Mesos collects more than 100 metrics from the leader nodes that orchestrate tasks and the agent nodes that run those tasks. The metrics include resource metrics such as CPU, memory, and disk utilization, as well as more targeted metrics around task execution (tasks finished, failed, killed, etc.).
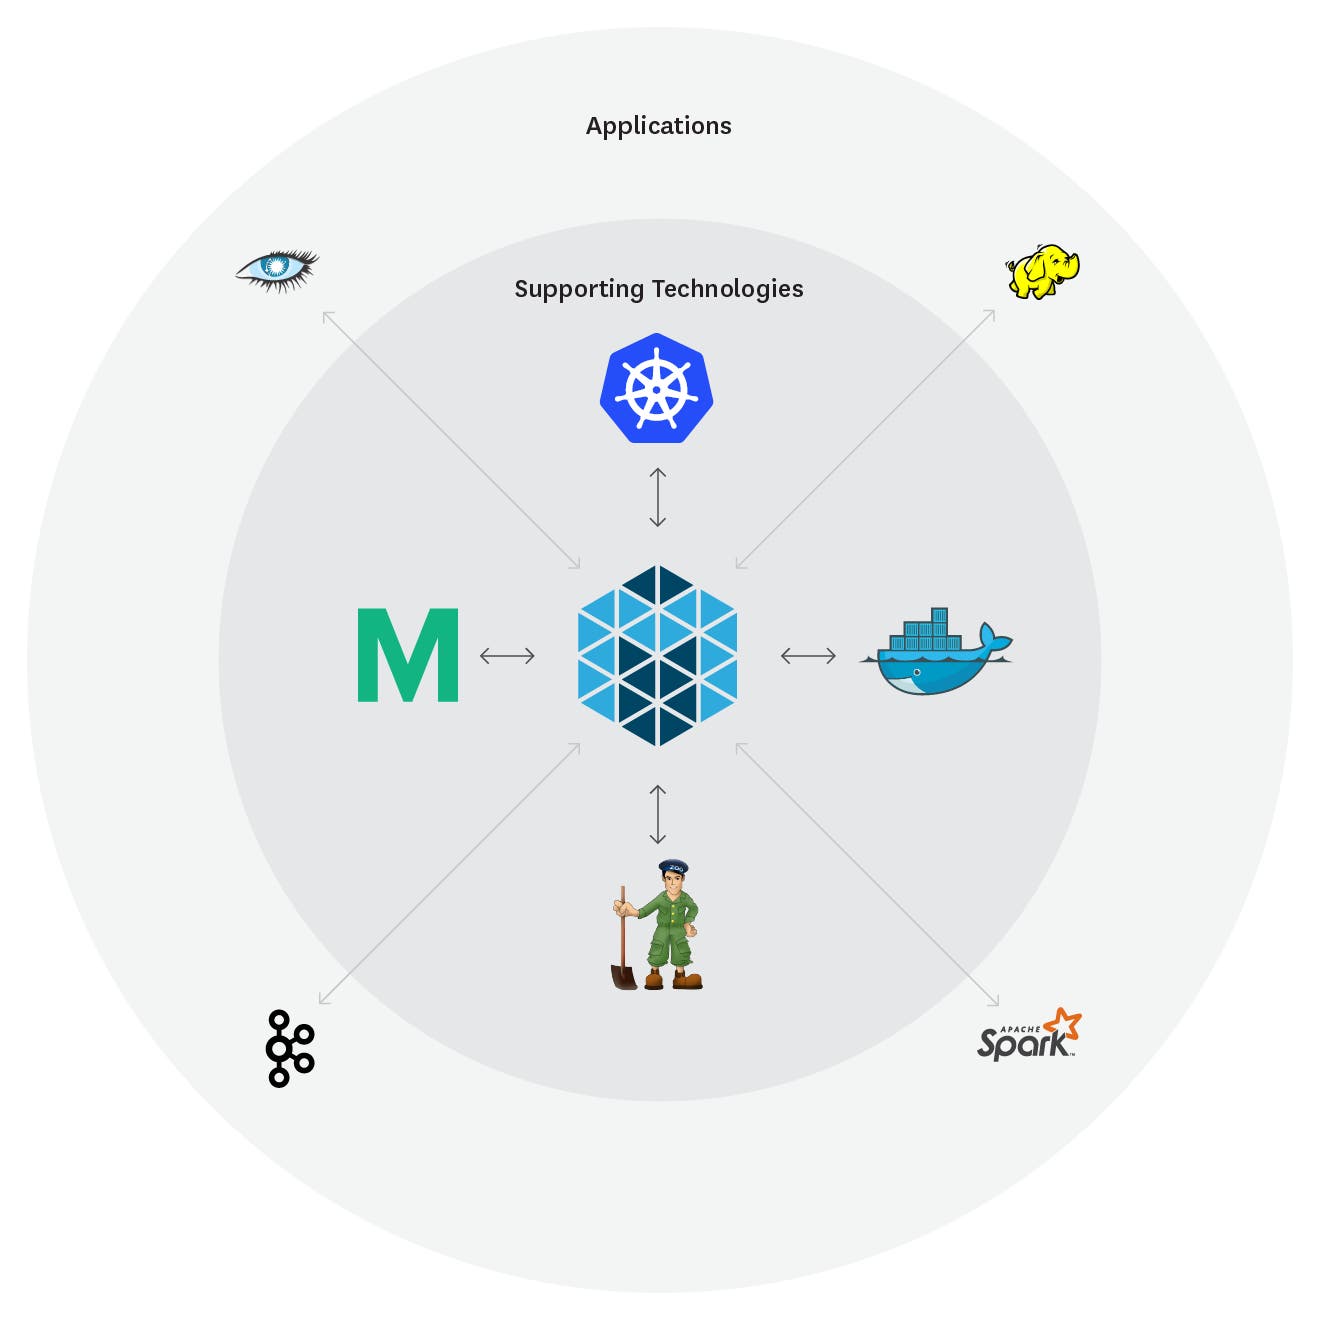
Monitoring Mesos and friends

Mesos ecosystem logos

In a typical Mesos use case, you might run ZooKeeper for leader election, Marathon for container orchestration, Docker for containers, and a workload including distributed applications such as Cassandra. Or you might run Kubernetes as a container orchestrator on top of Mesos to add the auto-scaling functionality of Kubernetes to the resource allocation of Mesos.

Because Datadog integrates with all of the above technologies, you can monitor all the components of your cluster in one place instead of running ad hoc command line queries or checking a separate web UI for each technology. You can build comprehensive dashboards for each of your services that include resource metrics, Mesos task metrics, application performance metrics, scaling events from Docker, and more.

If you’re already using Datadog, you can start monitoring your Mesos cluster by following the integration steps here. If you don’t yet have a Datadog account, here is the link to start your trial.