











Kai Xin Tai
Sidekiq is a Ruby framework for background job processing. Developers can use Sidekiq to asynchronously run computationally intensive tasks—such as bulk email sending, payment processing, and data importing—to help speed up the response times of their applications.
If you’re using Sidekiq Pro or Enterprise, Datadog’s integration helps you monitor the progress of your jobs and the applications that depend on them, all in a single platform. Once you’re collecting metrics from Sidekiq, you can immediately visualize them in a customizable out-of-the-box dashboard. Additionally, if you enable the collection of logs and distributed traces, you can correlate them with metrics to investigate issues such as failed jobs, backlogged queues, and resource-intensive processes.
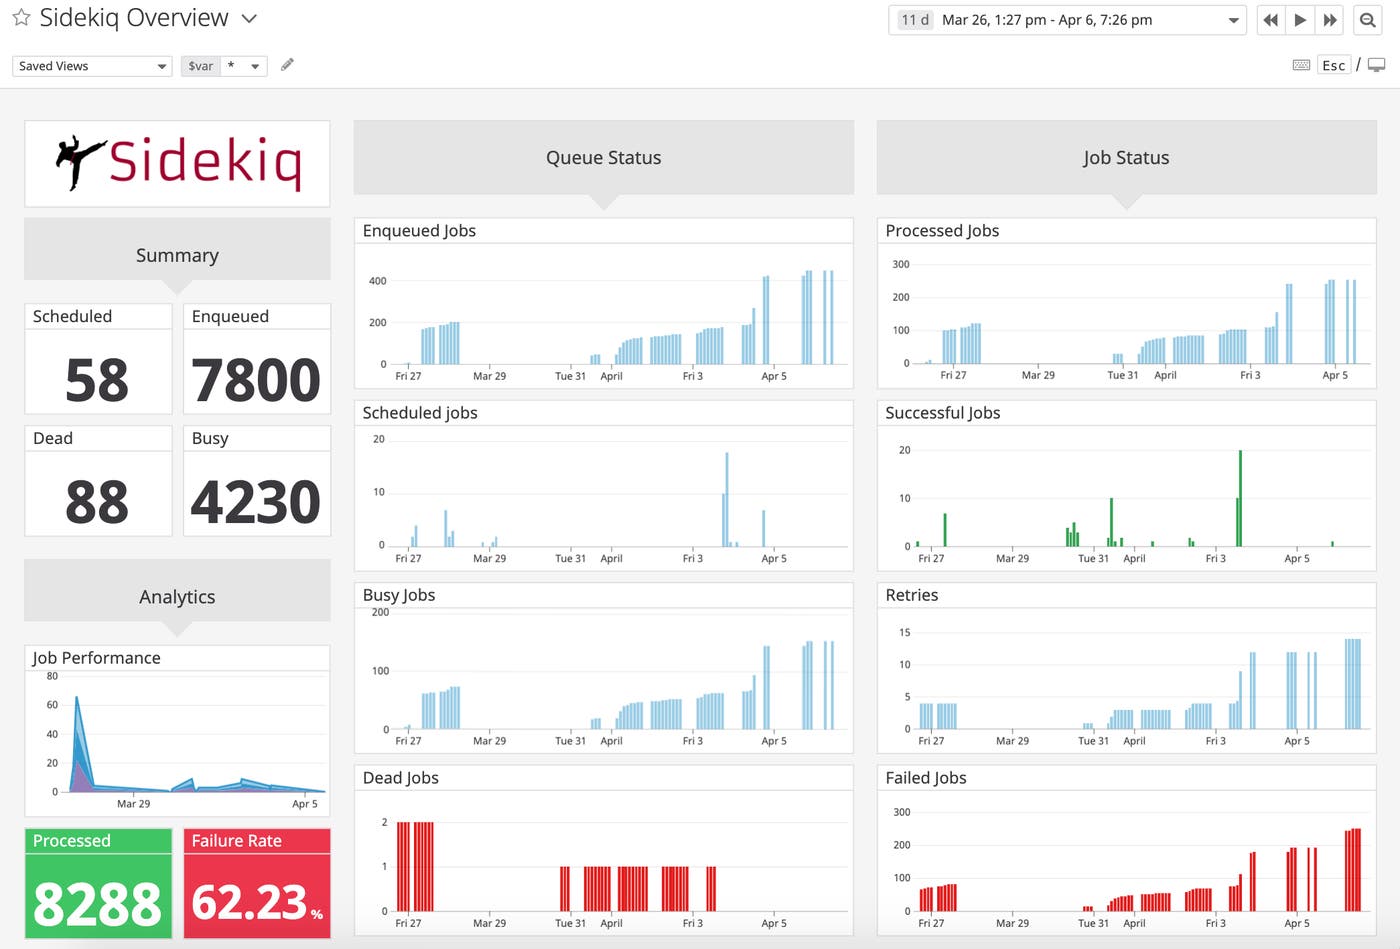
Sidekiq leverages Redis as an in-memory data store to hold its jobs in queues until they are ready to be processed. Each Sidekiq worker fetches one job at a time from a queue and processes it. Before a Sidekiq job completes, it moves through a series of possible states, such as Enqueued, Scheduled, and Busy. And if any errors arise during the processing of a job, it is automatically retried up to 25 times before it terminates and enters the Dead state.
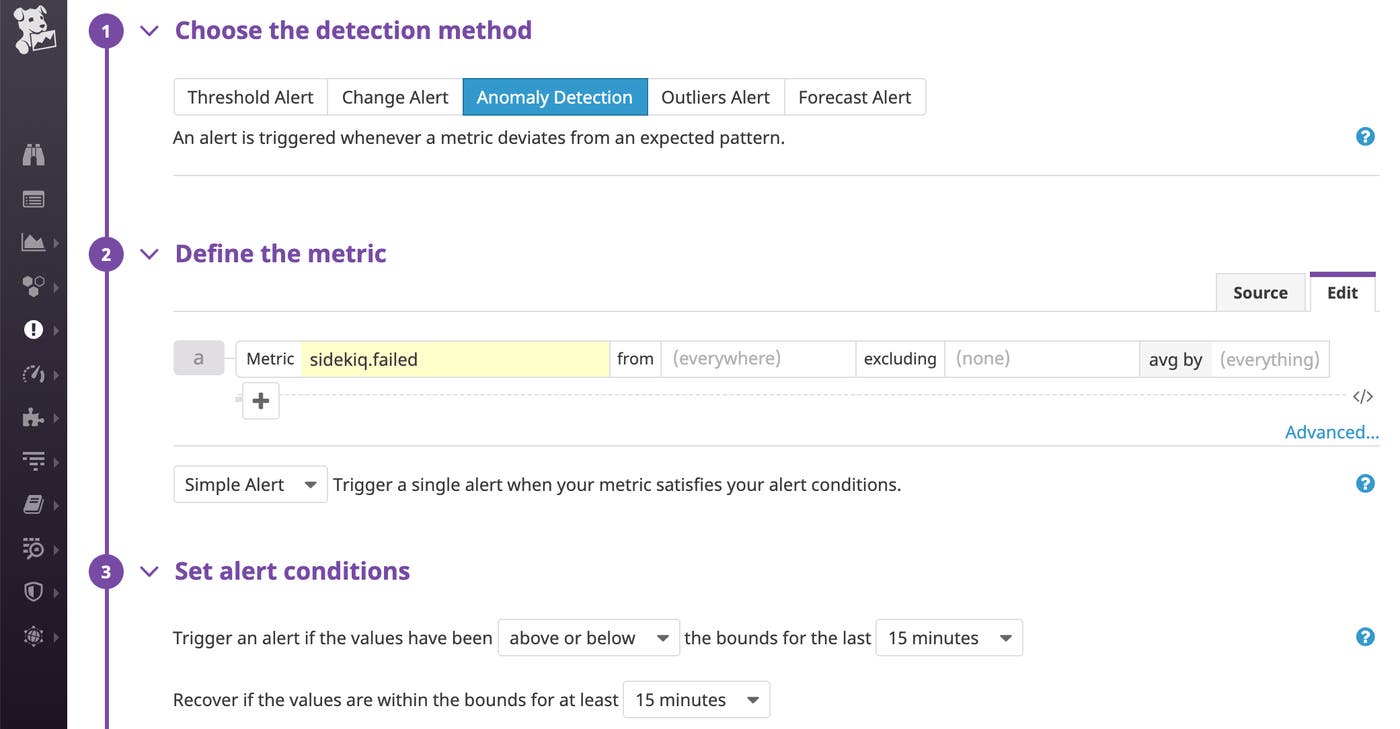
Datadog’s out-of-the-box dashboard shows how often jobs have succeeded and failed, as well as how many jobs are queued, waiting to be processed. You can also set up alerts to be automatically notified of potential issues, such as when there is an anomalous spike in overall job retries (sidekiq.retries) or failures (sidekiq.failures), so you can begin troubleshooting right away. This helps you keep tabs on whether your jobs are being executed as expected and ensure that you’re meeting your service level agreements (SLAs).
If your application experiences a surge in traffic—and your workers are not able to keep up with the rate of incoming jobs—your queues can start to become backlogged. As your queues grow, Redis could potentially run out of memory and begin swapping idle pages to disk, resulting in a significant increase in latency. To prevent Sidekiq data from being dropped when Redis’s memory limit has been reached, Sidekiq recommends setting the maxmemory-policy parameter in Redis to noeviction.
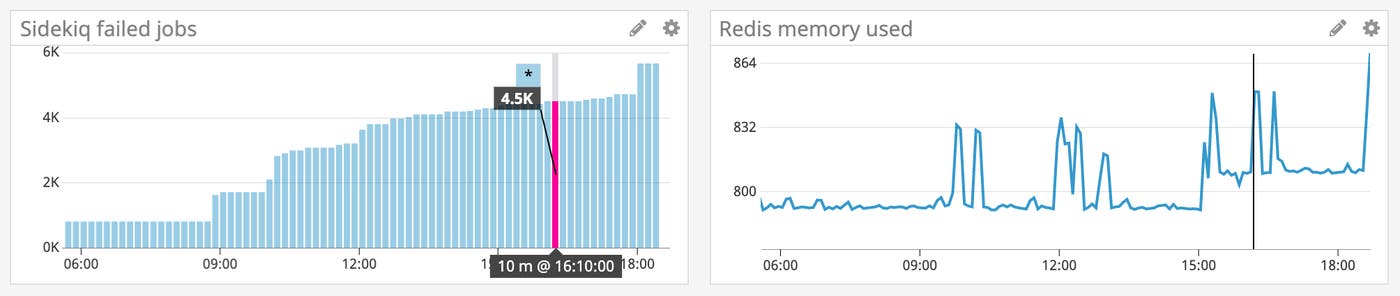
Datadog also includes built-in support for Redis so you can correlate the number of queued Sidekiq jobs (sidekiq.enqueued) with the amount of memory used by Redis (redis.mem.used) to determine whether your job processor is able to keep up with its workload. If memory is a bottleneck, you can consider provisioning more resources to your Redis instance or partitioning jobs across multiple Redis instances. To learn more about other key Redis metrics you should monitor, see our guide.
Slow jobs will delay other jobs in the queue from starting, so you should monitor Sidekiq job latency and troubleshoot any issues as soon as possible. Datadog APM auto-instruments your Ruby applications so you can quickly start tracing all your Sidekiq jobs as they propagate across your infrastructure. By inspecting the traces of long-running jobs, you can easily determine if time is mostly spent in Sidekiq itself or in external services—and drill into particular problem areas.
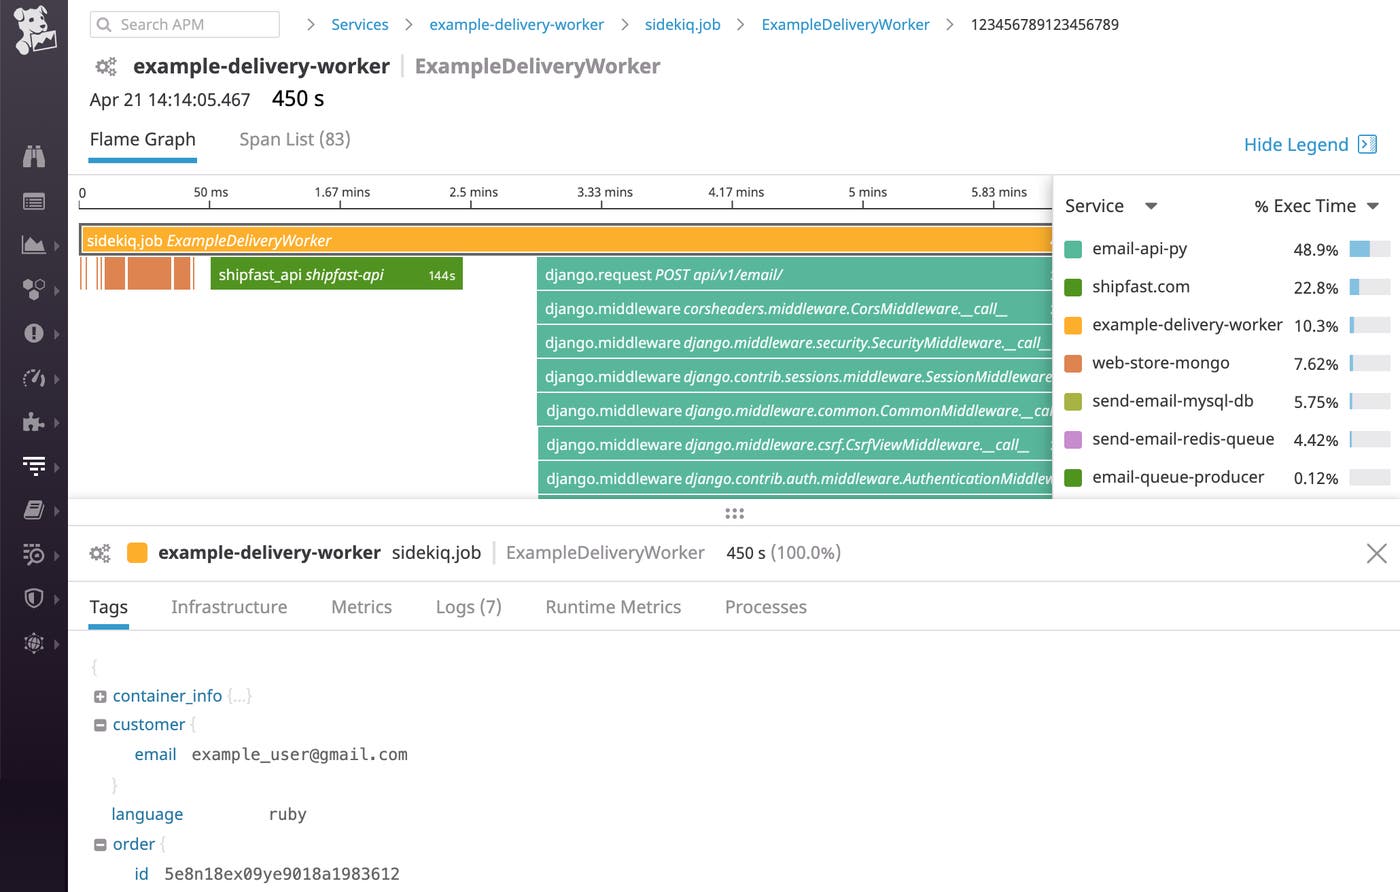
Long-running jobs risk timing out before they complete, which is why Sidekiq generally recommends breaking large jobs down into smaller jobs that can be processed in parallel. For instance, instead of running one job to send an email notification to all your users, it is better to create a batch of jobs that each send one email. This way, you are able to leverage concurrency to speed up processing without losing the ability to monitor similar types of tasks as a group.
Whether you have hundreds—or hundreds of thousands—of jobs, Datadog’s Sidekiq integration provides the metrics, logs, and distributed traces you need to comprehensively monitor your deployment in real time. If you’re already using Datadog, check out our documentation to learn how you can start monitoring Sidekiq alongside Redis and 1,000+ other technologies. Otherwise, sign up for a 14-day free trial today.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。