


One Ruby feature that embodies the principle of “optimizing for programmer happiness” is how the language uses garbage collection (GC) to automatically manage application memory. But as Ruby apps grow, GC itself can become a big consumer of system resources, and this can lead to high CPU usage and performance issues such as increased latency or reduced throughput. For this reason, it’s important for DevOps teams to keep an eye on Ruby GC activity as part of the effort to optimize application performance.
To help engineers track resource usage tied to GC and determine when this usage is problematic, Datadog’s Continuous Profiler surfaces garbage collection activity in both its flame graph and thread timeline visualizations. And now, with the general availability of the Ruby allocations profiler in version 2.3.0 of our Datadog tracing library, Continuous Profiler also lets you take your investigations even further within your Ruby applications. By revealing which parts of an application are allocating the most memory, the new allocations profiler helps you not only diagnose but also resolve GC resource consumption issues in Ruby.
In this post, we’ll explore the following topics:
You can uncover GC activity for Ruby applications in Continuous Profiler by looking at the CPU Time profile view within the flame graph visualization and then locating the top-level Garbage Collection frame. This frame will reveal the average CPU time for GC and its corresponding percentage of the profile, as shown below:
You can also drill down on GC activity in the thread timeline visualization. In this visualization, you can distinguish between minor and major GC activity and see the trigger that caused the garbage collector to start. For example, the screenshot below shows a pop-up indicating that minor GC activity has been triggered by object allocation:
The point at which GC resource usage becomes problematic depends on whether the application is latency-sensitive.
For applications that are not latency-sensitive, such as some background job processes, GC resource usage may start significantly impacting the application only once it’s close to fully using all available CPU resources. In these situations, any time saved from garbage collection translates into more useful processing time.
If however the application is latency-sensitive, even a low overall percentage of GC resource usage can have an effect on tail latencies. This outsized impact occurs because GC is always triggered in response to application activity, and thus the garbage collector is often competing with the application for resources.
To investigate which parts of a Ruby application are responsible for allocating the most memory, you first need to install version 2.3.0 or later of the Datadog tracing library (which includes our Ruby profiler) and then enable the allocations profiler. Once enabled, the allocations profiler allows you to investigate the memory allocations made by each function (i.e., method) of your Ruby application, including allocations that were subsequently freed. It also allows you to adjust the top list to view the heaviest allocators from different perspectives, such as the top threads, files, or libraries:
Another selection, Allocated Type, allows you to view which kinds of objects have been allocated the most often, as shown below:
In this last example above, any work done to reduce the number of arrays, strings, and hashes allocated in these codepaths will help reduce GC load. This reduction can be accomplished through the use of better algorithms, better data structures, or through object reuse strategies such as object pool caches or the flyweight design pattern.
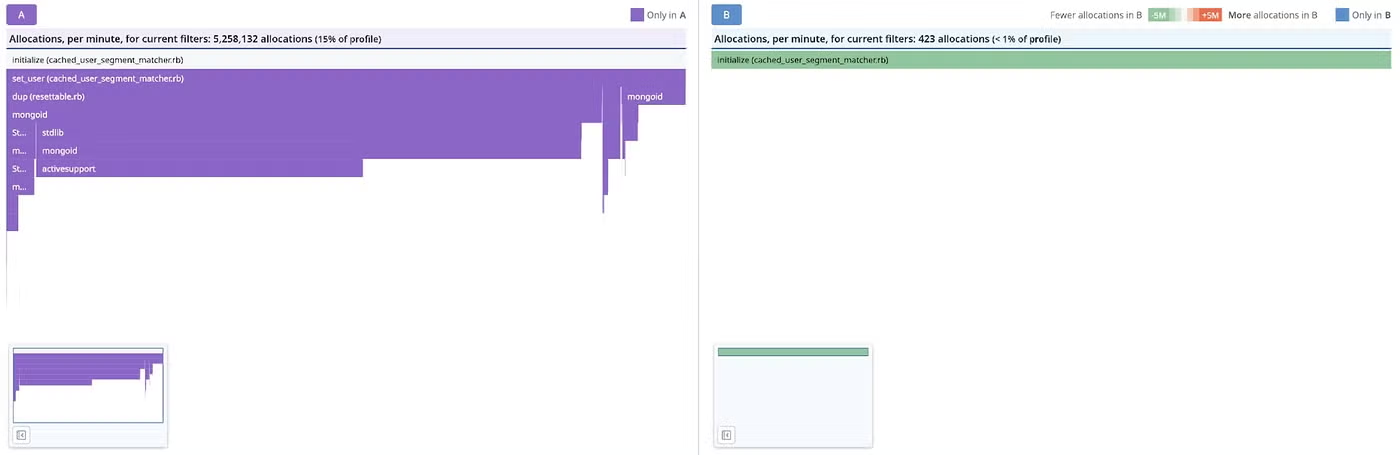
At the Datadog DASH 2024 conference, Zach McCormick from Braze described an investigation using our allocations profiler that led to a CPU usage reduction. One of Braze’s Sidekiq services had been seeing GC use more than 10 percent of the service’s CPU time. Investigating this problem with the allocations profiler, Zach used the Top Function list to determine that the app was performing a lot of object dup (i.e., cloning) operations.
The Braze team had originally put these dup operations in place to work around a logic bug, but that issue had since been fixed in the codebase. The workaround had stayed behind and over time had become quite costly.
Removing the workaround from the codebase led to a big decrease in allocated objects. In the image below, the left window (A) shows the allocations in the service before the fix, and the right window (B) reveals the significantly reduced memory allocations after the fix.
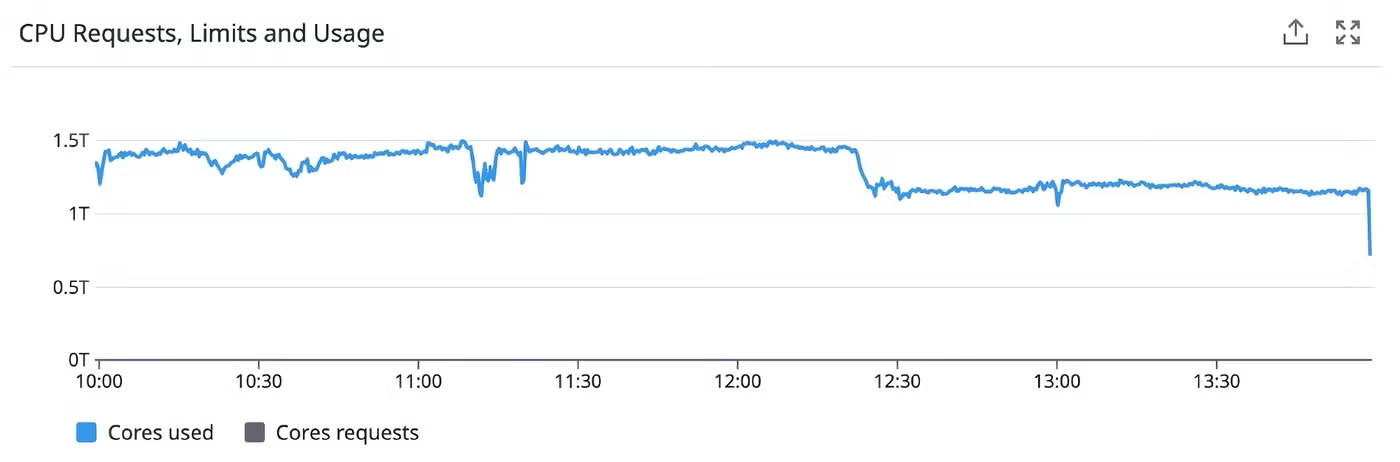
Accordingly, there was a reduction of time spent in garbage collection, as well as in overall CPU usage for this service. You can see the drop-off right before the 12:30 mark in the image below:
Using the Ruby allocations profiler, you can dig into problems you’ve detected with GC activity, determine their causes, and gain insights into how to fix the application to address these issues.
The allocations profiler for Ruby is now generally available and included as part of version 2.3.0 of Datadog’s tracing library.
For more information about Datadog Continuous Profiler, see our documentation. And if you’re not yet a Datadog customer, you can sign up for our 14-day free trial.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。