









Olivier Pomel
We first started working on Datadog in late 2010 because it seemed obvious to us that IT infrastructure would look drastically different in 2020—and as such it would need a new kind of monitoring and analytics platform. As long-time engineers, we had lived through our own transition to Agile processes and could feel the disruptive power of cloud infrastructure.
This was our bet: the combination of Agile and next-generation Cloud platforms would completely change the magnitude of the corresponding management problem, and force a complete retooling across the stack and—in particular—new Monitoring and Analytics.
Fast forward five years. Since launching Datadog, we’ve seen our thesis validated on a far broader scale than we had originally anticipated. And this explosive growth of the cloud user base over the past few years involves companies of all sizes, be they tiny tech startups or big banks, using public or private clouds.
So—what do we mean exactly when we talk about the “scale” of monitoring? We consider it to be the product of four dimensions:
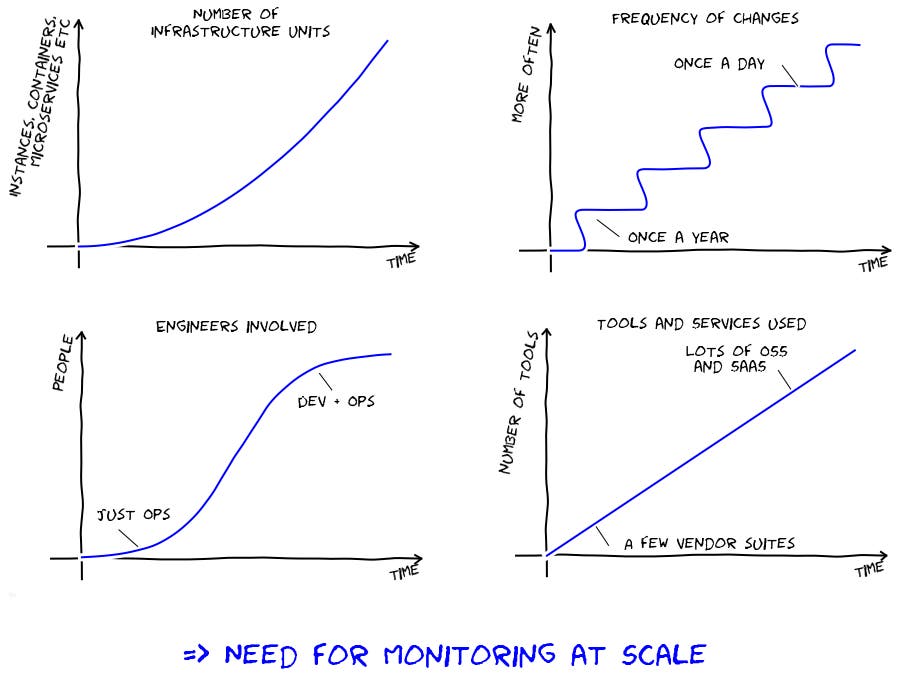
This is what most people directly associate with scale. We have seen, over the past five years the number of “infrastructure units” involved in any production environment increase by orders of magnitude. These infrastructure units used to be physical servers or fairly long-lived VMs, but are now increasingly made of ephemeral cloud instances, containers, and micro-services. Any company that was operating 100s of servers in 2010 is easily managing 1000s to 10,000s of units today. In other words, enterprises have replaced a few fairly static things with a lot more moving pieces.
In the not so distant past, software teams only used to ship products once or a couple of times a year. Today, some of us are shipping code several times a day as companies big and small have switched from Waterfall to Agile development processes. Multiply that by the large number of teams any enterprise is made of, and you obtain production environments that keep changing all the time.
This has been probably the biggest cultural change engineers have felt over the past few years. Where infrastructure used to be managed solely by the ops team—or in larger enterprises “shared services” groups—it is now touched by multiple teams spanning operations and development. As a result, the number of engineers interacting with the infrastructure has dramatically increased.
As an additional consequence of transitioning from Waterfall to Agile, companies have switched from having one centralized enterprise architecture group making all infrastructure choices ahead of time, to empowering each team to make their own decisions—so that they can ship products every week or month and don’t have to block on centralized decision-making. The result is a considerably more diverse ecosystem as different teams will pick different platforms and tools. This trend is compounded by the rise of open source and SaaS, which has drastically increased the number of components to choose from. In short, all enterprises are using a much broader set of technologies to build and run their applications today than they used to a few years ago.
That’s it. Because of rapid changes across each of these four dimensions, the magnitude of the monitoring problem has drastically changed. And we’ve built Datadog to scale across these very dimensions. All indicators are showing that 2016 will be a banner year for adoption of public and private clouds, and will usher in the era of Monitoring at Scale.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。