








When observability systems become unavailable due to a cloud provider outage, teams lose the real-time view of production systems they rely on to respond to incidents and continue deployments. Failures in shared dependencies, such as managed databases, identity systems, or object stores, can cascade across other services and regions, increasing downtime and user impact.
With Datadog Disaster Recovery (DDR), teams can maintain observability during widespread infrastructure disruptions. Now generally available, DDR lets you configure a secondary Datadog site ahead of time, replicate Datadog resources, and fail over telemetry data when your primary site is impacted.
In this post, you’ll learn how to:
Maintain observability during infrastructure disruptions
Configure a secondary Datadog site for failover
Trigger a failover when needed
Large-scale outages can affect more than the applications and infrastructure your teams operate directly. For example, the October 2025 AWS outage in US-EAST-1 started with increased Amazon DynamoDB API error rates and endpoint resolution failures. Downdetector logged more than 6.5 million reports across more than 1,000 services, including Amazon EC2, Network Load Balancer, AWS Management Console, AWS Lambda, Amazon ECS, Amazon EKS, and Fargate. Even organizations with multi-region deployments lost visibility because their control plane dependencies, including IAM and Secrets Manager, were hosted in US-EAST-1. Parametrix estimated total US financial losses at $500–650 million.
A June 2025 Google Cloud outage had a similar effect on Datadog customers who stored all of their telemetry data in Google Cloud regions, creating blind spots during the incident. Following a March 2023 outage of our own, Datadog launched a company-wide initiative to improve regional isolation across Datadog sites. All three outages show how reliance on a single cloud provider can compromise observability during an incident. DDR addresses this directly by giving you a pre-configured secondary Datadog site that stays synchronized with your primary site and activates on demand when it is impacted.
For teams with the highest resilience requirements, Datadog also supports active-active configuration. The Datadog Agent can forward telemetry to multiple Datadog sites simultaneously, which is how Datadog runs internally. Active-active offers the most resilience but doubles ingestion costs, and the return on investment doesn’t justify the spend for most organizations. DDR’s active-passive model is typically the more practical choice.
With DDR, you maintain a secondary Datadog site that mirrors your primary and activates when you need it. After onboarding, you provision an account on that site, which is geographically and operationally separate from your primary site. Datadog runs managed resource sync on your behalf using the open source datadog-sync-cli, which handles execution, storage, and scheduling. The secondary site’s resources are prepared before an incident occurs, so it’s ready to receive telemetry when you activate a failover.
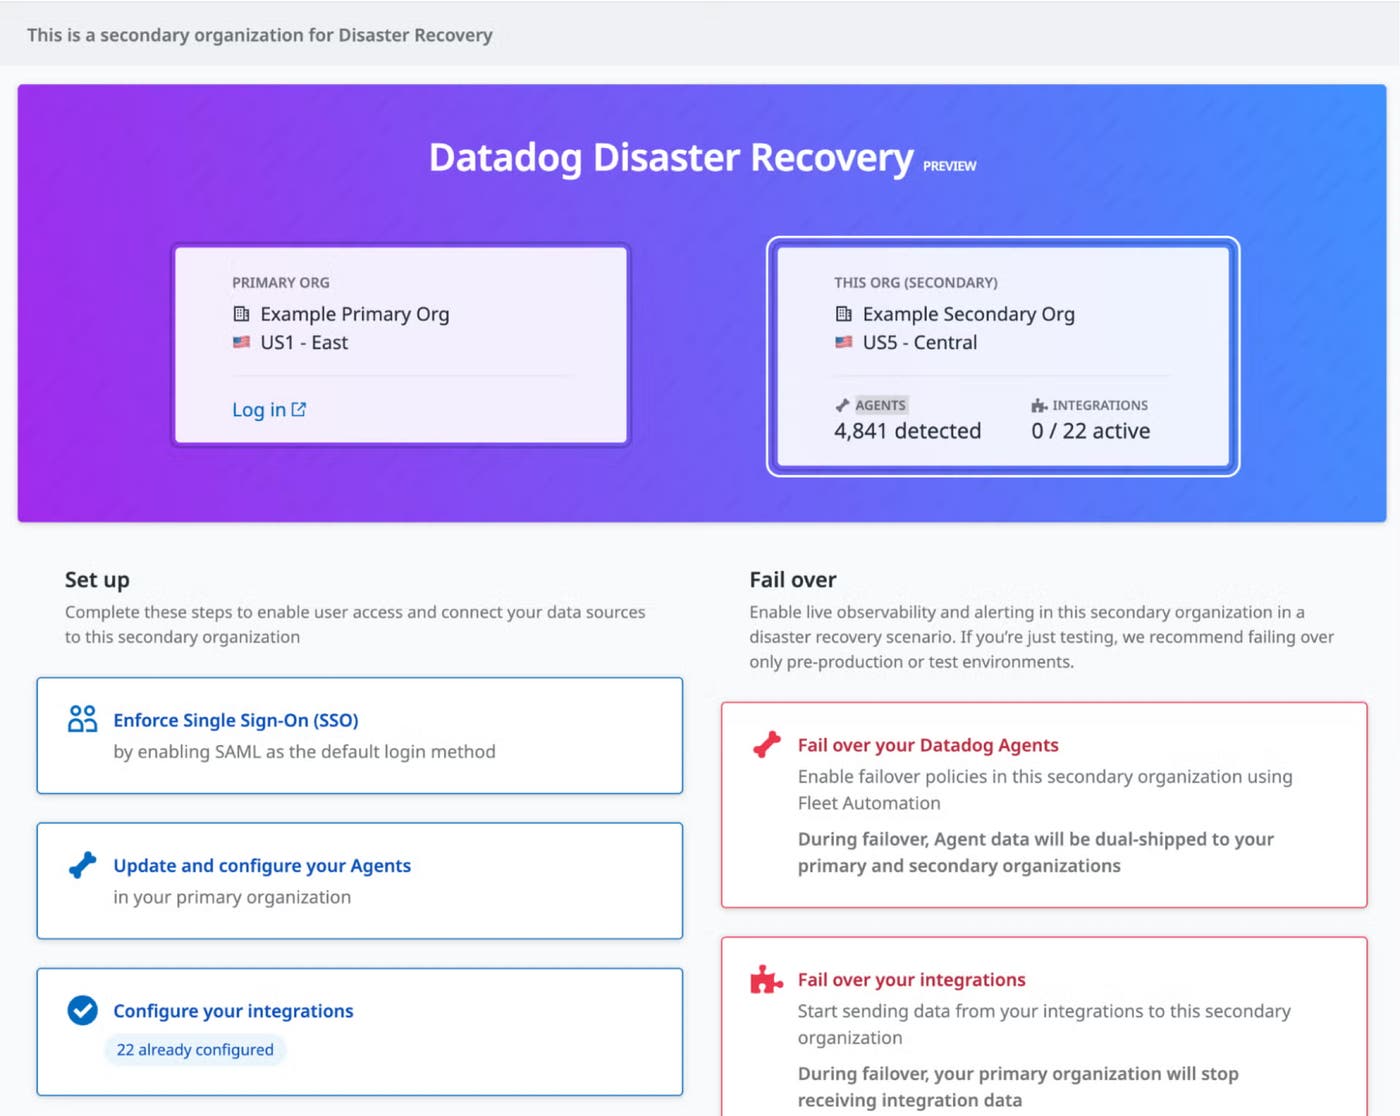
Managed sync replicates dashboards, monitors, users, notebooks, and more than 30 resource types from your primary site to your secondary site on a regular schedule. When you activate a failover, your secondary site already has the resources your team needs. Your team can respond immediately without rebuilding dashboards, recreating monitors, or reconfiguring users.
Datadog offers more than 1,000 integrations for observing third-party systems, apps, and services. Many are subject to vendor-specific API rate limits and quotas. When you configure integrations on your secondary site, they stay paused by default alongside synthetic tests and activate only when you trigger a failover.
When you trigger a failover, telemetry data routes to your secondary site and your replicated dashboards and monitors come online.
DDR does not trigger failover automatically. Your organization can decide when to cut over based on operational context. Some situations clearly warrant immediate action, such as a major outage that affects multiple services and regions. Others are more nuanced, such as a regional service degradation that affects only part of your environment or a provider issue that impacts specific control plane operations. Since a failover is initiated on demand, your team can choose the moment when routing telemetry to your secondary site best supports your response.
DDR supports two failover methods. Agent-based failover uses Fleet Automation and Remote Configuration. DNS-based failover uses a dedicated intake endpoint to route traffic without touching your Agent fleet.
Datadog Fleet Automation and Remote Configuration let you apply failover policies across your Agent fleet without manually updating individual Agent configurations.
From Fleet Automation, you can create a new failover policy or apply an existing one. Once applied, Agents begin dual-shipping telemetry to both your primary and secondary sites.
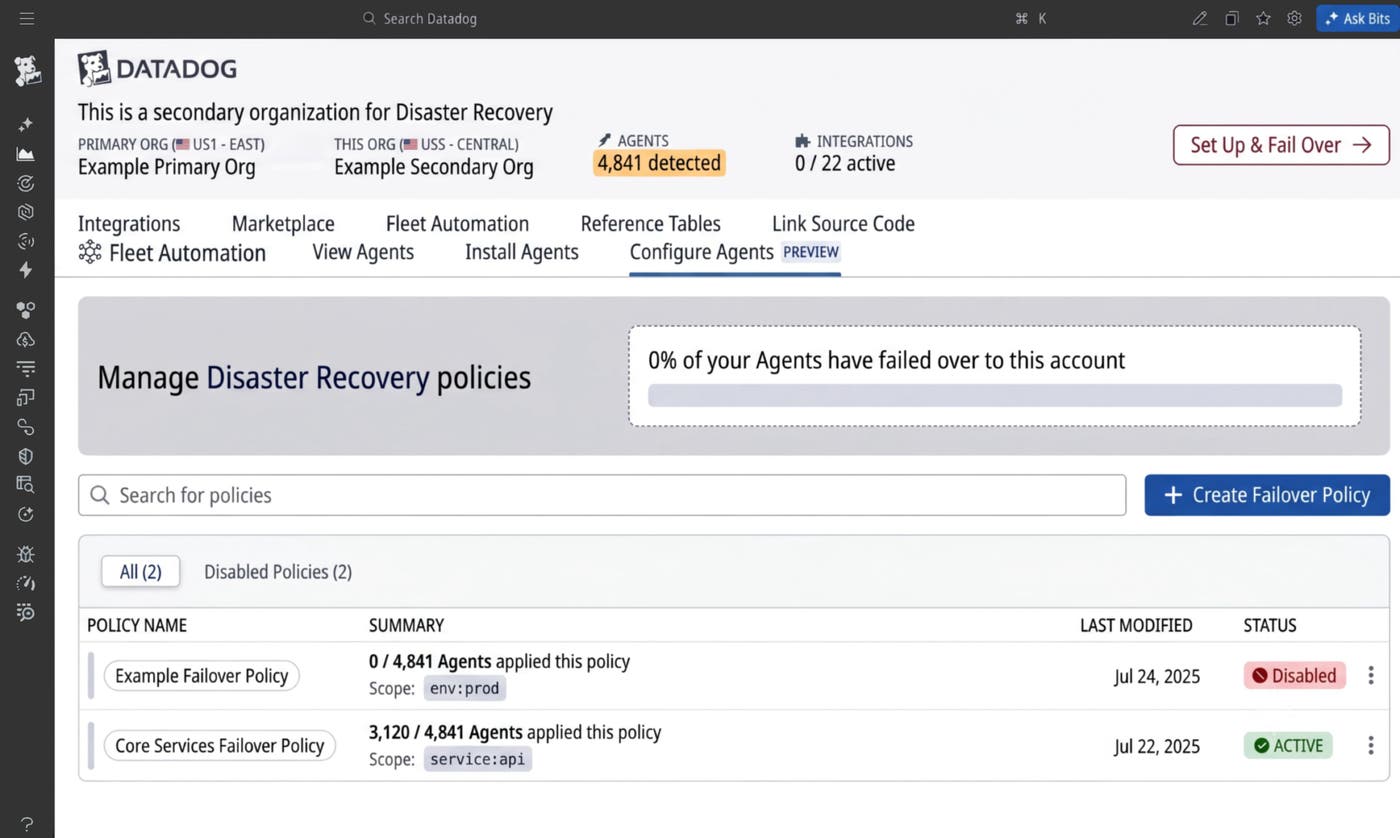
You can also trigger Agent-based failover through a direct configuration update. In `datadog.yaml`, configure `multi_region_failover` with the secondary site and API key:
multi_region_failover:
enabled: true # allow the agent to failover
failover_metrics: false # set to true to send metrics to secondary site
failover_logs: false # set to true to send logs to secondary site
failover_apm: false # set to true to send traces to secondary site
site: datadoghq.eu # secondary site
api_key: ... # secondary site api key
Then use the Agent command-line interface to update the failover configuration:
agent config set multi_region_failover.failover_metrics true
agent config set multi_region_failover.failover_logs true
agent config set multi_region_failover.failover_apm true
DNS-based failover centralizes cutover control without requiring any changes to your Agent fleet. Datadog provides a dedicated vanity URL that serves as your intake endpoint. You can update your Agents and integrations to point to that URL instead of your primary Datadog site URL. During a failover, Datadog updates the DNS records for that URL to route traffic to your secondary site. DNS-based failover is currently initiated by contacting your Datadog account team who coordinates the cutover. Customer-controlled DNS failover, which lets you trigger the cutover directly without going through Datadog, is currently in Preview.
Datadog Disaster Recovery lets you maintain observability during widespread infrastructure disruptions with a pre-configured secondary site that activates on demand. Managed resource sync keeps your secondary site current, and on-demand failover gives you control over when and how you cut over.
To learn more or enable DDR for your organization, reach out to your Datadog account manager.
If you’re not already a Datadog customer, sign up for a free free 14-day trial.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。