







Last Friday was PyData Paris, in words of the organizers, ''a gathering of users and developers of data analysis tools in Python''.

The organizers did a great job in putting together and the event started already with a full room for Gael's keynote
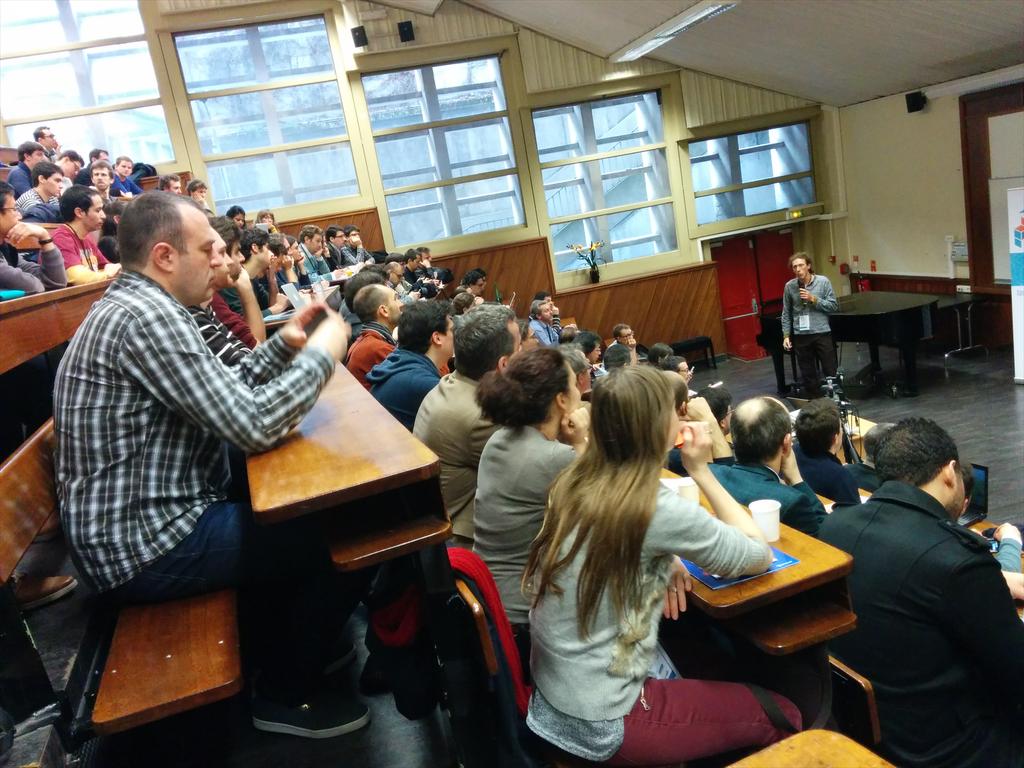
My take-away message from the talks is that Python has grown in 5 years from a language marginally used in some research environments into one of the main languages for data science used both in research labs and industrial environment.
My personal highlights were (note that there were two parallel tracks)
-
Ian Ozsvald's talk on Cleaning Confused Collections of Characters. Ian gave a very practical talk, full of real world examples. The slides have already been uploaded on his website. Many tips and many pointers to libraries. In particular, I discovered fixes text for you.
-
Chloe-Agathe gave a short talk on DREAM challenges. In her talk she mentioned GPy. One year ago, I visited Neil Lawrence at his lab in Sheffield and at that point they were in the process of migrating their Matlab codebase into Python (the GPy project). I'm very glad to see that the project is succeeding and being used by other research institutions.
-
Serge Guelton and Pierrick Brunet presented “Pythran: Static Compilation of Parallel Scientific Kernels”. From their own documentation: “Pythran is a python to c++ compiler for a subset of the python language. It takes a python module annotated with a few interface description and turns it into a native python module with the same interface, but (hopefully) faster”. The project seems promising although I do not have had experience as to judge the quality of their implementation.
-
Antoine Pitrou presented: “Numba, a JIT compiler for fast numerical code”. I must say that I'm an avid user of Numba so of course I was looking forward to this talk. One thing I didn't know is that support for CUDA is being implemented into Numba via the
@cuda.jitdecorator. From their website it looks like this is only available in the Numba Pro version (not free). -
Kirill Smelkov presented wendelin.core, an approach to perform out-of-core computations with numpy. Slides can be found here.
-
Finally, Frances Alted gave the final keynote on “New Trends In Storing And Analyzing Large Data Silos With Python”. Among the projects he mentioned, I found particularly interesting bcolz, his current main project and DyND, a Python wrapper around a multi-dimensional array library.