


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

博客园 - Franky
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
有赞技术团队
有赞技术团队
aimingoo的专栏
aimingoo的专栏
WordPress大学
WordPress大学
人人都是产品经理
人人都是产品经理
酷 壳 – CoolShell
酷 壳 – CoolShell
L
LangChain Blog
Blog — PlanetScale
Blog — PlanetScale
阮一峰的网络日志
阮一峰的网络日志
Microsoft Azure Blog
云风的 BLOG
云风的 BLOG
Google DeepMind News
T
The Blog of Author Tim Ferriss
G
Google Developers Blog
Hugging Face - Blog
Hugging Face - Blog
Y
Y Combinator Blog
D
DataBreaches.Net
Engineering at Meta
Engineering at Meta
MyScale Blog
MyScale Blog
大猫的无限游戏
大猫的无限游戏
S
SegmentFault 最新的问题
The GitHub Blog
The GitHub Blog
Recent Announcements

Pinecone

Pinecone Assistant: A Managed Knowledge Layer for Production AI Applications Multi-domain RAG in n8n: why one knowledge base is not enough Allspice Transforms the Culinary Experience with Semantic Search Powered by Pinecone | Pinecone Building RAG workflows in n8n: choosing the right Pinecone node Knowledge needs a meta-knowledge layer Garbage Day: How Pinecone Safely Deletes Billions of Objects at Scale When "Performance" Means Two Different Things Pinecone BYOC: Pinecone in your AWS, GCP, or Azure account, no vendor access True, Relevant, and Wrong: The Applicability Problem in RAG Use the Pinecone Plugin for Claude Code to develop AI Applications Faster Millions at Stake: How Melange's High-Recall Retrieval Prevents Litigation Collapse Powering High-stakes Patent Search at Scale: How Melange Built a Reliable AI System on Pinecone | Pinecone Pinecone Assistant Node in n8n: Turn Any Data Source Into Knowledge RAG with Access Control Pinecone Dedicated Read Nodes are now in Public Preview Inside Pinecone: Slab Architecture New Bulk Data Operations: Update, Delete, and Fetch by Metadata The Hidden Cost of Building: Lessons from Aquant Simplifying Vector Embeddings with Pinecone Integrated Inference Capabilities Pinecone joins Microsoft Marketplace as a Launch Partner GTM Engineering: Clay + Pinecone for AI-powered Sales Outbound Build an AI knowledge assistant with Google Docs and Pinecone Moving Pinecone forward with Ash Ashutosh as CEO and Edo spearheading our growing AI ambitions as Chief Scientist Pinecone Founder Edo Liberty to Spearhead Pinecone’s Growing AI Ambitions; Appoints Ash Ashutosh as CEO to Expand Vector Database Market Leadership Fast, Accurate Retrieval for Creators at Scale: Delphi’s Path Toward a Million Conversational Agents with Pinecone | Pinecone Announcing Pinecone Pioneers: A Program for Builders, Organizers, and Community Leaders What is Context Engineering? Chunking Strategies for LLM Applications Beyond the hype: Why RAG remains essential for modern AI Obviant Makes 30% More Accurate Defense Acquisition Recommendations Combining Sparse and Dense Retrieval with Pinecone | Pinecone
High-throughput vector indexes now generally available an...
Jeff Zhu · 2022-12-08 · via Pinecone

Back in August, we announced a new performance pod type - p2 - in public preview. Different from the existing p1 pods, p2 pods use a new graph-based index to provide blazing fast search speeds (up to 10x faster than p1) and higher throughput (up to 200 QPS) per replica.

Today, we are excited to announce that p2 pods are now generally available for all users. Since the preview announcement, we have made the pods even more efficient and accessible for high-throughput use cases. Along with being generally available, p2 pods are now:

  • Available in the Starter (free) plan: Users can now easily experiment with high-throughput use cases with a single p2 pod. Try a p2 pod today without any commitment!
  • 50% lower in cost: We’ve continued to invest in optimizing p2 memory utilization throughout public preview. These optimizations allow us to reduce the p2 price by 50%, making p2 a more cost-competitive option than ever before.
  • Dot product compatible: Along with support of cosine and euclidean distance metrics, p2 pods now support dot product. Choose the metric that works best for you.

Updated pricing for p2 pods has been in effect since December 1, 2022, starting at $0.144/hour and up depending on plan, pod size, and cloud environment. See the pricing page for more details.

Deciding between pod types? When to consider p2

In general, p2 pods are designed for applications that require minimal latency (<10ms) and/or high throughput (>100 QPS). Examples of performance-focused use cases are movie recommendations on video streaming applications or personalization in social media feeds.

Here are some sample query latencies using a single p2.x1 pod:
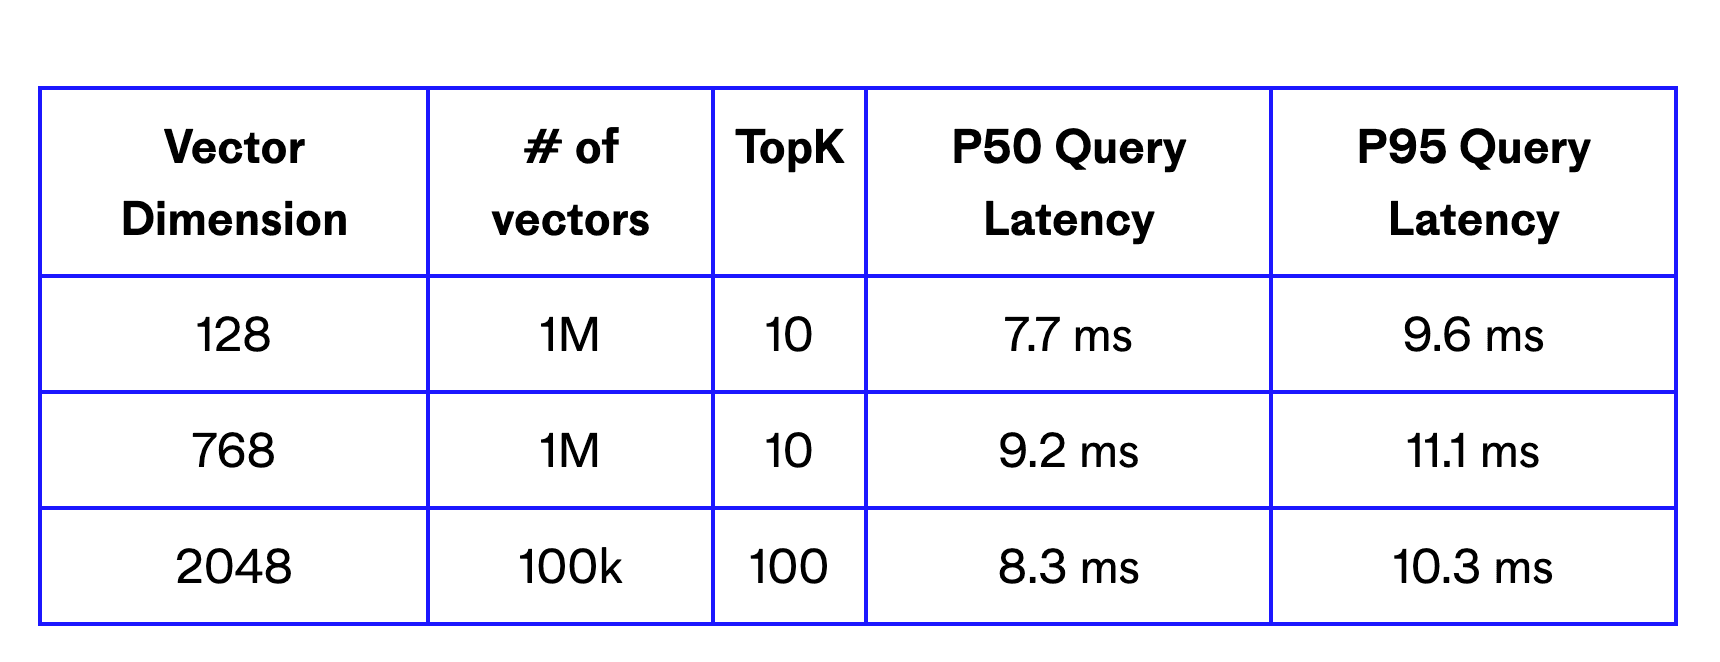
Vertically scaling p2 pods also improves each pod’s throughput. For example, with a single p2.x8 pod, you can support over 1000 QPS searching across 10 million 256 dimension vectors.

As always, your performance and accuracy may vary and we encourage you to test with your own data and follow our tips for performance tuning. Performance is dependent on vector dimensionality, topK, filter conditions, cloud provider, and other factors.

If you have high storage and low QPS requirements, consider using our s1 pod type.

Get started

Check out the documentation to learn more and how to start using p2 pods. We will share benchmarks against p1 in the near future, so stay tuned!