








Patent litigation leaves no room for uncertainty. When legal teams build a case, they rely on a complete historical record; a single overlooked document can redirect months of strategy and millions of dollars in potential outcomes. For companies that provide prior art search—the process of locating pre-existing evidence that an invention already existed—the margin for error is effectively zero. Their value comes from finding what others miss, and doing so consistently.
Melange, a patent analytics company, built its business on a clear premise: AI can examine far more data, in far less time, than human reviewers while accurately surfacing the 6–10 documents that determine the direction of a lawsuit. But delivering this outcome requires more than strong models. It requires an infrastructure layer that can reliably search across hundreds of millions of global patents and academic papers, and do so without failure.
What Melange discovered early is that the cost of inaccuracy is not just legal risk for their customers. It is operational risk, engineering cost, and time lost. It also opens the possibility of losing clients when competing firms find documents they might miss.
To avoid that outcome, Melange turned to Pinecone.
Melange works at the demanding intersection of AI, legal expertise, and vast technical data.
Every case begins with a single question: Did this invention already exist before the patent was filed? Answering that requires combing through decades of global patent filings, machine-translated foreign documents, technical manuals, obscure academic papers, and the collective written record of innovation across hundreds of categories.
If Melange’s system misses even one key document, the consequences cascade:
When we find that one killer piece of prior art that the customer thinks might win their case, we lock in the customer for life. — Joshua Beck, CEO at Melange
And the inverse is also true.
This is why accuracy, and the infrastructure that supports it, is central to Melange’s product and business.
Before Pinecone, Melange ran a self-hosted Milvus cluster. It worked fine at ~40M vectors, but that’s where it ended.
The moment they tried to scale toward the full global patent corpus (~450M documents at the time), the system collapsed under memory pressure. Uptime was unreliable. Index rebuilds failed. Maintenance costs soared. And most importantly, Melange could not guarantee complete, high-recall search.
The business implications were clear:
Melange did not have the people or time to fix those issues. They are a search and analytics company—not an infrastructure company. They needed a vector database that could give them reliable recall at massive scale and operate with minimal engineering work. As they evaluated replacements, including hosted options like Turbopuffer, Melange found that Pinecone offered the strongest recall and the most responsive support, both of which were essential.
Melange’s business needs are demanding and specific:
Pinecone matched those requirements directly by removing operational overhead and delivering consistent performance across massive datasets.
1. High-recall retrieval at scale
Accuracy starts with complete recall. Pinecone’s architecture keeps index structures stable and query performance predictable as dataset sizes grow into the hundreds of millions—and soon, billions—of vectors.
For Melange, this consistency is crucial. They can’t afford model regressions or index failures that would hide relevant documents from search results. This need for dependable, high-recall retrieval was a core reason Melange chose Pinecone over alternatives including Turbopuffer.
2. Serverless design = lower TCO
The most expensive part of running vector search isn’t compute; it’s people. Pinecone’s serverless design eliminated the need for Melange to maintain nodes, tune memory, rebuild indexes, or design storage strategies. Their team interacts with Pinecone as an API instead of an infrastructure system.
Our KPI for Pinecone is straightforward: how little time we spend thinking about it. — Joshua Beck, CEO at Melange
That simplicity directly decreases Melange’s total cost of ownership (TCO). They estimate Pinecone saves them ~$75,000 per year, not including the value of faster model iteration and less operational friction.
3. Stable ingestion and fast model iteration
Accuracy depends on fresh data and updated embeddings. Pinecone’s Parquet-based ingestion pipeline lets Melange load new model versions, run comparisons, and test new strategies without downtime or re-architecting their system.
4. Reliability as a competitive advantage
Melange’s customers expect their results to be complete and defensible. Pinecone’s reliability underpins that expectation. Since migrating, Melange reports zero reliability issues, even as vector counts climbed beyond 600M.
Reliability is not only a technical requirement—it is a differentiator in a market that often relies on trust built over years of legal work.
Melange works on cases where:
Missing a single prior-art document can materially alter the trajectory of those numbers.
But accuracy and inaccuracy also carry operational costs. These dynamics become clearer when you compare the costs of inaccuracy with the impact of a stable, high-recall retrieval system:
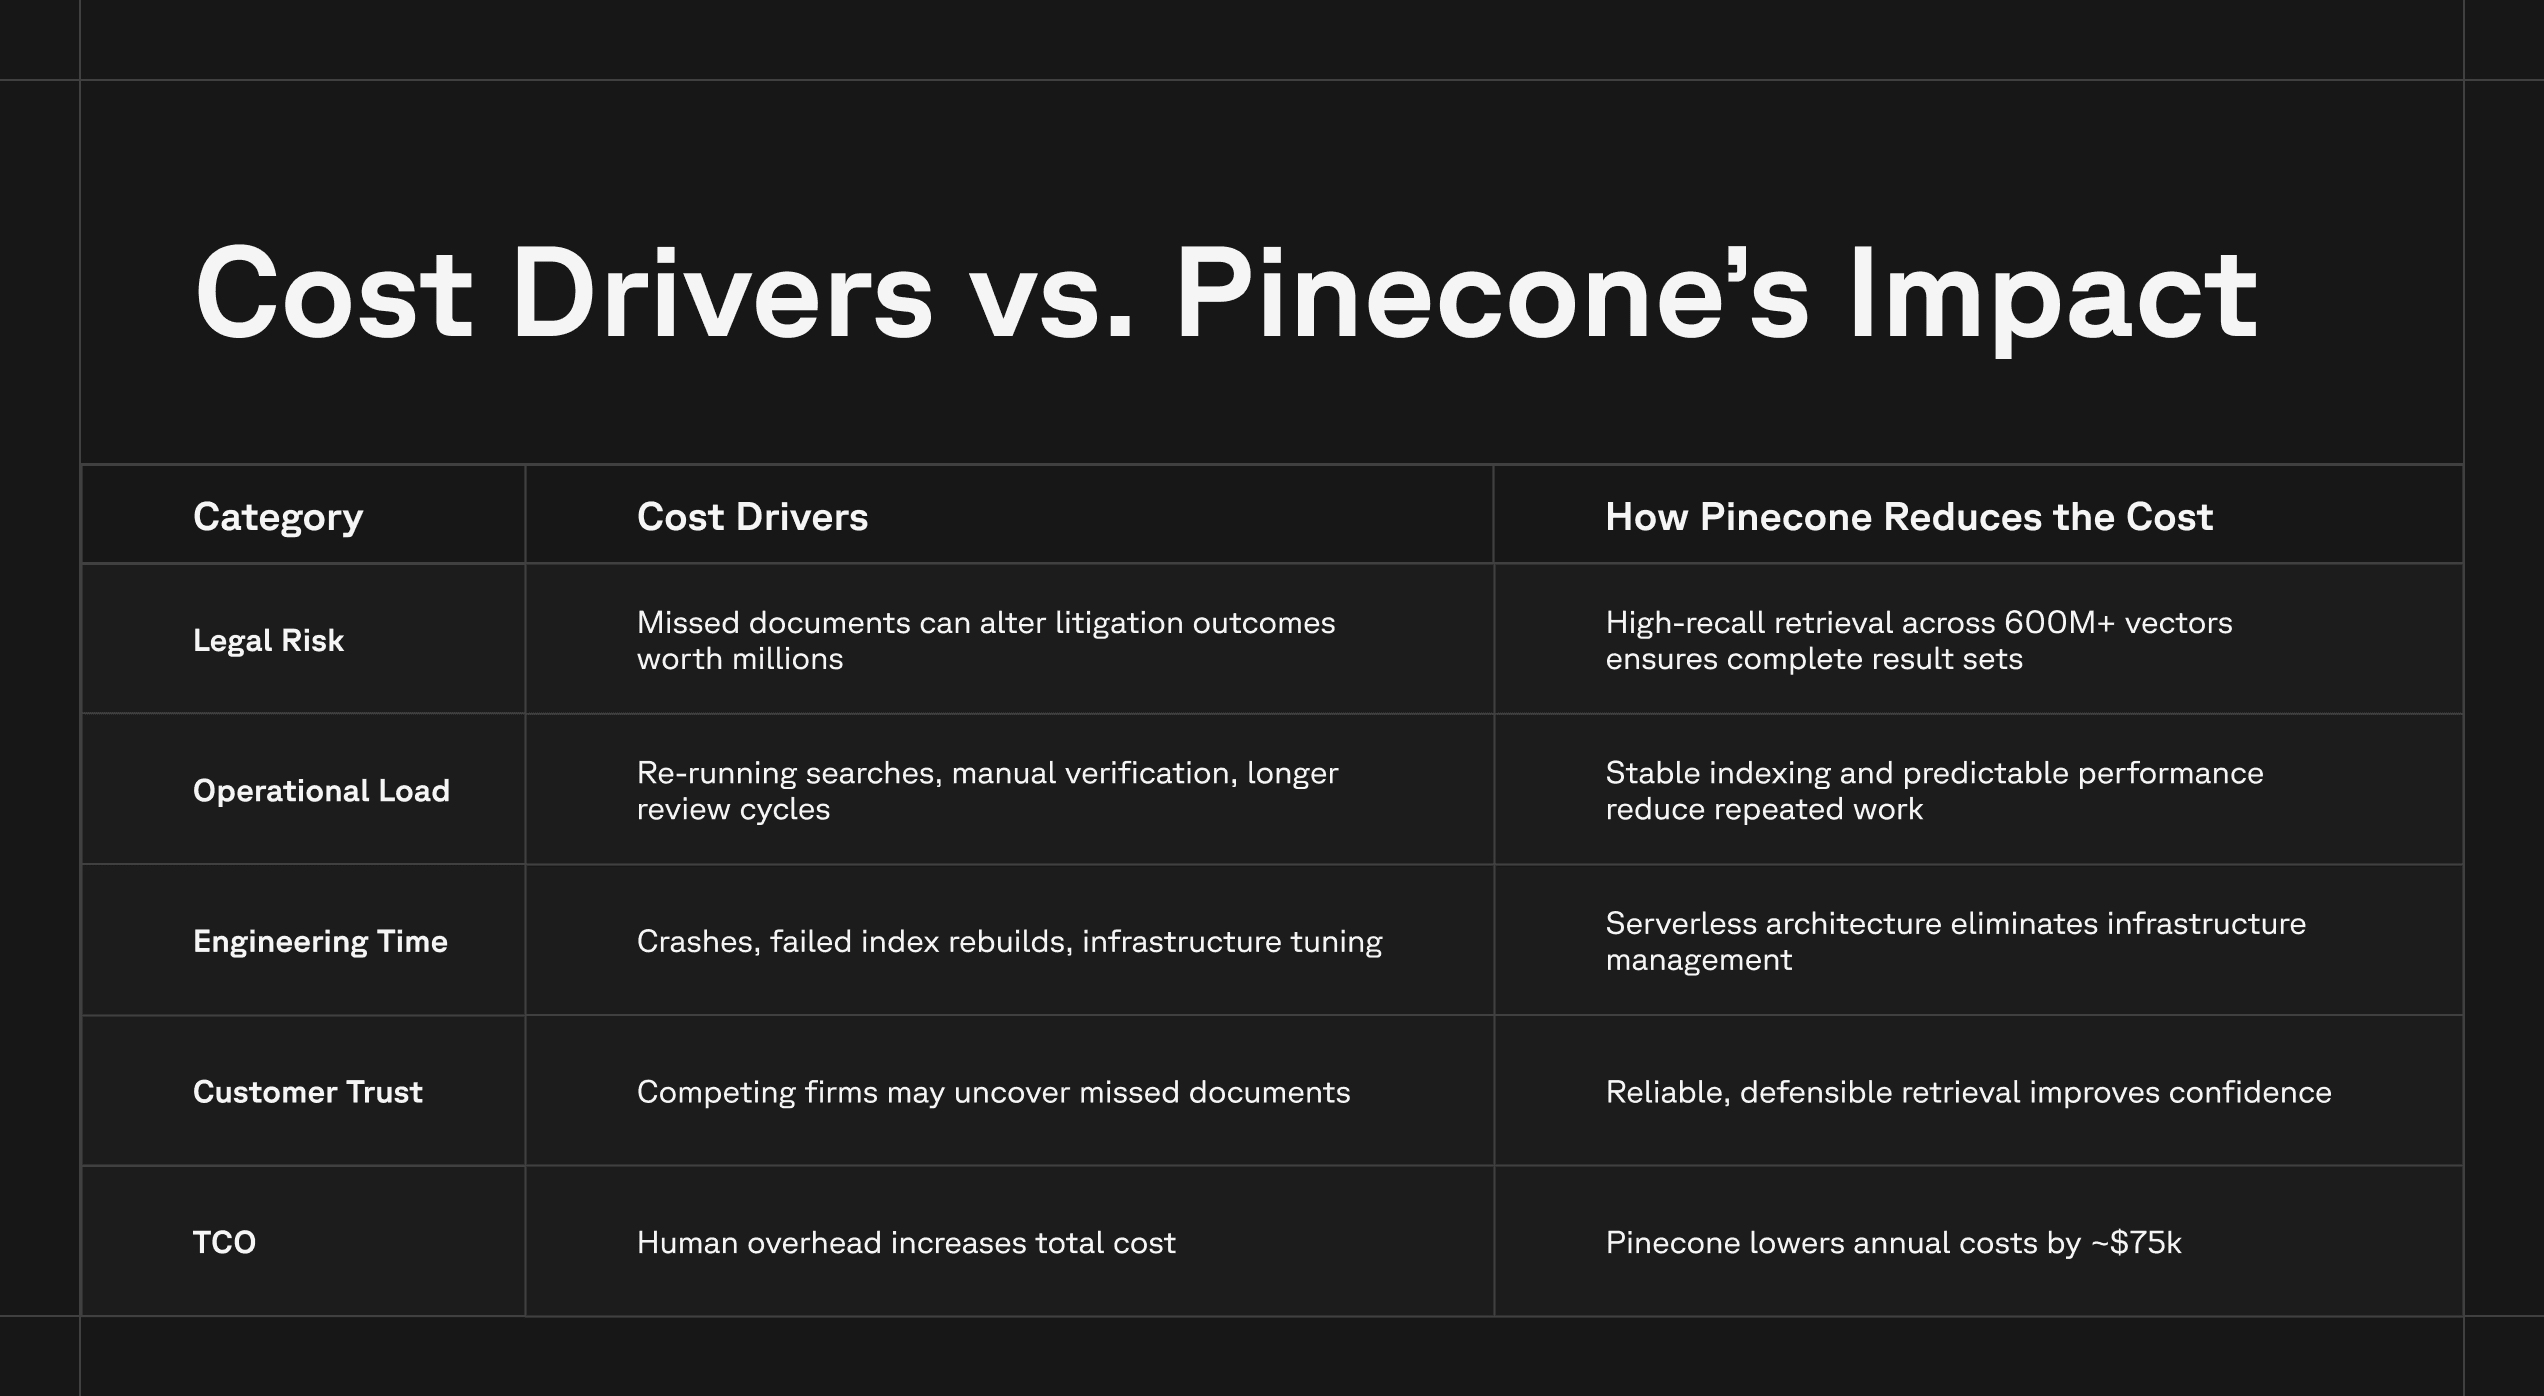
A common misconception is that accuracy in retrieval systems comes solely from the embedding model. In reality, for companies like Melange, accuracy is a system property:
Model quality × index structure × search performance × freshness × completeness
Pinecone serves as the backbone of that system:
Accuracy emerges from the entire pipeline working in concert.
And because Pinecone removes complexity, the Melange team can focus on the parts of the system that directly improve accuracy: embedding strategies, ensemble models, and domain-specific ranking techniques.
The cost of inaccuracy for Melange is real and quantifiable. In a world where a missed document can influence multi-million-dollar litigation, the retrieval system behind their AI must be both accurate and reliable.
Pinecone gives Melange a foundation where:
In an industry defined by high stakes and unforgiving margins, Melange uses Pinecone to deliver the one thing their customers care about most: Complete, reliable, defensible prior-art search—at scale.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。