


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

L
LangChain Blog
博客园_首页
钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
月光博客
月光博客
S
SegmentFault 最新的问题
量子位
Apple Machine Learning Research
博客园 - 司徒正美
博客园 - Franky
Google DeepMind News
Recent Announcements
B
Blog RSS Feed
C
Check Point Blog
The Cloudflare Blog
M
MIT News - Artificial intelligence
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
F
Fortinet All Blogs
Hugging Face - Blog
Hugging Face - Blog
博客园 - 叶小钗
V
Visual Studio Blog
V
V2EX
Microsoft Azure Blog
博客园 - 聂微东
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More

Pinecone

Pinecone Assistant: A Managed Knowledge Layer for Production AI Applications Multi-domain RAG in n8n: why one knowledge base is not enough Allspice Transforms the Culinary Experience with Semantic Search Powered by Pinecone | Pinecone Building RAG workflows in n8n: choosing the right Pinecone node Knowledge needs a meta-knowledge layer Garbage Day: How Pinecone Safely Deletes Billions of Objects at Scale When "Performance" Means Two Different Things Pinecone BYOC: Pinecone in your AWS, GCP, or Azure account, no vendor access True, Relevant, and Wrong: The Applicability Problem in RAG Use the Pinecone Plugin for Claude Code to develop AI Applications Faster Millions at Stake: How Melange's High-Recall Retrieval Prevents Litigation Collapse Powering High-stakes Patent Search at Scale: How Melange Built a Reliable AI System on Pinecone | Pinecone Pinecone Assistant Node in n8n: Turn Any Data Source Into Knowledge RAG with Access Control Pinecone Dedicated Read Nodes are now in Public Preview Inside Pinecone: Slab Architecture New Bulk Data Operations: Update, Delete, and Fetch by Metadata The Hidden Cost of Building: Lessons from Aquant Simplifying Vector Embeddings with Pinecone Integrated Inference Capabilities Pinecone joins Microsoft Marketplace as a Launch Partner GTM Engineering: Clay + Pinecone for AI-powered Sales Outbound Build an AI knowledge assistant with Google Docs and Pinecone Moving Pinecone forward with Ash Ashutosh as CEO and Edo spearheading our growing AI ambitions as Chief Scientist Pinecone Founder Edo Liberty to Spearhead Pinecone’s Growing AI Ambitions; Appoints Ash Ashutosh as CEO to Expand Vector Database Market Leadership Fast, Accurate Retrieval for Creators at Scale: Delphi’s Path Toward a Million Conversational Agents with Pinecone | Pinecone Announcing Pinecone Pioneers: A Program for Builders, Organizers, and Community Leaders What is Context Engineering? Chunking Strategies for LLM Applications Beyond the hype: Why RAG remains essential for modern AI Obviant Makes 30% More Accurate Defense Acquisition Recommendations Combining Sparse and Dense Retrieval with Pinecone | Pinecone
Introducing Pinecone Inference to streamline your AI work...
Gibbs Cullen · 2024-07-09 · via Pinecone

Introducing Pinecone Inference, an API that provides easy and low-latency access to embedding and reranking models hosted on Pinecone’s infrastructure. Inference — alongside our vector database — makes Pinecone a “one-stop shop” for embedding, managing, and retrieving vector data through a single API. This lets you build knowledgeable AI applications faster, with less complexity and fewer tools to manage.

Inference is in public preview and currently supports the multilingual-e5-large model, with others coming soon.

Embed, manage, and query your data with a single API

Choosing a suitable embedding model can be time-consuming: You must choose from over two hundred based on multiple factors such as modality, subject domain, and deployment mode, and then you must implement a separate inference service into your application workflow. You’d probably rather spend your efforts prototyping and shipping knowledgeable AI applications.

We chose to start with ‘multilingual-e5-large’ because it’s small, open source, natively multilingual, and performs well on benchmarks across languages. Learn more in our deep dive on e5, including an example notebook for building a search application with Inference.
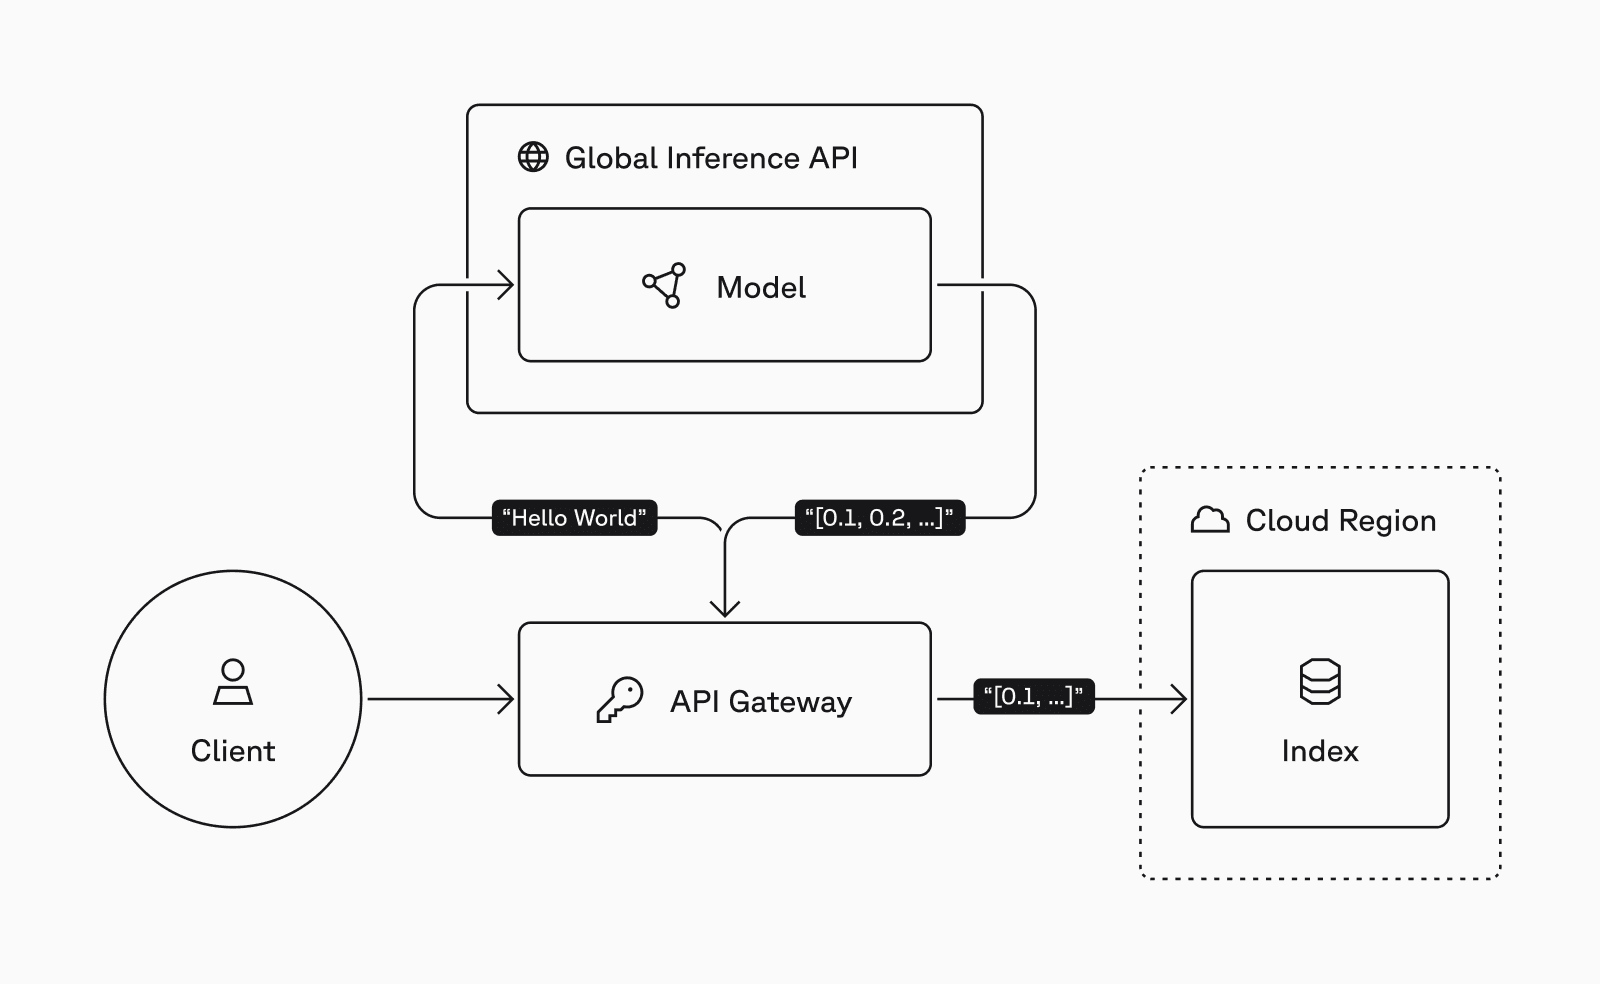
Embed, manage, and retrieve your vector data through a single API within Pinecone.

from pinecone import Pinecone

pc = Pinecone("API-KEY")

pc.inference.embed(
   model="multilingual-e5-large",
   inputs=[
       "The quick brown fox jumped over the lazy dog"
   ],
   parameters={
"input_type": "passage", # passage or query
"truncate": "END" # END or NONE, if NONE raises error
   }
)

Note: multilingual-e5-large leverages asymmetric embeddings for retrieval. You can set the input_type to either ‘passage’ or ‘query’.

While Inference can help accelerate your AI development, Pinecone also supports dense embeddings with up to 20k dimensions from any embedding model or model provider. Choose the model that works best for your workload, regardless of source.

Try Inference today and simplify your workflow

Pinecone Inference is now available in public preview for all users. Starter and Enterprise users pay $0.08 per million tokens, while those on the Starter (free) plan have access to 5 million monthly tokens. We will add reranking and more embedding models in the coming months. Here is a quick resource on how to generate embeddings. Explore our interactive model gallery, and start building with Inference today.