





AI Gateway now displays throughput and latency metrics across hundreds of models, helping you choose the right model based on live performance data.
Metrics appear in three places and are updated every hour:
Model list: Best performance per model (P50 latency and throughput)
Model detail pages: Provider-level performance breakdown
REST API: Rolling endpoint performance aggregates (latency and throughput, P50/P95)
Link to headingModel list
The AI Gateway model list now includes sortable columns for latency and throughput. Each row displays the best P50 metrics (lowest latency, highest throughput) for that model across all its available providers. Metrics are updated every hour and based on live AI Gateway customer requests.
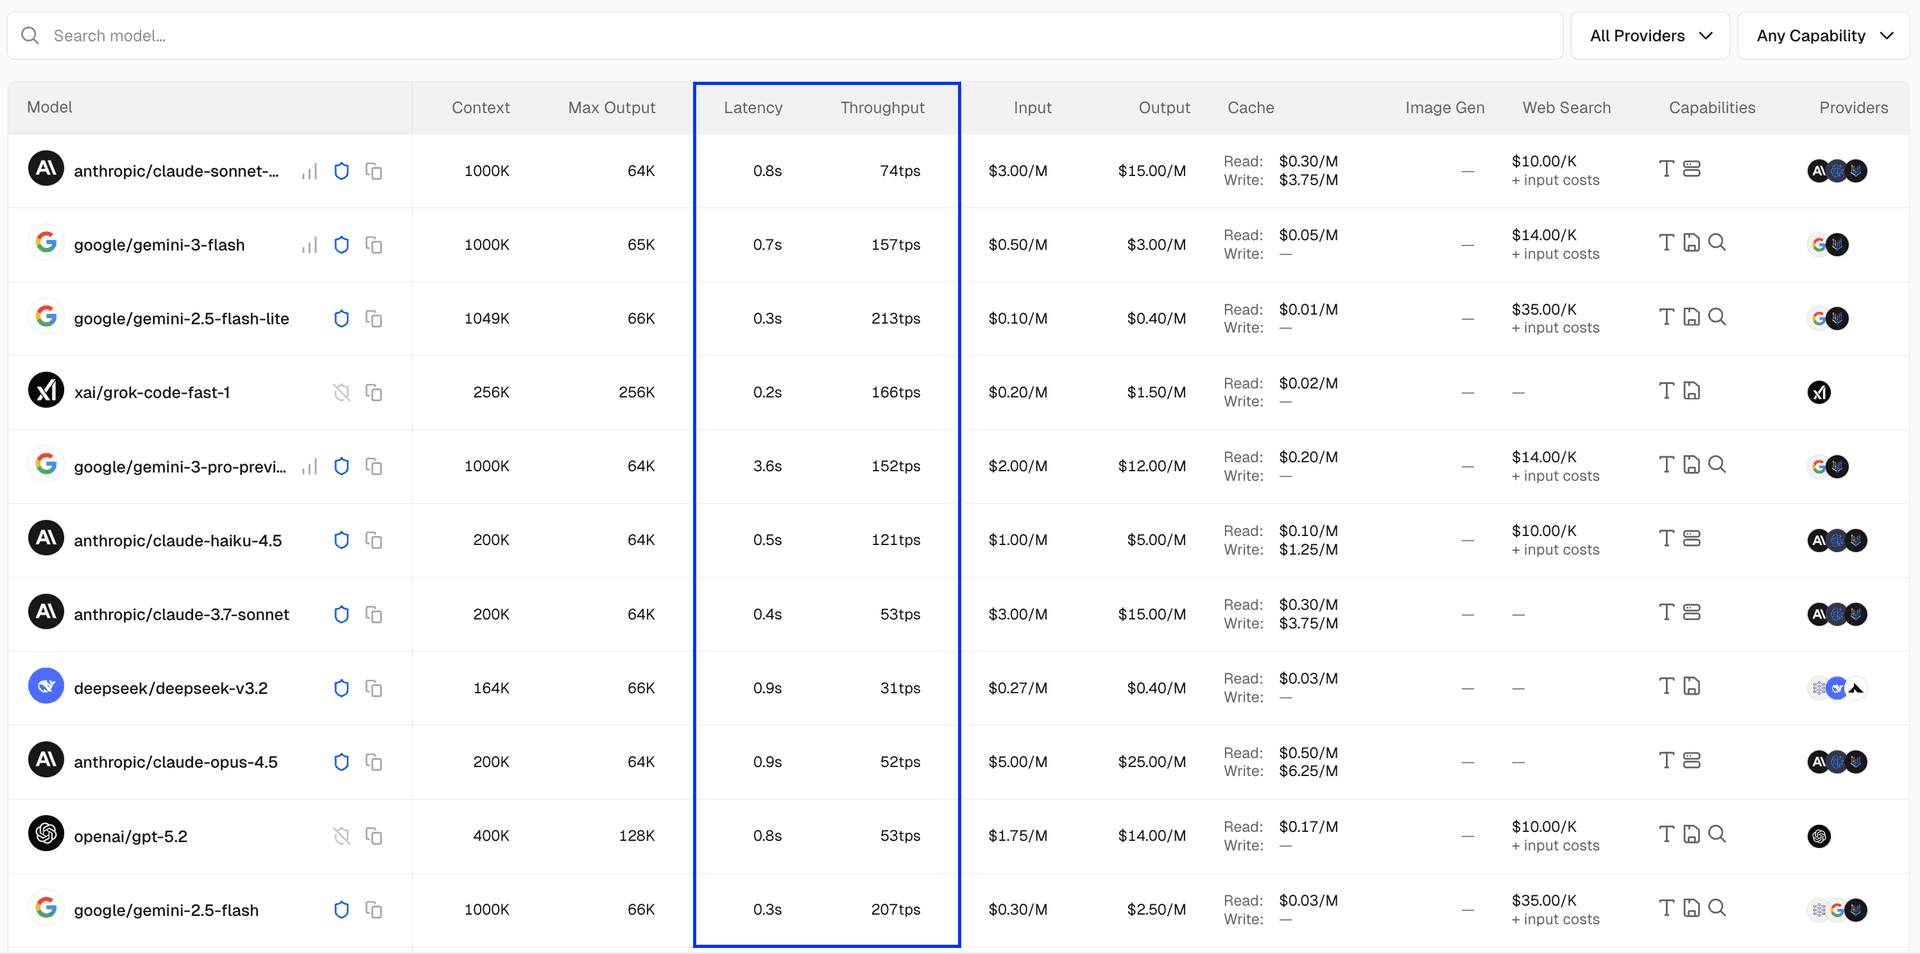
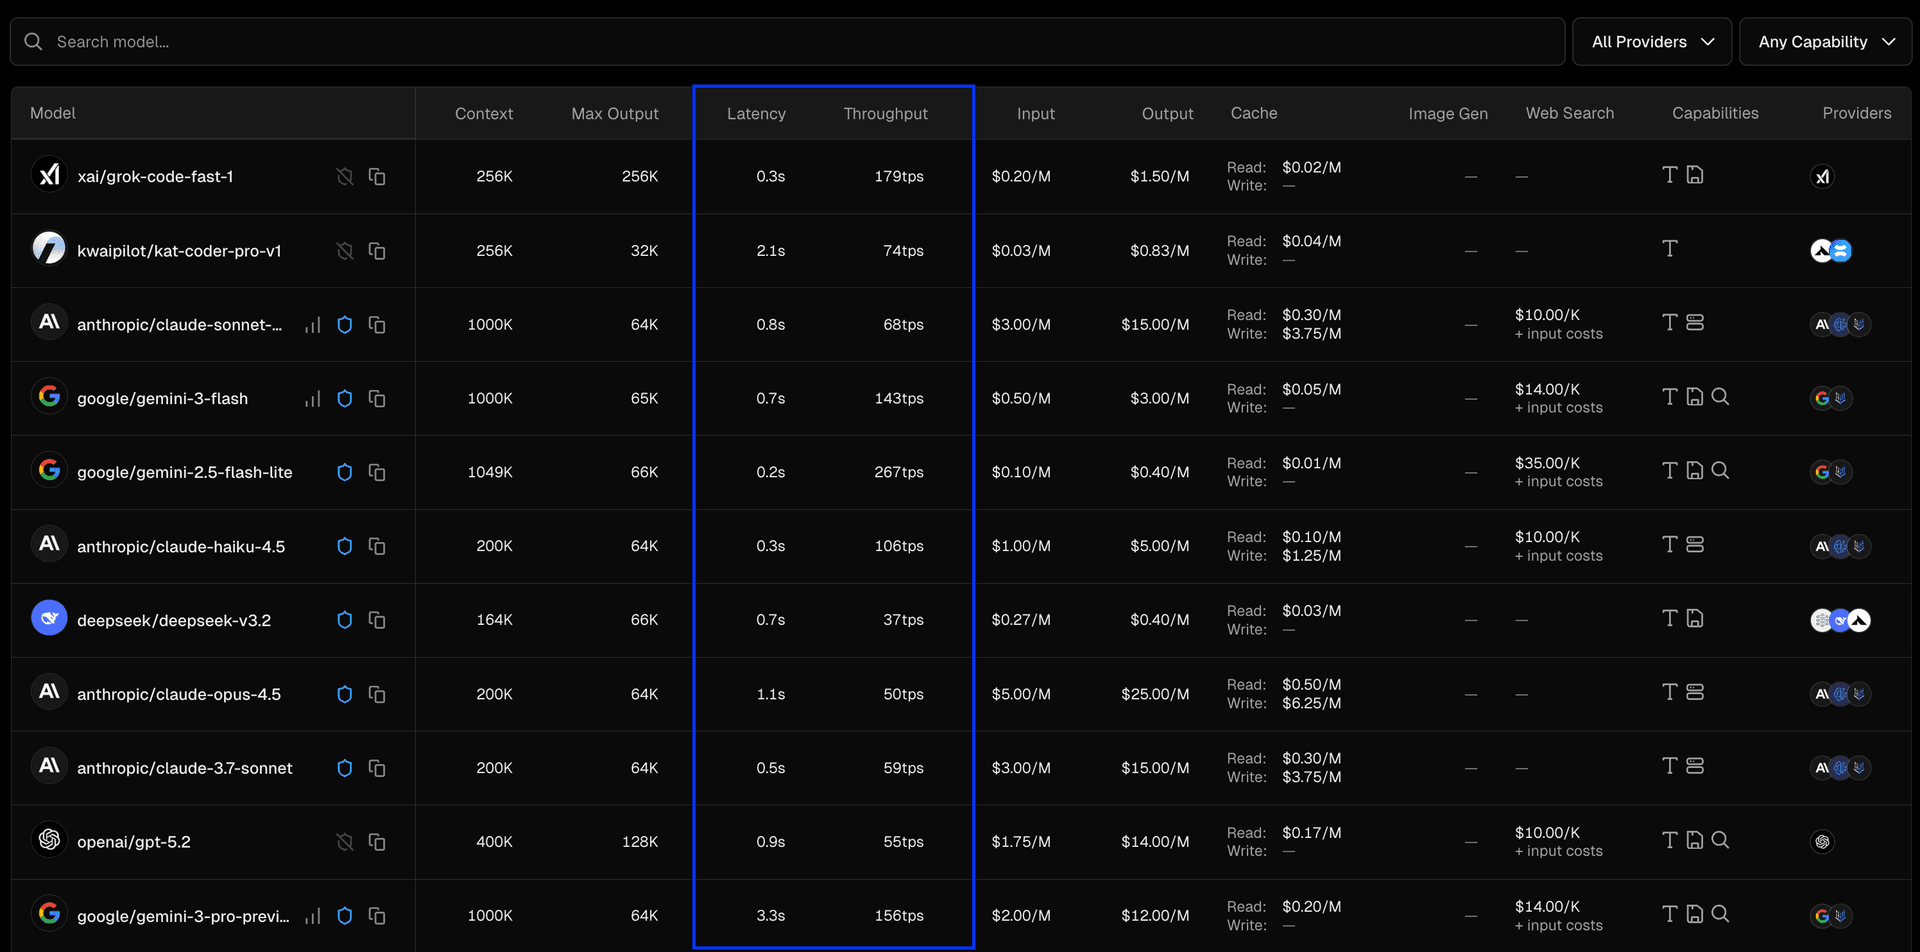
Sort by throughput to find the fastest token generation, or by latency to find models with the quickest time-to-first-token.
Link to headingModel detail pages
On the individual model pages, you can see P50 latency and throughput for each provider that has recorded usage. This helps you compare provider performance for the same model and choose the best option for your use case.
To access these pages, click on any model in the model list to get a more detailed view of the breakdown across all the providers that carry the model in AI Gateway. Metrics are refreshed hourly and only appear for providers with sufficient traffic.
Here is an example for openai/gpt-oss-120b:
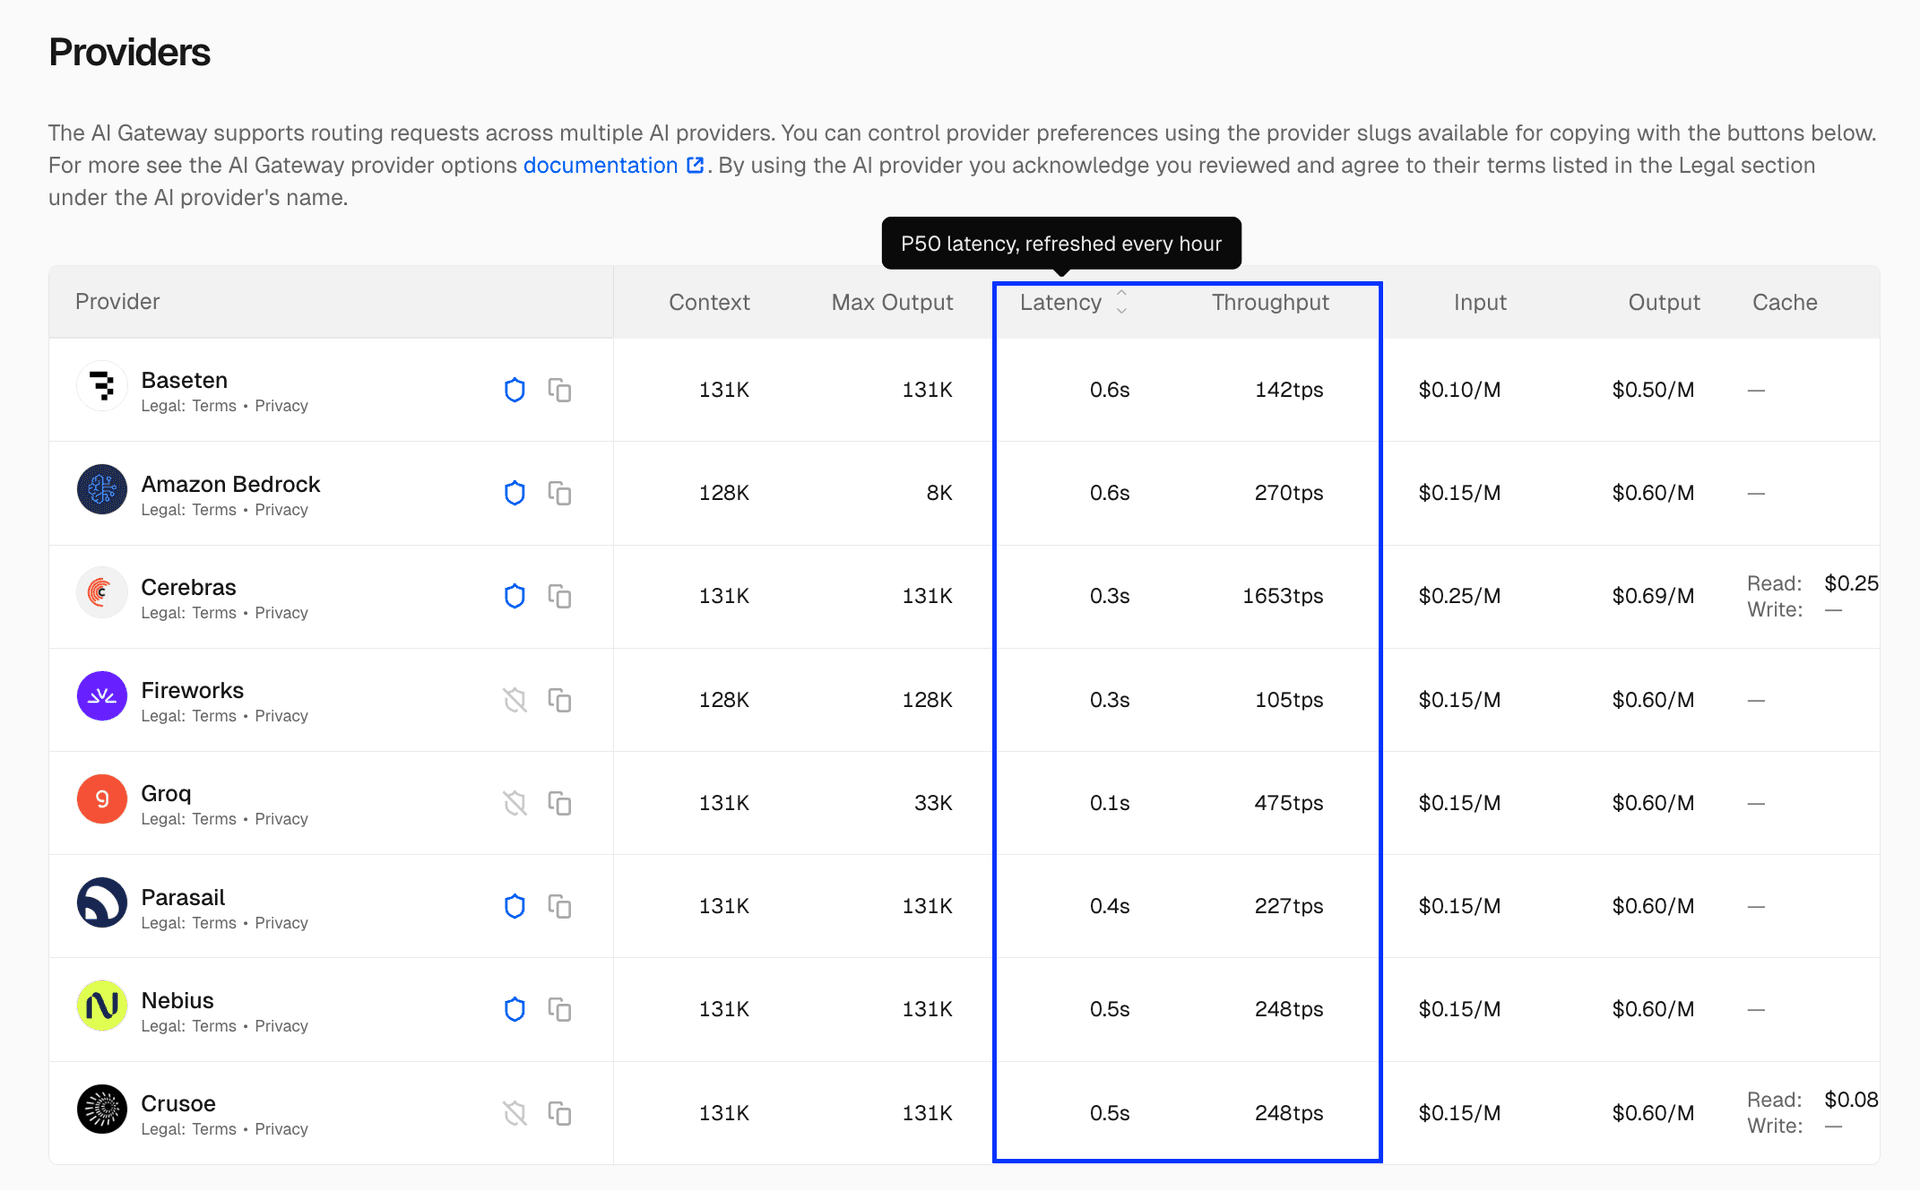
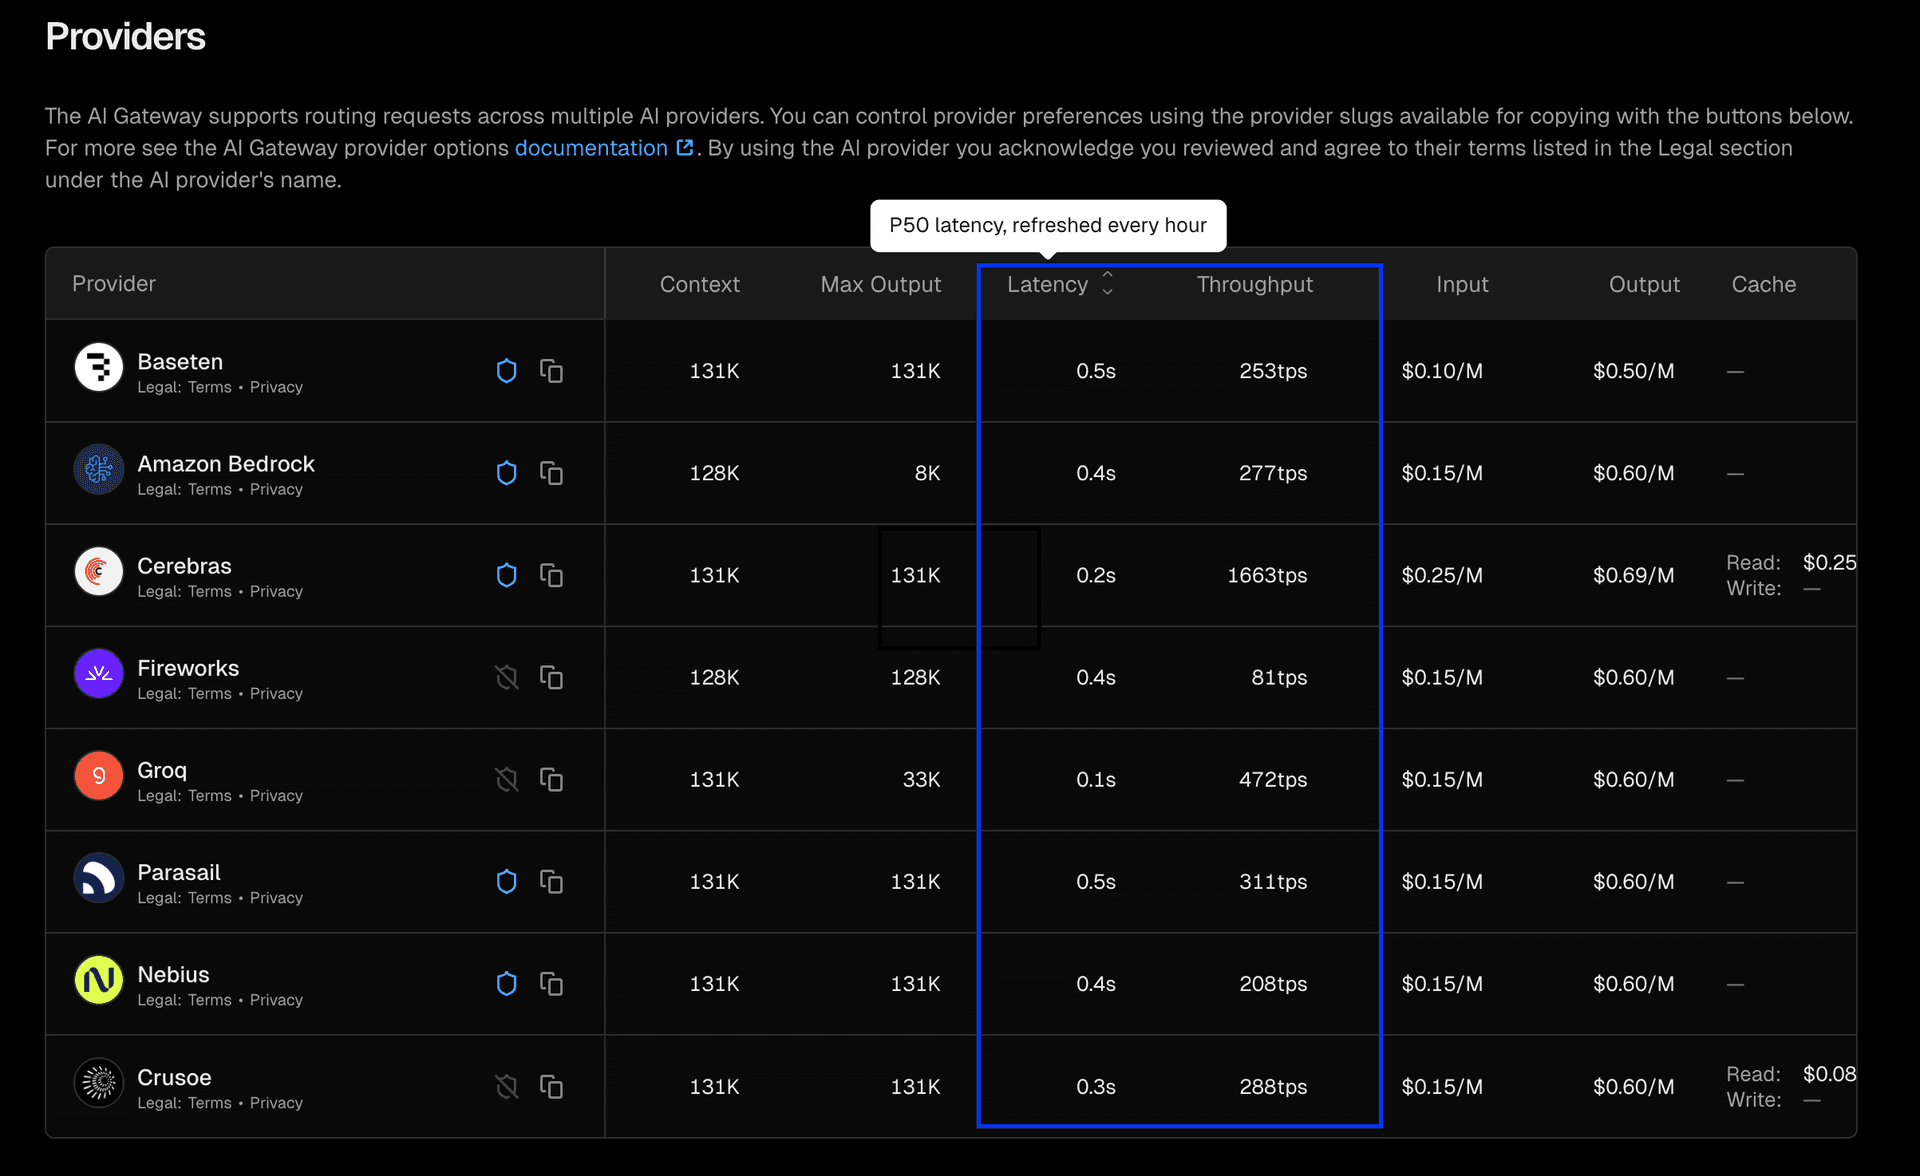
Similar to the overall model list, you can sort by latency and throughput across providers on the model detail pages.
Link to headingREST API
These metrics are also available programmatically via the endpoints REST API. To use this, replace [ai-gateway-string] with the creator/model-name for the model of interest.
curl ai-gateway.vercel.sh/v1/models/[ai-gateway-string]/endpoints
This returns live hourly P50 and P95 latency (ms TTFT) and throughput (T/s) for the specified model, by provider. Here is an example output from the endpoint for the Cerebras provider for zai/glm-4.7.
curl ai-gateway.vercel.sh/v1/models/zai/glm-4.7/endpoints
{
"name": "cerebras | zai/glm-4.7",
"latency_last_1h": {
"p50": 456.5,
"p95": 774.95
},
"throughput_last_1h": {
"p50": 354,
"p95": 445.45
},
}
If you want to query the full list of models, you can also use the model metrics endpoint in conjunction with https://ai-gateway.vercel.sh/v1/models.