




, co-founder and CEO of Snorkel AI, spoke at @Scale: Systems & Reliability about one of the most underappreciated problems in AI deployment: our ability to measure agents has been outpaced — arguably for the first time in the history of the field — by our ability to build them. The talk digs into what it actually takes to close that evaluation gap, and why the data behind benchmarks is the linchpin.
The core asymmetry is this: when the state of the art was training a model to tell a cat from a dog, building a hundred ground-truth examples was trivial, and measuring accuracy on a held-out test set was straightforward. Today, model capabilities are advancing faster than we can build the data sets and benchmarks to empirically evaluate them. You see this in benchmark saturation — an agent scores 90%+ on the evals you care about, but then underperforms in real-world settings. The benchmarks have lagged behind what we’re actually using agents for.
That gap matters because all the monitoring and logging and observability infrastructure in the world is only as useful as your ability to evaluate the output it captures. Observing agents tells you what they did. Benchmarks tell you whether what they did was right.
Alex frames the expanding evaluation problem around three dimensions, using software engineering agents as a running example because it’s a domain that can feel saturated but isn’t.
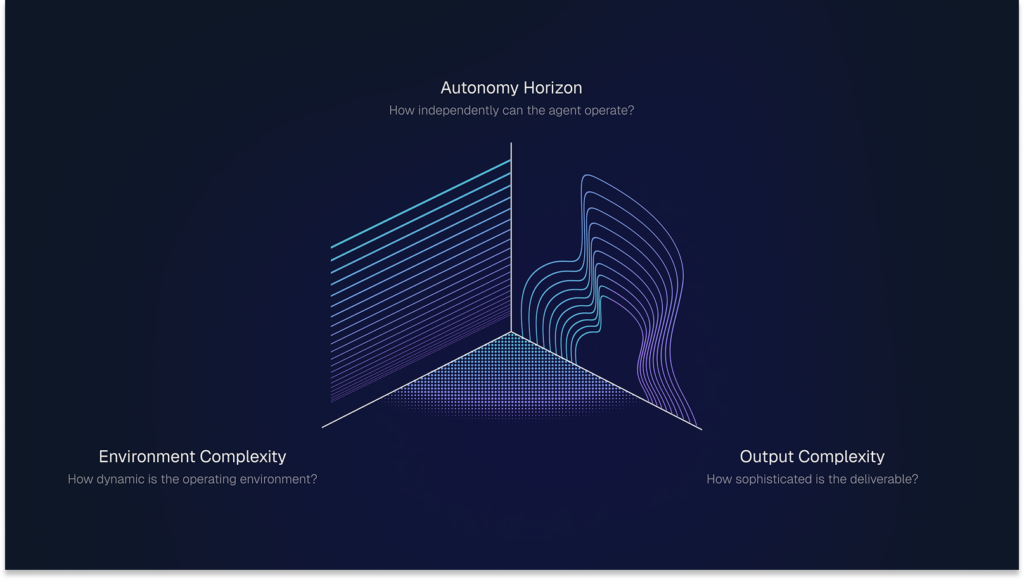
Environment and input complexity. A simple coding benchmark might be a single tricky problem stated in a paragraph. A realistic software engineering evaluation might include an entire miniature codebase — files, tooling, CI harnesses, Slack messages from a PM, input from other systems — everything an agent would actually encounter on the job. Most current benchmarks live at the simple end. The real world lives at the complex end.
Autonomy horizon. The length and dynamism of the task. A multiple-choice coding question requires one step. ProgramBench, which asks agents to replicate entire program artifacts, can require the equivalent of weeks of human work. Crucially, real tasks aren’t linear — goals and constraints shift mid-execution — so the relevant question isn’t just how many steps but how well does the agent adapt when the ground shifts.
Output complexity. As inputs and horizons scale up, so does the difficulty of grading the output. A unit test can check a 101-level coding solution. Evaluating whether an agent built a good software product requires rubrics, verifiers, and multi-dimensional grading keys. Building those graders is itself a research problem.
Even in a seemingly saturated domain like coding, the white space is exponential. HumanEval is approximately saturated at 95%. Terminal-Bench 2.1 sits at ~83%. Terminal-Bench 3.0 is forthcoming and expected to push failure rates well past 80%. ProgramBench has a fully-resolved accuracy rate in the low single digits. The next generation — staff-engineer-level system architecture problems — is harder still. The pattern isn’t a ceiling; it’s a frontier that keeps receding as we build better evals. Track the latest results on the Snorkel leaderboards.
The talk makes a point worth dwelling on: in the agentic world, the data spec is a majority of the product spec. Defining what tasks an agent should complete, what environments it should operate in, and what a good output looks like is an increasing percentage of the work of building the product itself.
What that data looks like has changed dramatically. In the chatbot era, a test question was a prompt and an expected response. In the agentic era, a test question might be: a complex, domain-specific task; a full simulated environment (legal research tools, an EHR system, a code repository); rubrics and verifiers that give feedback not just at the end state but at intermediate steps along the way.
Building that data well requires scoping and calibrating the benchmark continuously, constructing environments and tasks in tandem, running agents against early drafts to find failure modes, and reviewing every component of the resulting payload before it’s versioned and published. It’s slow, careful work — and it’s where most of the leverage sits. For a deeper look at what this pipeline requires, see why coding agents need better data, evals, and environments.
Three examples from Snorkel’s Open Benchmarks Grants program illustrate where the field is heading:
Terminal-Bench gives agents full terminal access and covers a wide range of agentic operations and failure modes. It’s been both a measuring stick and a guidepost — it has shaped the direction of coding agent development over the past year. Good benchmark distribution matters: a benchmark every agent aces isn’t useful; one that only probes one failure mode isn’t either.
SlopCodeBench measures coding tasks where the spec changes during execution — a direct test of that autonomy-horizon problem. Most real-world projects don’t go straight-line. Requirements shift. An agent that performs well on a fixed spec may accumulate technical debt and drift when the target moves. This benchmark surfaces that failure mode.
Continual Learning Bench (out of Berkeley) evaluates whether agents can improve across a sequence of tasks — not just whether they can perform a task, but whether they can learn from task one before tackling task two. You can’t improve what you can’t measure, and this benchmark makes that form of improvement measurable.
The evaluation gap won’t close on its own. The surface area of what agents can do — and what we want them to do — is expanding faster than sample efficiency gains will offset. The path forward runs through better data: richer environments, longer-horizon tasks, and more nuanced graders that match the frontier of actual agent capabilities.
If you’re working on a benchmark in this space, the Open Benchmarks Grants program is open. Snorkel has committed $3M, about 20 benchmarks are being announced in the coming months, and a new batch is being onboarded. The goal is to support open, well-designed benchmarks driven by academic and open-source teams — the kind of evaluation infrastructure the field actually needs.
For more on how data powers better agent evaluation, see Closing the Evaluation Gap in Agentic AI, Benchmarks Should Shape the Frontier, Not Just Measure It, and our research hub.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。