




You’ve spent years building valuable knowledge for your organization—the kind of specific data that makes or breaks the daily work of your teams. But your organization’s work is being spread across more and more surfaces: AI tools, Slack conversations, documents, coding environments, and private sessions. You’re moving faster than ever because of AI, which means you’re also accumulating more data than you can keep up with.
And it's not just hard for your people to keep track of—it's hard for your agents too. Which document is current? Which answer is actually right? Your agents are asking the same questions your teams are, just faster, and with a lot more confidence than the answer deserves. If you’re still treating your data like it’s business-as-usual, much of the context your team is creating will be collecting dust in your many distributed tools.
Agents are being pushed into production with stale, conflicting, and missing information, and they’re executing historical mistakes confidently and at speeds that your human teams can’t keep up with. To make it work, humans need to be in every loop, double checking everything agents do, and that costs you time, efficiency, and tokens. When you stack all of this across teams and agents, your business pays the cost. And along the way, your team’s valuable solutions are disappearing instead of becoming reusable organizational knowledge. So how do you fix it?
Good thing we’ve just launched new capabilities in Stack Internal as we build our upcoming platform experience.
The new Stack Internal platform is an AI-native knowledge platform that fits within your existing infrastructure and provides knowledge you can make decisions on across your organization. Stack Internal turns your team’s solutions, discussions, and outcomes into decision-grade knowledge that can benefit the next person—or agent—that needs it. When knowledge management stops being a chore and becomes a byproduct of the work itself, information silos are broken down, and your agents start producing reliable, autonomous results.
Rather than just retrieving information that might be relevant, Stack Internal determines if that information is reliable, current, authoritative, and safe to use. It automatically ingests knowledge across sources, sliced and evaluated for trust, and delivers it to your teams and agents whenever and wherever they need it. Even as an enterprise’s underlying AI models, applications, and systems change, Stack Internal keeps your context fresh, creating a persistent and durable knowledge layer for all of your work. This is living, relevant, and validated knowledge that can be used across the entire organization and fed into AI workflows.
While there may be a simple answer for the enterprise-level AI tool woes, getting that decision-grade knowledge isn’t so simple. So let’s break down what we’re building for Stack Internal to help simplify context for your team.
The platform automatically builds and maintains a source of truth from knowledge created across your organization. Our July release introduces automatic ingestion that breaks raw data into durable stored knowledge. We’re starting with Stack Internal community, Google Docs and Slack connectors that ingest critical context from your distributed tools—slicing, storing, and evaluating for trust.
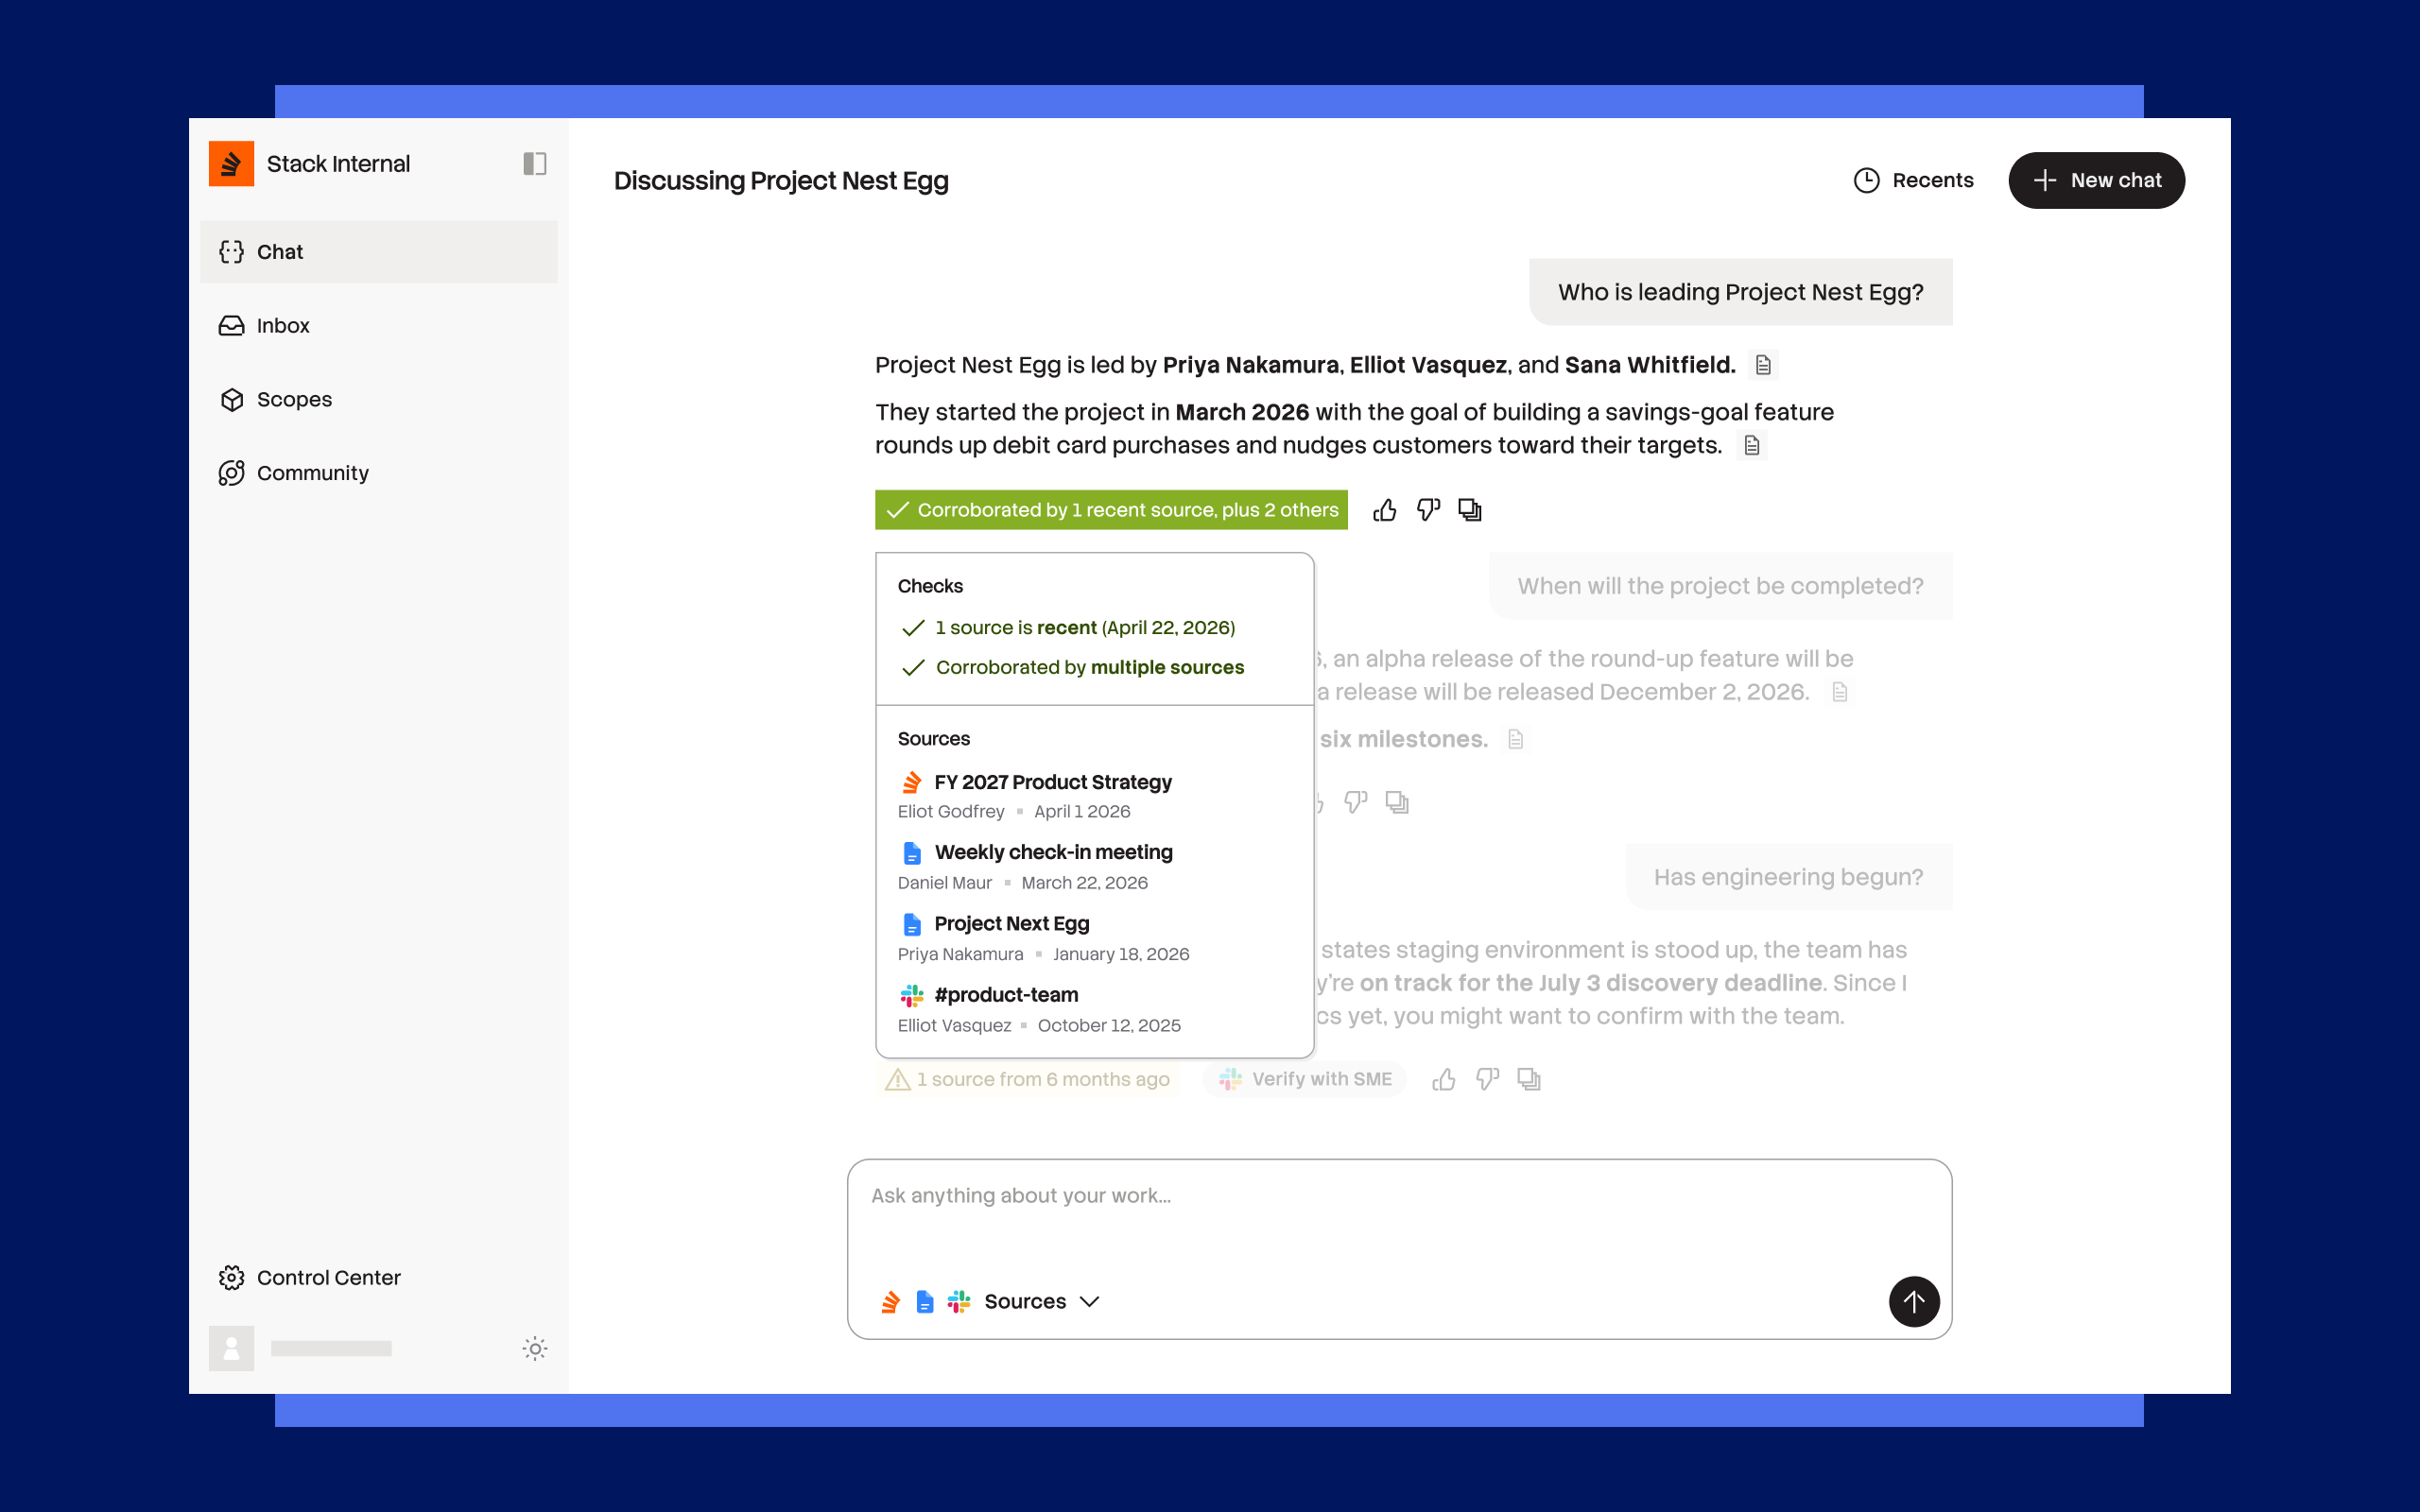
Give your teams and AI agents knowledge they can actually make decisions with. Our new chat interface has response-level confidence labels and provenance cards so there’s never a doubt about where information came from or how much it can be trusted.
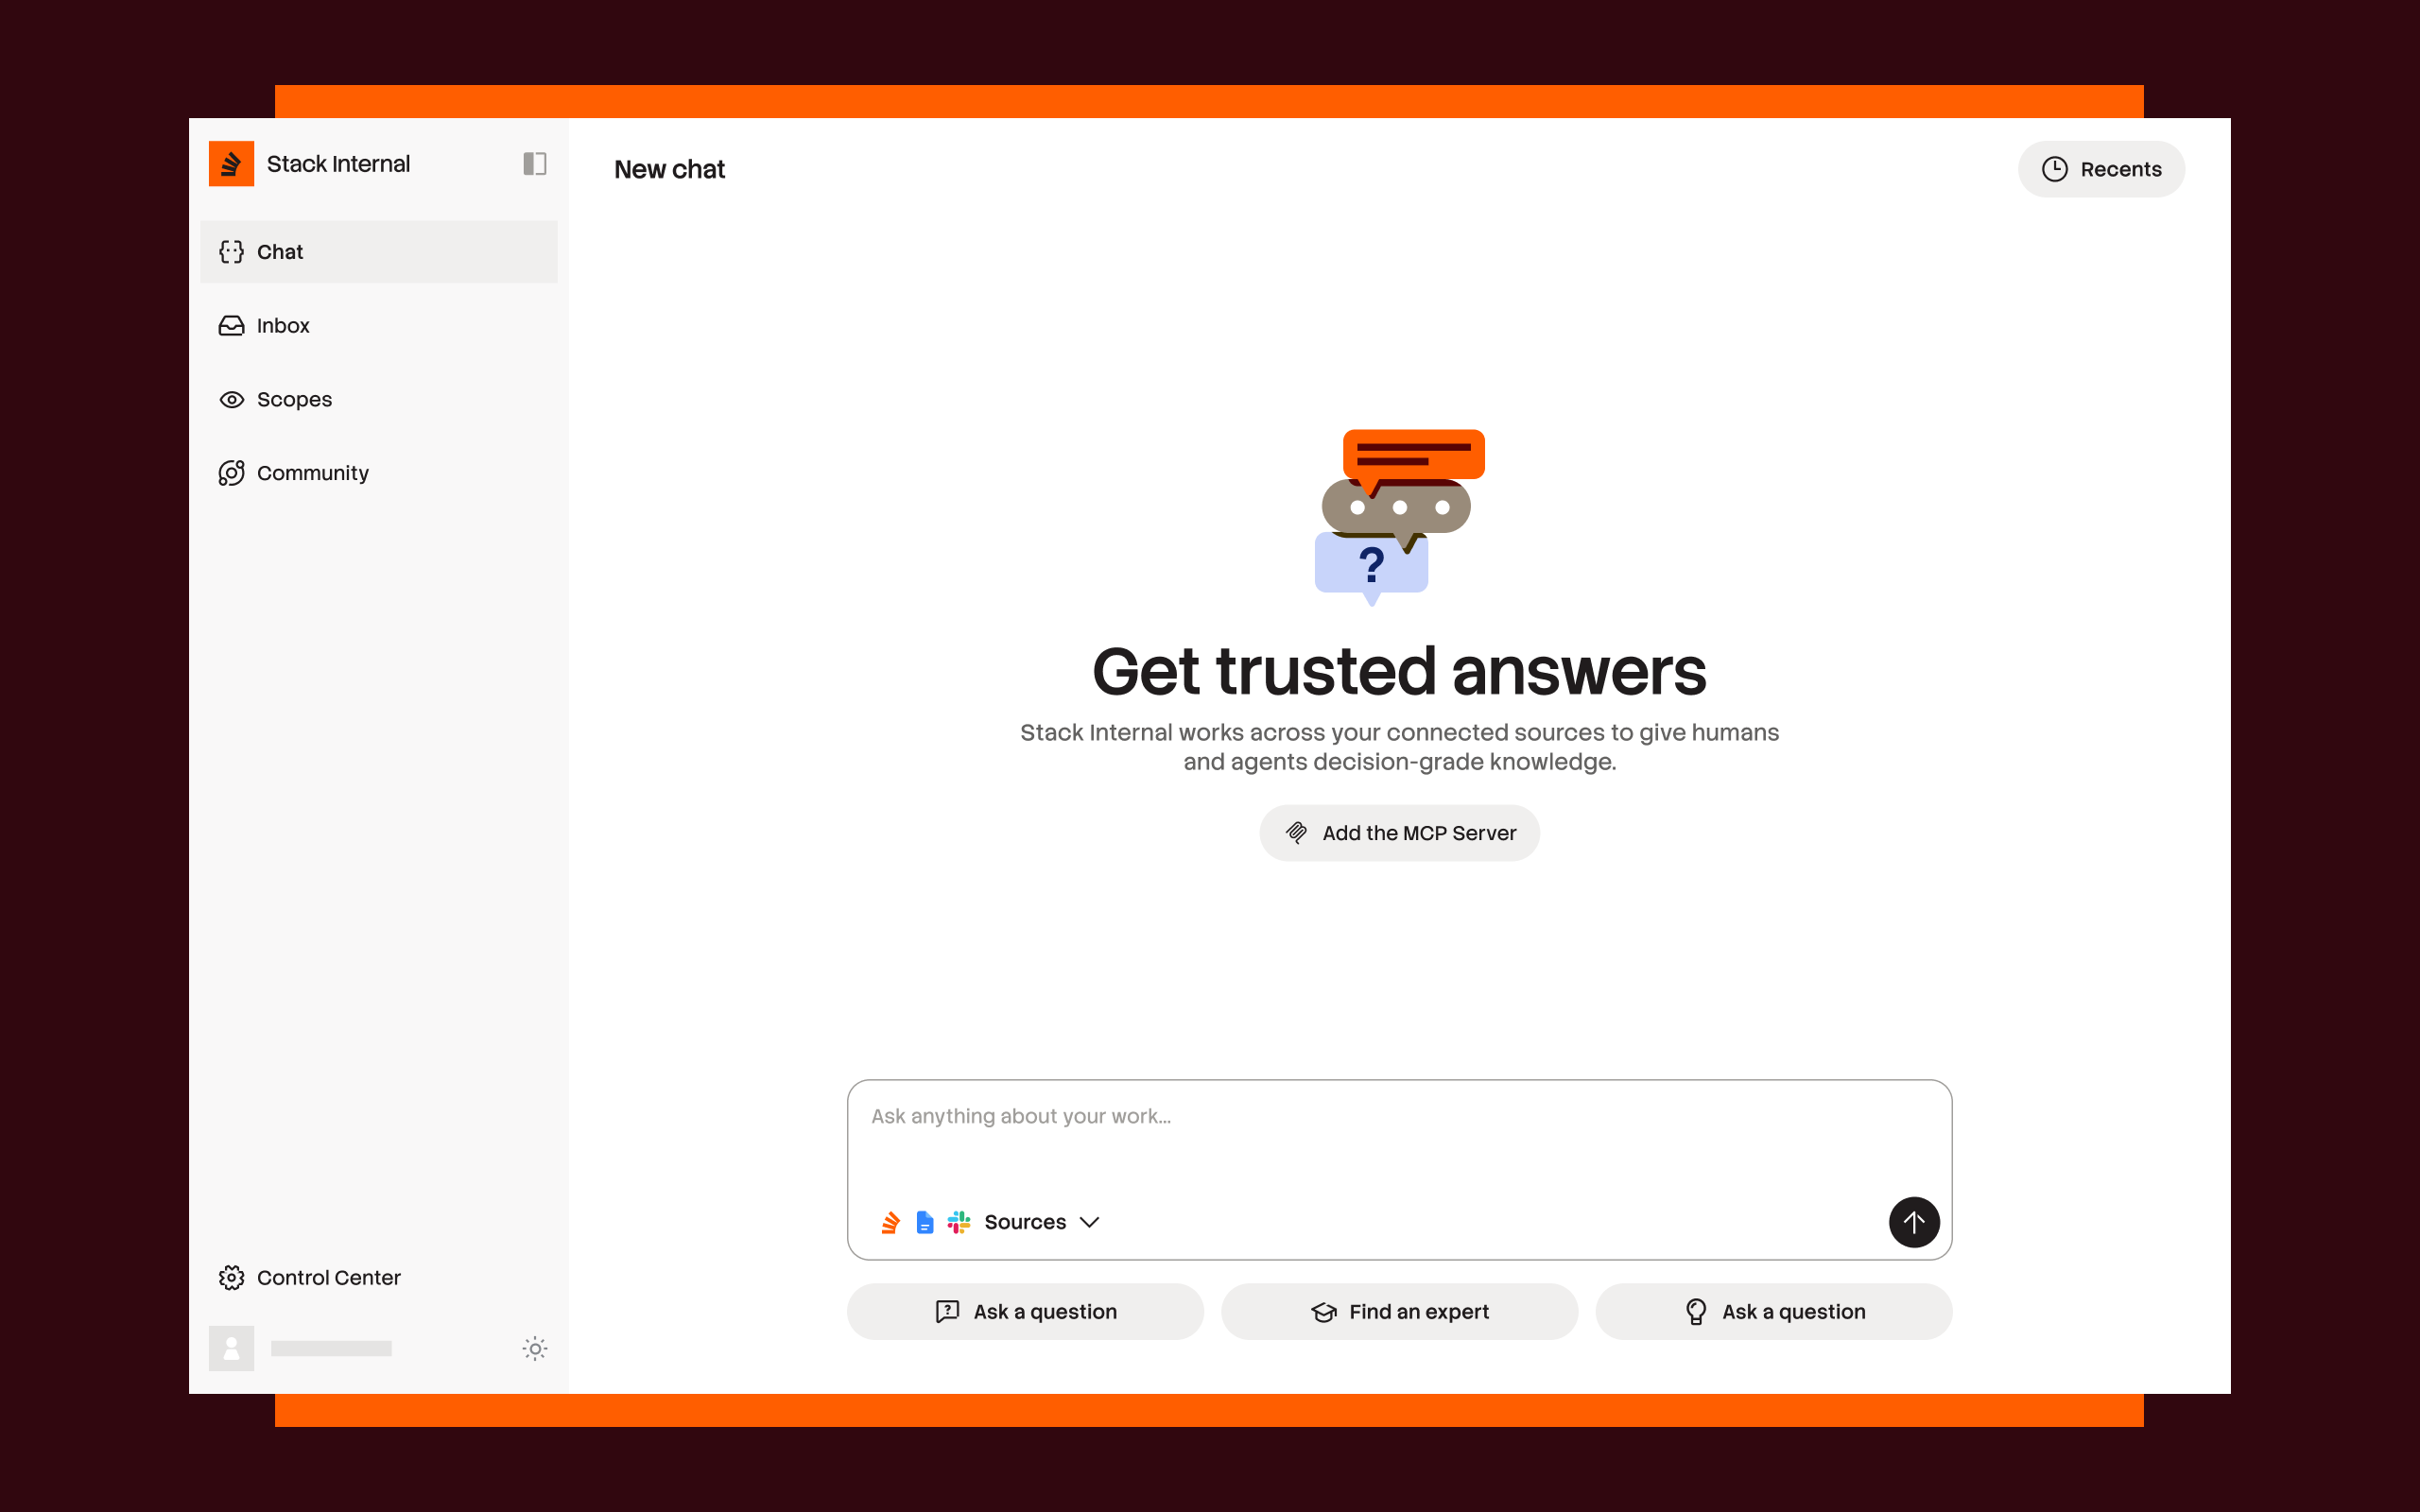
And when Stack Internal detects a gap in existing knowledge, it’ll automatically route questions to domain experts to verify (coming soon). You can also streamline AI agent context retrieval in-flow with our API and MCP server integrations to wherever work happens.
AI agents are helping build the future of your company, so you should be building your knowledge with them in mind. The new Stack Internal treats agents as first-class citizens with compliant, explainable, and permission-aware knowledge access. Agents operate within permission boundaries, just like humans, to prevent unauthorized data access. There are identity-aware data boundaries across all surfaces to mitigate security risks and data leakage.
Your community is built on years of human expertise, and knowing what context your teams need is critical. But engineering leaders also need to know where and how that context is being consumed. With our new Swagger API (v3) endpoints, you can now query precise metrics on internal API usage. Break down call volumes by specific internal applications to monitor high-traffic dependencies, compare API V2 and V3 adoption, and gain comprehensive visibility into how your community knowledge is consumed.
The more your teams work, contribute, validate, and reuse knowledge, the more valuable your organizational memory becomes. And voilà! Your existing knowledge management system gets compounding interest, building the reliable and reusable context that your teams and AI tools need to succeed. So begins the virtuous cycle that maximizes your AI investment, improves reliability, and helps your teams move faster than ever, without any added work or token spend.
This is just the beginning of what the new Stack Internal platform experience can do for your organization. In the coming months, we’ll be adding even more features that will help your team build your trusted knowledge layer. You can look forward to even more connectors for your favorite software and workspaces, machine-facing trust scores, conflict and decay detection, super powered knowledge capture and synthesis, and much more.
Here’s one of the most exciting parts: if you’re a current Stack Internal customer, you can actually test out these new capabilities starting today, July 30, 2026, before the new platform experience is released widely. To start the free trial, Admins can follow this guide, or reach out to your Stack Internal account representative to get started. Learn more about this release.
If you’re not a current customer, but interested in trying this new platform, talk to an expert and learn more about Stack Internal.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。