


惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

IT之家
IT之家
J
Java Code Geeks
小众软件
小众软件
Jina AI
Jina AI
OSCHINA 社区最新新闻
OSCHINA 社区最新新闻
Hugging Face - Blog
Hugging Face - Blog
Stack Overflow Blog
Stack Overflow Blog
Blog — PlanetScale
Blog — PlanetScale
C
Check Point Blog
人人都是产品经理
人人都是产品经理
freeCodeCamp Programming Tutorials: Python, JavaScript, Git & More
博客园 - Franky
Apple Machine Learning Research
G
Google Developers Blog
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
H
Hackread – Cybersecurity News, Data Breaches, AI and More
The GitHub Blog
The GitHub Blog
腾讯CDC
T
The Blog of Author Tim Ferriss
大猫的无限游戏
大猫的无限游戏
量子位
M
MIT News - Artificial intelligence
Last Week in AI
Last Week in AI
L
LangChain Blog

Martin Alderson

Have the frontier labs mixed up AI safety and security? Reducing codebase cognitive debt through... quizzes? What GLM-5.3 Flash running on Chinese hardware actually means The summer of open weights How I think about reducing AI costs Watch out for cache read costs I'm (mostly) picking models on speed now, not intelligence The first known runaway AI agent - or a very bad marketing stunt? Winners and losers in the coming AI margin collapse (part 2) GLM 5.2 and the coming AI margin collapse (part 1) Expert-aware quantisation: near-Q4 quality at near-Q2 size? A brief history of KV cache compression developments xAI is looking more like a datacentre REIT than a frontier lab Is datacentre sovereignty really that important? I went on the Built for Turbulence podcast What's going on with Gemini? Managed agents are the new Lambda Open weights are quietly closing up - and that's a problem 29th August 2026: a scenario Figma's woes compound with Claude Design Has Mythos just broken the deal that kept the internet safe? What next for the compute crunch? Telnyx, LiteLLM and Axios: the supply chain crisis Using agents and Wine to move off Windows Why Claude's new 1M context length is a big deal How to use the Qwen 3.5 LLMs to OCR documents No, it doesn't cost Anthropic $5k per Claude Code user Is the AI Compute Crunch Here? Why on-device agentic AI can't keep up Using OpenCode in CI/CD for AI pull request reviews
A little tool to visualise MoE expert routing
Martin Alderson · 2026-04-13 · via Martin Alderson

I've been curious for a while about what's actually happening inside Mixture of Experts models when they generate tokens. Nearly every frontier model these days (Qwen 3.5, DeepSeek, Kimi, and almost certainly Opus and GPT-5.x) is a MoE - but it's hard to get an intuition for what "expert routing" actually looks like in practice.

So I built a small tool to visualise it: moe-viz.martinalderson.com
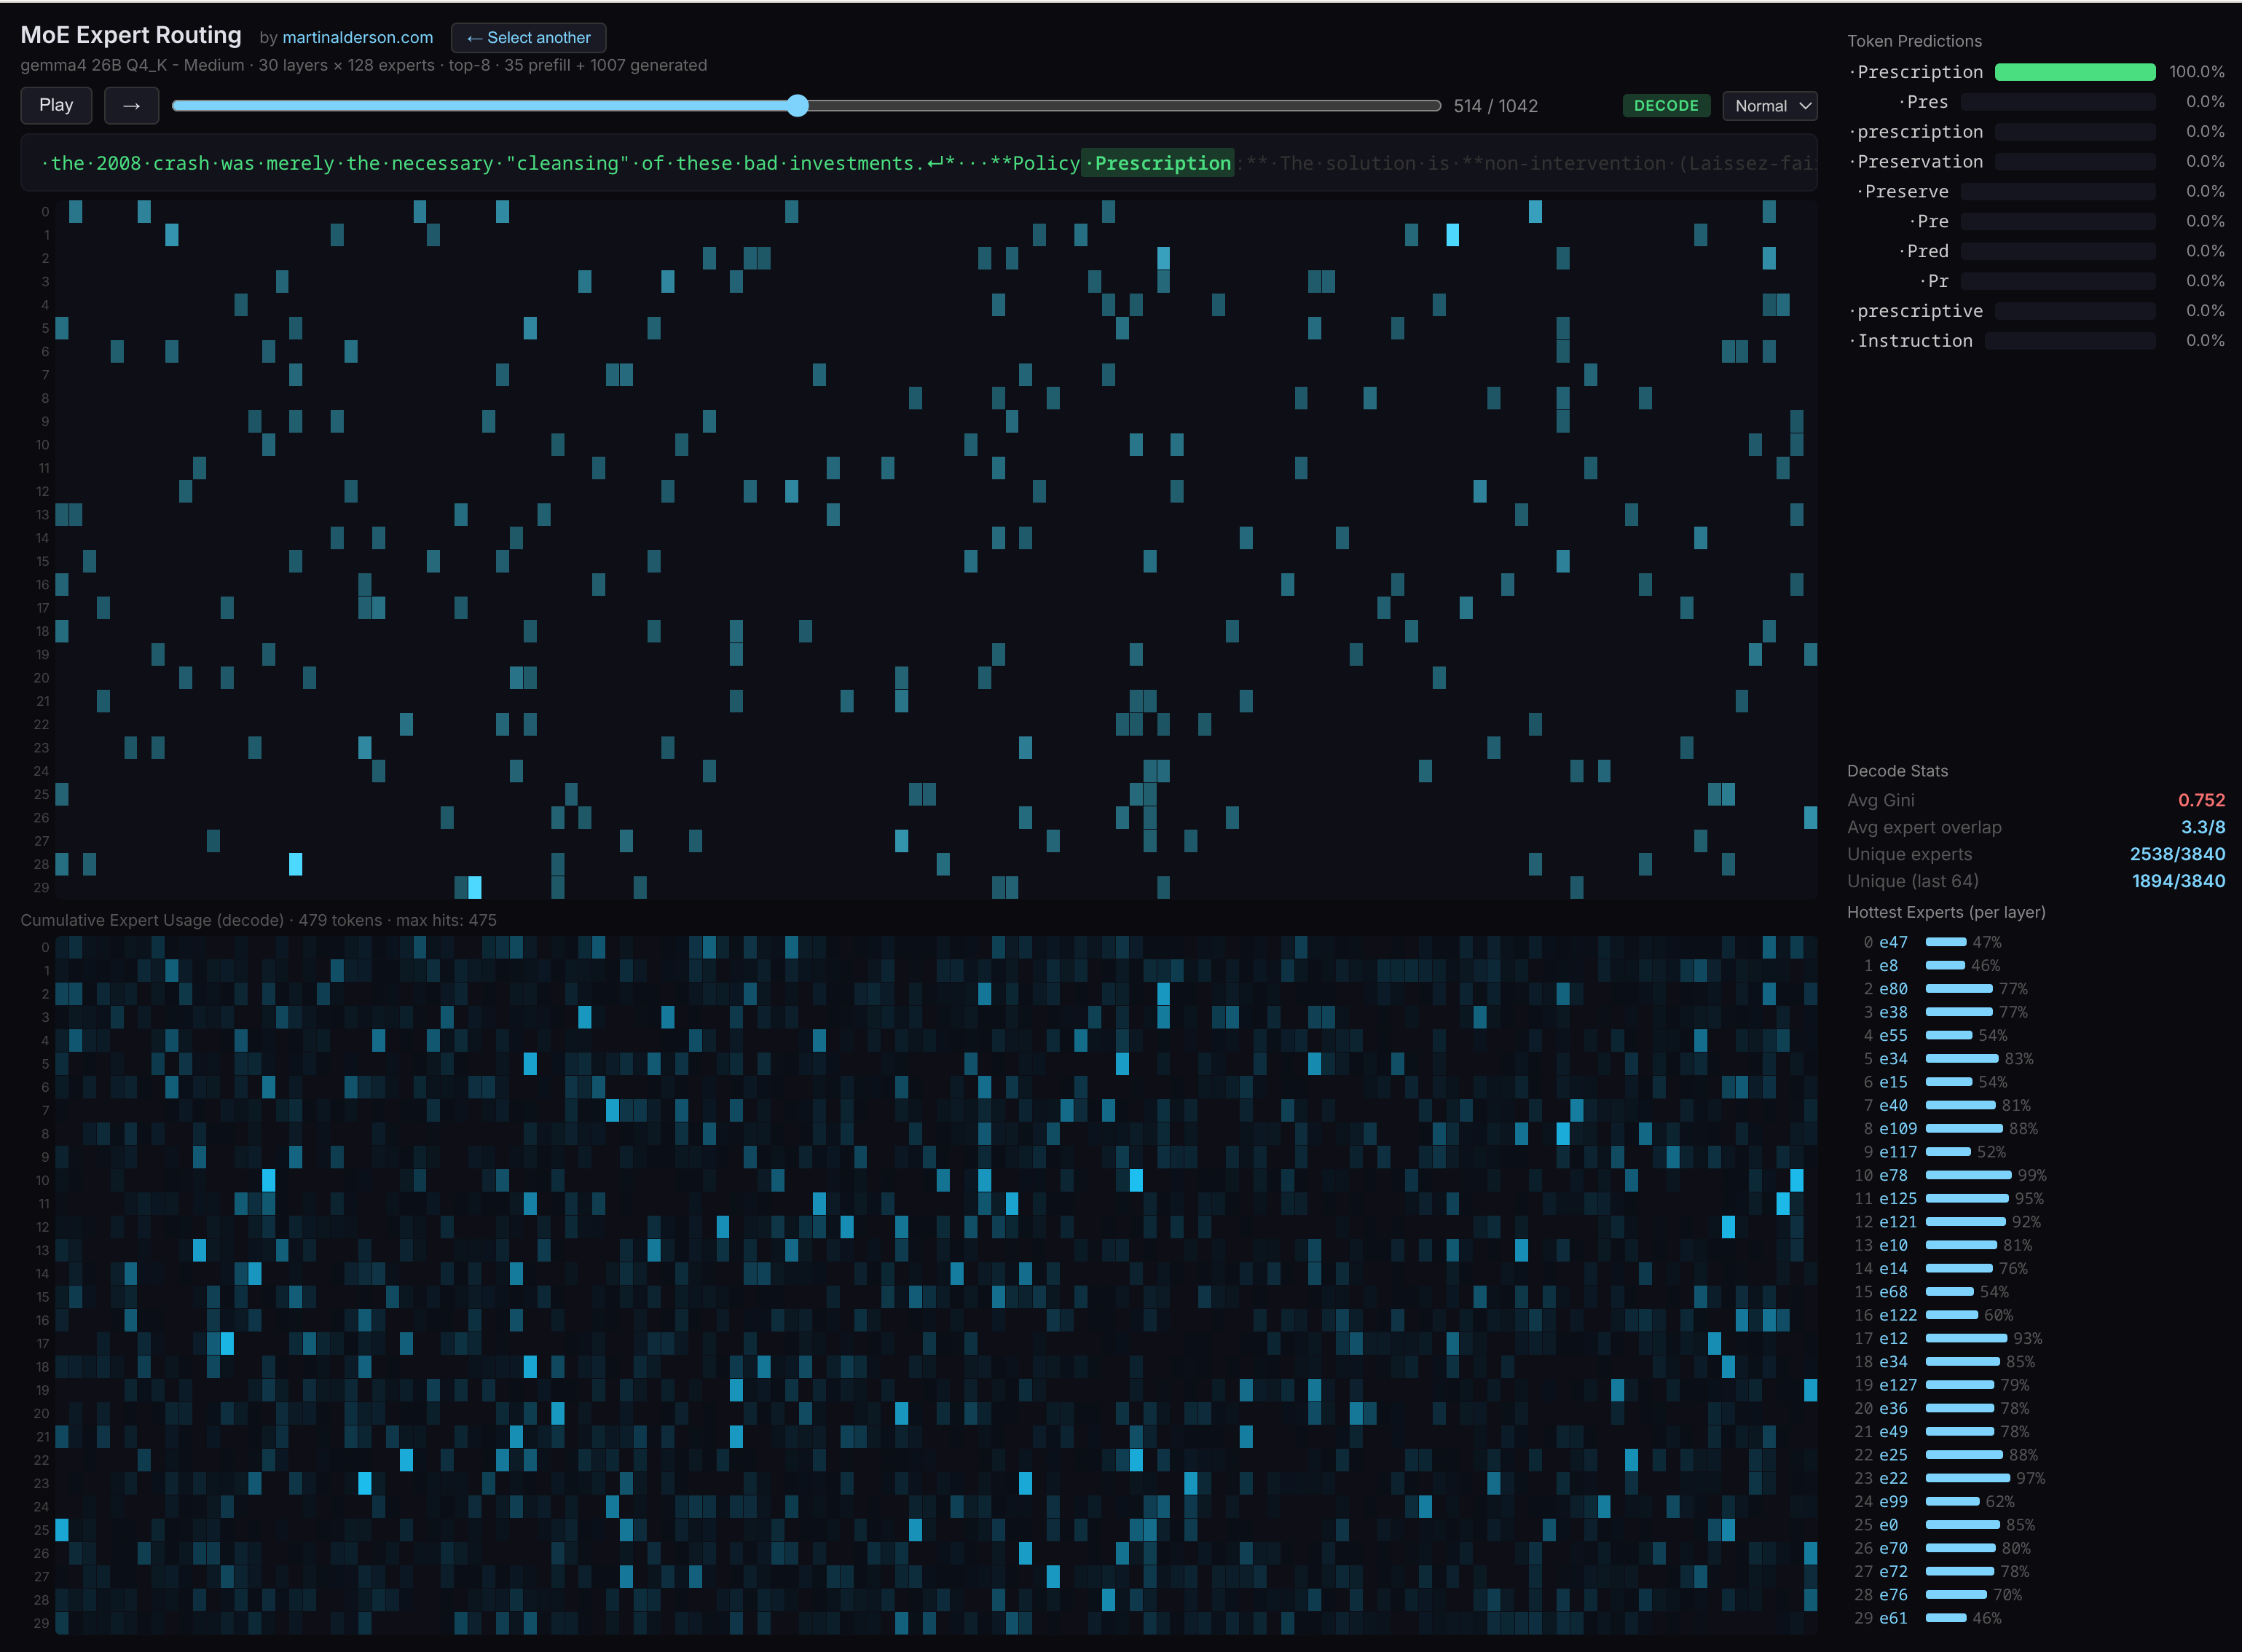
MoE Expert Routing visualisation showing token-by-token expert activation

You can pick between a few different prompts, watch the generation animate out, and see exactly which experts fire at each layer for each token. The top panel shows routing as the token is generated, the bottom panel builds up a cumulative heatmap across the whole generation.

I built this by modifying the llama.cpp codebase to output more profiling data, with Claude Code's help. So it may have serious mistakes, but it was a really fun weekend project.

The thing that really surprised me: for any given (albeit short) prompt, ~25% of experts never activate at all. But it's always a different 25% - run a different prompt and a different set of experts goes dormant.

That's a much more interesting result than I expected. Interestingly Gemma 26BA4 runs really well with the "CPU MoE" feature - 4b params is not a lot to run on a fairly fast CPU and having KV cache on GPU really helps. I think there's a lot of performance improvements that could be done with MoE inference locally as well - eg caching certain experts on GPU vs CPU.

If you're interested in learning more about LLM inference internals I'd certainly recommend pointing your favourite coding agent at the llama.cpp codebase and getting it to explain the various parts - it really helped me learn a lot.