





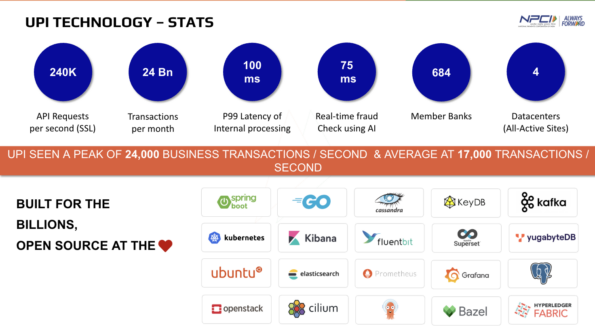
Every month, roughly 24 billion transactions worth close to ₹285 billion move through India’s Unified Payments Interface. Behind that volume sits the National Payments Corporation of India (NPCI), a not-for-profit backed by the Reserve Bank of India and the country’s banks. And behind NPCI’s infrastructure sits a stack that, by design, runs almost entirely on open source software.
Speaking at KubeCon + CloudNativeCon India, NPCI senior specialist Tittu Varghese walked through how that came to be and why NPCI treats its open source foundation as a deliberate choice rather than a cost-cutting afterthought.
From ATM switch to national infrastructure
NPCI’s story begins in 2008, when the organization was established as a national financial switch operator handling ATM transactions. The unified payments interface (UPI) launched in 2016, and its growth since has been rapid: the platform crossed its first billion monthly transactions in 2019 and has since scaled to 24 billion a month today.
“People used to ask, can we really scale a national critical infrastructure only with open source?” Varghese said. “UPI is a testament to that. We can actually operate critical infrastructure only with open source at a massive scale.”
The numbers back that up. NPCI’s systems handle close to 240,000 requests per second, guarantee P99 latency at 100 milliseconds, and run on an active-active architecture, meaning that if a transaction fails due to an NPCI-side issue, the next attempt is engineered to succeed. All of it, Varghese said, runs on an open source stack drawn largely from CNCF and Linux Foundation projects, with only a small footprint of licensed software anywhere in the system.
Built in layers, on purpose
As UPI’s volume grew, so did the fraud risk. Rather than bolt on fraud detection after the fact, NPCI built a platform approach meant to make training, inference, and data access consistent across the organization, and to avoid any single point of failure or dependency.
The stack breaks into four layers: the underlying infrastructure, a driver layer built on open source tooling and internal customization, a platform layer for standardizing how systems are operated and managed, and an ecosystem layer that handles repositories, discoverability, and metadata. That structure let NPCI onboard new use cases and machine learning models without slowing down the rest of the organization.
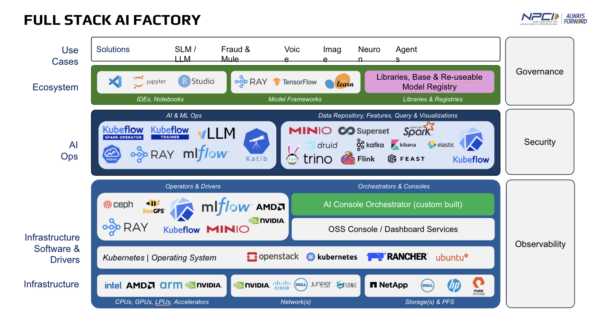
NPCI’s AI team dates back to 2019, before the current wave of enterprise AI adoption. Its fraud detection models now evaluate transactions in real time, returning a decision in roughly 20 milliseconds, either declining a transaction outright or flagging it back to the bank.
Two terabytes a day
UPI generates around two terabytes of transactional data daily, and NPCI’s approach to handling it is intentionally simple. Backend systems write into a Kafka stream, which feeds both stream and batch processing for aggregation and transformation. From there, data lands in object storage, either Ceph or MinIO, with a query layer on top. The results surface in Superset, giving product, engineering, and support teams a shared way to explore the same data without separate pipelines. The same repository extends to model lifecycles as new AI use cases come online.
From consumer to contributor
For most of its history, NPCI was, in Varghese’s words, “one of the largest consumers” of open source software, customizing existing projects to meet the scale UPI demanded. That’s shifted. NPCI has started releasing its own enhancements back to the community, including:
Varghese described the tokenization release specifically as a commitment to NPCI’s role as a piece of digital public infrastructure, something built for the country rather than for NPCI alone.
Sovereign AI infrastructure, built in the open
What Varghese’s talk makes clear is that NPCI’s open source stack is critical to UPI’s success. NCPI’s open infrastructure approach enables a fast, reliable, and low-cost payment system, built without vendor lock-in and at a scale most enterprises never approach. Now NCPI is paying the open source ecosystem back, one released project at a time.
Tags: AI, Ceph, KubeCon, KubeFlow, Kuberentes, OpenStack, vLLM

Allison is the VP of Marketing & Community at the OpenInfra Foundation (previously the OpenStack Foundation). Her mission is to continue the storytelling of the global community by building relationships with the developers, operators and ecosystem around global open source communities. In her free time, she likes to listen to Celine Dion, rank local margaritas, and travel.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。