






A Developer’s Guide to Managing Models, Cost and Quality in Microsoft Foundry
The hardest part of building AI systems today is no longer getting access to a capable model. It is knowing how to choose, validate, optimize, and operate the right model across the full lifecycle of a real application.
Take a retrieval-augmented generation (RAG)-based customer support copilot or a tool-calling agent that helps employees complete business workflows. In a prototype, it may be enough to pick a strong model, connect a few data sources, and get a useful response. In production, the system needs to retrieve the right context, call the right tools, meet quality and safety thresholds, stay within latency targets, and run at a cost the business can sustain.
Models evolve, costs shift, and production requirements often arrive after the first version is already working. Success depends less on choosing the most powerful model and more on building a disciplined operating approach around the application.
That is where Microsoft Foundry comes in: a unified platform to select, evaluate, optimize, operate, and continuously improve AI applications at production scale.
What’s new
Microsoft Foundry continues to expand the model ecosystem and operating surface for developers building production AI systems.
Fireworks AI on Microsoft Foundry is now generally available, giving developers access to production-grade open model inference through a single Azure endpoint, with enterprise service-level agreements (SLAs) and zero-setup onboarding.
Foundry is also adding new model families and capabilities across modalities, including Microsoft AI models, partner models, open-source models, custom models, and post-trained variants. Together, these updates give developers more choice while keeping selection, evaluation, deployment, and operations in one consistent workflow.
The challenge is no longer access. It is operations.
In a prototype, the questions are simple: Can the model answer the prompt? Can it connect to my data? Can it complete the happy path?
In production, the questions change. Which model fits each task? How do I validate it on my own data? What latency budget does this experience require? How much throughput do I need at peak? What happens when quota is constrained, costs spike, or a newer model becomes available? How do I monitor quality, detect eval drift, roll back safely, and prove the system is governed?
Agentic systems often fail when the model is mismatched, evaluation is incomplete, costs run unchecked, or governance arrives too late. Teams that rely on a single provider face another risk: lock-in, with no escape hatch when a model degrades, pricing changes, or capacity becomes constrained.
Foundry is built on the opposite philosophy. It is a model-agnostic platform spanning Microsoft, open-source, and independent software vendor (ISV) partner models, all on the same operating surface.
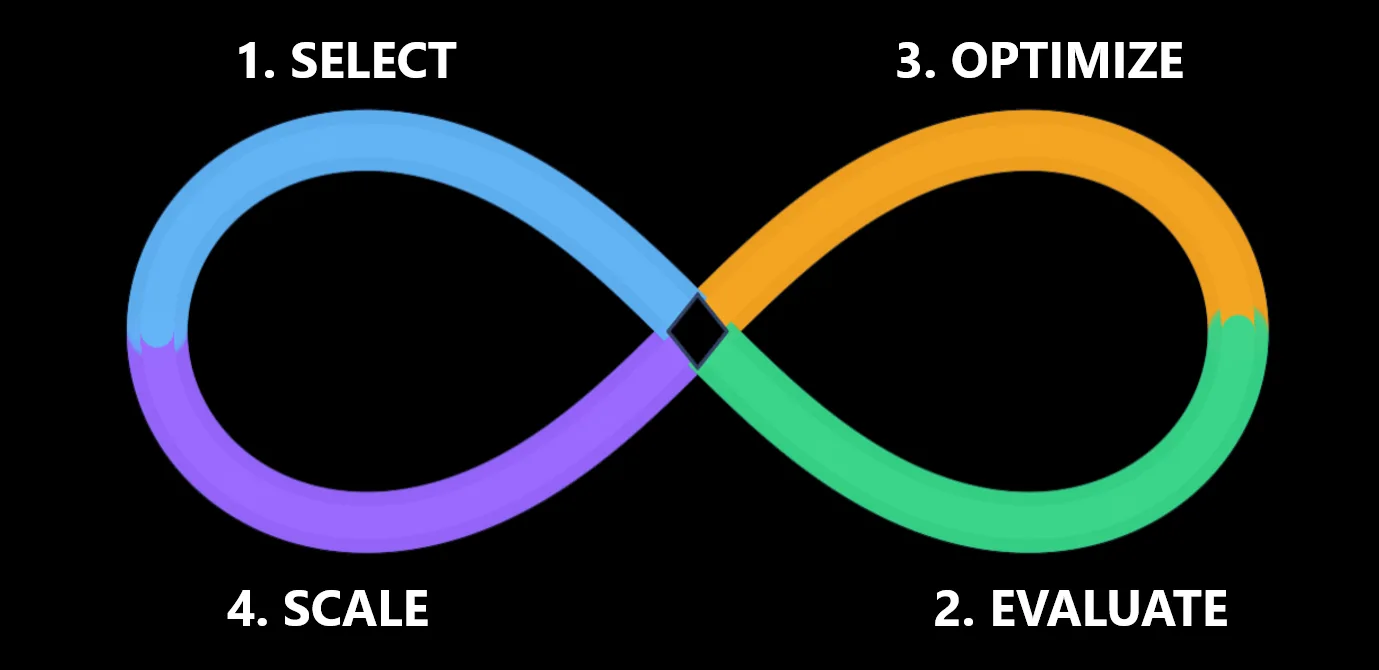
The answer is to treat model selection and optimization as a continuous operating discipline:
1. Select the right model for the task
Model selection is about workload fit, not leaderboard rank. Before choosing a model, define the task contract: what the model needs to do, what good looks like, what constraints it must operate within, and which failure modes are unacceptable.
A routing step may need low latency. A policy question may need grounded reasoning with citations. A coding agent may need deeper reasoning and tool use. A customer-facing copilot may need strong safety boundaries, predictable latency, and cost efficiency at scale.
A simple model selection framework:
| Workload need | Favor this approach | Why |
|---|---|---|
| Classification, routing, extraction, or high-volume chat | Smaller, lower-latency model | Keeps cost and latency low |
| Complex reasoning, coding, or planning | Stronger reasoning model | Improves quality for harder tasks |
| Image, speech, voice, or physical AI | Modality-specific model | Matches the model to the input and output type |
| Mixed workloads with different complexity | Model Router | Routes each request based on quality, cost, and latency |
| Domain-specific behavior, tone, or format | Fine-tuned or custom model | Improves consistency for your scenario |
Effective model choice depends on four dimensions: capability, safety, latency, and cost.
Foundry helps developers make these tradeoffs through a broad model ecosystem and a consistent operating surface. Developers can access Microsoft models, leading base models, partner models like Fireworks AI, open-source models, custom models, and post-trained variants through one selection, evaluation, and deployment workflow.
Developer tip: For developers who want to bypass manual selection, Foundry provides Model Router in Foundry Models. Model Router automatically routes each request to the most appropriate model based on workload characteristics, cost targets, and latency requirements.
2. Validate with your own evals and data
Benchmarks are not enough. A model that leads a public leaderboard may still underperform on your prompts, your data, your users, and your business rules. Production confidence comes from evaluating against the workloads your application will actually run.
With Foundry, developers can bring their own evaluation inputs, including CSV or JSONL datasets with prompts, expected outputs, labels, or ground-truth answers. They can run side-by-side comparisons across models and prompts, evaluate agents and multi-step workflows, and inspect results across datasets, traces, and production-like scenarios.
Built-in quality and safety evaluators help measure signals such as relevance, groundedness, coherence, fluency, safety, and policy adherence. Custom evaluators can capture application-specific rules, formats, and business logic.
A strong evaluation covers:
Quality: Did the model complete the task correctly? Accuracy and groundedness: Did it produce reliable answers based on the right context? Safety: Did it follow policies and avoid unacceptable responses? Performance: Did it meet latency, throughput, and reliability requirements? Cost: Did it deliver the right outcome at the right price?
Evaluation should run continuously as new model versions, fine-tuned variants, agent changes, or new model families become available.
Developer tip: Define success criteria before opening the model catalog. Criteria-first evaluation prevents anchoring on model reputation instead of workload fit.
3. Optimize cost and performance
Cost is a first-class architectural concern, not an afterthought. In prototypes, it may be acceptable to send every task to the most capable model. In production, that approach breaks down quickly.
A simple classification task, a RAG response, a long-context reasoning workflow, and a multi-step agentic process should not always use the same model or deployment strategy.
Foundry gives developers levers to optimize across quality, cost, and latency at the system level:
Intelligent routing: Send each task to the right model based on complexity and budget. Batching: Use asynchronous processing for workloads that do not require real-time responses. Caching: Avoid paying repeatedly for identical or near-identical requests. Provisioned throughput: Use dedicated capacity for predictable performance at scale. Quota management: Scale more predictably with quota tiering, global customer quota, and data zone customer quota. Model optimization: Use model compression, fine-tuning, or distillation where appropriate.
Fireworks AI on Foundry is now generally available, giving developers access to a high-performance open model catalog through a single Azure endpoint, with enterprise SLAs, no separate infrastructure, and no separate contracts.
Developer tip: Profile cost by task type before optimizing globally. Routing decisions are workload-specific, not one-size-fits-all.
4. Operate at scale with enterprise confidence
Deploying an endpoint is not the same as operating a production AI system. Teams need to understand how the system behaves, enforce policies, monitor usage and cost, test model changes safely, and roll back when quality or performance regresses.
Foundry brings these operating capabilities into one surface: versioning, SLA-backed reliability, security, governance, access controls, audit logging, usage monitoring, and controlled upgrades.
Teams can monitor token usage and throughput, inspect logs and traces, evaluate model and agent behavior, enforce policies, and compare changes before rolling them out broadly. As new model versions become available, they can test against evaluation datasets and traces, validate quality, latency, and cost impact, and reduce risk with versioning and rollback strategies.
The Fireworks AI on Foundry generally available (GA) release is a concrete example of this operating model, with enterprise SLAs, provisioned throughput unit (PTU) Data Zone support, SOC2 readiness, and the same access controls and audit logging that govern Foundry.
Production adopters span AI-native and traditional enterprise workloads, including Perplexity, Motif, UiPath, and StackBlitz. During preview, the platform processed more than 176 billion tokens across 17 S&P 500 enterprises.
Developer tip: Treat model upgrades like dependency upgrades: test against baselines, stage rollouts, monitor regressions, and keep a rollback plan.
5. Continuously improve as models and workloads evolve
AI systems are dynamic. Models improve, workloads shift, user behavior changes, pricing evolves, and new model families arrive. The best system today may not be the best system six months from now.
That is why the lifecycle loop matters:
Select the right model for the task. Evaluate it against your own data and production baselines. Optimize for quality, cost, latency, and throughput. Operate with governance, observability, and reliability. Improve as new models, tools, and customization options emerge.
For engineering teams, every model, prompt, tool, agent, or workflow change should be treated like a production change. New model versions should be tested automatically against regression datasets, production traces, and known edge cases before rollout.
A model may improve quality but increase latency, reduce cost but weaken groundedness, or perform better on common cases while regressing on high-risk scenarios. Automated evaluations help teams detect those tradeoffs early.
Developer tip: Automate your evaluation pipeline so every new model version is compared against production baselines for quality, safety, latency, throughput, and cost before deployment.
What this means for developers
The next phase of AI development will not be won by teams that simply have access to the biggest models. It will be won by teams that know how to operate models well.
That means choosing by workload fit, validating with real data, optimizing cost and performance, deploying with governance, and improving as the landscape shifts.
Microsoft Foundry is designed for exactly this reality: a model-agnostic platform spanning Microsoft, open-source, and ISV models, all on one operating surface. No lock-in. No re-architecture. No guesswork.
The future of AI development is not about guessing which model might work. It is about building an operating discipline that lets you know.