






On 26 August 2025, Citrix shipped patches for three fresh holes in its NetScaler appliances. One of them, CVE-2025-7775, let an unauthenticated attacker run code on the box outright. Normally, turning an advisory like that into a working exploit is grim, patient work. You have to understand the appliance’s memory layout, its authentication quirks, and the little undocumented behaviors that only show up after days of poking at it. Skilled people. Weeks of effort.
Not this time. Within roughly twelve hours, Check Point analysts watching underground forums caught threat actors openly comparing notes on how to point a newly released tool called HexStrike-AI at the flaw and let the AI handle the reconnaissance, exploit crafting, and payload delivery. Some claimed successful compromises and offered lists of vulnerable NetScaler instances for sale.
A job that used to eat a specialist’s week could, according to those threat actors, be kicked off in under ten minutes, against thousands of hosts at once, with every failed attempt retried in a slightly different shape until one of them landed.
This article isn’t really about that one tool, or that one hack. It’s about three things that have quietly come together and, taken as a set, undercut the economics web security has always leaned on. Cheap, powerful hardware you can own outright. Open models with their safety training peeled off. And agent frameworks that turn a chat model into something that acts on its own. None of it is science fiction. All three are on sale, on GitHub, or on Hugging Face as you read this.
For most of the last decade, the comforting part of every “AI will supercharge hacking” warning was the friction. The good models lived behind APIs, and those APIs came with abuse teams, rate limits, and refusal training. Renting enough compute to fine-tune your own model cost real money and left a trail on somebody’s cloud invoice. If you wanted a genuinely obedient, capable, private attack assistant, you had to fight for every one of those pieces.
Over about a year, all three got cheap.
On their own, each of these is a good engineering story. Stacked together, they hand one person something that used to take a team: a private, tireless pentester that never sleeps, never files an expense report, and never asks why.
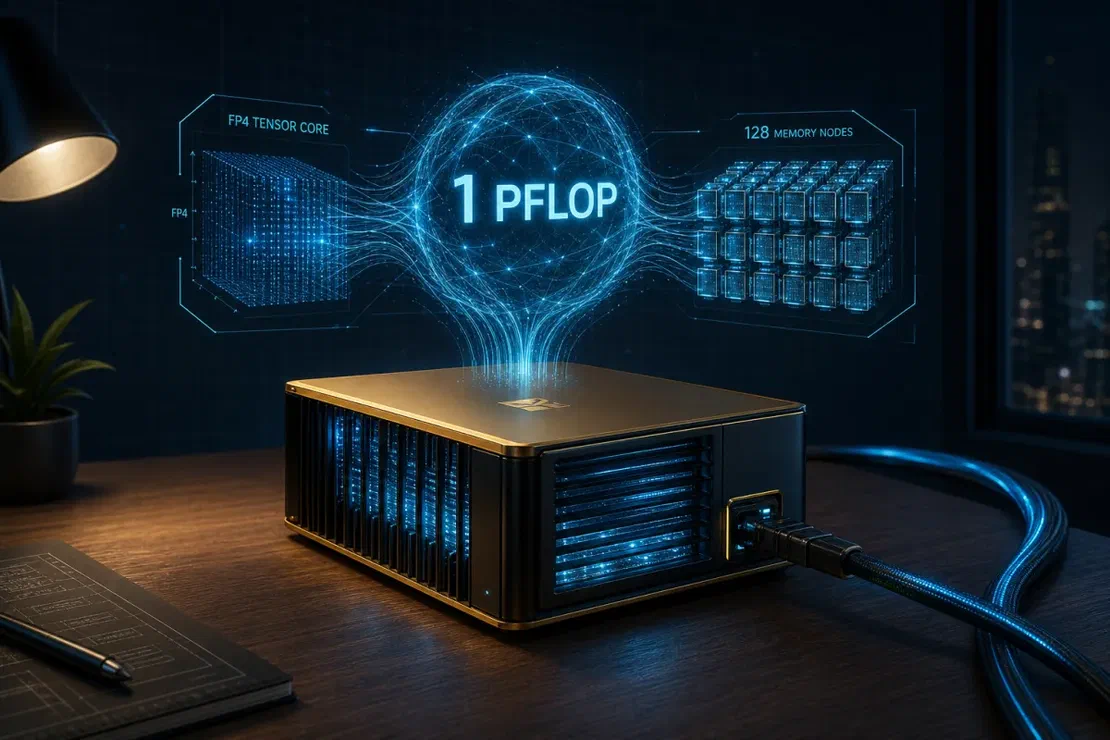
Start with the hardware, because that’s the part people tend to wave away.
NVIDIA’s DGX Spark is a small desktop system measuring 150 × 150 × 50.5 mm and weighing 1.2 kg. The GB10 Grace Blackwell superchip inside is rated for 1 petaFLOP of FP4 AI performance, with 128 GB of unified memory and a 4 TB self-encrypting SSD. It also includes ConnectX-7 networking rated at up to 200 Gbps for linking two DGX Spark systems. As of August 2026, the official price is $4,699.
The intended use is right there on NVIDIA’s product page: DGX Spark is “a complete platform for local autonomous agents,” built to “run always-on agent workloads — right from the desktop.” It can fine-tune models up to 70 billion parameters with LoRA/QLoRA, and run inference on models up to 200 billion (405B if you chain two of them). The self-encrypting drive and the ability to work fully offline are pitched as enterprise privacy features, which they are. They also happen to describe exactly what you’d want if your goal were for no cloud provider ever to see what the machine is doing.
Which is the awkward dual-use part. Everything that makes DGX Spark a great tool for a startup building a local coding assistant (privacy, autonomy, no per-token cloud bill, always-on operation) is the same thing that makes it attractive for running an offensive agent that no abuse team can throttle. The box has no opinion about which one you build.
| What the marketing says | What it also means for an attacker |
|---|---|
| Local autonomous agents, always-on | An attack agent that runs 24/7 with no API to get banned from |
| 128 GB unified memory, fine-tune up to 70B params | Enough headroom to customize a capable model on your own data |
| Self-encrypting 4 TB SSD, runs offline | No cloud logs, no invoice, nothing to subpoena |
| 1 PFLOP FP4, local inference up to 200B parameters | High local inference capacity without relying on a cloud API |
| $4,699 | A price an individual can absorb, not an organization-sized budget |
None of this means NVIDIA built a hacking machine, and it’s worth saying plainly that the overwhelming majority of people buying these are researchers and developers doing legitimate work. The point is narrower, and it’s about price. The compute that used to be the real bottleneck for private, unmonitored AI work has quietly become affordable, and “the adversary can now buy their own supercomputer” is a line that rarely shows up in a threat model.
A supercomputer is useless for this if the model running on it keeps politely declining. So the second ingredient is a model that won’t decline anything.
People get there two ways, and both have gotten easy.
The first is the criminal-branded route that’s been around since 2023: WormGPT, FraudGPT, and the long line of imitators sold on Telegram and dark-web markets. The branding alone says little about the underlying technology. Some offerings are repackaged commercial or open models with jailbreak prompts and a subscription layer rather than independently trained systems.
The second route is more interesting, and harder to stamp out, because it doesn’t rely on a prompt trick a vendor can quietly patch. It’s called abliteration.
The technique was popularized by the researcher FailSpy, building on Arditi et al.’s 2024 work, and it rests on a genuinely strange finding: in many of the aligned models the researchers studied, refusal behavior was mediated by a single, identifiable direction inside the model’s activation space. Altering that direction suppressed refusals with relatively little effect on other capabilities in their experiments, although later evaluations found measurable performance degradation. The Hugging Face write-up shows how the technique can remove refusals without conventional retraining.
What used to be a fiddly research procedure is now available as a command-line tool. Heretic automates the process with a parameter optimizer and is designed for people without a detailed understanding of transformer internals. Abliterated variants of popular open models are also widely available on Hugging Face.
Does it actually work? An April 2026 study from Alice Research ran five safety-trained models against 110 adversarial prompts. At baseline, the models complied with harmful requests 5.8% of the time. After abliteration, that jumped to 98%. Three categories, phishing, malware, and chemical weapons, hit 100%. One model that had refused every harmful prompt at baseline complied with every one afterward. The researchers argue that this makes current safety alignment a removable configuration rather than an intrinsic property of the model.
The study also stresses an important limitation: compliance is not the same as accuracy or operational usefulness. Abliteration can degrade broader model performance, and a model’s weights can be modified or realigned again. The defensible conclusion is not that the technique creates a permanently reliable attack assistant, but that refusal behavior in open-weight models cannot serve as a durable security boundary on its own.
Recommended Reading
When AI Turns Criminal: Deepfakes, Voice-Cloning & LLM Malware
A model that answers any question is still just a reference book. Dangerous, but passive. The third ingredient is what turns the book into a worker, and the industry calls it agentic orchestration.
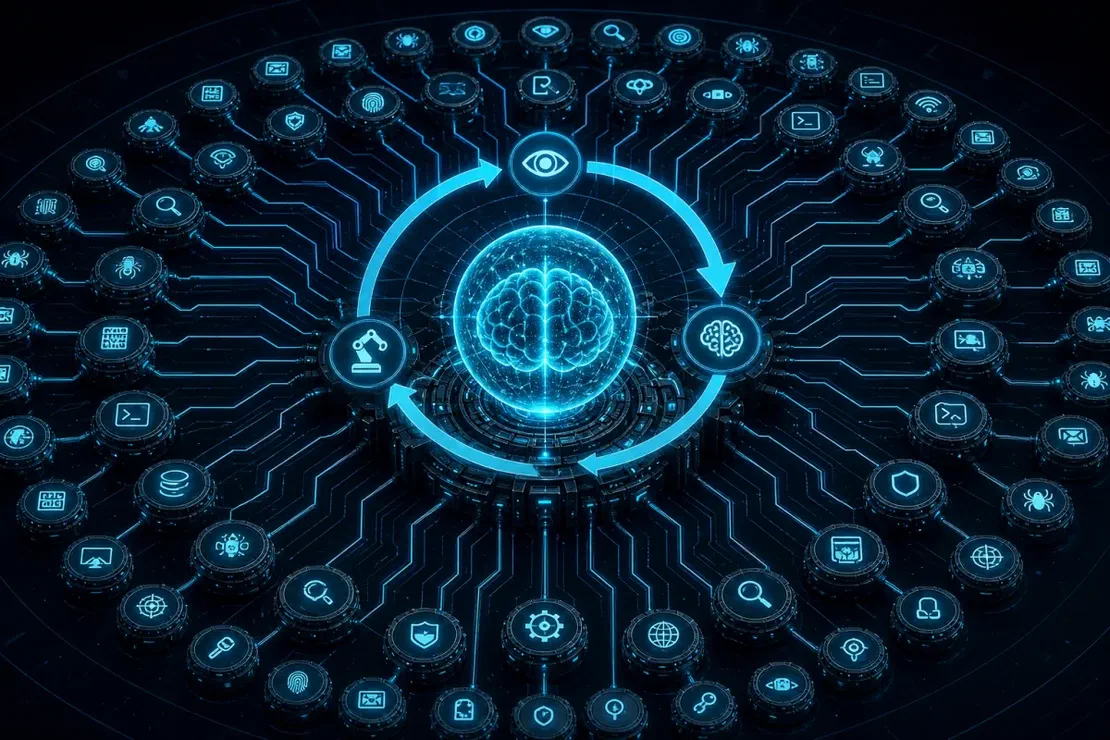
The pattern is well understood by now, mostly because defenders build the same thing for their own automation. You wrap the model in a loop: it looks at the current state, reasons about the goal, picks an action from a set of tools, runs it, reads the output, and decides what to do next. Give it the right tools and a target, and it grinds through the problem the way a junior pentester would, except in parallel and without ever getting tired.
The tools are the whole trick. The Model Context Protocol (MCP), an open standard for connecting AI applications to external systems, can link a model to business data and developer tools. It can also connect one to a port scanner, a password cracker, or an exploitation framework. HexStrike-AI, the tool from the top of this article, applies the same orchestration pattern to more than 150 security tools. According to Check Point, its abstraction layer can turn a high-level instruction into an ordered sequence of technical steps. The human supplies the intent. The machine does the craft.
That’s what changes the shape of an attack, not just its speed. Here’s how the classic kill chain maps onto an agentic system:
| Kill-chain phase | Traditional (human-led) | Agentic AI |
|---|---|---|
| Reconnaissance | Analyst runs tools, reads output by hand | Agent scans thousands of hosts, parses results itself |
| Vulnerability analysis | Manual triage against advisories | Model cross-references versions and ranks targets |
| Weaponization | Specialist writes the exploit over days | Model drafts and iterates exploit code in minutes |
| Delivery / exploitation | One target, one operator, one attempt | Thousands of parallel attempts, auto-retried on failure |
| Persistence / exfiltration | Hands on keyboard | Agent drops web shells, harvests, reports back |
The underlying MITRE ATT&CK techniques barely move: T1595 (Active Scanning), T1190 (Exploit Public-Facing Application), T1059 (Command and Scripting Interpreter), T1505.003 (Web Shell). The techniques are old news. What’s new is that one operator can now run all of them, everywhere, simultaneously.
If any of this still feels theoretical, November 2025 settled the argument.
That month Anthropic published a report titled Disrupting the first reported AI-orchestrated cyber espionage campaign. Back in mid-September, its team had spotted a campaign that it attributes with high confidence to a Chinese state-sponsored group it calls GTG-1002. Anthropic describes it as the first reported large-scale intrusion carried out mostly by AI rather than merely with its help.
The operators built a framework around Claude Code and MCP-connected pentest tools, then aimed it at around thirty targets: tech companies, banks, chemical manufacturers, government agencies. The AI did the reconnaissance, vulnerability discovery, exploit code, credential harvesting, lateral movement, and data triage. Anthropic estimates it handled 80–90% of the tactical work on its own, with humans stepping in at maybe four to six decision points per campaign to approve an exploit, sign off on using stolen credentials, or pick what to exfiltrate. At its peak, the system was firing off thousands of requests, several per second, which the report drily notes would have been “simply impossible” for human hackers.
Two things in that report are worth dwelling on, because they show where the pressure is heading.
The first is how they got past the safety training, and it’s almost anticlimactic: they didn’t bother with abliteration at all. They told the model it was an employee of a legitimate cybersecurity firm conducting authorized defensive tests, then sliced the attack into small, individually harmless-looking tasks so that no single request revealed the full malicious operation. Plain role-play plus task decomposition was enough to march a frontier, heavily aligned model through its own guardrails. Now picture the same framework driving a model that has no such refusal behavior, on a box nobody else can see.
The second is that hallucination remained a significant obstacle. Claude sometimes claimed to have found credentials that did not work or treated public information as a critical discovery, so the human operators still had to verify its output. That limited the system’s reliability, but Anthropic’s report does not establish how many targets it protected or whether future models will improve at a predictable rate.
And here’s what should genuinely unsettle defenders: the same machinery is already winning at the legitimate version of this game.
In June 2025, an autonomous AI pentester called XBOW climbed to number one on HackerOne’s US leaderboard, ranking above thousands of human researchers by reputation, a first in bug-bounty history. XBOW reported nearly 1,060 submissions, including remote code execution, SQL injection, SSRF, XSS, path traversal, and exposed secrets; hundreds had already been triaged or resolved when the company published its results. Its findings included a previously unknown flaw in Palo Alto’s GlobalProtect VPN that XBOW said affected more than 2,000 hosts. According to the company, the system can map an attack surface, chain bugs together, and confirm exploitability, completing a broad assessment in hours.
XBOW is a legitimate, well-funded company that follows HackerOne’s rules and puts a human reviewer in front of every submission. That’s not the point. The point is that the capability demonstrably exists in production and has been benchmarked publicly against human researchers. Automated agents are particularly well suited to vulnerabilities that can be tested and confirmed programmatically, including injection flaws, misconfigurations, leaked secrets, and some forms of broken access control.
So what actually separates XBOW from a weaponized implementation? Not one technical component, but governance: authorization, defined scope, human oversight, disclosure rules, and accountability for the outcome.
Recommended Reading
AI-Driven Attack Surface Discovery
Web security has always run on a few quiet economic assumptions. Attacker attention is finite. Skilled exploit development is expensive and rare. There’s usually a comfortable lag between a bug being disclosed and it being weaponized at scale, and that lag is your patching window. Small and mid-sized sites mostly survive because no human attacker can be bothered to look at them one by one; they hide in the sheer noise of the internet.
Automated, uncensored, self-hosted AI attacks eat away at every one of those assumptions at the same time.
Our whole security posture is tuned for a world where mounting a competent, sustained, multi-target attack is genuinely hard. Put these three ingredients together, and it gets easy, and, just as importantly, it gets private. There’s no cloud provider in the loop to notice, no API key to pull, no invoice to trace back to anyone.
Recommended Reading
When Patches Fail: An Analysis of Patch Bypass and Incomplete Security
Doom isn’t a strategy, and there are real responses here. Most of them boil down to accepting that you’re now up against a machine, and matching its tempo instead of your own.
There’s nothing exotic on that list. It’s the discipline the industry has preached for years, just executed at a tempo most shops haven’t actually reached. And the gap between “best practice on a slide” and “actually automated in production” is exactly the gap these attacks are built to walk through.
It’s tempting, after all that, to reach for the usual reassurance on the way out. The models still hallucinate. XBOW still needs a human reviewer. GTG-1002 still needed an operator at the key moments. We still have time. All of that is true today, and none of it is a property of the technology. It’s a snapshot of one moment on a curve that’s bending the wrong way.
The blunt version is shorter. The compute that used to gate private, powerful AI now sits on a desk and costs less than a used car. Safety training on open models can be modified after release, and command-line tools have made removing refusal behavior much easier. The orchestration layer that turns a model into an autonomous operator is mature enough that attackers and defenders are building it from many of the same open-source parts.
For thirty years, web security quietly relied on the fact that a capable, sustained, private attacker was rare and expensive. That’s the assumption that just broke. The right response isn’t panic, and it definitely isn’t pretending the parts aren’t already sitting on the shelf. It’s to internalize that the adversary now scales like software, and to make sure your defenses do too, before the curve finishes bending.

I can show you how deep the Internet really goes
Discover exposed assets, infrastructure links, and threat surfaces across the global Internet.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。