







Even with the new closed model successes of Grok and Sonnet 3.7, DeepSeek R1 is still considered a heavyweight in the LLM arena as a whole, and remains the uncontested open-source LLM champion (at least until DeepSeek R2 launches, anyway.) We've written before about the concerns of using a closed-source LLM if you are working with sensitive data, and it's unlikely those concerns over data usage and transmission will ever truly disappear in the AI world as we know it today. Data crossing borders may fall under different legal frameworks, and you can't fully audit what happens to your data on closed platform; it can become a challenge to provide evidence of data handling practices to regulators.
DeepSeek's large model size means it has been something of a challenge to host, however, compared to simply signing up for a paid closed model service. Thanks to the magic of quantization, though, you can now run a Q4 4-bit quantization on Runpod through a one-click template deploy which will spin up a pod running KoboldCPP, and between download and loading should get you up and running in approximately 20 minutes. This will only cost $10/hr in Secure Cloud on 6xA100s or $16/hr on 4xH200s.
To get started, you can go to our Template hub or deploy a pod, search for KoboldCpp - DeepSeek-R1 - 6x80GB of VRAM, and deploy on a pod configuration with at least 480GB of VRAM. This will set up an OpenAI-compatible endpoint on port 5001 in the pod that you can then send API requests to. (Note that community templates can have bugs or unintended operation - use with caution!)
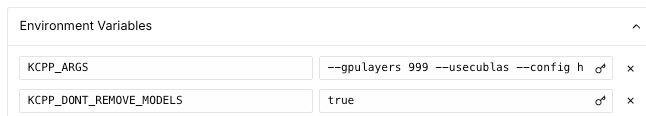
If you'd like an alternate template for this package, you can try the official KoboldCPP package and setting up the download in the environment variables on your own. Here is the model quantization by Bartowski, and here is a guide to set up the template parameters.
Want to run it on even less hardware? Can do - you can offload some of the work to the system RAM in the pod. Change the --gpulayers argument in the environment variable to something below 61, which will start pushing the layers off of the GPU. Note that this will result in a sizable performance hit, but may be preferable for some use cases since you could run the model on even less of 480GB of VRAM and drop some cards from your system requirements.
As a reminder, here are the official suggested sampler and prompting settings:
While waiting for the next iteration of the model (practically an inevitability, given the success of R1) DeepSeek has open-sourced five repos on GitHub for Open Source Week. Here's a quick roundup:
DeepSeek's FlashMLA is a significant open-source contribution that addresses a critical performance bottleneck in LLM deployment. It's specifically designed to handle variable-length sequences efficiently during model inference. FlashMLA builds upon innovations from FlashAttention 2 & 3 and CUTLASS projects, but extends them specifically for MLA decoding which is becoming increasingly important for efficient LLM inference (especially given the sheer size of the largest open source models; Llama-3 having a 405b variant and R1 having 671b parameters would have been absolutely unthinkable just a year or two ago. BLOOM having 176b was considered an extreme anomaly back then!)
Mixture of Experts models (like R1) are becoming essential for scaling AI capabilities beyond traditional dense models, but they've been bottlenecked by communication overhead. DeepEP directly addresses this limitation.
DeepEP is a specialized communication library designed for MoE architectures and expert parallelism. It provides high-performance GPU kernels for the critical "all-to-all" communication pattern that MoE models require when routing tokens to their appropriate experts. The library achieves near-theoretical maximum performance on both NVLink (~158 GB/s) and RDMA (~47 GB/s) connections, meaning it's extracting nearly all available performance from the hardware.
DeepSeek's DeepGEMM library represents a significant contribution to the AI infrastructure ecosystem by addressing the critical performance bottleneck of matrix multiplications, particularly for FP8 precision operations. The benchmarks are impressive, showing up to 2.7x speedups over existing carefully-optimized CUTLASS implementations, with some configurations reaching 1358 TFLOPS on NVIDIA Hopper GPUs.
DualPipe introduces a novel bidirectional pipeline parallelism algorithm that significantly improves distributed training efficiency by fully overlapping computation and communication phases between forward and backward passes. While lightweight in code, it demonstrates a significant architectural innovation that could influence how large language models are trained in distributed environments.
EPLB addresses a critical challenge in scaling MoE models, which are becoming increasingly important for achieving state-of-the-art performance while managing computational costs. While lightweight in code, it demonstrates a significant architectural innovation that could influence how large language models are trained in distributed environments.
The Fire-Flyer File System (3FS) from represents a significant contribution to AI infrastructure, addressing one of the most critical but often overlooked components: storage. It bridges traditional file system interfaces with modern hardware capabilities, leveraging advanced SSD storage and high-speed RDMA networking to create a cohesive, efficient storage layer. One of the biggest challenges in a serverless setup is how do you load a huge LLM like R1 responsively enough to avoid long cold starts? Moving all that data takes time, and by the time you even catch wind of a request, the user is already waiting. In large scale testing this system achieved 6.6 TiB - enough to completely move R1 in well under a second.
The team at DeepSeek is clearly cooking some new innovations beyond releasing one of the most notable LLMs in history - and many of them help address the challenges involved moving the data required for such a large model. We'll keep you posted on any new updates on their new model!
Author profile: Brendan McKeag
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。