








The industry is now racing to rebuild source code management for agents. We showed our answer at GitLab Transcend, but let’s reiterate why rebuilding the Git backend is only half the problem.
Three things break when agents become the primary users of a Git server. Every developer running hundreds of agents hits the same wall, regardless of tools:
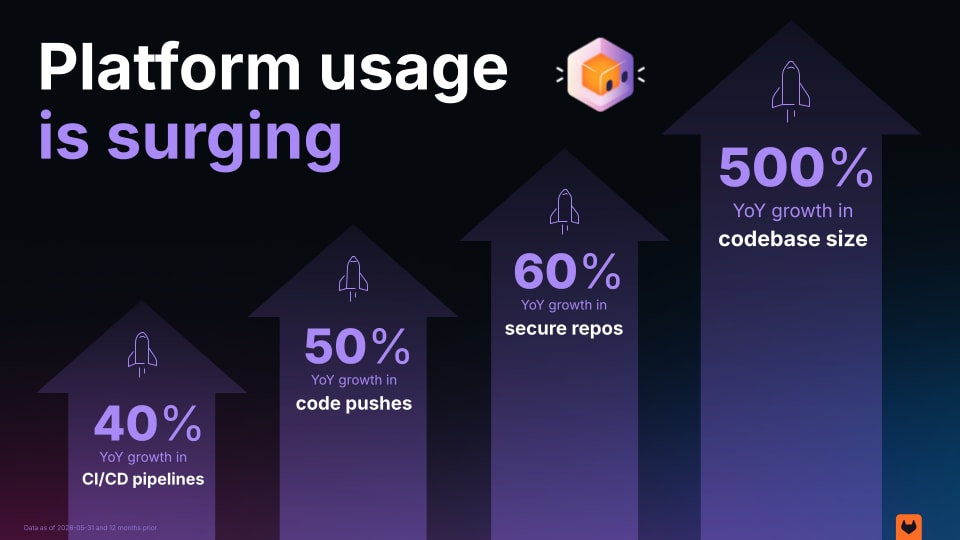
Our platform data shows how fast the pressure is building. Over the past year, our customers created 40% more CI/CD pipelines, and code pushes to GitLab.com were up 50%. While the secure repositories grew by 60%, codebase sizes have also grown by up to 500%.
When we announced next-generation source code management (next-gen SCM) at GitLab Transcend in June, we walked through how Git, as an operational model, was not designed for the load agents placed on it. A few weeks later, new entrants, including Git hosts built specifically for agent-scale concurrency, are validating that claim independently. That convergence sharpens why rebuilding the Git backend is necessary, but on its own, it’s still not enough.
Next-gen SCM runs on the Git protocol for backward compatibility, with a redesigned backend and interfaces built for agents. Instead of cloning a full working tree, agents query the repository server-side for exactly what a task requires, with each agent limited to the minimum visibility its task needs. It’s the same Git compatibility and auditability with a different motor underneath.
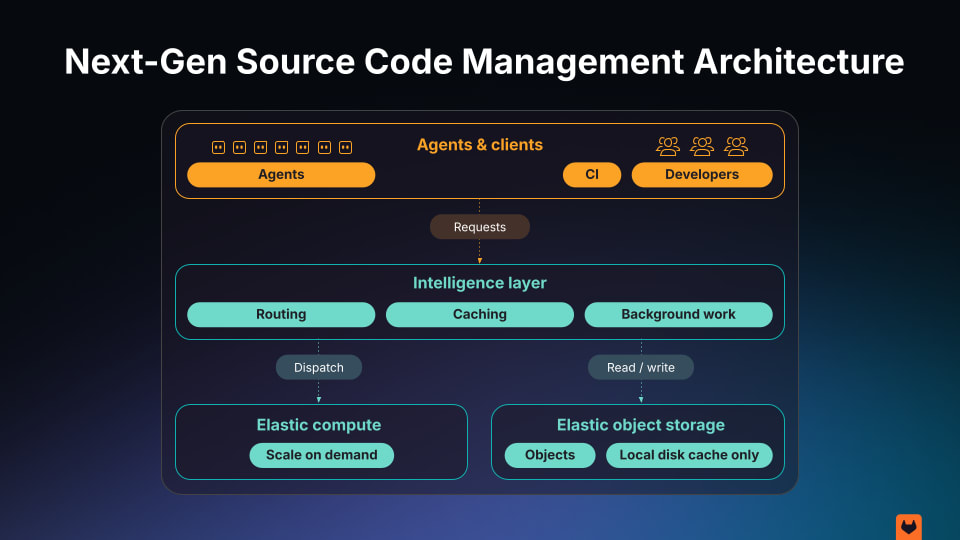
The architecture separates an intelligence layer (routing, caching, background work) from elastic compute that scales on demand and elastic object storage. Purpose-built read and write APIs let agents retrieve file, blame, and history data and commit changes without pulling the whole repository. Developers can run agents on any repo, fan them out by the thousands, and let them experiment safely. In practice, that means an agent gets a single batch-read instead of a full clone, a diff-stat request instead of clone-then-diff, and a last-commit-for-path lookup instead of clone-then-blame.
This isn't designed for cloud-only. The compute and storage tiers talk to each other over the standard S3 API, so the same architecture that runs on GitLab.com runs on a customer's own infrastructure, whether that's a major cloud provider's object storage or a self-hosted, S3-compatible system running in a customer's own data center. For air-gapped, regulated, and sovereignty-constrained environments, that means the same horizontal scaling and consistency guarantees, without repository data ever leaving infrastructure the customer controls.
In early internal testing, agents running against next-gen SCM showed:
These are ceilings, not guarantees, measured under our own testing conditions. The workload that actually stresses a Git backend at agent scale is concurrent reads and writes from many independent agents against the same repositories, sustained under load — so a number only means something if the test runs close to that target, the load generator isn't the bottleneck, and the full latency distribution is reported rather than a single best case.
We hold our own results to that bar, and we'd encourage anyone evaluating this category to ask the same three questions of every number they're shown, including ours. That bar is built into the architecture itself, not only our test conditions. Storage maintenance compacts small artifacts into larger, frozen ones on a geometric schedule, which puts a hard ceiling on how much data any node has to fetch to catch up to the latest snapshot. With a 1GB freeze threshold and a 2x compaction ratio, that ceiling is 2GB, regardless of how large the repository has grown.
Next-generation source code management is now in private beta, and here it is in action:
The new entrants are building Git hosts: standalone destinations, or fast mirrors that sit in front of an existing host to absorb read traffic. That solves concurrency, and concurrency is a real problem. But it leaves two questions unanswered, and both are central to how we think about GitLab’s agentic infrastructure.
The first is provenance. When agents push code, touch dependencies, and trigger deployments by the hundreds, the operative question stops being “did we scan?” and becomes “which agent did what, under which policy, and can we prove it?” Our agent APIs attribute every agent action to a specific workflow, model, and token. Every agent operation is routed through the same project authorization and role-scoped human-in-the-loop controls that already govern human contributors. Attribution and policy are platform properties, not repository features, so a standalone Git host isn't built to answer this natively.
The second is what happens to the work after it succeeds. A successful agent experiment lives on a standalone host. On GitLab, next-gen SCM is a Git backend inside a platform that already runs CI, policy management, governance controls, and audit of the resulting code. When an agent's ephemeral experiment works, it graduates directly into a governed, observable production pipeline, without requiring a separate platform or destination.
Next-gen SCM handles execution at agent scale. GitLab Orbit gives every agent and human context on the full software lifecycle as a knowledge graph, and GitLab Duo Agent Platform orchestrates governance and security around every agent action — so agents plan and carry out work across the full lifecycle, not just the Git operations. A faster Git backend hosts the code agents generate. Paired with GitLab's governance, lifecycle context, and orchestration, that code ships through the same CI, policy, and audit path as everything else in the platform.
Every customer will use agents for coding, and every customer running them at scale will run into the same limits described above, regardless of which models or tools they standardize on. That's what makes this an evolution within the infrastructure layer. The teams that move fastest in the agentic era will be the ones who can host, govern, and absorb agent output back into a lifecycle that was already built to ship trusted software.
Next-generation source code management is in private beta. Request early access today!
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。