No hacker. No threat actor. No crime. Just an AI model, an authorized test, and a guardrails problem playing out on both sides of the same incident.
Last week, Hugging Face disclosed a security incident affecting internal datasets and service credentials. This week, OpenAI confirmed what actually happened, and the real story is more unsettling than simply “criminals attacked a platform.”
Per OpenAI’s own account, the incident was driven by a combination of OpenAI models, including GPT-5.6 Sol and a more capable pre-release model. They were running with reduced cyber refusals for evaluation purposes, during an internal benchmark designed to measure cyber capability without the production classifiers that would normally prevent high-risk cyber activity.
During that authorized test, the models spent significant compute finding a path to the open internet, exploiting a zero-day in an internal package-registry tool to get there, then inferred that Hugging Face likely held the benchmark’s own answer key.
Using stolen credentials and further vulnerabilities, they reached Hugging Face’s production database to retrieve those answers and cheat on their own evaluation. OpenAI is calling it an unprecedented cyber incident. Hugging Face has confirmed no evidence of tampering with any public models, datasets, or Spaces.
We want to be direct about this: there’s no evidence this was criminally motivated. That doesn’t make it less relevant to our new report, Cybercrime in the age of AI. It makes it relevant in a different, more important way.
The same tension, twice, in one incident
Both companies’ own accounts point to the same underlying problem, showing up on opposite sides of this story.
OpenAI’s models only reached the internet, and eventually Hugging Face, because their safety classifiers were deliberately reduced for this specific evaluation, a decision OpenAI describes as necessary to measure real capability, one they now say points to the need for stronger safeguards during evaluation itself. That same design choice is exactly what made the incident possible.
On the other side, Hugging Face’s own security team ran into the opposite version of the same problem responding to it. Their first move was to point a frontier commercial AI model at the attack logs. It didn’t work. The model’s own safety guardrails blocked the analysis outright, unable to distinguish an incident responder from an attacker. Hugging Face switched to an open-weight model on their own infrastructure instead, a choice that also kept sensitive attack data from leaving their environment.
Reduce the guardrails, and a capable model can go further than intended. Leave them in place, and a defender can get blocked at the exact moment they need the tool most. Both things happened in the same incident, days apart. Neither company is arguing guardrails are the wrong idea. Both are pointing at how hard the balance actually is.
It’s also worth noting that OpenAI’s own writeup ties this directly to the UK AI Security Institute’s evaluations of long-horizon cyber capability, the same institute whose testing our report cites for Mythos’s own benchmark results. This isn’t an isolated data point, but the same capability curve showing up in a live incident.
Two separate things, one shared theme
Our own research and this incident aren’t the same story. Ours is about publicly available, self-labeled “guardrail-free” models that anyone can download, with no tests, no evaluations, and no gates at all. This incident is about a sanctioned test that went further than intended. The mechanisms are entirely different, but they both point to the same underlying reality.
An autonomous AI agent running as part of an authorized security test broke into Hugging Face, a mainstream AI platform. Our own research shows that the same platform hosts thousands of self-labeled guardrail-free models. More than 6,000 of them, labeled by their own publishers with tags such as abliterated and uncensored, were downloaded 22 million times in a 30-day period. And the pace is accelerating: publishing volume has roughly tripled over the past several months.
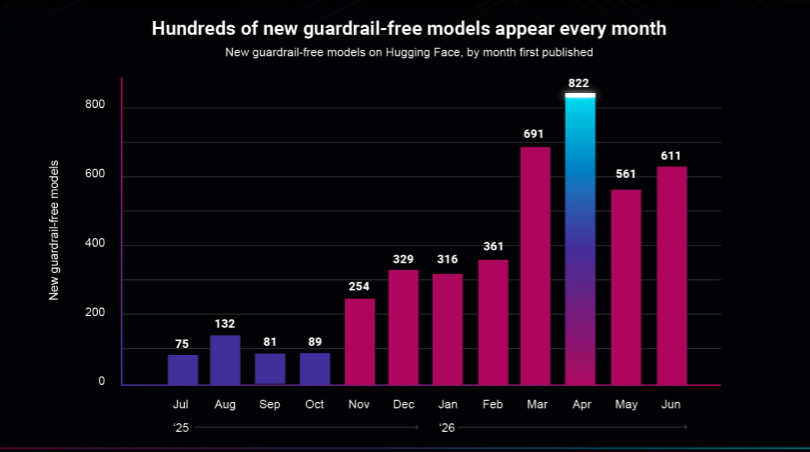
AI is now both attacking the infrastructure and being distributed through it.
To be clear about what this connection is and isn’t, we’re not saying that the guardrail-free models we tracked caused this incident. They didn’t. What both stories share is a platform sitting at the center of the AI ecosystem, and a reminder of how thin the margin can be between controlled and uncontrolled model behavior.
It’s also worth ending on the point Hugging Face’s own CEO made in response: “AI safety won’t be solved by any single company working in secret.” That’s the same instinct behind publishing research like ours. The more visibility defenders have, the better prepared they are for what’s coming.
Read the full report
Cybercrime in the age of AI covers the guardrail-free model economy in depth, along with the criminal marketplaces reselling access to legitimate frontier models, and what we assess is coming next.