







Every day, Meta’s recommendation platforms handle billions of user interactions, generating rich temporal signals that capture individual preferences and intent across products, ads, and content. In our 2024 post on sequence learning for ads recommendations, we showed how modeling the order and timing of user actions (rather than relying on static, manually engineered sparse features) produces richer, sequence-aware representations of user interests and ad preferences.
This post goes a step further, introducing two architectural breakthroughs that let us scale sequence learning advancements from foundational innovations into a production platform with predictable, LLM-style scaling laws: (1) a multi-stage sequence model that decouples heavy offline user modeling from lightweight online ranking tasks and (2) a learning technique based on dense tokenization and target-aware attention that efficiently learns feature interactions directly from data.
Together with our broader model innovations, these advancements have contributed to a cumulative lift of 6% in conversions on Instagram, 3% in conversions on Facebook and 3.5% in ad clicks on Facebook. This unified platform for sequence modeling is a core component of Meta’s Generative Ads Recommendation Model (GEM), helps to harness the comprehensive user behavioral understanding of this learning paradigm to maximize the benefit to advertisers.
Ads recommendation systems must retrieve and rank thousands of ads within milliseconds, processing millions of candidates per second. To manage this scale, some approaches to sequence models rely on hybrid model configurations where a specific model processes user event sequences and another model handles sparse feature interactions.
While effective at meeting production demands, this hybrid approach has potential tradeoffs:
Scaling both temporal sequence lengths and the transformer models that process them can turn the tradeoffs of the hybrid approach into a bottleneck, limiting the ability to improve the ads experience of users and the performance of advertisers’ campaigns.
We’ve made two fundamental architectural breakthroughs in sequence learning that resolve the core tension between model complexity and serving efficiency: (1) a multi-stage sequence model that decouples offline user modeling from online ranking and (2) a dense tokenization with target-aware attention learning paradigm. Together, they provide a flexible production strategy that helps generalize sequence learning models and establish an LLM-style scaling law that predictably balances model performance with compute.
To address scaling efficiency, a multi-stage model has been developed that enables scaling of a transformer-based sequence model in a compute efficient manner. Separating the sequence model into two complementary stages (upstream/offline user modeling and downstream/online ranking), enables model capacity to scale so that performance keeps improving without proportional increases in serving resources.
In Figure 1, the left panel shows the offline user model. It processes long user histories asynchronously and produces cached embeddings that capture deep behavioral patterns. The right panel shows the online ranking model that combines these cached representations with real time ad candidate signals to produce the final ranking. The arrow between the two stages carries the user feature embeddings from offline → online ranking models.
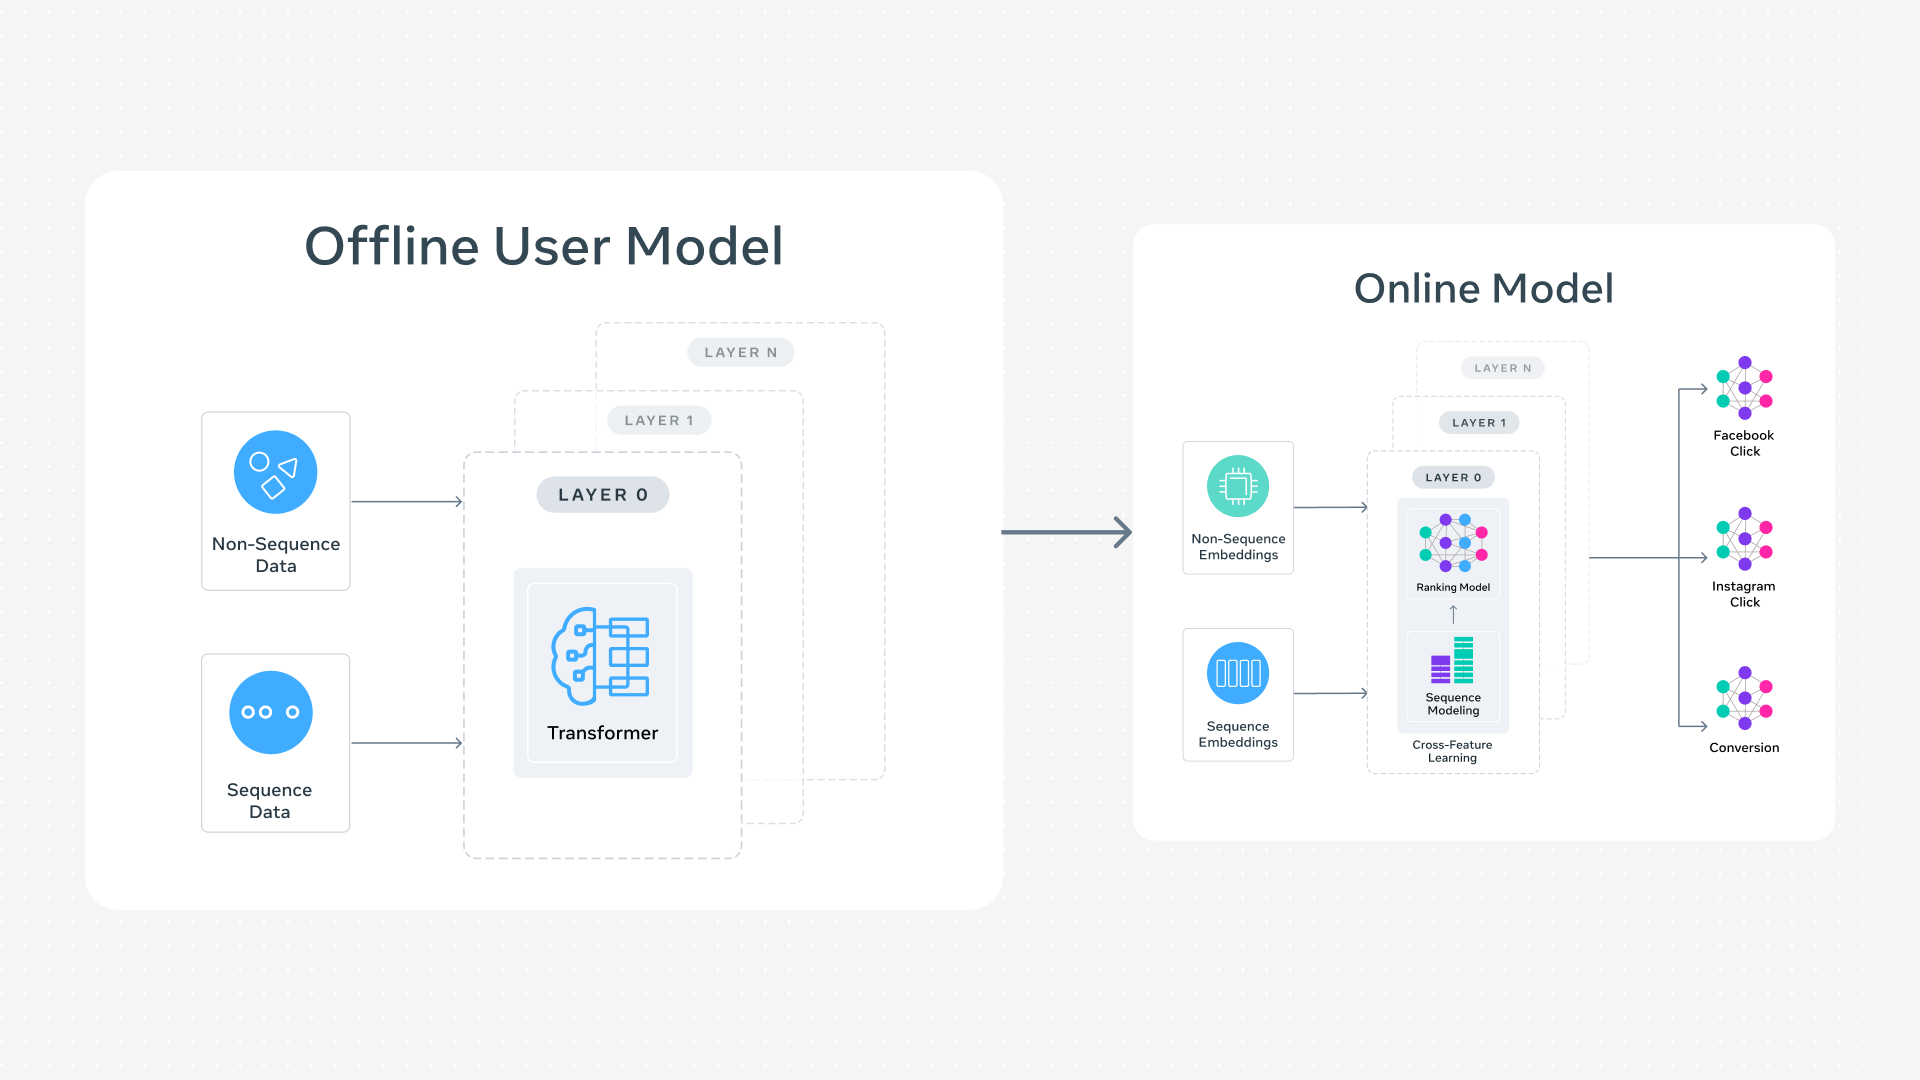
User-side features are processed asynchronously using deep transformer upstream models. These models scale to several transformer layers with sequence lengths in the thousands and generate embeddings that are precomputed and cached at the user level. The upstream model strictly separates user features from ad and context features to ensure user embeddings remain independent of any particular ad candidate.
The offline user model representations are complemented with online ranking models that use fresh user signals and ad candidate information for real time ranking. This stage is optimized for speed, meeting strict latency budgets while leveraging the deep representations computed offline.
Separating the sequence modeling system into two distinct, yet complementary, stages enables an increase in model complexity along a scaling curve for the Offline User Model without causing a spike in serving costs for the Online Ranking Models.
This tokenization approach integrates sparse features with sequential behavioral data into a single dense vocabulary, enabling attention mechanisms to discover interactions independently. Unlike traditional recommendation systems, which rely on manually engineered representations to capture sparse cross-feature interactions, this approach lets the model learn those interactions directly from the data.
Tokenized sparse features and ad candidate information are fused with user behavior sequences, then processed by a memory-efficient form of multi-head attention that lets each layer weigh a user’s past behaviors against the specific ad being scored. Stacking multiple aligned attention blocks with stable attention distributions allows each layer to capture higher-order interactions between the target ad and the user’s historical behavior, progressively distilling long sequences into compact representations.
When running on real-world ads traffic, the multi-stage sequence model demonstrates the emergence of predictable scaling laws for ads recommendations that are analogous to those observed in large language models. Performance improvements follow a log-linear relationship with respect to compute, with a marked improvement in scaling efficiency over other transformer-based sequence models. Figure 2 conveys these scaling properties by showing the relationship between compute (FLOPs) and model performance (measured by normalized entropy, NE) across several dimensions: model depth, content/semantic enrichment, model width, and sequence length.
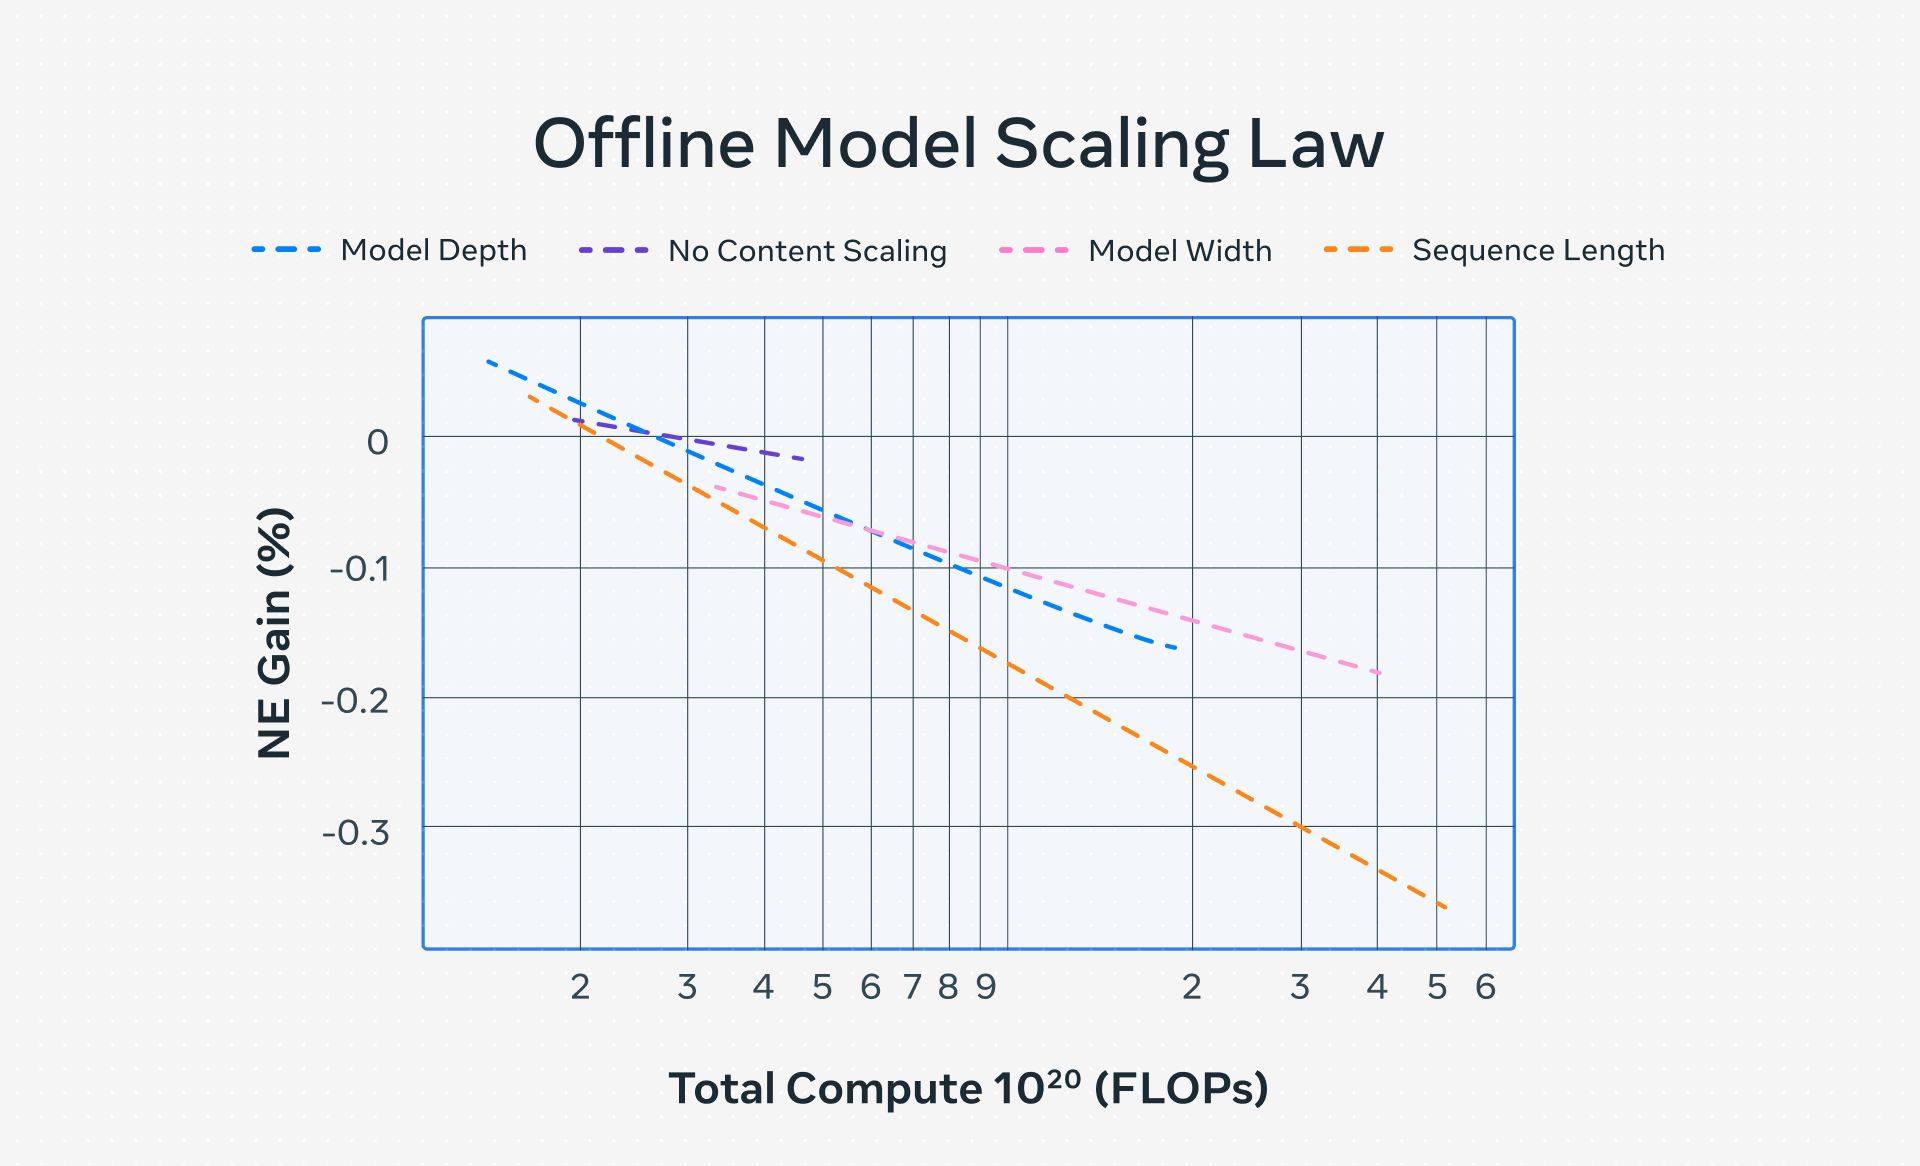
Unlike LLMs, which process dense and continuous text, ads recommendation systems must integrate sparse ID features with temporal user sequences. The fact that LLM-style scaling emerged despite the structural differences provides a strong indicator of model architectural fit for further sequence learning applications.
We have identified four levers that we anticipate will help unlock the frontier of the scaling law:
Optimal performance requires balanced growth across model depth, width and sequence lengths. If scaling only occurs on a single axis, the other axes will likely bottleneck the performance improvements, potentially leading to diminishing returns. This mirrors findings from LLM scaling law research, a principle we call the scaling synergy principle.
The multi-stage architecture provides a tunable lever to scale either the offline or online model up/down. Scaling the online ranking model drives steeper improvements per unit of compute that is bounded by serving/request time requirements. Scaling the offline model (shown in Figure 2) follows a more gradual curve, but its async inference avoids latency constraints, allowing scale in at an unhindered rate.
Performance continues to improve as sequences get longer, but an impactful finding is that sequence diversity beats sequence homogeneity. A balanced mix of action types (e.g., views, clicks, conversions) yields better results than sequences composed of a single action type. This finding suggests that a diverse mix of engagement types and broad temporal coverage produce richer behavioral representations of users than homogeneous sequences of high signal actions in isolation.
Semantic content features from foundation models complement traditional collaborative filtering (i.e. which users interacted with which items) signals. They are especially helpful in cold-start scenarios (e.g., new ads or advertisers with limited historical engagement data). By addressing this persistent challenge of recommendation systems, we improve overall signal coverage to a fundamental sparse problem in recommendation systems.
The multi-stage sequence modeling architecture is delivering impact across three dimensions:
By modeling thousands of user event sequences (e.g., clicks, views, and purchases) the offline model generates highly nuanced user representations. This depth of behavioral understanding improves ad relevance and conversion rates across Meta’s Family of Apps. Together with our broader modeling innovations, these sequence-derived representations drove a cumulative lift of 6% in conversions on Instagram, 3% on Facebook and 3.5% in ad clicks on Facebook.
The two-stage design delivers performance improvements with greater compute efficiency compared to hybrid approaches. Initial evaluations improved ads ranking quality with minimal impact to serving resources, confirming that model complexity and production efficiency can scale together.
As a core part of GEM, this model architecture for sequence learning has been designed for generalization, where the same multi-stage backbone and scaling properties can extend to any ads ranking task with minimal adaptation and overhead.
The sequence model scaling law shows no signs of saturation. With architectural parity achieved, scaling model complexity can draw on techniques proven in the LLM domain (e.g., mixture-of-experts, cross-user compute sharing, advanced attention mechanisms) with potential to continually scale at the optimal performance/efficiency tradeoff.
A detailed technical publication of this model architecture and its scaling properties is available in our paper, “LLaTTE: Scaling Laws for Multi-Stage Sequence Modeling in Large-Scale Ads Recommendation.”
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。