






I used to think opt-ing out of training on AI services, as a paid user, meant they cannot use your interactions for training. Recently, I read OpenAI’s consumer terms, and let’s just say they are ambiguous. In particular, I think there might be a loophole that allows training on hidden CoT reasoning, which contains the input and output, and if so, would make the guarantee vacuous. Let’s dive in:
From OpenAI's consumer terms, opt-out applies to “Input” and “Output” (together called “Content”), defined as:
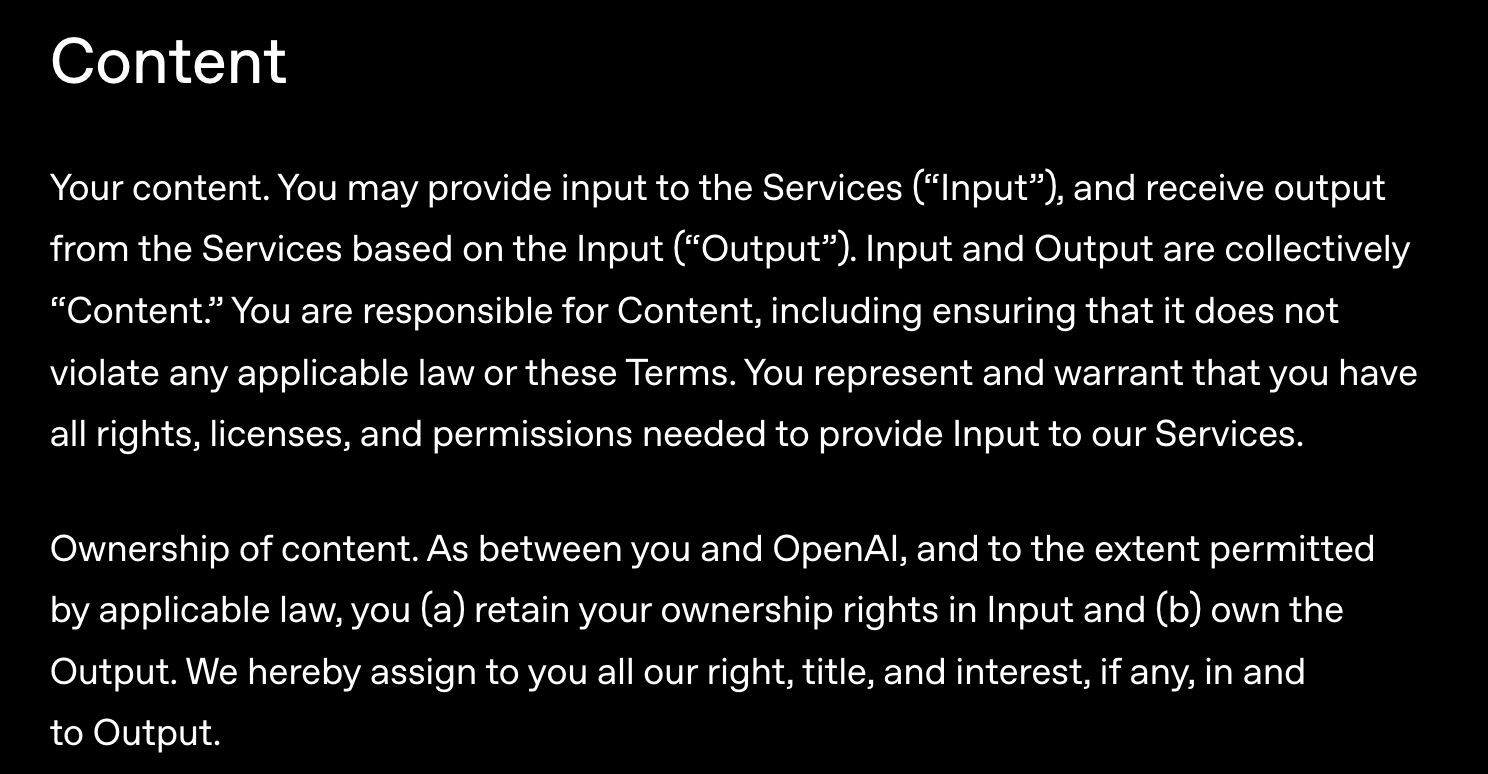
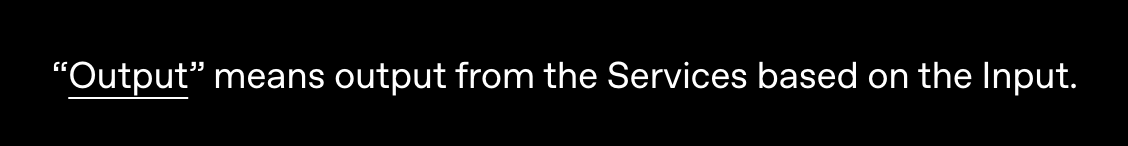
Notice, we do not receive hidden CoT from OpenAI, so its unclear if it counts as "Output" in this definition. It likely does not, as if we own Output, but are never provided CoT, then we cannot own CoT? This is important, because hidden CoT mostly contains a lightly processed version of everything useful for training, including user input and the output returned to users. If the opt-out applies to Content, and CoT is not Output and thus not Content, then CoT can be used for training even if you opt-out?
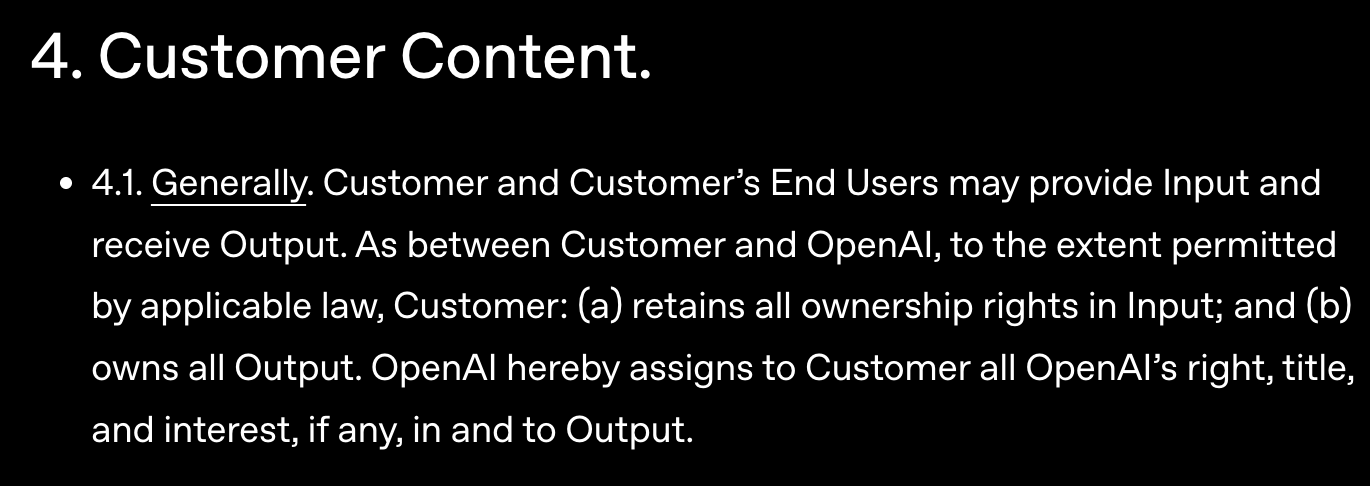
It is interesting to contrast the wordings of other similar services, e.g. OpenAI's own enterprise terms, or Anthropic’s consumer terms. It is not mentioned that the user needs to receive Output.
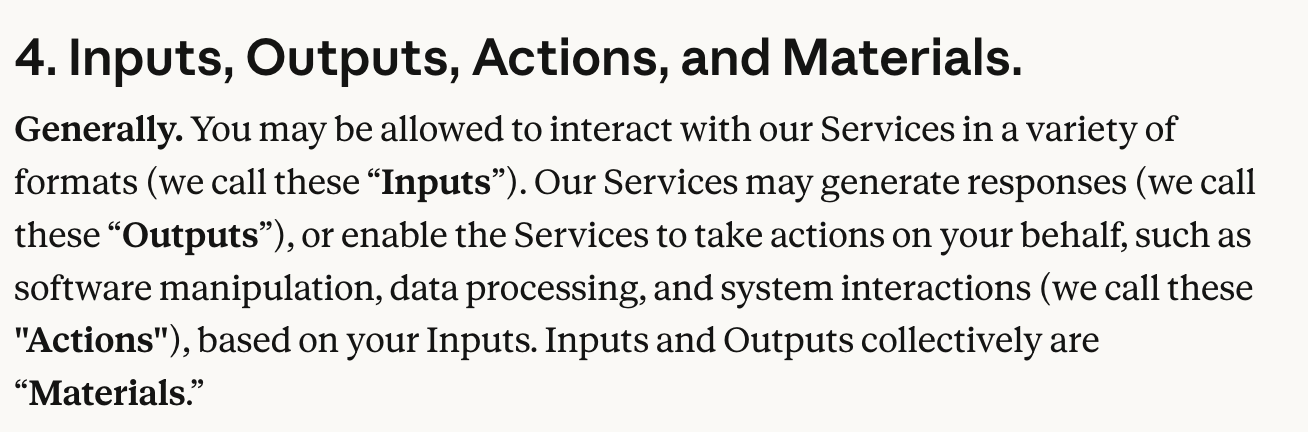
Though similar statements about users owning and being responsible for Output apply

So what are the implications?
I think if the training opt-out guarantee only applies to the (exact?) input we send and output we receive, then it means OpenAI can definitely post-process your data lightly, and use it as part of their training pipeline. This can be fully automated, and not require any humans to read the data, thus being consistent with recent claims that employees cannot access user data. However, this does allow OpenAI to train on your “IP”, even if you pay them 200$ a month on their Pro plan.
All that said, I am not a legal expert, and did not consult one, so it would be great if someone who knows better (or OpenAI) could confirm. I contacted the OpenAI data policy officer email provided 2 days back, and did not receive a clarification. Note that I am only pointing out an ambiguity in the guarantee, and not saying OpenAI definitely trains on hidden CoT. A clarification would be super useful in any case!