











The focus of LLM alignment has rapidly shifted from static chatbot alignment to dynamic agentic workflows. Today’s models don't just talk—they execute multi-step reasoning, call external APIs, and interact with complex environments.
Training reasoning agents encounters special challenges and bottlenecks. The recent evolution of agentic RL training shifts the process from single-turn alignment to multi-turn decision-making with complex environment interactions and tool usage. This shift raises new challenges on the infrastructure side for rollout performance and efficiency; when an agent pauses to execute code, query a database, or wait on a web search, the expensive AI accelerator utilization plummets as TPUs sit idle waiting for environment steps.
Tunix—Google’s post-training library—natively solves this bottleneck in its latest release, introducing an efficient, composable framework for training LLM agents at scale. Tunix keeps accelerators fully utilized on two fronts:
Beyond orchestration, agentic RL requires specialized observability. While standard profilers like XProf offer deep operator-level traces, their high overhead limits them to short, sporadic captures. Tunix introduces continuous, lightweight instrumentation built directly around domain-specific RL metrics. By correlating these high-level loop metrics with TPU timelines, developers get a global view of execution efficiency to quickly spot and resolve system bottlenecks.
Ultimately, Tunix is built to maximize TPU throughput, keep environments modular, and make multi-turn training efficiency fully transparent. Here is how it works under the hood.
Achieving peak hardware throughput means keeping TPUs constantly busy. Tunix accomplishes this by combining asynchronous rollouts to eliminate execution bubbles and stragglers with a decoupled pipeline that continuously streams data to the trainer.
In Agentic RL, trajectory generation (rollout) is the most time-consuming phase. However, the traditional synchronous rollout architecture creates two major problems, as depicted in the figure below.

Tunix solves this with an Asynchronous Trajectory Collector Engine.
RolloutOrchestrator, the framework manages massive pools of concurrent agent-environment interactions. While one agent pauses for a host-side tool execution, the inference engine immediately pivots to generate tokens for other active trajectories.This architecture completely overlaps model inference, tool execution, and reward computation, preserving high hardware utilization.
While async rollouts solve trajectory generation bottlenecks, another critical challenge for hardware efficiency in the end-to-end RL workflow is bridging dynamic, variable-length, and potentially long-tail rollouts with a strictly synchronous training loop. A naive approach relies on a synchronization point that forces the accelerator to wait until an entire batch of trajectories is complete before initiating the training step, starving the trainer TPU.
Tunix eliminates this bottleneck by decoupling rollout and training into a continuous producer-consumer pipeline (illustrated in the diagram below):
AgenticRLLearner consumes from this queue. For algorithms like GRPO—which require multiple reasoning paths per prompt to compute group advantages—Tunix dynamically groups these asynchronous trajectories on the fly.
The moment a trajectory group is complete, it is post-processed, scored, and streamed directly into the trainer. This pipeline ensures the synchronous trainer is constantly fed, maximizing end-to-end throughput.
A major friction point in RL frameworks is the rigid coupling of the algorithm to the environment loop. Modifying a codebase to support a new open-source software (OSS) benchmark like SWE-bench, WebArena, or a custom game engine often requires a massive rewrite.
Tunix resolves this with a decoupled, composable architecture. By exposing a clean API boundary, Tunix automates step invocation and lifecycle management so you can focus entirely on core interaction logic.
ConversationAgentBase.TaskEnvironment and ToolEnvironment classes. You can also inherit from BaseTaskEnv to interface with any external system. Tunix handles multi-turn episode lifecycles, observation routing, and reward processing automatically.Why it matters: You can onboard any open-source RL environment in minutes. Because the agent and environment logic are completely decoupled from the training workflow, swapping a single-turn math verifier for an interactive bash terminal requires zero modifications to your training code. To demonstrate the power of this composable design, we next showcase a few examples of how easily new agents, models, or environments can be used. You can find more detailed examples of customized Agent/Env in our recipes.
Tunix offers built-in classes like ModelAgent and ToolAgent that work immediately via configuration.
from tunix.rl.agentic.agentic_grpo_learner import GRPOLearner
from tunix.rl.agentic.agents.model_agent import ModelAgent, ToolAgent


# Non tool calling single turn agent
learner = GRPOLearner(
    agent_class=ModelAgent,
    agent_kwargs={"system_prompt": "my system prompt"},
    ...
)


# Customized tool call agent
tool_map = {"calculator": CustomizedCalculatorClass, ...}
learner = GRPOLearner(
    agent_class=ToolAgent,
    agent_kwargs={
        "system_prompt": "my system prompt",
        "tool_parser_name": "gemma",
        "tool_map": tool_map,
    },
    ...
)
Python
Copied
Alternatively, you can build your own custom Agent and add specific logic on how to process the model responses. Tunix will automatically wire this agent in the end to end training workflow. E.g. SWEAgent, FrozenLakeAgent
from tunix.rl.agentic.agents.base_agent import ConversationAgentBase
from tunix.rl.agentic.agents import agent_types


# Bring your own agent!
# Notice how the agent doesn't need to know anything about the model (if it is Qwen, Llama, or Gemma)
class MyAgent(ConversationAgentBase):
    def __init__(self, args):
        ...


    def update_from_model(self, response: str, **kwargs) -> agent_types.Action:
        # Custom logic to process the raw response (e.g., extracting <answer> tags)
        ...


# Tunix automatically wires up the e2e workflow
learner = GRPOLearner(agent_class=MyAgent, agent_kwargs={...}, ...)
Python
Copied
Similar to Agents, Tunix offers a number of pre-built environments including TaskEnvironment, ToolEnvironment. Alternatively, you can also bring your own custom environment by simply implementing a few main APIs, including any open source environment such as the Gymnasium example below.
import gymnasium as gym
from tunix.rl.agentic.agentic_grpo_learner import GRPOLearner
from tunix.rl.agentic.environments.base_environment import BaseTaskEnv, EnvStepResult


# You only need to focus on the core logic of environment interactions, and Tunix will automatically handle the rest of the lifecycle management and function invocation.
class MyEnv(BaseTaskEnv):
    def _initial_observation(self):
        # handle env creation and initial observation
        self.env = gym.make("your_chosen_env")
        observation, info = self.env.reset(seed=42)
        return observation


    def _step_impl(self, action):
        # compute observation, reward, done, info
        action = self.env.action_space.sample()
        obs, reward, done, info = self.env.step(action)
        return EnvStepResult(obs, reward, done, info)


    def close(self):
        self.env.close() # clean up env after trajectory is done


learner = GRPOLearner(env_class=MyEnv, ...)
Python
Copied
When running asynchronous agentic training at scale, traditional logging falls short. You need granular yet domain-specific visibility to identify efficiency problems: Is the bottleneck in the generation phase? Is the tool call taking too much time? Or is the data-loader too slow?
Standard profilers like XProf provide detailed, op-level traces to understand micro-level performance like kernel and model execution. However, capturing long-spanning traces with these tools is typically cost-prohibitive, and identifying macro-level bottlenecks within the noise of low-level data remains difficult. For the complex workflows of agentic RL, developers need a lightweight, macro-level view built on domain-specific metrics that map directly to RL stages.
Tunix delivers this big picture by carefully tracking a minimal set of critical RL-specific metrics that represent both the global pipeline (how rollout, training, and weight sync phases interact) and important sub-steps (each model call, environment interaction, etc.). Because they are lightweight, these metrics run continuously throughout the entire training job. Users can quickly identify where the workflow is stalling globally, and then deploy a tool like XProf for targeted, further debugging.
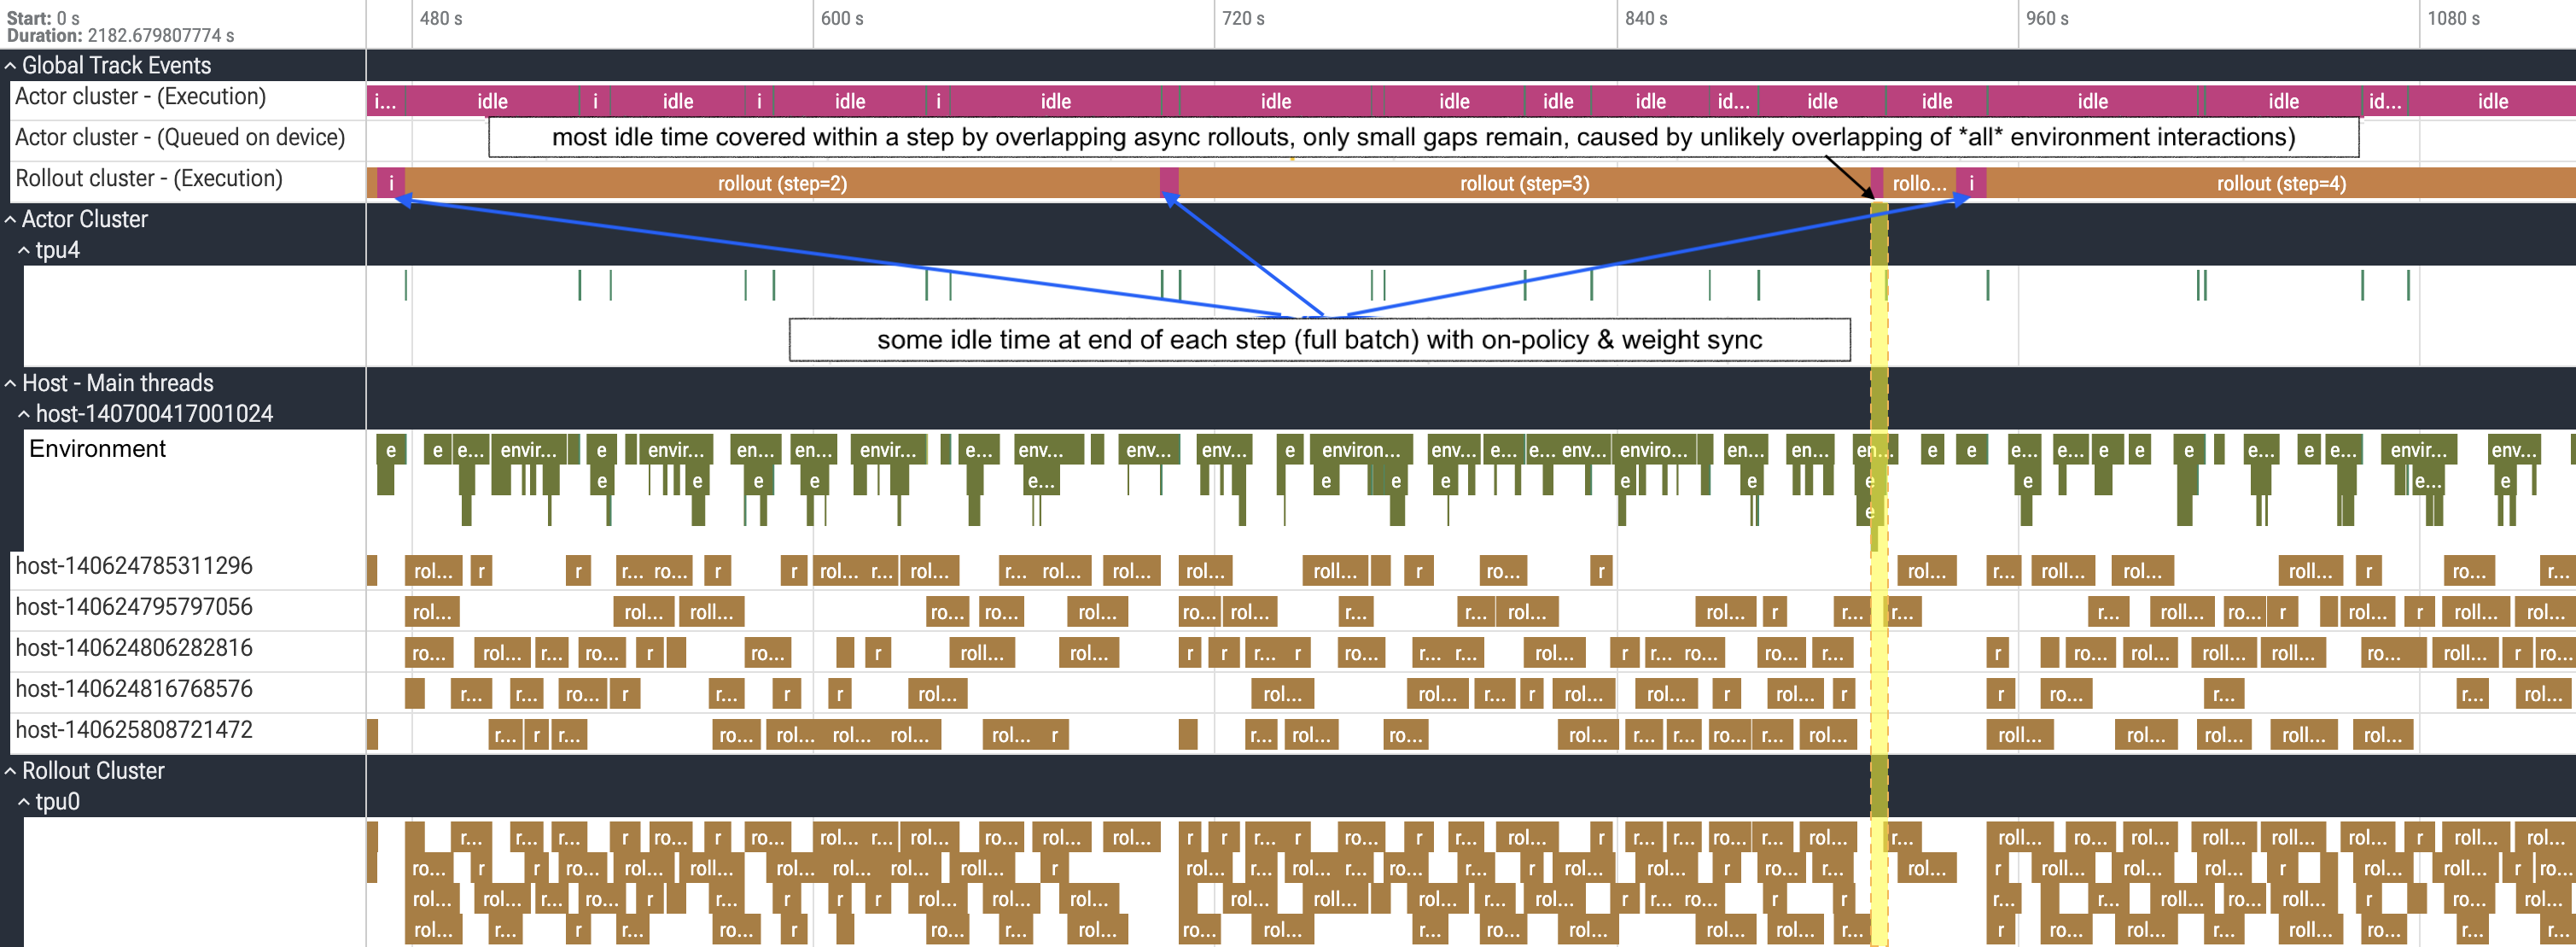
The figure above illustrates a Perfetto trace captured from a multi-turn agentic training job, detailing the staged execution timelines across CPU threads and TPU devices. As demonstrated by the trace, TPU device utilization is much higher than that of the CPU threads, whose idle time is primarily due to environment execution latency.
This macro-level tracing of staged RL pipelines enables you to:
Tunix turns the "black box" of distributed multi-turn RL into a transparent, optimizable timeline for the training job.
If you are evaluating frameworks for Agentic RL, here is how Tunix stands out:
Whether you are reproducing SOTA reasoning models, fine-tuning the Gemma or Qwen families to "think," or deploying complex multi-agent systems, Tunix provides the high-performance foundation needed for the next generation of reasoning agents. Start building today!
/examples folder to explore a variety of recipes and run your first training job today!Tunix is under active open-source development by Google and the wider community. If you are building the next generation of reasoning agents, drop by our GitHub Issues and let us know what environments you are plugging in.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。