








Your LLM bill is leaking — see exactly where, on your machine.
Free, local, open-source LLM cost analyzer. Point Frugon at your LLM call logs and see — on your machine — how much you'd save by switching or routing models.

Your data never leaves your machine. Your keys go straight to your own providers. Nothing reaches us.
Install & run
# one-shot (no install)
uvx frugon analyze ./logs.jsonl

# permanent install
pipx install frugon
frugon analyze ./logs.jsonl

# for --measure (optional): samples real prompts through your own provider keys
pip install 'frugon[measure]'
frugon analyze ./logs.jsonl --measure
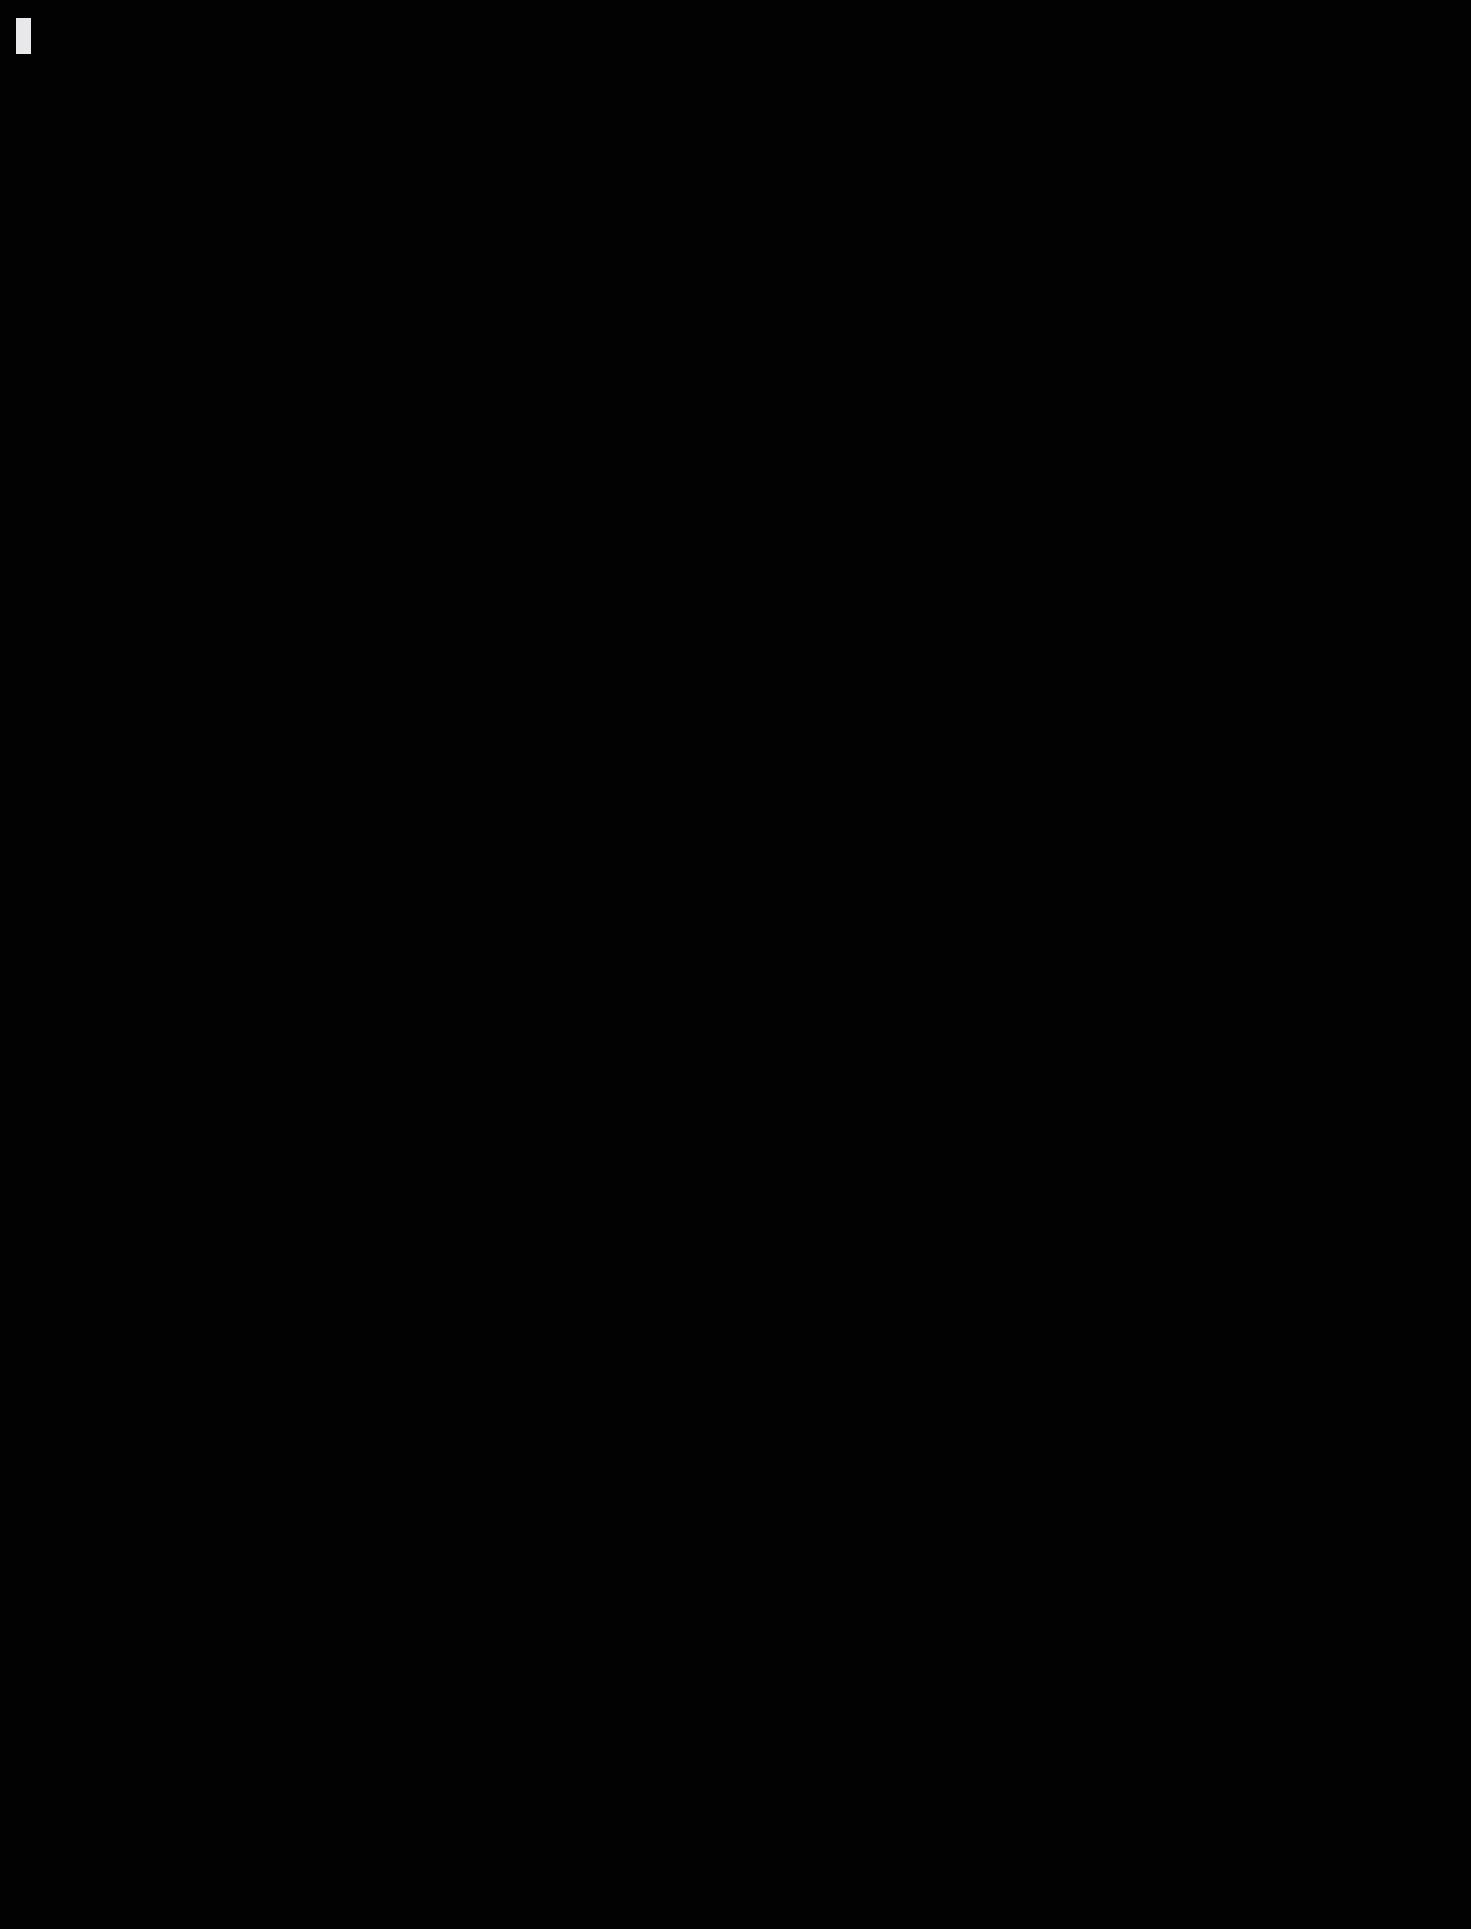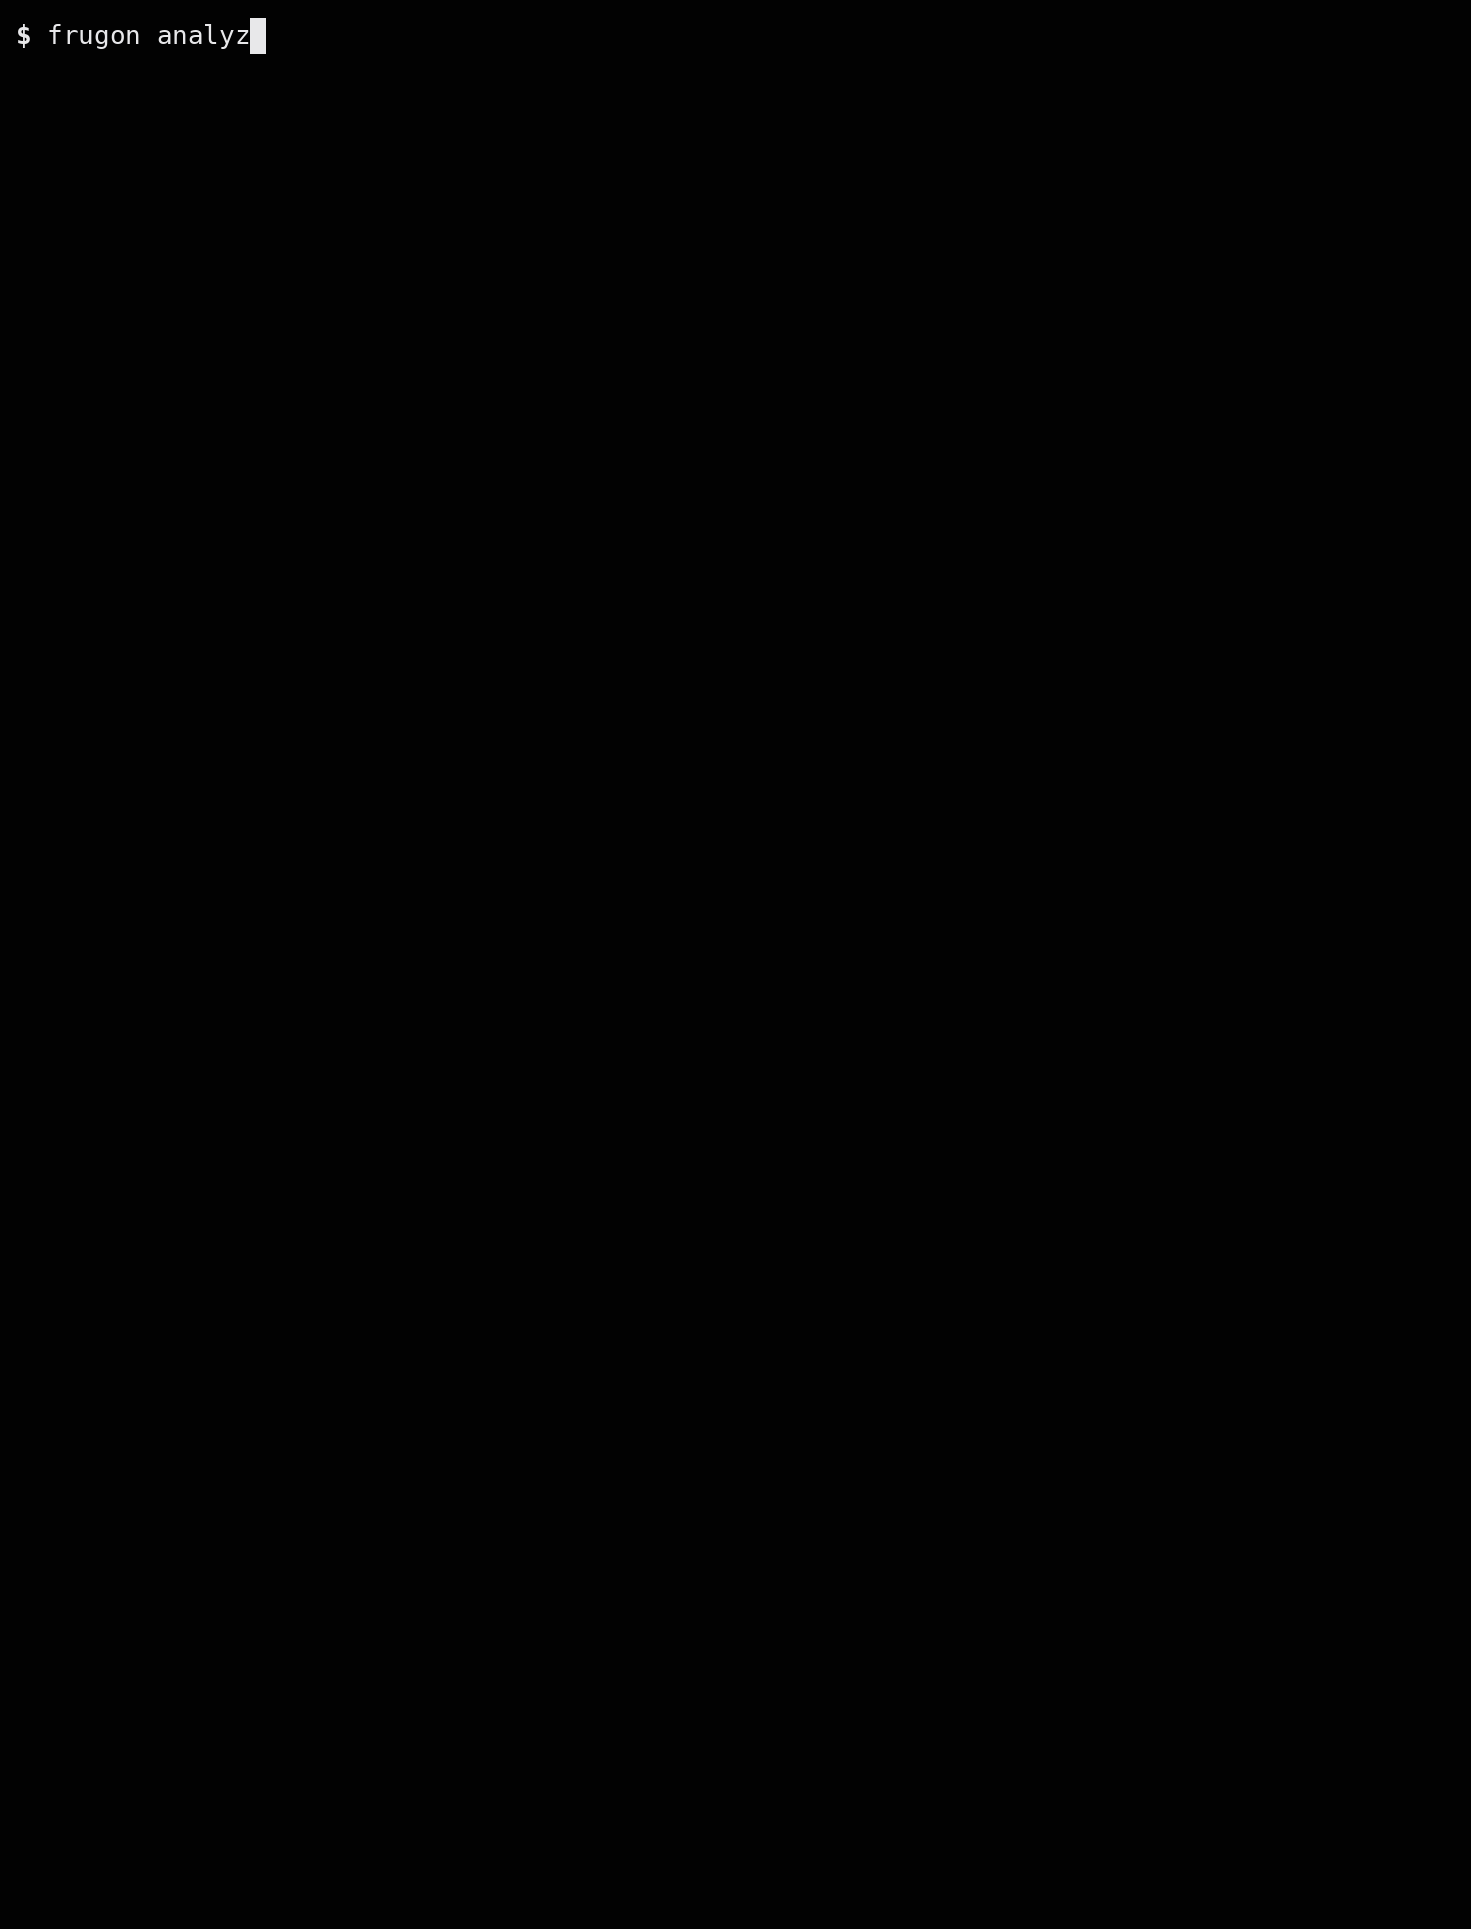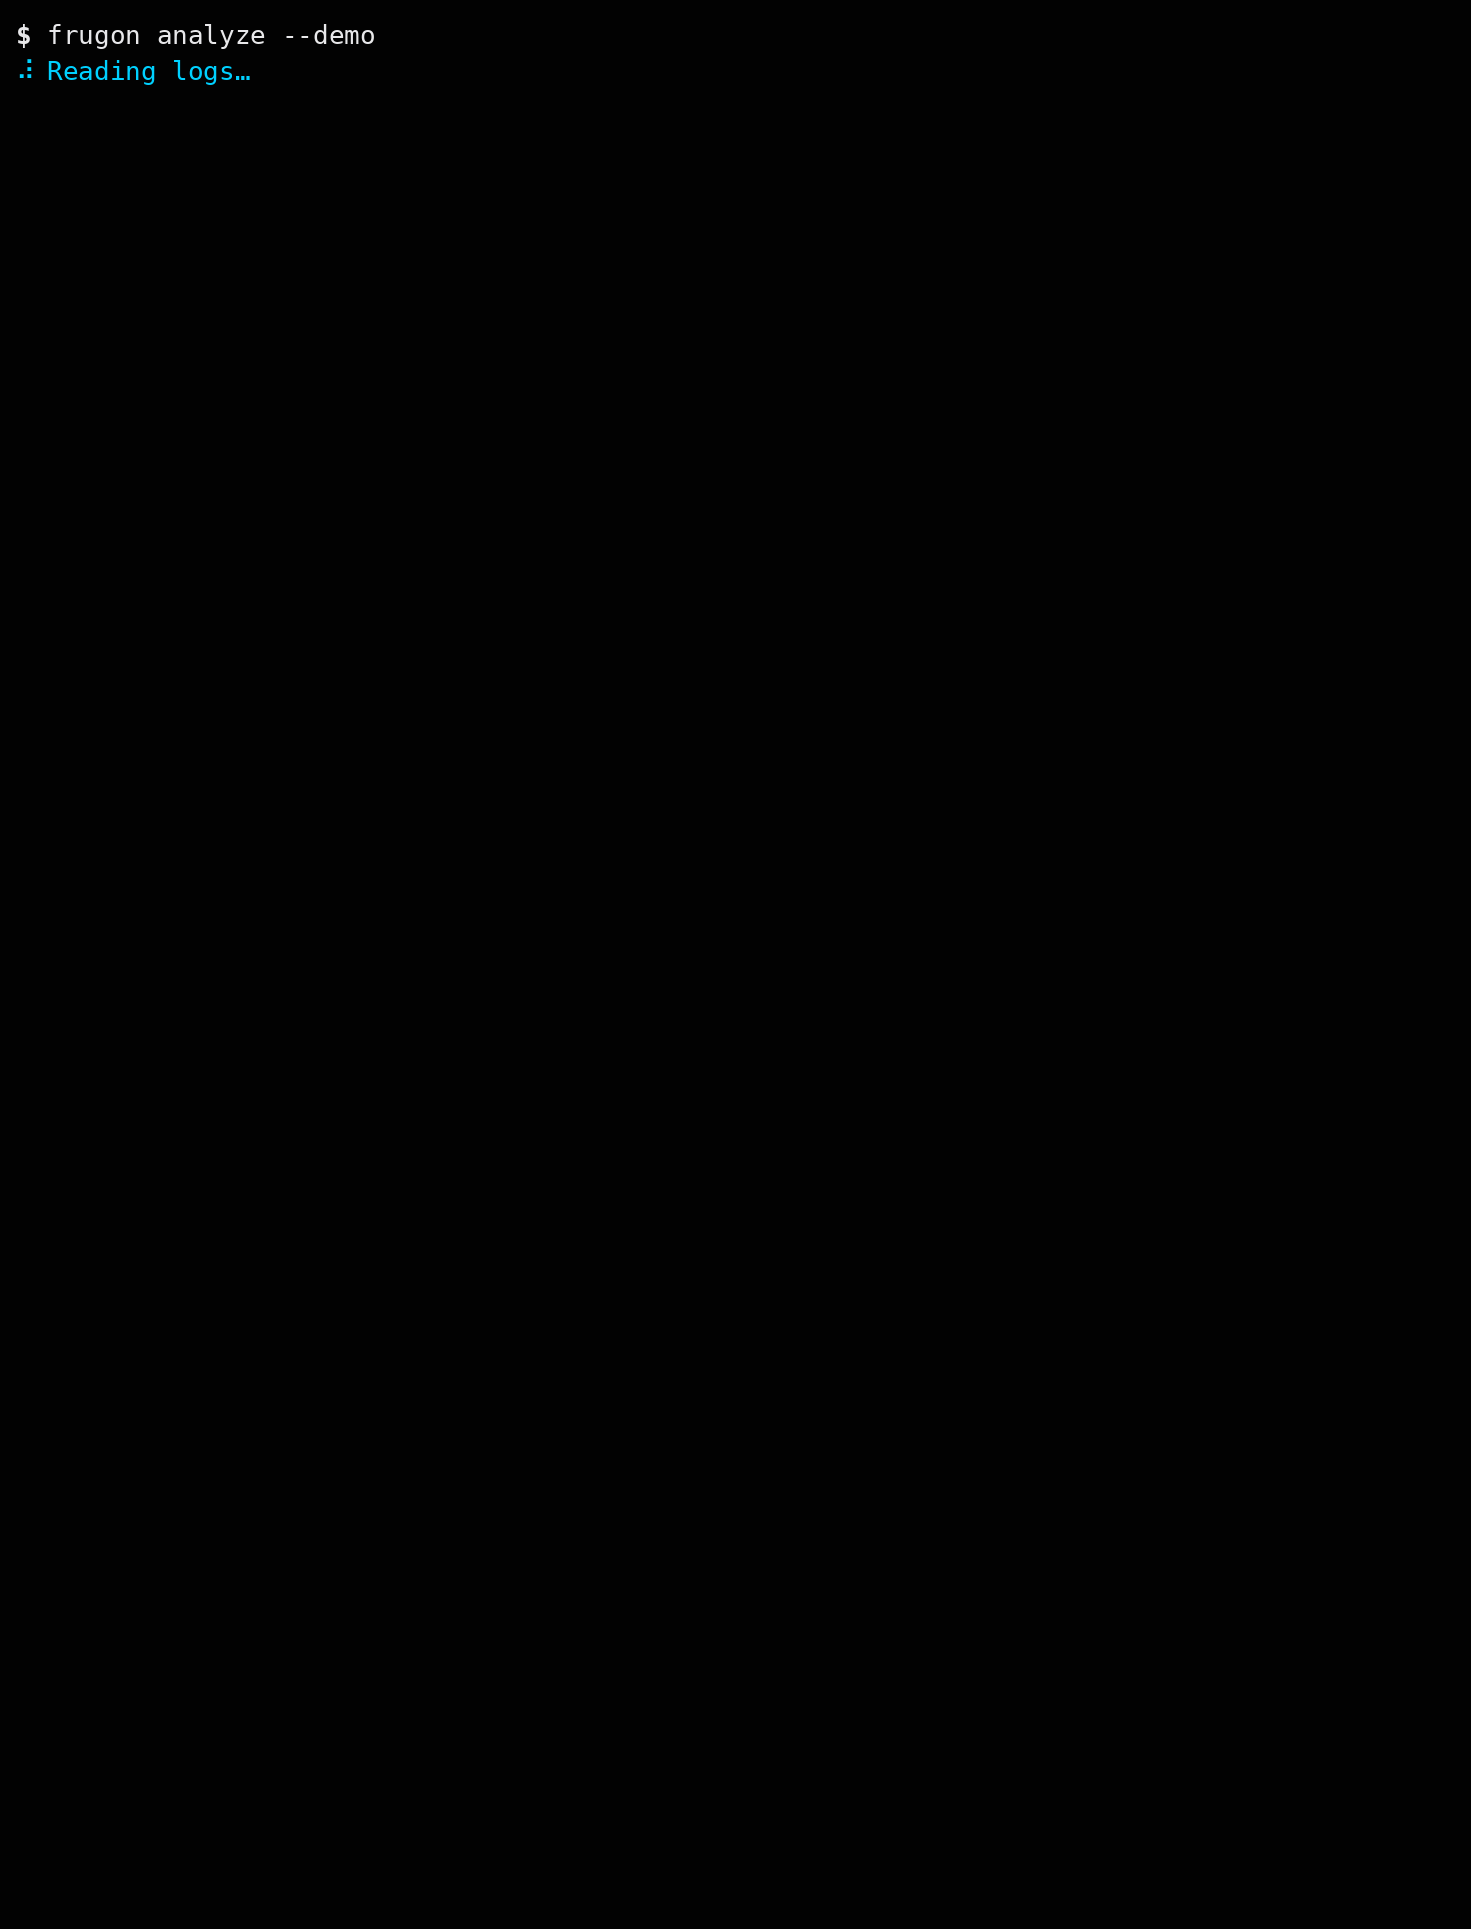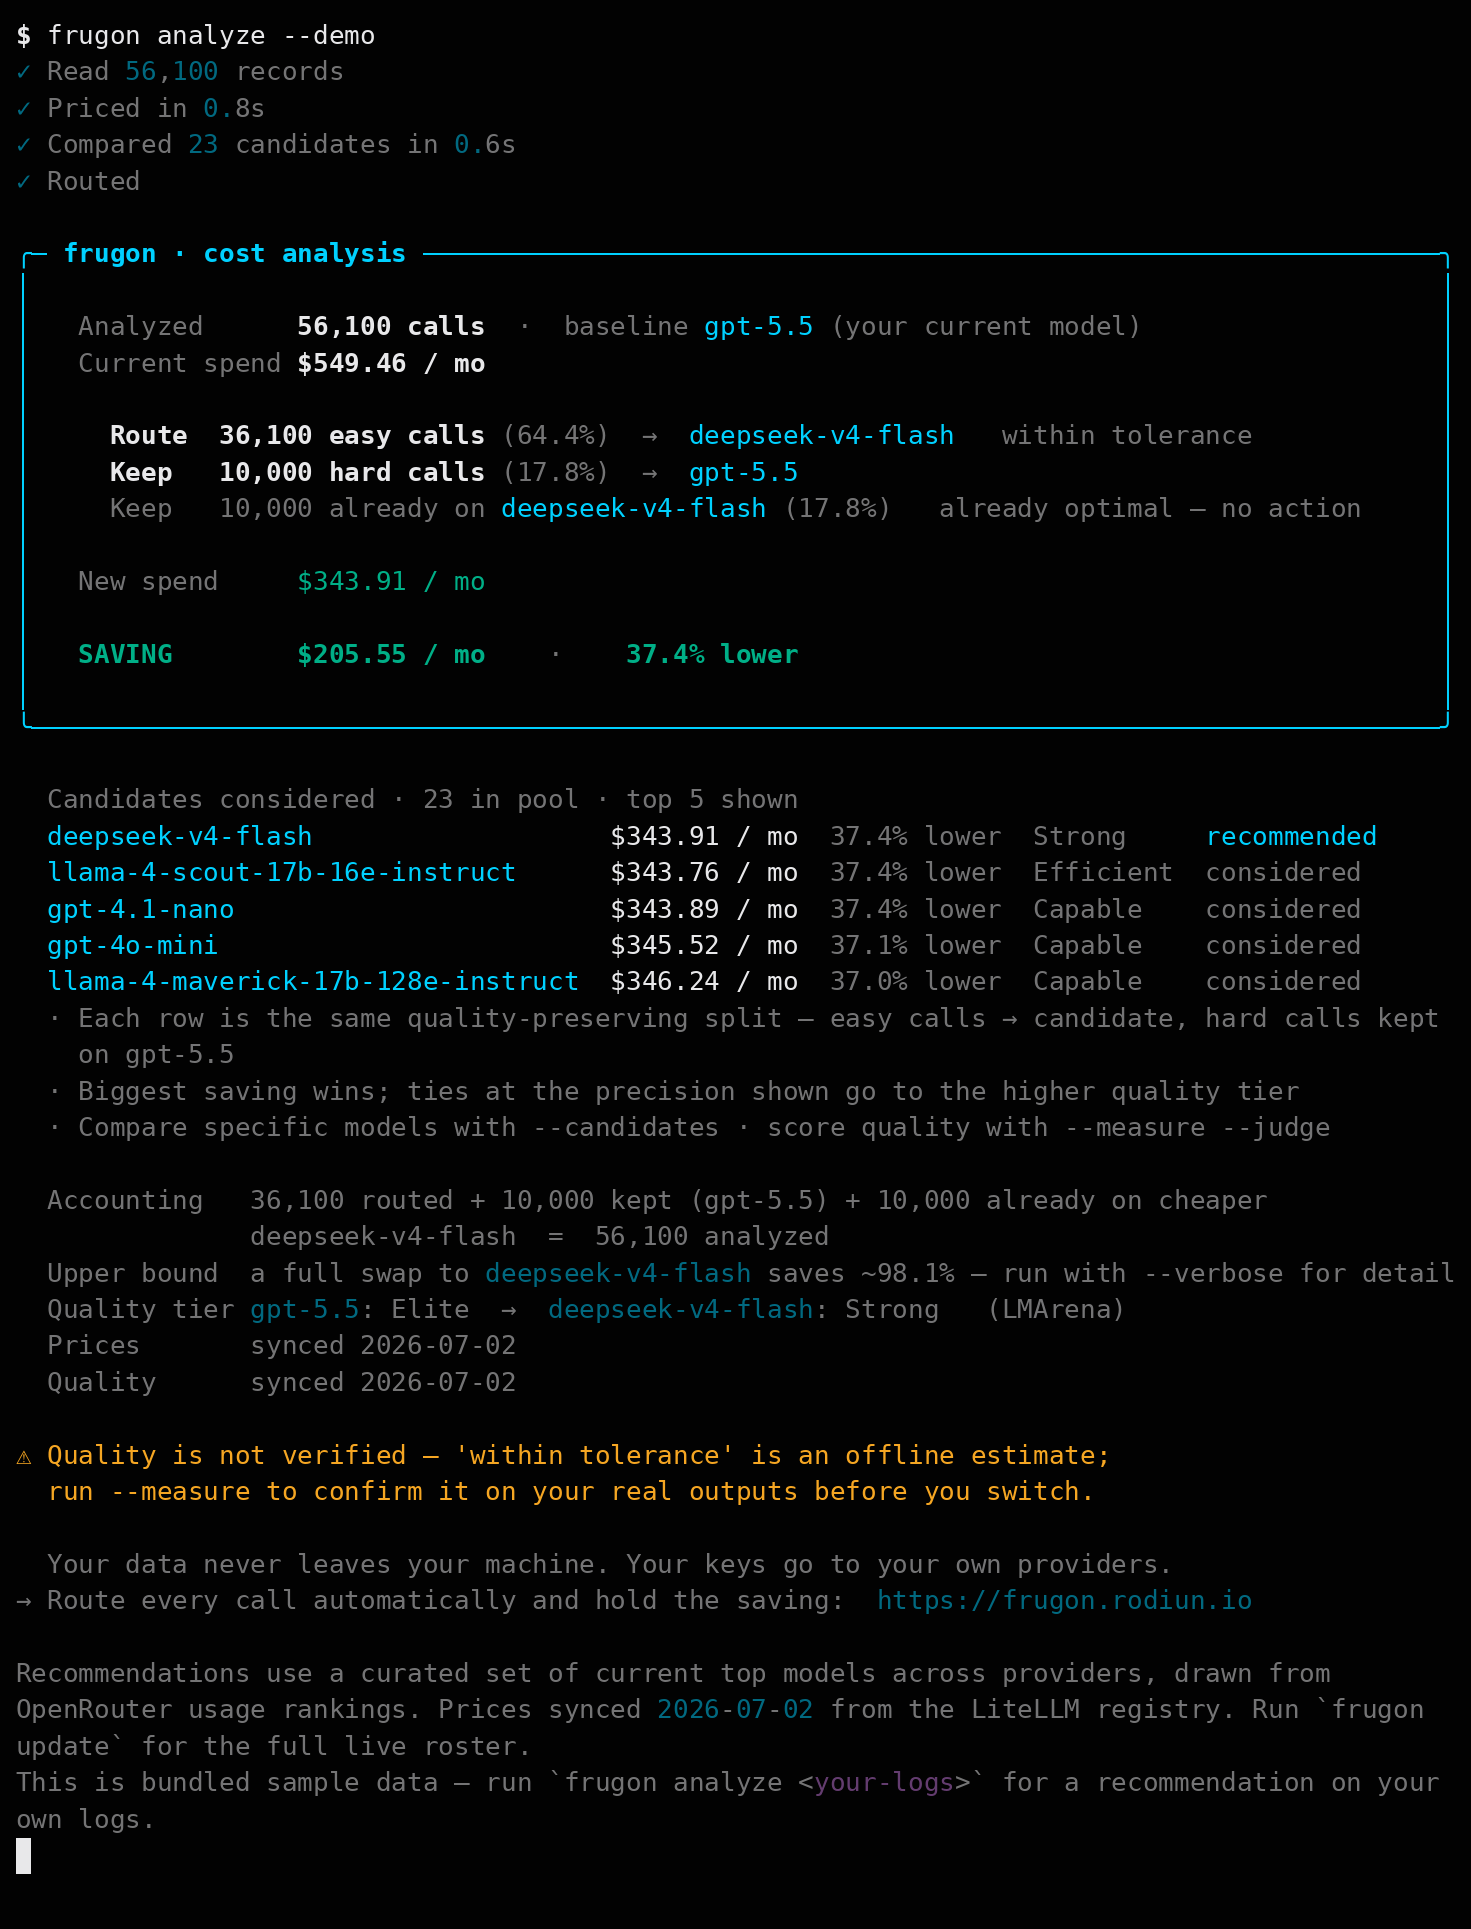
No logs yet? See Getting your logs below, or run frugon analyze --demo to see it work on a bundled sample.
Getting your logs
frugon reads JSONL files in the OpenAI request/response format. There are two ways to produce them.
Option A — frugon capture (proxy shim)
frugon capture is a local HTTP proxy that sits between your app and your provider.
Every call is forwarded unchanged to your real provider and saved as one JSONL line.
# Start the shim (default port 8787, output file capture.jsonl)
frugon capture --out ./logs.jsonl

# Then point your app's base URL at the shim instead of api.openai.com:
OPENAI_BASE_URL=http://127.0.0.1:8787 your-app           # bash / zsh
$env:OPENAI_BASE_URL="http://127.0.0.1:8787"; your-app   # PowerShell (Windows)
# or in code: client = OpenAI(base_url="http://127.0.0.1:8787/v1")
Options: --port, --out, --upstream (override the forwarding target), --verbose
(print one line per captured call to verify it's recording), --proxy (opt in to route
upstream calls through a proxy — by default frugon ignores any ambient HTTP_PROXY /
HTTPS_PROXY, so your API key never passes through a third-party proxy). The shim adds no
latency overhead on localhost and makes no calls to any frugon endpoint.
Option B — write JSONL directly
If you already capture logs (e.g. via middleware or a provider SDK callback), write one JSON object per line with this shape:
{
  "model": "gpt-4-turbo",
  "request": {
    "messages": [
      {"role": "system", "content": "You are a helpful assistant."},
      {"role": "user",   "content": "Summarise this document: ..."}
    ]
  },
  "response": {
    "choices": [{"message": {"content": "Here is the summary: ..."}}]
  },
  "usage": {
    "prompt_tokens": 312,
    "completion_tokens": 84
  },
  "timestamp": "2024-11-01T14:22:01Z"
}
usage.prompt_tokens / usage.completion_tokens — preferred when present; frugon falls
back to its own tokenizer when absent. timestamp is optional but enables frugon to
project costs over a real observed span. model is required; everything else degrades
gracefully.
5-minute path from install to first analysis
uv tool install frugon          # or: pipx install frugon / pip install frugon
frugon capture --out ./logs.jsonl &   # start the proxy in the background
# ... run your app, make some LLM calls ...
frugon analyze ./logs.jsonl     # see the cost breakdown and routing recommendation
What it does
- Cost analysis — fully local, no LLM calls, no network. Tokenizers + pricing + arithmetic on your machine.
- Quality visibility (
--measure, optional) — samples your traffic through candidate models using your own API keys, sent directly to your own providers. Never to us.--measureneedspip install 'frugon[measure]'and a provider API key (OPENAI_API_KEY, etc.); calls go to your own provider, never to us. On--demo, sampling is pinned to a single OpenAI model so the try-out needs onlyOPENAI_API_KEY; on your own logs,--measuresamples the actual recommendation. - Routing recommendation — "move these X% of calls to a cheaper model and save ~$Y/mo; keep the hard Z% where they are." Comes with an explicit quality caveat so you know what you're trading.
Run
frugon modelsto see the model names available for--candidates(optionallyfrugon models gpt-4oto filter by substring). - Share the result — add
--report savings.html(or.md) to write a clean, shareable report you can drop into a PR, a Slack thread, or a budget review. - Fast on real logs — everything runs locally and is comfortable well past 100k records. The bundled ~56,100-call demo (
frugon analyze --demo) prices in a few seconds. Very large logs (>200k records) may take a little longer; Frugon shows a live progress bar and a one-line heads-up so you can see it working. There's no hard limit.
Example output
$ frugon analyze --demo --candidates claude-sonnet-4-5,gpt-4.1,claude-haiku-4-5,gemini-2.5-flash,deepseek-v4-flash

┌─ frugon · cost analysis ────────────────────────────────────────────────────┐
│                                                                             │
│   Analyzed      56,100 calls  ·  baseline gpt-5.5 (your current model)      │
│   Current spend $549.46 / mo                                                │
│                                                                             │
│     Route  36,100 easy calls (64.4%)  →  deepseek-v4-flash   within         │
│   tolerance                                                                 │
│     Keep   10,000 hard calls (17.8%)  →  gpt-5.5                            │
│     Keep   10,000 already on deepseek-v4-flash (17.8%)   already optimal    │
│   — no action                                                               │
│                                                                             │
│   New spend     $343.91 / mo                                                │
│                                                                             │
│   SAVING        $205.55 / mo    ·    37.4% lower                            │
│                                                                             │
└─────────────────────────────────────────────────────────────────────────────┘

  Candidates considered
  claude-sonnet-4-5  $452.23 / mo  17.7% lower  Strong   considered
  gpt-4.1            $405.89 / mo  26.1% lower  Capable  considered
  claude-haiku-4-5   $377.82 / mo  31.2% lower  Capable  considered
  gemini-2.5-flash   $356.35 / mo  35.1% lower  Strong   considered
  deepseek-v4-flash  $343.91 / mo  37.4% lower  Strong   recommended
  Each candidate is shown under the same quality-preserving split (easy calls
  to the candidate, hard calls kept on baseline); the biggest saving is the
  headline recommendation, and when savings tie at the precision shown the
  higher quality tier wins. Run --measure --judge to score each candidate's
  quality.

  Accounting   36,100 routed + 10,000 kept (gpt-5.5) + 10,000 already on
               cheaper deepseek-v4-flash  =  56,100 analyzed
  Upper bound  a full swap to deepseek-v4-flash saves ~98.1% — run with
               --verbose for detail
  Quality tier gpt-5.5: Elite  →  deepseek-v4-flash: Strong   (LMArena)
  Prices       synced 2026-07-02
  Quality      synced 2026-07-02

⚠ Quality is not verified — 'within tolerance' is an offline estimate;
  run --measure to confirm it on your real outputs before you switch.

  Your data never leaves your machine. Your keys go to your own providers.
→ Route every call automatically and hold the saving:  https://frugon.rodiun.io

Recommendations use a curated set of current top models across providers, drawn
from OpenRouter usage rankings. Prices synced 2026-07-02 from the LiteLLM
registry. Run `frugon update` for the full live roster.
This is bundled sample data — run `frugon analyze <your-logs>` for a
recommendation on your own logs.
Your numbers depend on your logs and your locally synced pricing/quality data.
Run frugon analyze --demo --candidates claude-sonnet-4-5,gpt-4.1,claude-haiku-4-5,gemini-2.5-flash,deepseek-v4-flash
to see the same output on your machine.
Quality tiers for reasoning models reflect the model at its default/typical reasoning effort — effort changes how many tokens a call spends thinking, not its per-token rate, so it never affects the price shown above.
How it's different
A provider's billing dashboard tells you what you already spent, and a raw token counter prices a single call — Frugon prices your real logs against every model, locally, and tells you which calls to move and which to keep.
Realistic savings
Based on RouteLLM's published research (LMSYS):
| Traffic mix | Typical saving |
|---|---|
| General mixed workload | 30 – 50% |
| Easy / repetitive (high MT-Bench similarity) | up to ~85% |
| Hard reasoning / MMLU-heavy | ~30% |
Your actual number comes from your logs. Frugon never inflates — it shows what the math says for your data.
Is this you?
- Agent builders — your GPT-4o agents are expensive; most easy hops don't need them.
- AI dev teams — monthly LLM bill is real; routing pays for itself in days.
- RAG & support — retrieval + rerank is cheap; the final answer call doesn't have to be Opus.
- Data-ETL pipelines — batch extraction is 100% repeatable; mini models handle it fine.
- Indie hackers — every dollar saved is a dollar of runway.
Keep the savings
This is a one-time snapshot. Want it to keep routing automatically and hold the savings? → frugon.rodiun.io
Star the repo if this saved you money.
Contributing
Bug reports and pull requests are welcome — see CONTRIBUTING.md.
Frugon is deliberately small: six commands (analyze, capture, models,
update, pricing, quality), three capabilities (cost analysis, quality visibility,
routing recommendation). Gateways, live routing proxies, web UIs, and
multi-tenant accounts are out of scope by design.
Built by Rodiun. MIT licensed.