







Gemini Robotics ER 2 represents a step change in powering robots with video understanding, task orchestration, and multi-robot collaboration — making it possible for robots to be more helpful in the physical world.
Peng Xu
Staff Software Engineer
For robots to assist humans in everyday environments, accurate spatial reasoning is not enough. Robots must also think fast, timing their decisions and reasoning with the real-time speed of the physical world.
That’s why today we’re launching Gemini Robotics ER 2, our most capable “embodied reasoning” model for robotics. Think of Gemini Robotics ER 2 as a high-level brain for robots. It allows robots to chat with humans, understand the physical world, and plan multi-step tasks. It then hands off motor execution to any given lower level vision-language-action (VLA) model. Gemini Robotics ER 2 can also natively call tools like Google Search to find information, or any other user-defined function. The design of Gemini Robotics ER 2 allows the robot to “think” about what comes next while simultaneously performing its actions.
Gemini Robotics ER 2 represents a significant upgrade over Gemini Robotics ER 1.6. By watching continuous video feeds, robots can now track their own progress, adapt if something goes wrong, and know exactly when to move on to the next step. We are also introducing multi-robot collaboration, enabling robots to work together in shared spaces and complete complex workflows a single robot could not do alone.
Gemini Robotics ER 2 is now publicly available to developers via the Gemini API, Google AI Studio, and in private preview on Gemini Enterprise Agent Platform. To help you get started, we’re sharing examples of how to configure the model and prompt it to power more useful physical AI tasks.
Advancing physical agentic capabilities
Most tasks in the physical world are complex and require multiple steps to complete. Gemini Robotics ER 2 is a physical agent, orchestrating steps for the robot and enabling it to self-correct, and generalize to more novel situations. To build an agentic setup, developers can declare low-level control interfaces — like Vision-Language-Action (VLA) models or navigation APIs — as tools, and stream multimodal video, audio, or text directly into the model.
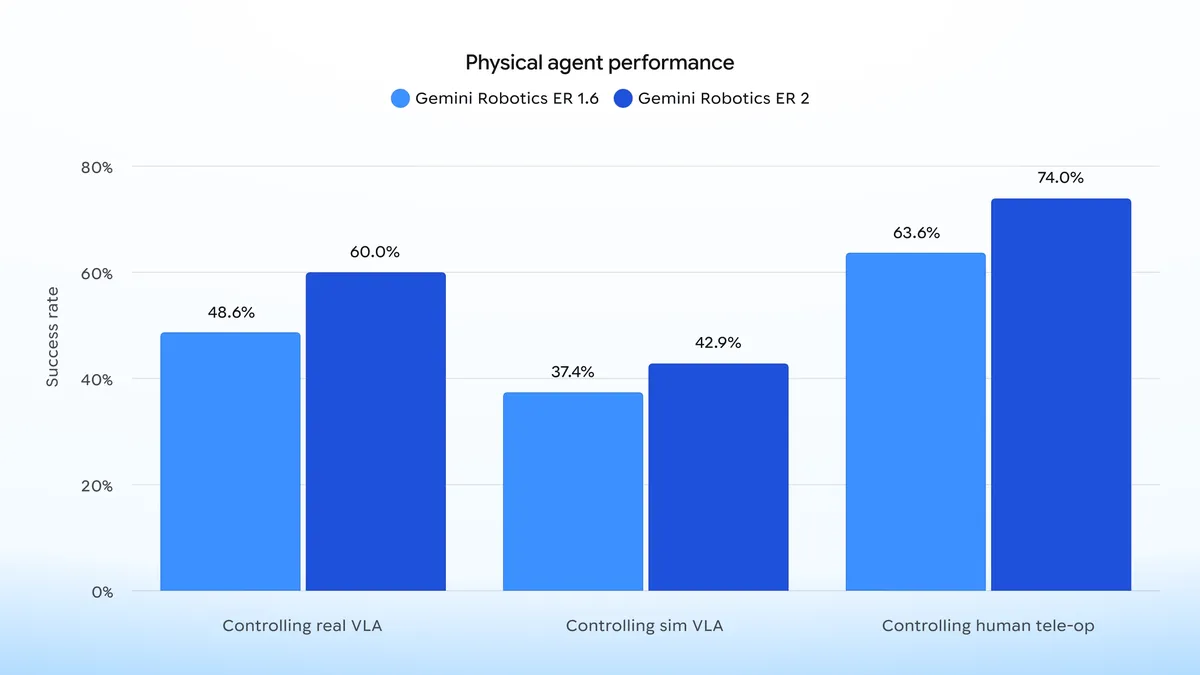
Gemini Robotics ER 2 improves this tool orchestration workflow. We can evaluate its performance with robots in simulation, using real-world robot control, and even pair it with a human controlling the robot remotely.
Gemini Robotics ER 2 consistently outperforms ER 1.6 for tool orchestration across three control modes: real VLA, sim VLA, and human tele-op.
In robotics, high-level reasoning depends on execution speed. Gemini Robotics ER 2 integrates into the Gemini Live API, using a bidirectional streaming endpoint optimized for latency-sensitive tasks. The result is fluid orchestration: Gemini Robotics ER 2 commands action models and robotics APIs to complete multi-step tasks without the jarring “stop-and-think” pauses.
To illustrate this, we’ve built a demo with Spot from our partners at Boston Dynamics. We use Gemini Robotics ER 2 to orchestrate Spot APIs, such as navigation and manipulator movement, creating an interactive robot that fetches objects for you.
Gemini Robotics ER 2 powered Boston Dynamic Spot fetches a popcorn snack up on a natural language command.
The code is available on Github with other examples.
Unlocking temporal intelligence for robust task completion
One of robotics’ hardest challenges is knowing when a task is done. Gemini Robotics ER 2 brings a step-change in video understanding and progress tracking to verify that complex tasks — such as tightening a light bulb or tying a trash bag — are complete to specification before switching to the next task.
In this update, we’ve made progress on two foundational capabilities for task progress understanding: progress classification and moment finding.
Continuous progress classification
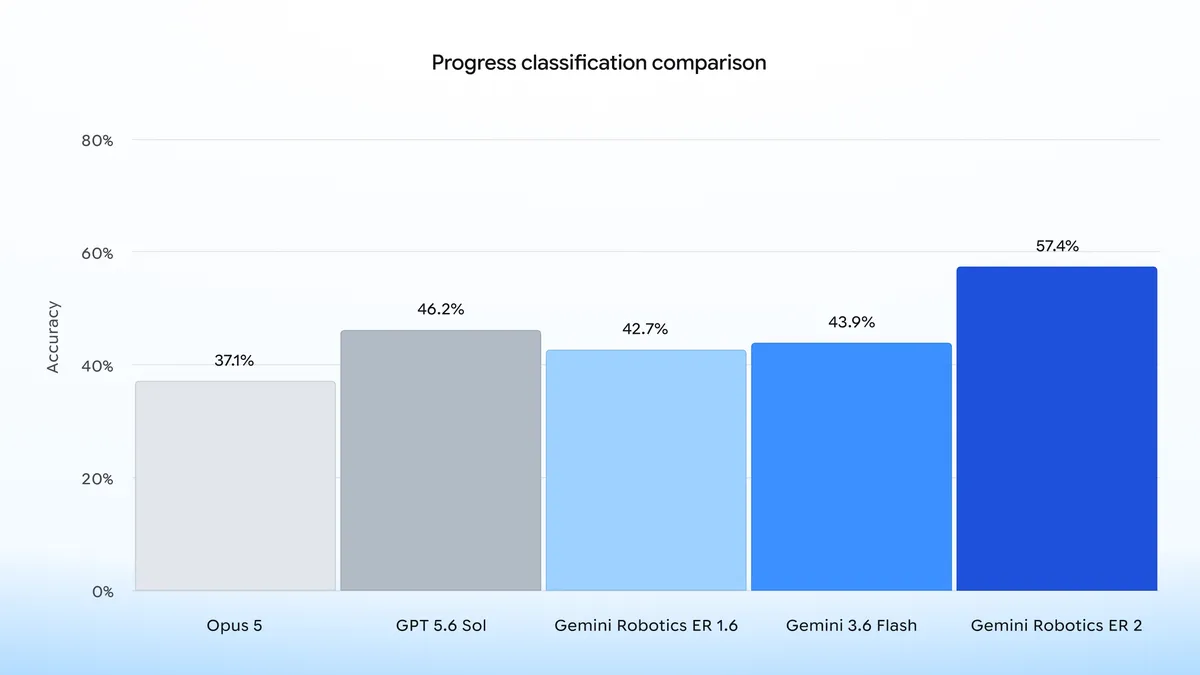
Progress classification refers to a robot’s ability to track progress towards task completion. In our evaluations, we assign each frame in a video feed into five levels of progress (0-20%, 20-40%, 40-60%, 60-80%, 80-100%). By quantifying task progress, Gemini Robotics ER 2 provides robots with real-time situational awareness, and allows them to adjust actions on the fly or retry failed steps without restarting an entire workflow.
Gemini Robotics ER 2 achieves 57.4% accuracy on progress classification tasks, outperforming previous generation models and competing frontier models.
Precision moment-finding
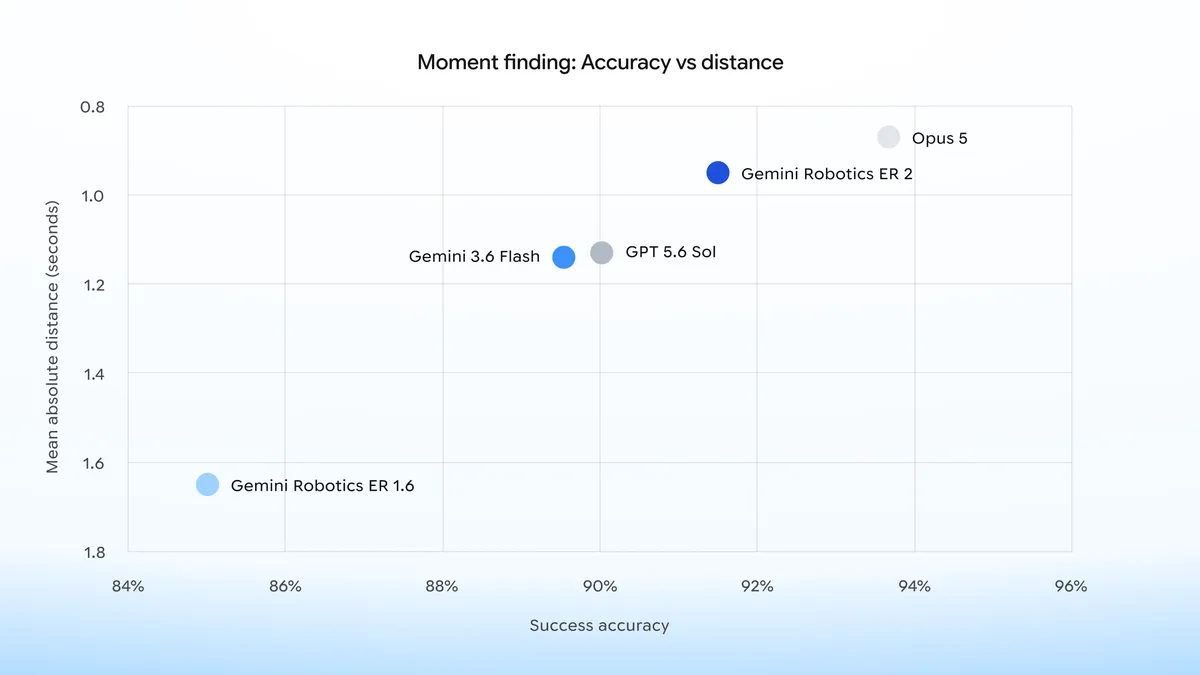
Moment-finding measures a model's ability to identify the exact video frame where a critical event takes place (i.e. when to stop pouring coffee into a cup). Gemini Robotics ER 2 achieves significant gains in performance on moment finding, enabling robots to precisely switch between tasks, verify success and suggest corrections.
For moment-finding tasks, Gemini Robotics ER 2 achieves 91.3% accuracy and a 0.96s mean absolute distance. It competes closely with much larger model categories, but delivers this precision at a fraction of the compute cost and 4x the execution speed—the sub-second latency actually required to safely operate physical robotics in the real world.
Multi-robot collaboration
No single robot fits every task — a wheeled rover excels indoors, while a humanoid robot may excel at uneven terrain. Gemini Robotics 2 enables multi-robot collaboration, allowing diverse machines to communicate via a shared semantic understanding to handoff and complete complex tasks. See how Gemini Robotics ER 2 enables Apptronik’s Apollo 2 and Franka F3 Duo to collaborate here.
Improving general spatial intelligence
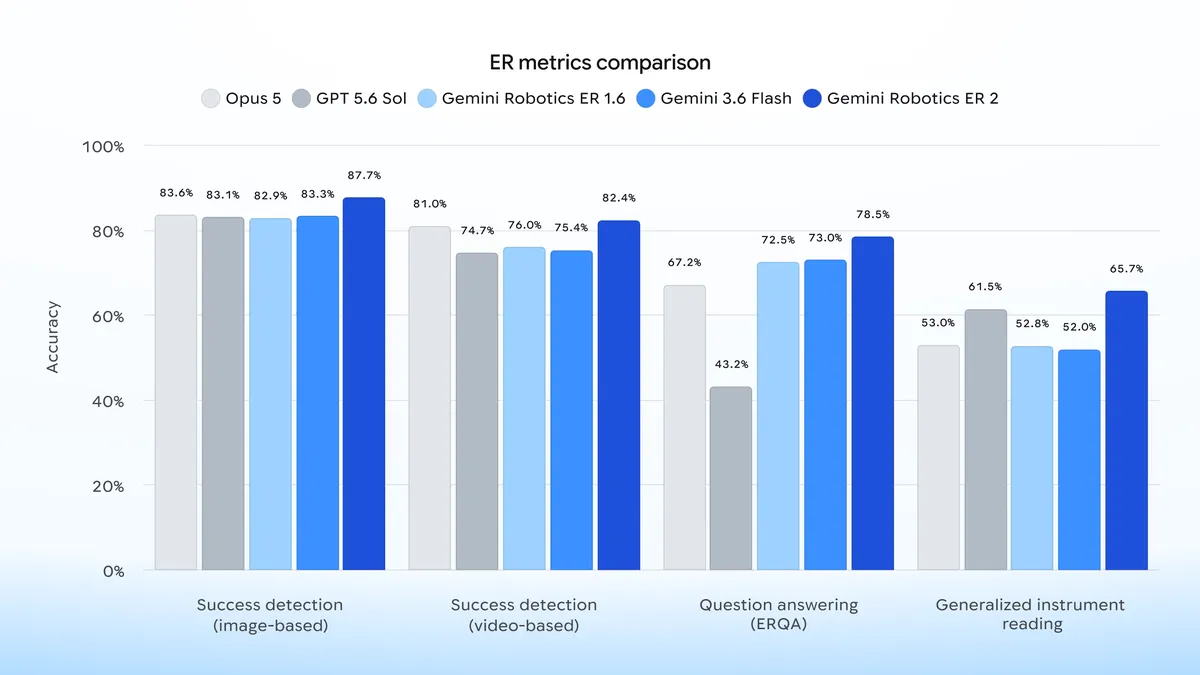
Gemini Robotics ER 2 advances our core spatial reasoning capability, as measured by three benchmarks:
- Success/failure detection: Now operates on raw video feeds rather than static snapshots to catch mid-execution failures like spills, slips, or misalignments.
- General instrument reading: Extends beyond circular dials and sight glasses to include digital displays, linear scales, rulers, and liquid thermometers. We tested it across 10 different types of instruments.
- Enhanced spatial VQA: Improves Visual Question Answering throughGemini’s advancements in multi-modal understanding.
Gemini Robotics ER 2 consistently achieves the highest accuracy across all core capabilities, with highlights including success detection (image/video), Question Answering (ERQA), and generalized instrument reading.
Advancing safety for embodied intelligence
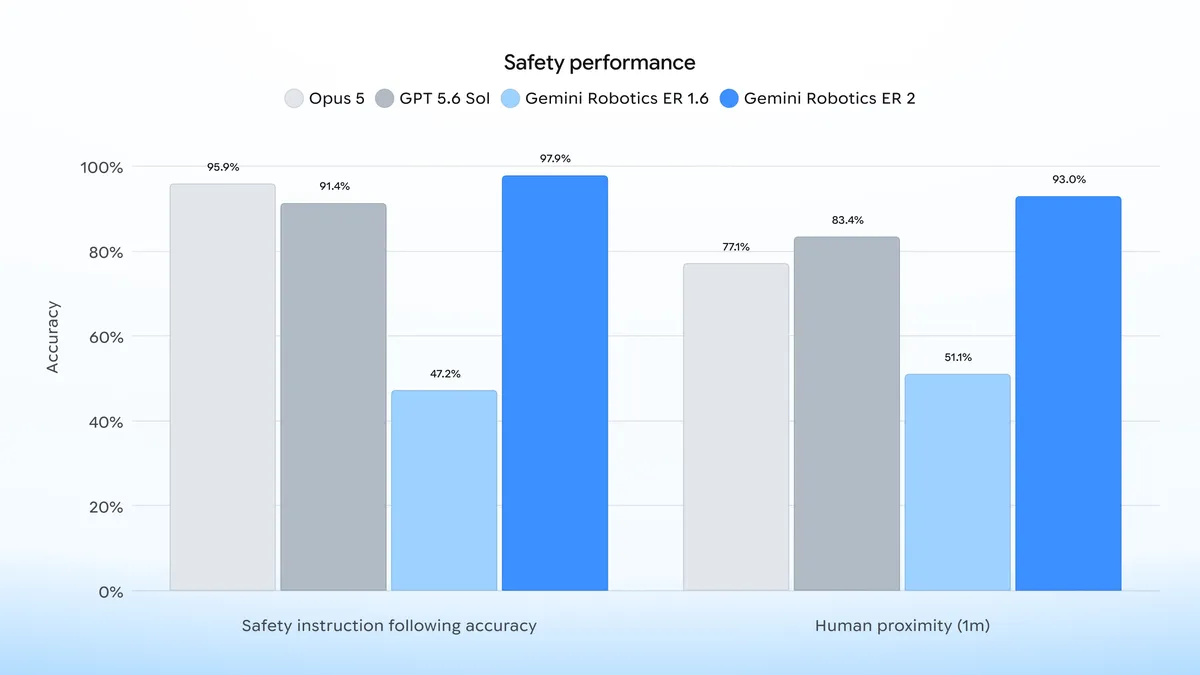
Gemini Robotics ER 2 is our safest model, achieving significant gains on Safety Instruction Following and Human Proximity benchmarks, which evaluate how a model adheres to physical constraints during reasoning tasks and spatial awareness for detecting humans. We found that Gemini Robotics ER 2 successfully halts a humanoid robot when a person is nearby and autonomously resumes work only once the area is clear. To advance safety for physical agents, we’re introducing a benchmark that evaluates a foundation model's ability to act as a safe VLA orchestrator by testing its capacity to enforce safety constraints, monitor the environment, assess physical feasibility, and seek human clarification. For details, see our safety technical report.
Gemini Robotics ER 2 outperforms ER 1.6 and other frontier models on Safety Instruction Following and Human Proximity benchmarks.
Looking ahead, our plans are to push these models towards even more complex tasks to accelerate the development of helpful robots and support the robotics community.
Get the latest news from Google in your inbox
Sign up for our newsletters with product updates, event information, special offers, and more.
Your information will be used in accordance with Google's privacy policy. You may opt out at any time.