







TL;DR
Which CDN is best?" is the wrong question the right one is "which CDNs are good enough right now?" This is the story of four attempts at CDN selection at Mux and the solution we finally built to answer it in 9.9ms.
CDN selection sounds simple: pick the best CDN for each viewer. But “best” is where it gets tricky. What does best even mean? Cheapest for the business? Fastest for the customer? Most reliable? Or, the one with the best support team so that when things eventually go wrong (and they will), you're not waiting days for a response? CDN selection is easy until it's not.
Since joining Mux five years ago, I’ve been involved in many attempts to revamp our CDN selection process. None have been perfect, but each one moved us forward and improved how we make decisions.
In the early days, our CDN selection ran on a third-party RUM (real user metrics) service. You’d send it an IP address, and it would tell you which CDN to use. It was eventually acquired and sunset, which pushed us to another RUM service. The new service worked similarly, with a few extra levers for traffic control. Switching between the two felt natural. They shared the same interface. Send an IP, get the “best” CDN back.
However, we quickly realized there were a few problems with this approach.
First and most noticeably we didn’t have fine-grained levers we could pull during outages to move traffic. At that point, our only option was to globally drain a CDN. Widespread CDN outages are rare; more often, we see smaller issues limited to a specific location. So we built more levers at both the location and customer level. That way, we could drain a CDN in specific locations or for specific customers. This logic lived after our calls to the RUM service. We always had the final say in which CDN was used.
The RUM data itself was also an issue. It’s collected from opt-in websites that embed scripts. On page load, the script makes requests for an image across several CDNs. The results are recorded and used to power CDN selection. But those images are permanently cached at the CDN edge, so the tests don’t measure CDN → origin, only CDN → website. If a CDN has an outage that affects its ability to reach origin, the RUM service can miss it. More importantly, these tests don’t hit our origins at all. We’ve seen cases where a specific CDN couldn’t communicate with our origin without it being a broader, service-wide outage.
We decided to take matters into our own hands. What started as a hackweek project evolved into our first fully Mux-owned CDN selection process. The service took the request IP, mapped it to a location, and looked up CDN performance for that location. The goal was to pick the CDN with the lowest latency based on our logs. After some testing, we ran into major issues and had to abandon the project.
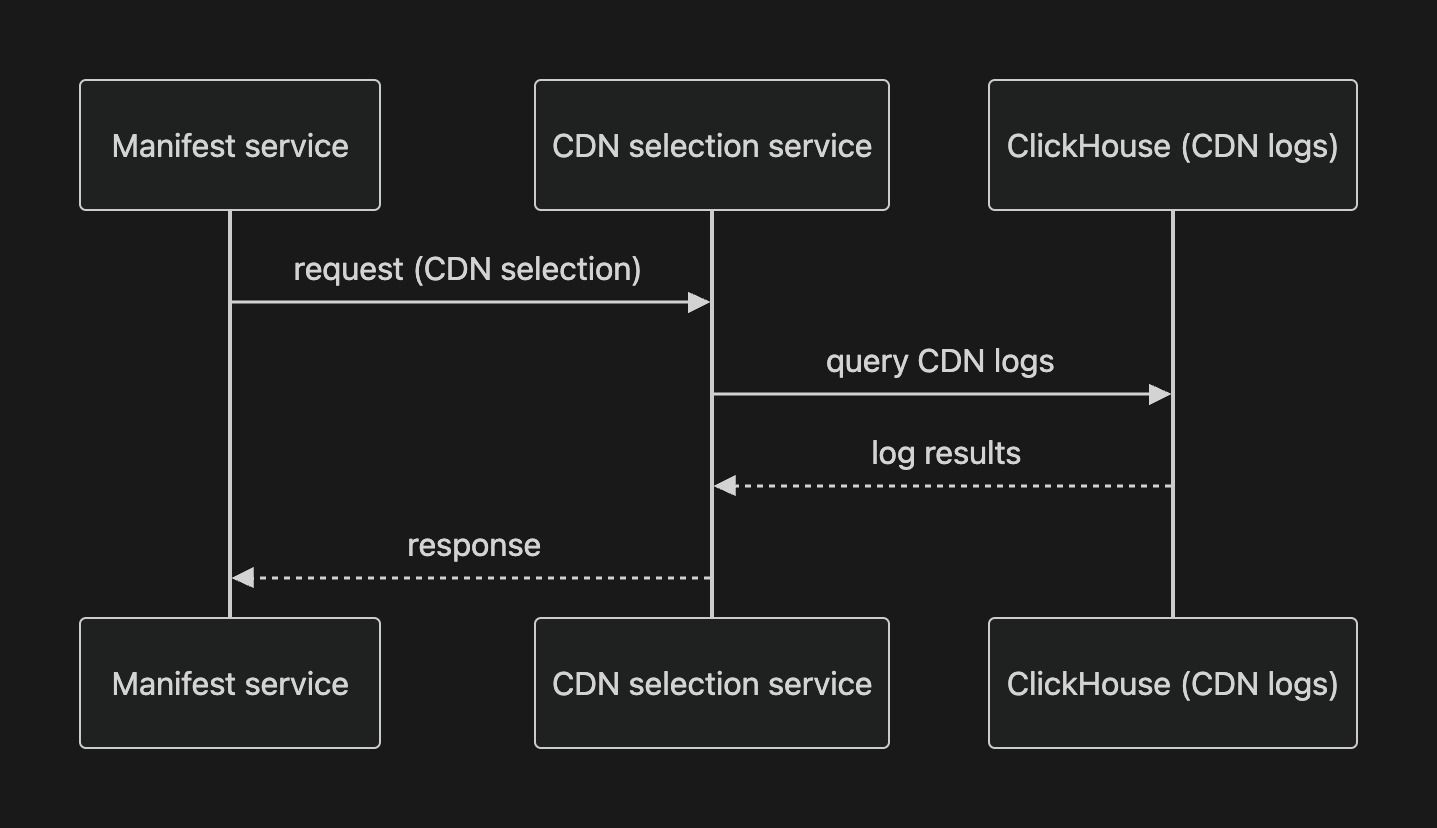
Using CDN logs as our only data source was a mistake. It created a snowball effect. Once the service decided to use CDN A, all logs came from CDN A and none from CDN B, which meant the system only had data about CDN A. Also, CDN logs are reliable for latency but not for availability. There’s no way to tell from the logs whether an error came from a CDN outage versus an origin issue versus something in our edge code.
We were also overly focused on getting the BEST CDN for each request, where “best” meant lowest latency. If CDN A had a p99 latency of 80ms and CDN B had a p99 latency of 78ms, we’d always pick CDN B. That led to lopsided selection ratios in cases where customers would never notice the difference.
Finally, we calculated p99 latency on the fly for every request. Selection was too slow, sometimes taking up to 700ms, and the extra load slowed downstream services.
No one can feel the difference between 78 and 80ms. Chasing the "best" cost us: we leaned too hard on one provider, which made us less resilient, and recomputing latency on every request slowed selection enough to drag on other services.
Inevitably, CDN selection resurfaced as a priority, and we decided to try again. The first thing I did was review our past attempts and list what we’d learned from each one.
At the same time, we'd added a third CDN to our pool. A and B are the traditional kind, the ones you picture when you hear “CDN” and that show up on the first page of Google. C is a collaboration with a partner to set up our own POPs, so it’s smaller, we don’t share its cache with other customers, and it has edge POPs in fewer regions. Most importantly, unlike A and B, it can’t scale infinitely. We decide when and how to scale it, and that isn’t instant. If we send it too much traffic, we’ll overwhelm the servers allocated to us and start dropping requests. That added a whole new dimension to the design.
The business context plays a role as well. Costs, performance, features, quality of support, and more all play a role. Now, when performance is equal (and C is at capacity), we’d rather use A than B.
With all of this in mind, we started designing the system. These were the requirements:
The CDN selection service has three components:
1. Health probes
HTTP requests we make against our CDNs. We run two test types: one that goes all the way through the CDN to origin, and one that’s answered at the CDN edge. Each test runs against every CDN in multiple locations around the world (and the origin test against all 4 of our origins) every 60 seconds. Results are recorded in our database.
2. Database
We use CockroachDB, a distributed SQL database that runs across multiple regions and clouds. It stores raw probe results, routing decisions, and CDN C's real-time usage metrics.
3. CDN router
The router runs in two modes, leader and server mode.
Leader mode runs three asynchronous jobs, each on its own interval:
Each decision pass looks back over the last 5 minutes of probe data, and we rerun it every minute. That rolling window keeps decisions stable against a single noisy probe, while still letting us detect issues and route new traffic away within about a minute.
Server mode decides which CDN a given request can use:
The caller serves the video from the first CDN.
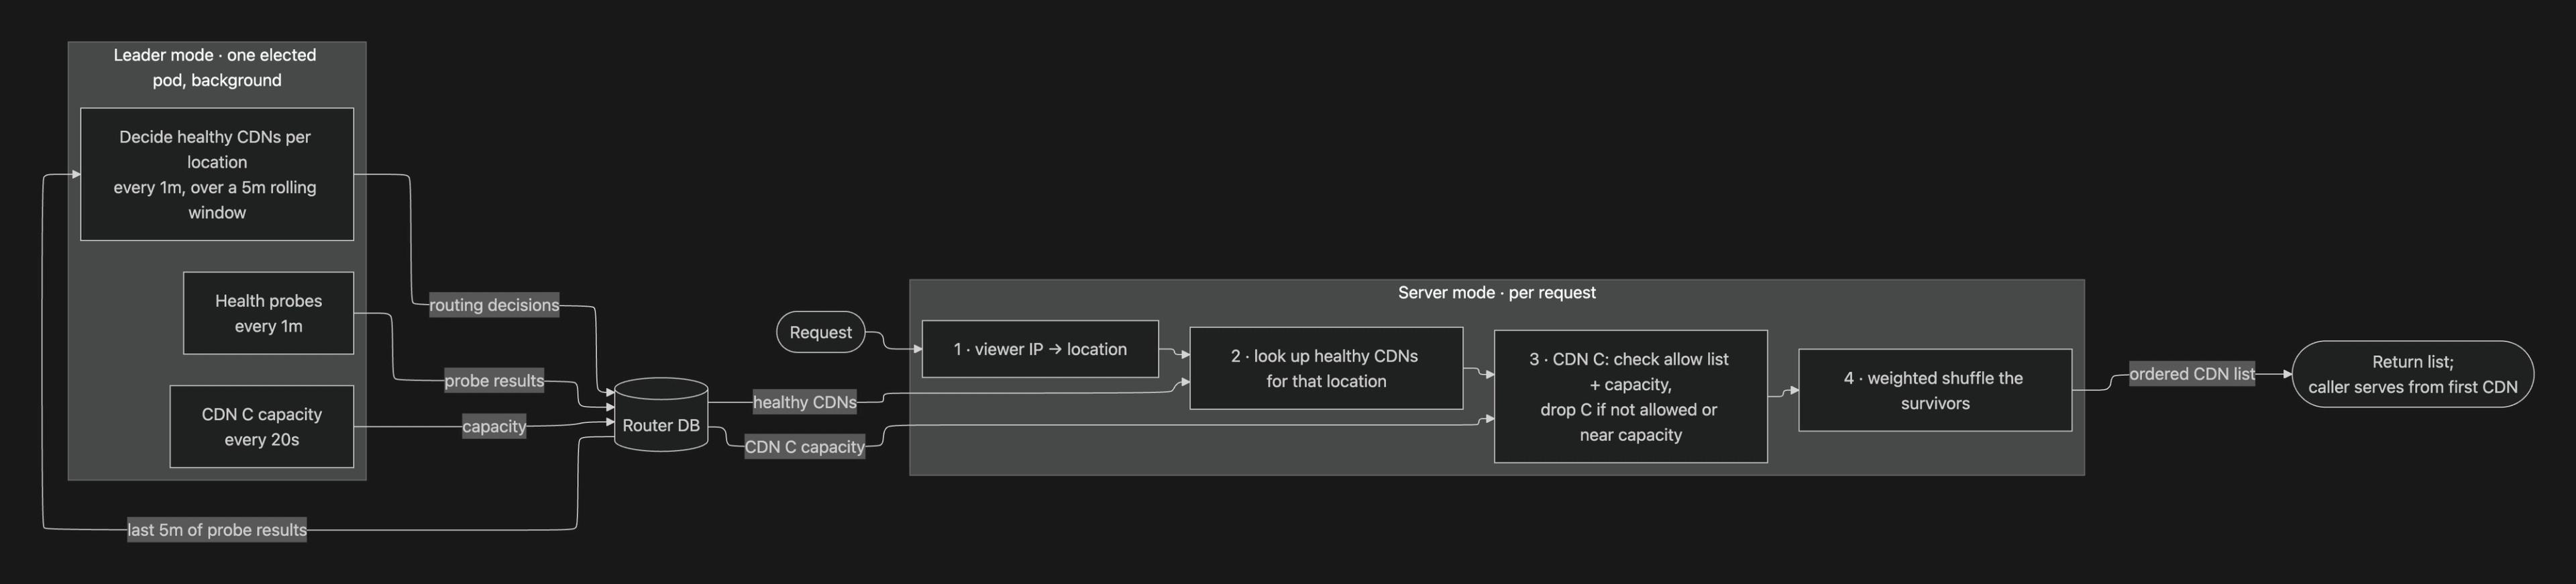
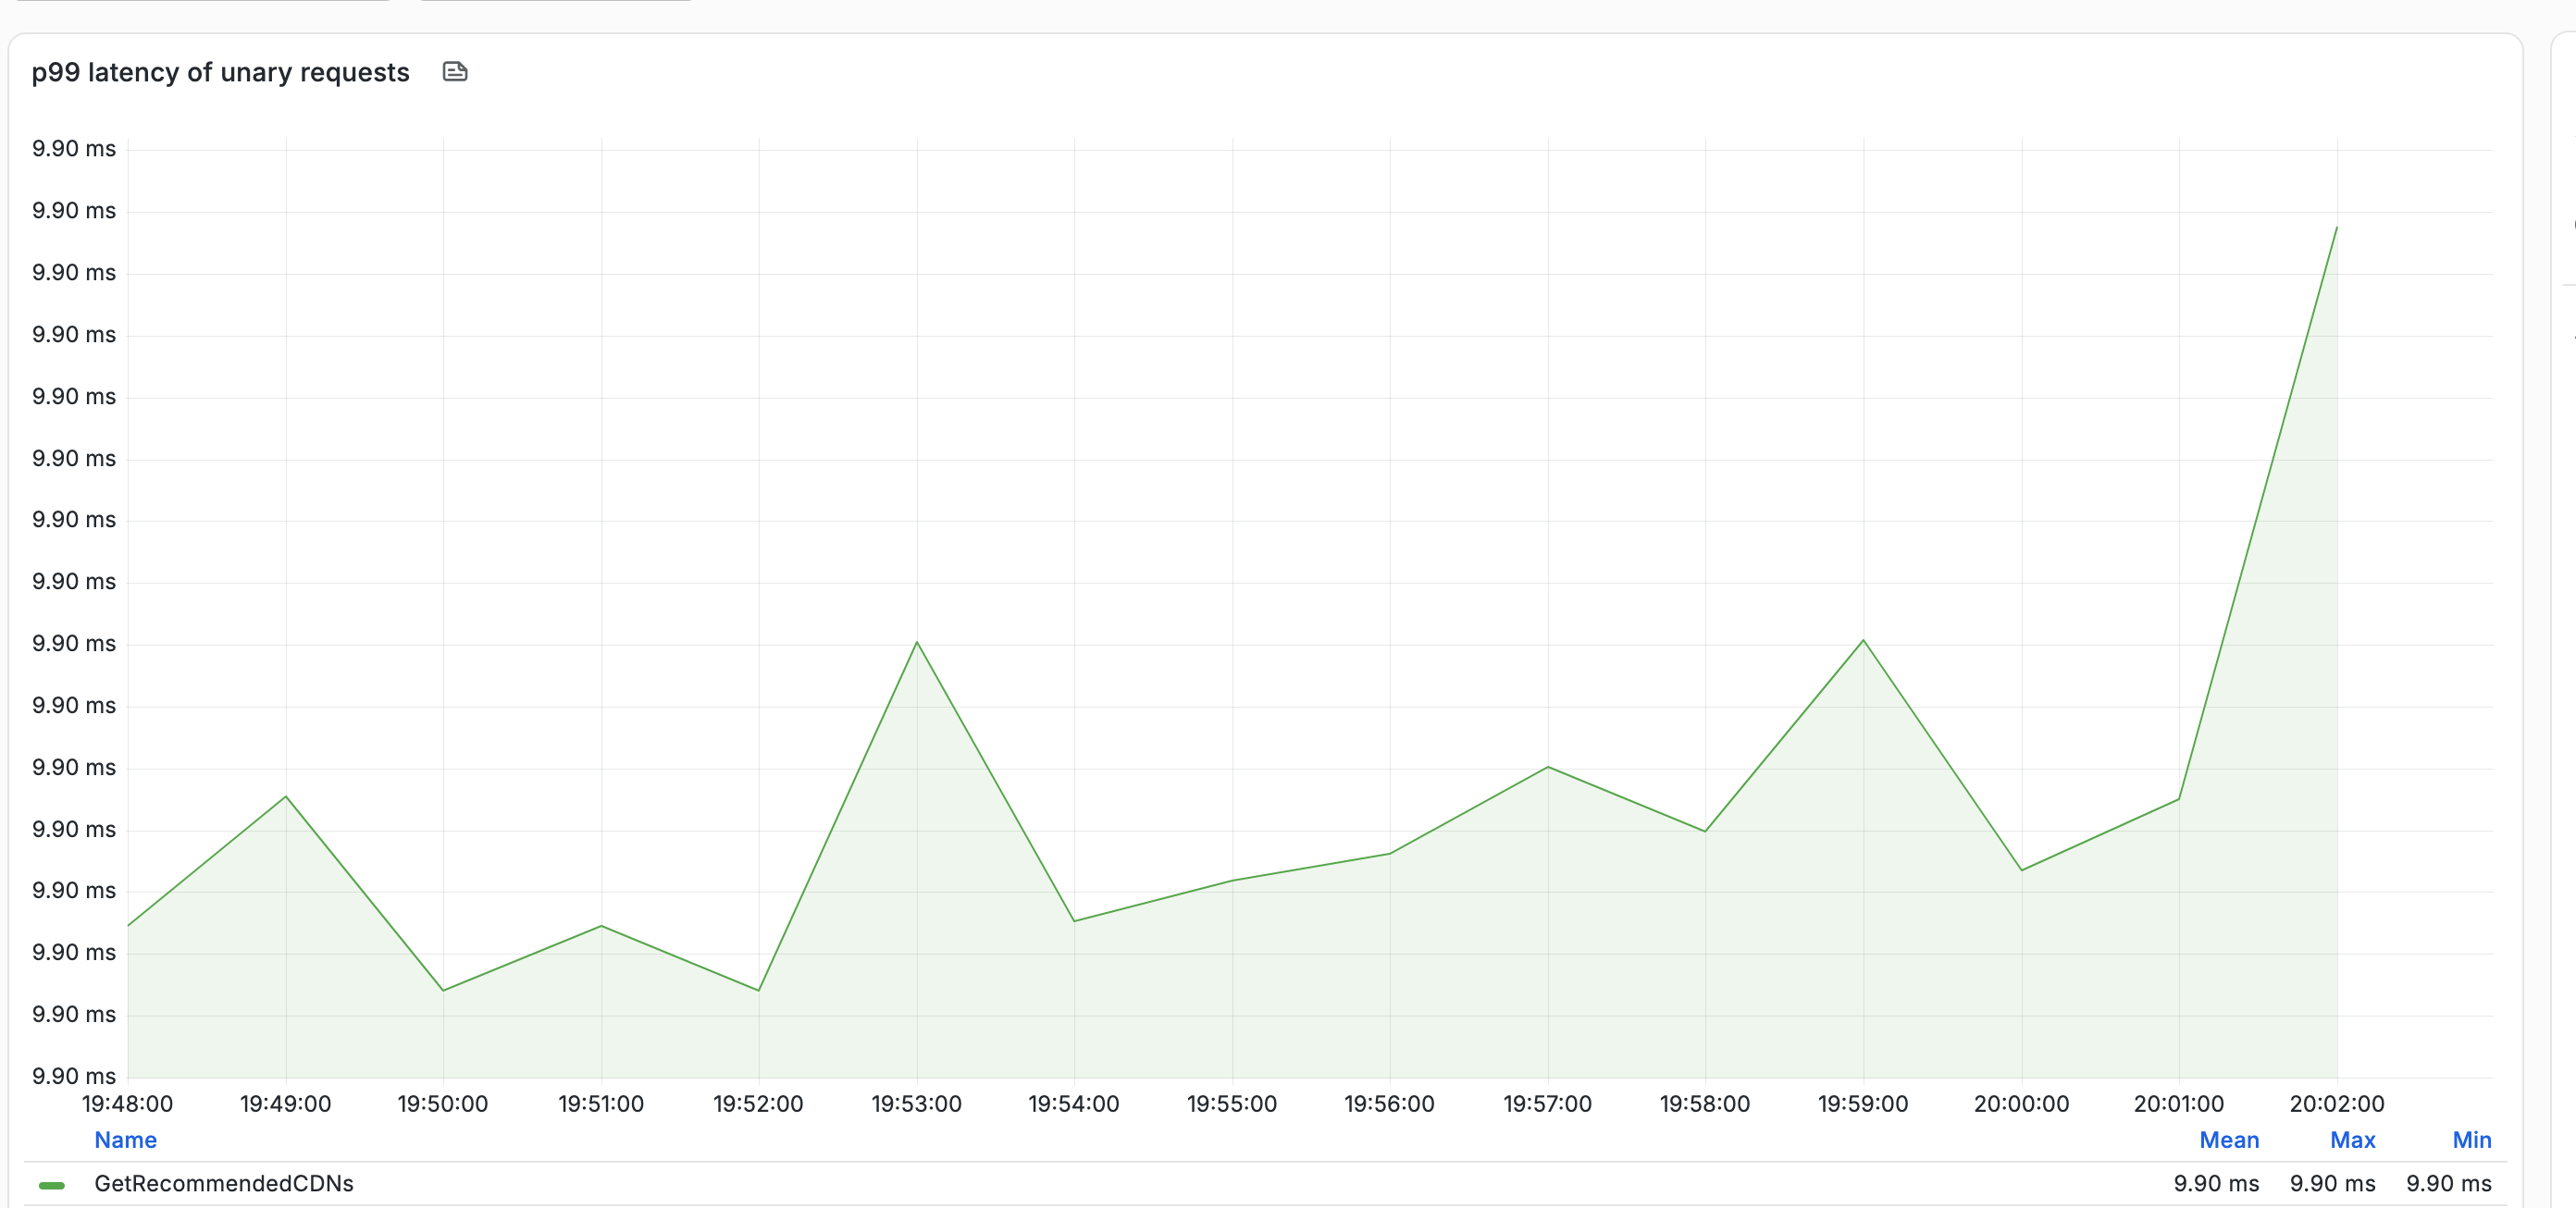
The result is super-fast CDN selection with a p99 of 9.9ms.
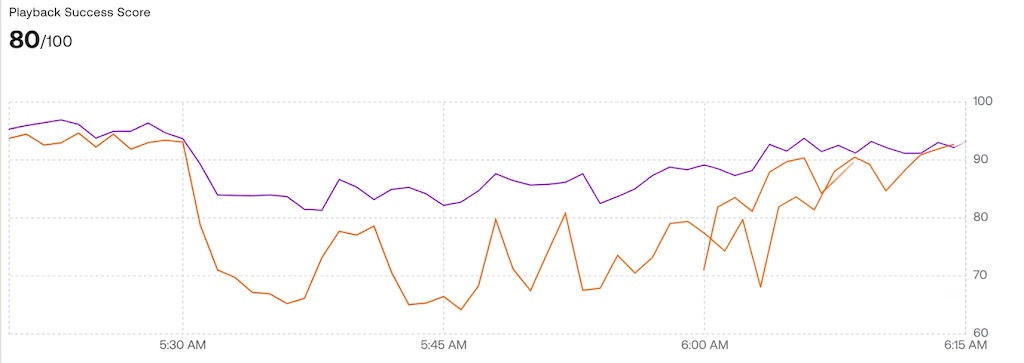
Our CDN selection runs when a viewer first loads a video. That means someone watching a long video could be assigned a healthy CDN at the start, only for that CDN to run into trouble by the time they reach the end. To address this, we released redundant stream support over 6 years ago. But because it was opt-in, most customers never used it. Recently, we flipped redundant streams to be opt-out instead of opt-in. Combined with our CDN selection, this means we’ll start you on the CDN we think is best while still giving your player the ability to switch mid-stream if something goes wrong.
The following image is from our redundant stream testing captured during a minor cdn outage. The purple line represents views that were using redundant streams. The orange represents views that were not.
The CDN router is live and fast, but we’re not done. There are two things we want to add. First, more data sources. We want to layer in additional data sources like CDN logs and real-time info from Mux Data. Second, content steering, which would let the player shift CDNs on its own and build even more resilience on top of our redundant stream support.
Four attempts in, what finally worked wasn’t a cleverer way to find the single best CDN. It was accepting that “best” is fuzzy and building a system that rules out CDNs that aren’t good enough, then spreading the remaining traffic on our terms. Owning the data end to end, keeping it independent of our own routing decisions, and pre-computing availability so the request path stays cheap is what got us to a 9.9ms p99.
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。