


One of the most common requests I've gotten from users of my little Firefox extension(https://timewasterpro.xyz) has been more options around the categories of websites that you get returned. This required me to go through and parse the website information to attempt to put them into different categories. I tried a bunch of different approaches but ended up basically looking at the websites themselves seeing if there was anything that looked like a tag or a hint on each site.
This is the end conclusion of my effort at putting stuff into categories.
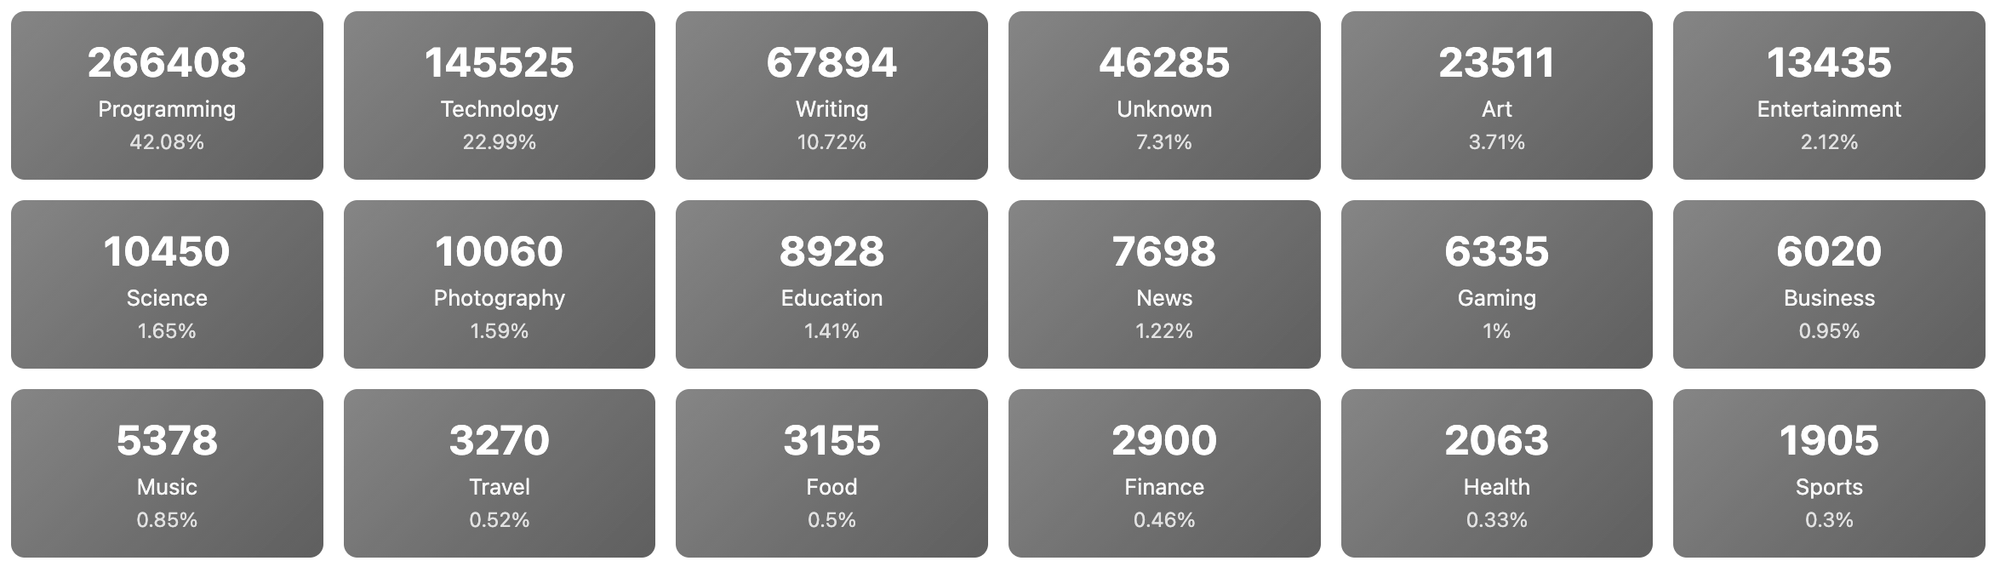
Unknown just means I wasn't able to get any sort of data about it. This is the result of me combining Ghost, Wordpress and Kagi Small Web data sources.
Interestingly one of my most common requests is "I would like less technical content" which as it turns out is tricky to provide because it's pretty hard to find. They sorta exist but for less technical users they don't seem to have bought into the value of the small web own your own web domain (or if they have, I haven't been able to figure out a reliable way to find them).
This is an interesting problem, especially because a lot of the tools I would have previously used to solve this problem are....basically broken. It's difficult for me to really use Google web search to find anything at this point even remotely like "give me all the small websites" because everything is weighted to steer me away from that towards Reddit. So anything that might be a little niche is tricky to figure out.
Interesting findings
So there's no point in building a web extension with a weighting algorithm to return less technical content if I cannot find a big enough pool of non-technical content to surface. It isn't that these sites don't exist its just that we never really figured out a way to reliably surface "what is a small website".
So from a technical perspective I have a bunch of problems.
- First I need to reliably sort websites into a genre, which can be a challenge when we're talking about small websites because people typically write about whatever moves them that day. Most of the content on a site might be technical, but some of it might not be. Big sites tend to be more precise with their SEO settings but small sites that don't care don't do that, so I have fewer reliable signals to work with.
- Then I need to come up with a lot of different feeding systems for independent websites. The Kagi Small Web was a good starting point, but Wordpress and Ghost websites have a much higher ratio of non-technical content. I need those sites, but it's hard to find a big batch of them reliably.
- Once I have the type of website as a general genre and I have a series of locations, then I can start to reliably distribute the types of content you get.
I think I can solve....some of these, but the more I work on the problem the more I'm realizing that the entire concept of "the small web" had a series of pretty serious problems.
- Google was the only place on Earth sending any traffic there
- Because Google was the only one who knew about it, there never needed to be another distribution system
- Now that Google is broken, it's almost impossible to recreate that magic of becoming the top of list for a specific subgenre without a ton more information than I can get from public records.