惯性聚合 高效追踪和阅读你感兴趣的博客、新闻、科技资讯
阅读原文 在惯性聚合中打开

推荐订阅源

钛媒体:引领未来商业与生活新知
钛媒体:引领未来商业与生活新知
Hugging Face - Blog
Hugging Face - Blog
奇客Solidot–传递最新科技情报
奇客Solidot–传递最新科技情报
人人都是产品经理
人人都是产品经理
Microsoft Azure Blog
Engineering at Meta
Engineering at Meta
B
Blog RSS Feed
大猫的无限游戏
大猫的无限游戏
博客园_首页
雷峰网
雷峰网
V
Visual Studio Blog
爱范儿
爱范儿
A
About on SuperTechFans
量子位
N
Netflix TechBlog - Medium
Microsoft Security Blog
让小产品的独立变现更简单 - ezindie.com
MongoDB | Blog
MongoDB | Blog
U
Unit 42
Cyber Security Advisories - MS-ISAC
月光博客
月光博客
S
SegmentFault 最新的问题
J
Java Code Geeks
H
Hackread – Cybersecurity News, Data Breaches, AI and More

Proxmox Support Forum

[SOLVED] - Github Auth for Mirrors-Kernel Repo? [Automation] Mass migration tool for MS Win11/Server Proxmox GUI hang - not response is it possible to reject or quarantine spam based on conditions I set ? The PVENode task list in PVE9 is partially obscured due to the terminal font being too large. About 100% error reporting due to pveproxy.service hooks Kubernetes overlay networking breaks when upgrading from PVE 9.1 to PVE 9.2.3 Zentraler Speicher No space left on device Combine datastore and direct file archival to tape Kernel panic VFS: Unable to mount root fs on unknown-block (0,0) sobald ein 7.x Kernel verwendet wird. How to migrate disk of a VM from one ZFS to another Windows Server 2025 fails to boot after PVE 9.2 / Linux 7.0 Kernel upgrade Cannot Install Proxmox on T610 Poweredge with H700 PERC card sdn Config. gateway not reachable How to safely change domain/FQDN? Welche Filterquote erreicht ihr? NFS Share status unknown on 2 of 5 nodes Can't connect to PVE9 consoles [solved] Can't connect to PVE9 consoles [solved] [SOLVED] - Use secondary network for PVE commands Created cluster, one node storage gone BUG: proxmox mail gateway FROM = null bypass spam filtering Moving existing PBS from VMWare workstation to PVE cluster Does eBGP SDN fabric support external peering? Bug: PDM 1.1 not recognizing valid license status Proxmox GUI hang - not response PVE crashes unexpectedly Proxmox Backup Server 4.2 released! Advice
Ceph constantly adding PG
invalid@exam · 2026-06-23 · via Proxmox Support Forum

Hello!

Quick recap: I have 5 hosts, 5 x 4TB (enterprise SSD, Micron Pro) per host with Ceph on its own 10Gbp network. All has been running great for about 6 months.

Last night I had a server host kernel panic. I rebooted the host. All came up just fine, cluster returned to HEALTH_OK within minutes, and the rebalancing begun. Now I think it had started to rebalance prior to me getting to the host, but when the existing PGs came alive on the rebooted host, the rebalance appeared to go pretty quick.

Almost 12 hours later, and its still rebalancing. However, I started with 256 PG, and now its up to 344.
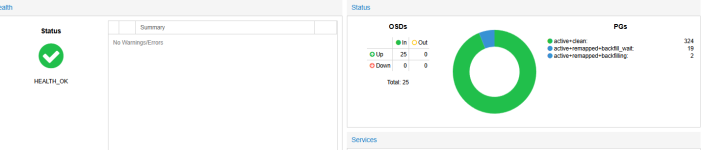
1782146268982.png

Watching the logs, I don't see any issues about hardware failure, or stuck PG. Would that status here show me a stuck PG? Is it just doing its thing, and will continue to grow PG until it feels it is happy? Why was 256 ok for the longest time, but last night started growing? Did it just not want to / need to?
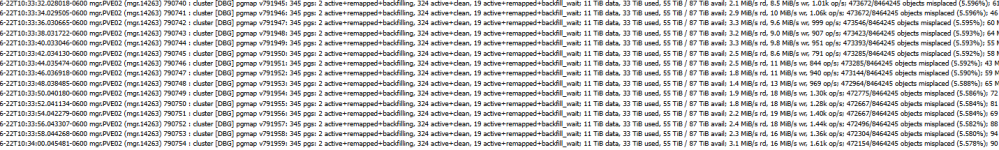
1782146347505.png

One thing that to note, the misplaced objects, will drop to about 427k, and then something happens and its back to 490k and works its way down.

Much appreciated for your input!
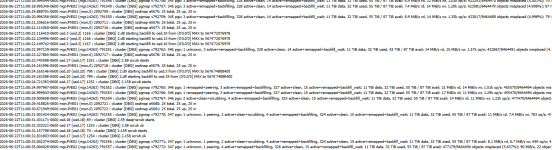
Update: I was able to catch it when the PG jumped another one and this is in the logs.

1782147744128.png

1782147751091.png

Appears to me it just wants to make more PG? <shrug>

Thanks!

check ceph balancer status. it probably increased the pg count from 256 to 512, and you're seeing it doing its thing in real time.

I see this:

root@PVE01:~# ceph balancer status
{
"active": true,
"last_optimize_duration": "0:00:00.000217",
"last_optimize_started": "Mon Jun 22 11:29:39 2026",
"mode": "upmap",
"no_optimization_needed": true,
"optimize_result": "Too many objects (0.055091 > 0.050000) are misplaced; try again later",
"plans": []
}
root@PVE01:~#
1782149489815.png

Ideas? Thank you!