







Share this letter & I’ll send you some rewards for the referrals.
You’ve rewritten the prompt five times, but the AI model still ignores your format…
It returns clean JSON on one request but “broken” JSON on the next. The tone you asked for doesn’t last either… No matter how you write the instructions, the model won’t follow them "reliably”.
So how do you make the behavior stick?
Getting there takes a series of judgment calls, each one yours to make…
Onward.

Agents can generate code. Getting it right for your system, team conventions, and past decisions is the hard part. You end up wasting time and tokens in correction loops.
More MCPs give agents access to information, but not understanding. The teams pulling ahead use a context layer to give agents exactly what they need.
Join live on Sep 2 (FREE) to see:
Where teams get stuck on the AI maturity curve
How a context layer solves for quality, efficiency, and cost
Live demo: the same coding task with and without a context layer
(Thanks to Unblocked for partnering on this newsletter.)
I want to introduce Dimple Sharma as a guest author.

Dimple is an AI engineer. Previously, she worked as a software engineer at Microsoft & Samsung.
At Microsoft, she built security infrastructure for SharePoint Online, serving millions of users. At Samsung, she developed a reinforcement-learning system for real-time video streaming, shipped in Samsung HD Displays.
She also holds two patents & a published research paper.
Today she builds applied AI systems and writes about how they work. She has a knack for taking a complex topic apart until it clicks into a clear mental model, with the precision of an engineer who has built production systems at scale.
You can follow her on:
Here’s what’s inside this newsletter:
Fine-tuning is probably not where you should start. The decision framework for when fine-tuning makes sense, when prompting/RAG is enough, and red flags that tell you to stop before spending money on training.
LoRA changed the economics of fine-tuning. Why updating a tiny fraction of a model’s parameters can be enough to specialize an LLM, and how QLoRA pushes hardware requirements even lower.
SFT, RLHF, DPO, ORPO, KTO, GRPO. The modern fine-tuning landscape, what these techniques are designed to teach a model, and where each one fits.
Fine-tuning now goes far beyond better text responses. Reasoning, reliable tool use, function calling, and multimodal models can all require specialized training approaches.
Getting a better benchmark score can hide a worse model. Production failure modes that can appear after training, including overfitting, catastrophic forgetting, and safety degradation.
The complete path from base model to production. Model selection, dataset preparation, training, evaluation, deployment, monitoring, and continual fine-tuning, including what to watch at each stage.
Fine-tuning never starts from scratch…
You take a model that already works & train it a little more on a small, curated dataset of your own examples showing the exact behavior you want. Each example nudges the model’s weights1, the billions of numbers shaping its output. Run enough of them, & the behavior becomes the model’s new default.
It’s a “permanent” physical edit to the model.
But it’s NOT always the best choice…
It’s expensive in data, compute & maintenance. So don’t reach for it by reflex when a sharper prompt/retrieval step would have solved your problem for far less.
Before you train anything, learn fine-tuning’s capabilities & limits. Plus learn how it differs from prompting, retrieval & agents…
Fine-tuning changes model behavior reliably…
It shapes tone, voice, response style, format compliance (JSON, templates), domain-specific reasoning patterns, response persona, and consistent structured outputs.
Consider a support team’s resolved tickets:
Feed the model thousands of (ticket, ideal response) pairs, and it stops sounding like generic internet text. Instead, it starts responding in the team’s voice, consistently. Escalation paths, tone with a difficult customer, phrasing refined over years--the model learns all of it.
The change lives in the weights, NOT in a system prompt.
Yet adding new factual knowledge is where it becomes “unreliable”…
Forcing new facts through fine-tuning can make the model hallucinate. This is called the Superficial Alignment Hypothesis2. Pretraining builds knowledge; fine-tuning shapes “how” the knowledge comes out by default.
When the gap is knowledge instead of behavior, fine-tuning is often NOT the best fix.
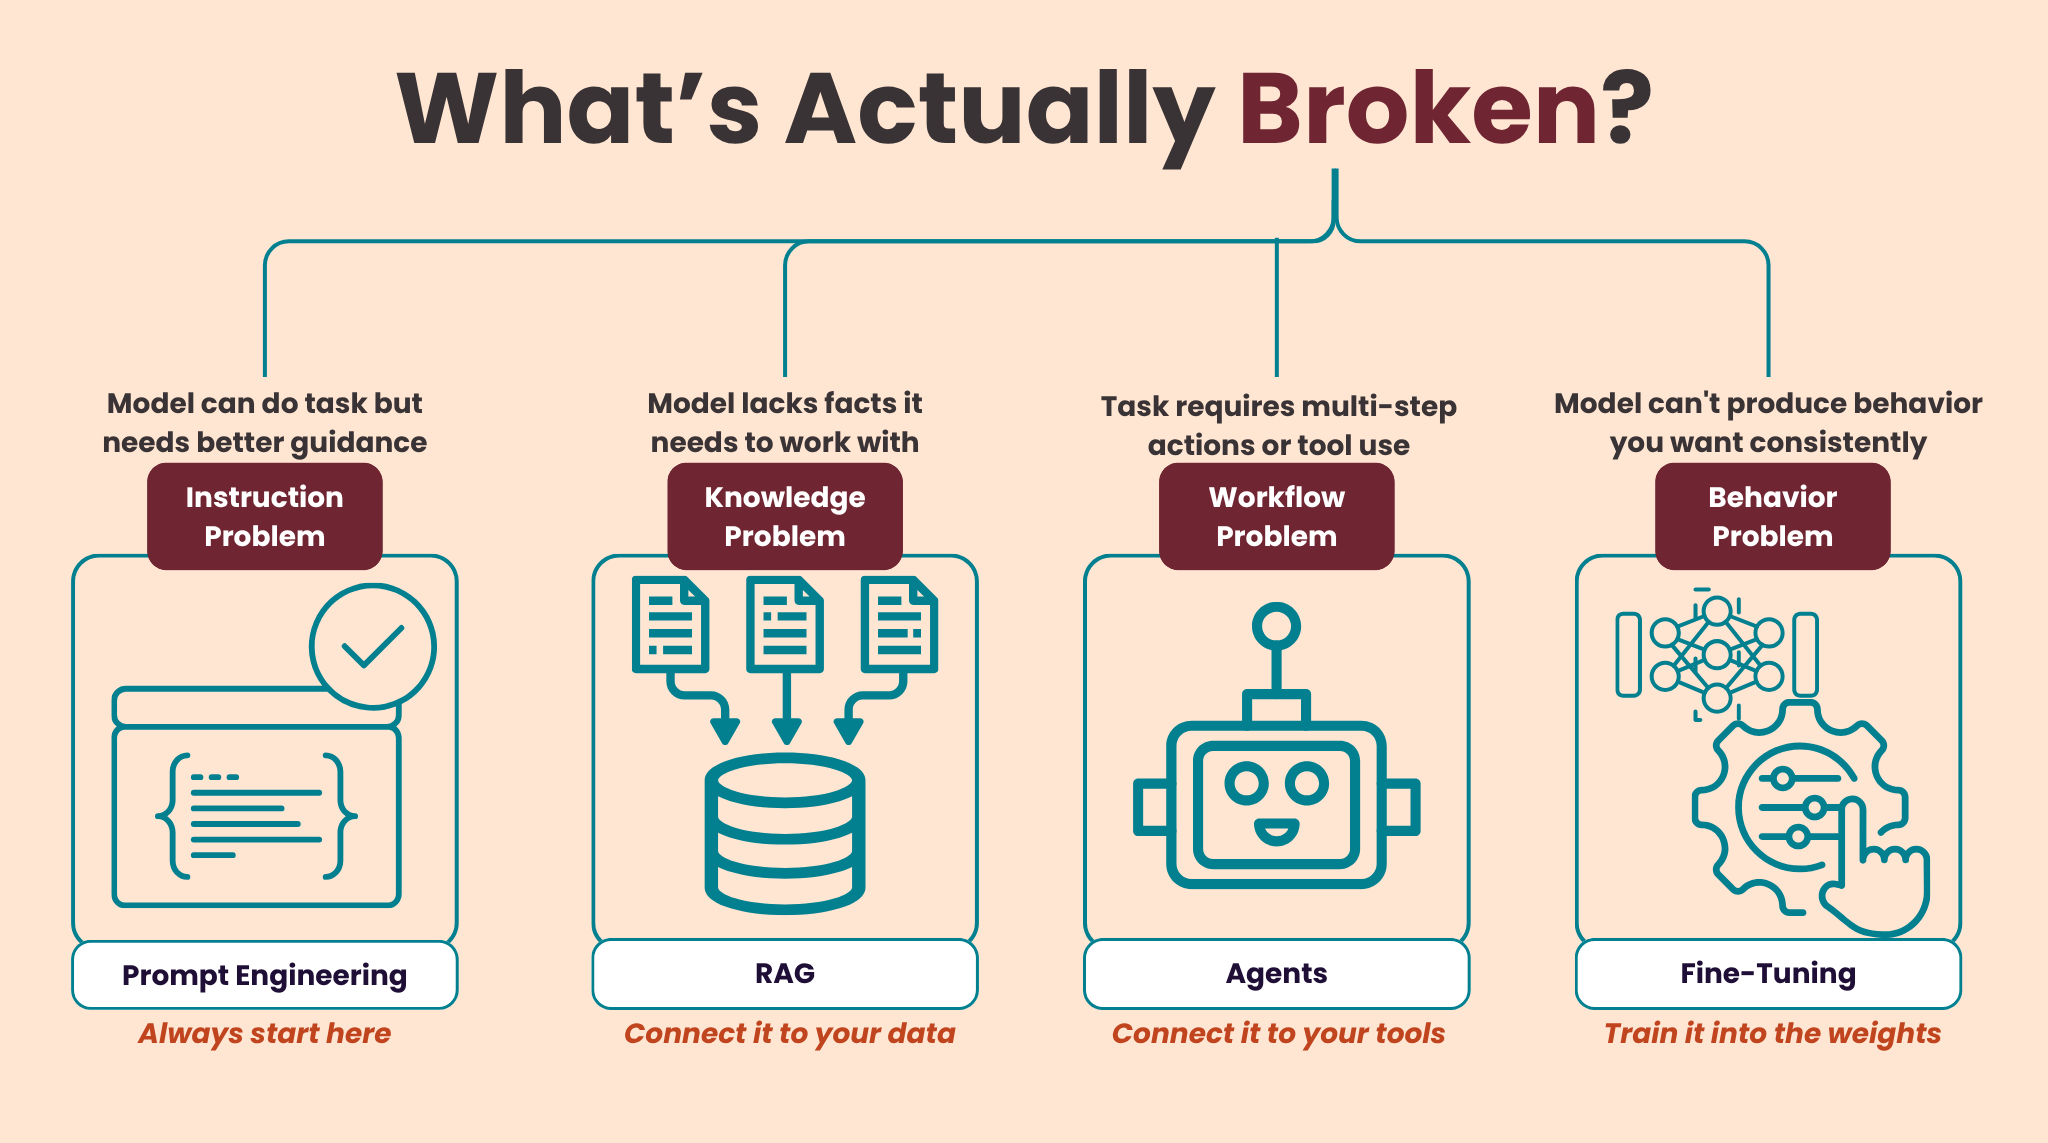
So which tool a problem needs depends on what’s actually broken…
Imagine your model gives solid answers to some questions but hallucinates on others. It follows your format instructions one moment & ignores them the next.
So what do you fix: prompt, data, model, or workflow?
Think of your LLM as a new hire at your company:
Prompt engineering is how you give instructions: format, tone, constraints. Like writing your new hire a detailed brief before every assignment. It’s cheap, fast, and often enough. But you can’t instruct someone to know things they were never taught.
Retrieval-Augmented Generation (RAG) is how you supply knowledge. You pull relevant documents from a database & feed them into the prompt, so the model stays “current” without retraining. Like handing your hire the company’s latest documentation before they answer a client.
Agents are how you enable action. You give the model access to tools, APIs, and external systems, and then let it decide how to complete a goal. Like giving your hire access to the company’s CRM, email, and databases, then trusting them to pick the right tool.
Fine-tuning is how you teach behavior. You train the model on curated examples of what you want it to do, and the change lasts. Like sending your hire through a specialized training program--they come back with a skill baked into how they work.
Now notice what actually changed in each case…
Prompt engineering, RAG, and agents work “around” the model: they shape what goes in/what the model can access, but the model itself stays identical. Not a single weight moves.
While fine-tuning “works” on the model.
i.e., the model comes out different from what went in.
Prompt engineering costs tokens.
RAG adds retrieval infrastructure: a vector database, an embedding model, a pipeline.
Agents multiply LLM calls per task and add orchestration overhead.
Fine-tuning demands GPU compute, curated data, and iteration cycles.
Start with the cheapest option; in production, these often combine…
So should you fine-tune?
Whether to fine-tune comes down to a few clear signals--some say stop, some say go:
Prompting still works. Try using a detailed system prompt, few-shot examples3, and clear format instructions first. Only then think about fine-tuning.
Your data changes frequently. Fine-tuning bakes a snapshot into weights. Live data goes stale at deployment; this is what RAG is for.
You don’t have enough quality data. Quality & representativeness of training data matter more than volume. If your examples don’t cover edge cases, the count doesn’t save you.
Your requirements keep changing. Fine-tuning cycles take days to weeks. If requirements are still shifting, the spec will have changed by the time your training run finishes.
You need instant rollback. Fine-tuning encodes behavior. If something goes wrong, there’s no quick patch; fixing it means retraining and redeploying.
Your structured output keeps breaking. The model handles familiar inputs but breaks on “edge cases” even with explicit formatting instructions. Fine-tuning bakes the format into behavior.
You need a specific voice/persona. Prompting cannot reliably hold a distinctive tone at scale. Fine-tuning makes it the model’s default, not a request.
Your inference costs are unsustainable. Fine-tuning a smaller open-source model on your specific task can match the same performance at a fraction of the cost. You pay for generality only when you need it.
You have a well-defined, narrow task. When the problem is bounded (classification, extraction, structured generation4), a fine-tuned small model consistently outperforms a large general one. The narrower the task, the bigger the advantage.
Your data can’t leave your infrastructure. GDPR, HIPAA5, and/or internal policy blocks you from sending training data to a third-party API. Self-hosted open-source fine-tuning keeps everything on-premises.
If the green flags fit, one question remains before you commit: what are you taking on?
Fine-tuning costs money to build & saves money to run.
The build cost is higher than it looks; per-call savings are larger than the GPU bill alone suggests.
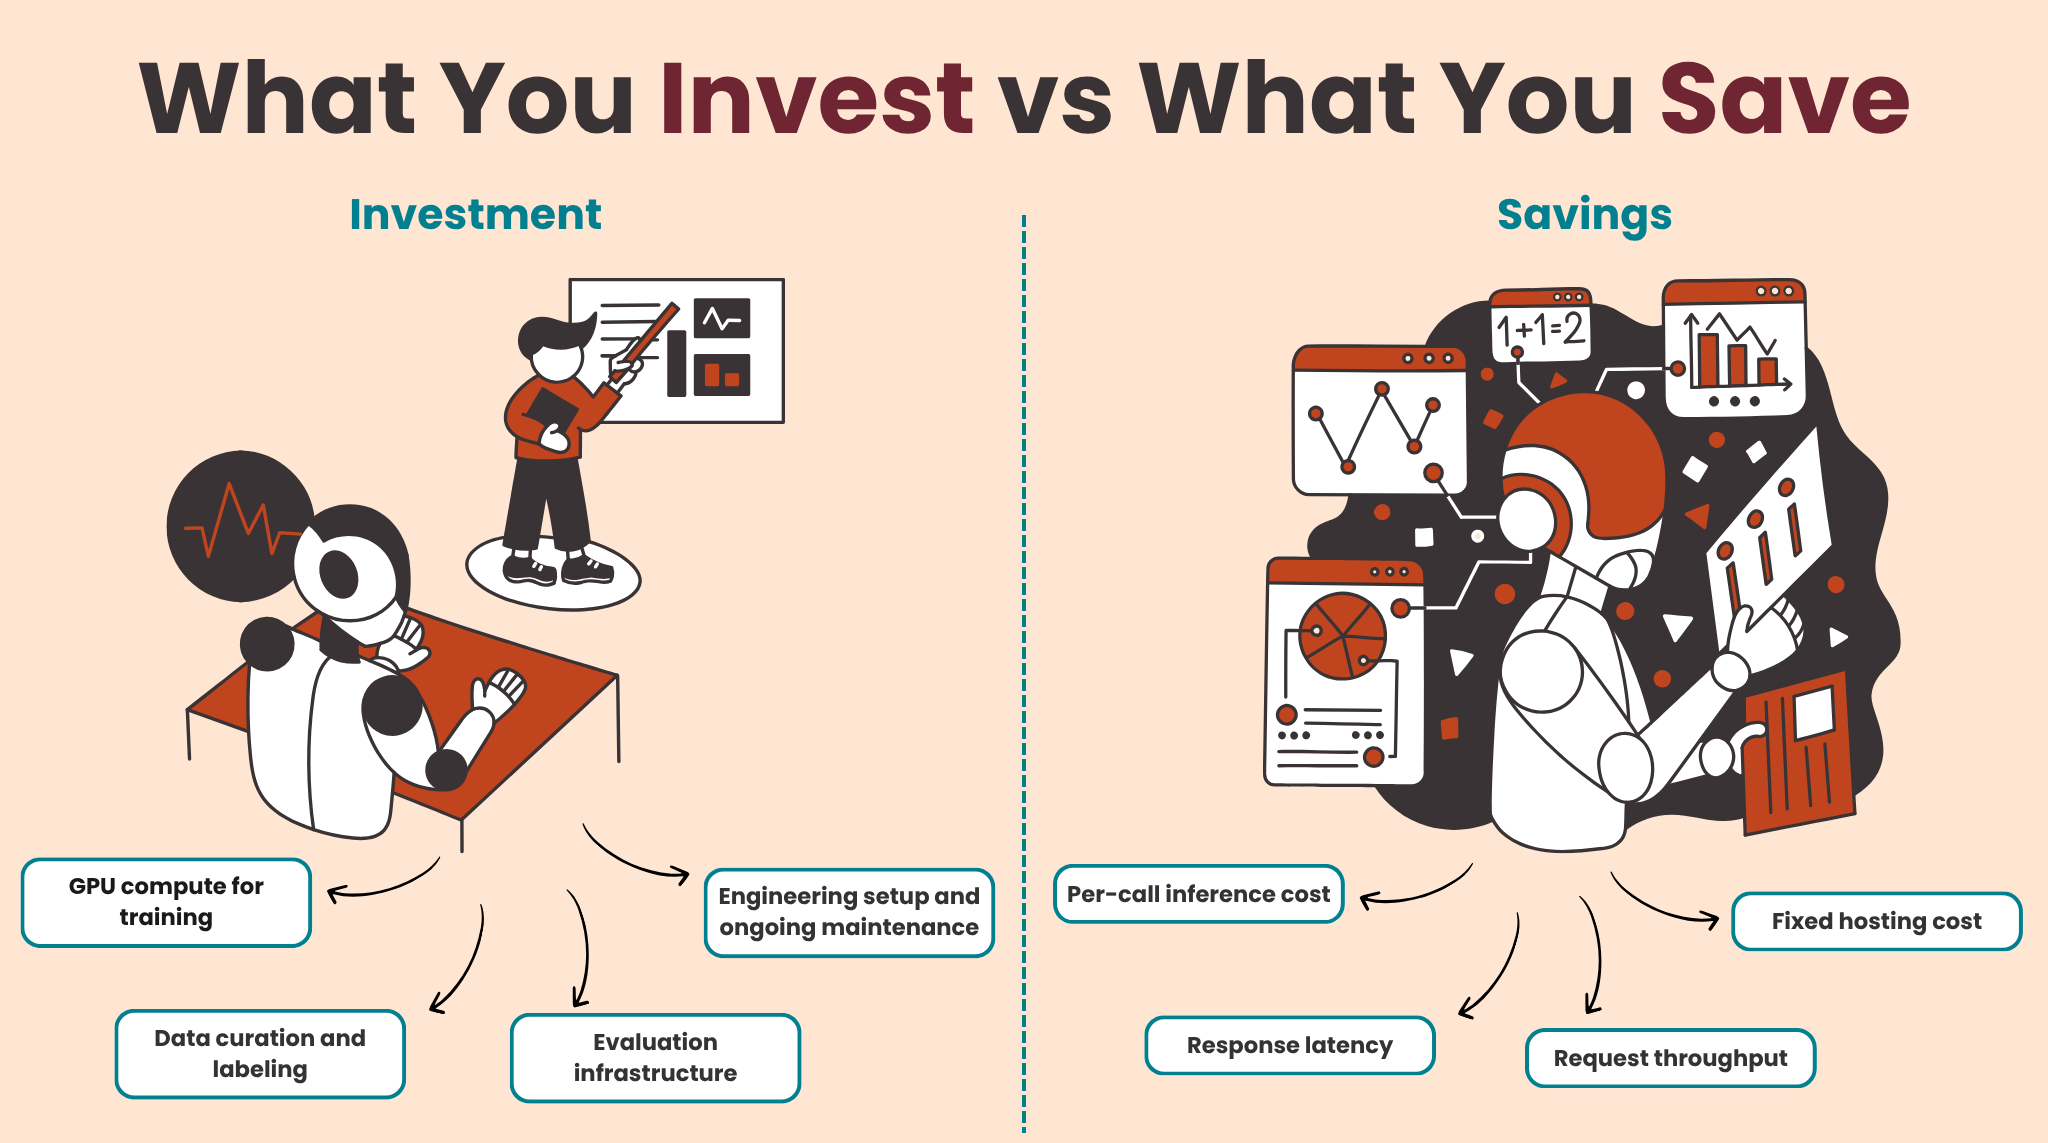
The investment pays off in three cases:
You have high & steady inference volume.
You’re replacing a costly frontier model API.
Your data must stay within your infrastructure.
Task fine-tuning carries one more cost not shown above: it can “erase” the model’s built-in safety behaviors. So budget for safety evaluation as part of every training cycle.
First, the groundwork…
So you’ve decided to fine-tune… but first you need to know where fine-tuning fits in a model’s lifecycle & which kind of model you start from.
When you fine-tune a model, you’re changing one thing: numbers inside.
Those numbers are parameters: weights packed into every layer. Your text enters as tokens; attention connects them across context. Each layer transforms the representation using those weights. Fine-tuning updates them on your data6.
Everything else stays fixed…
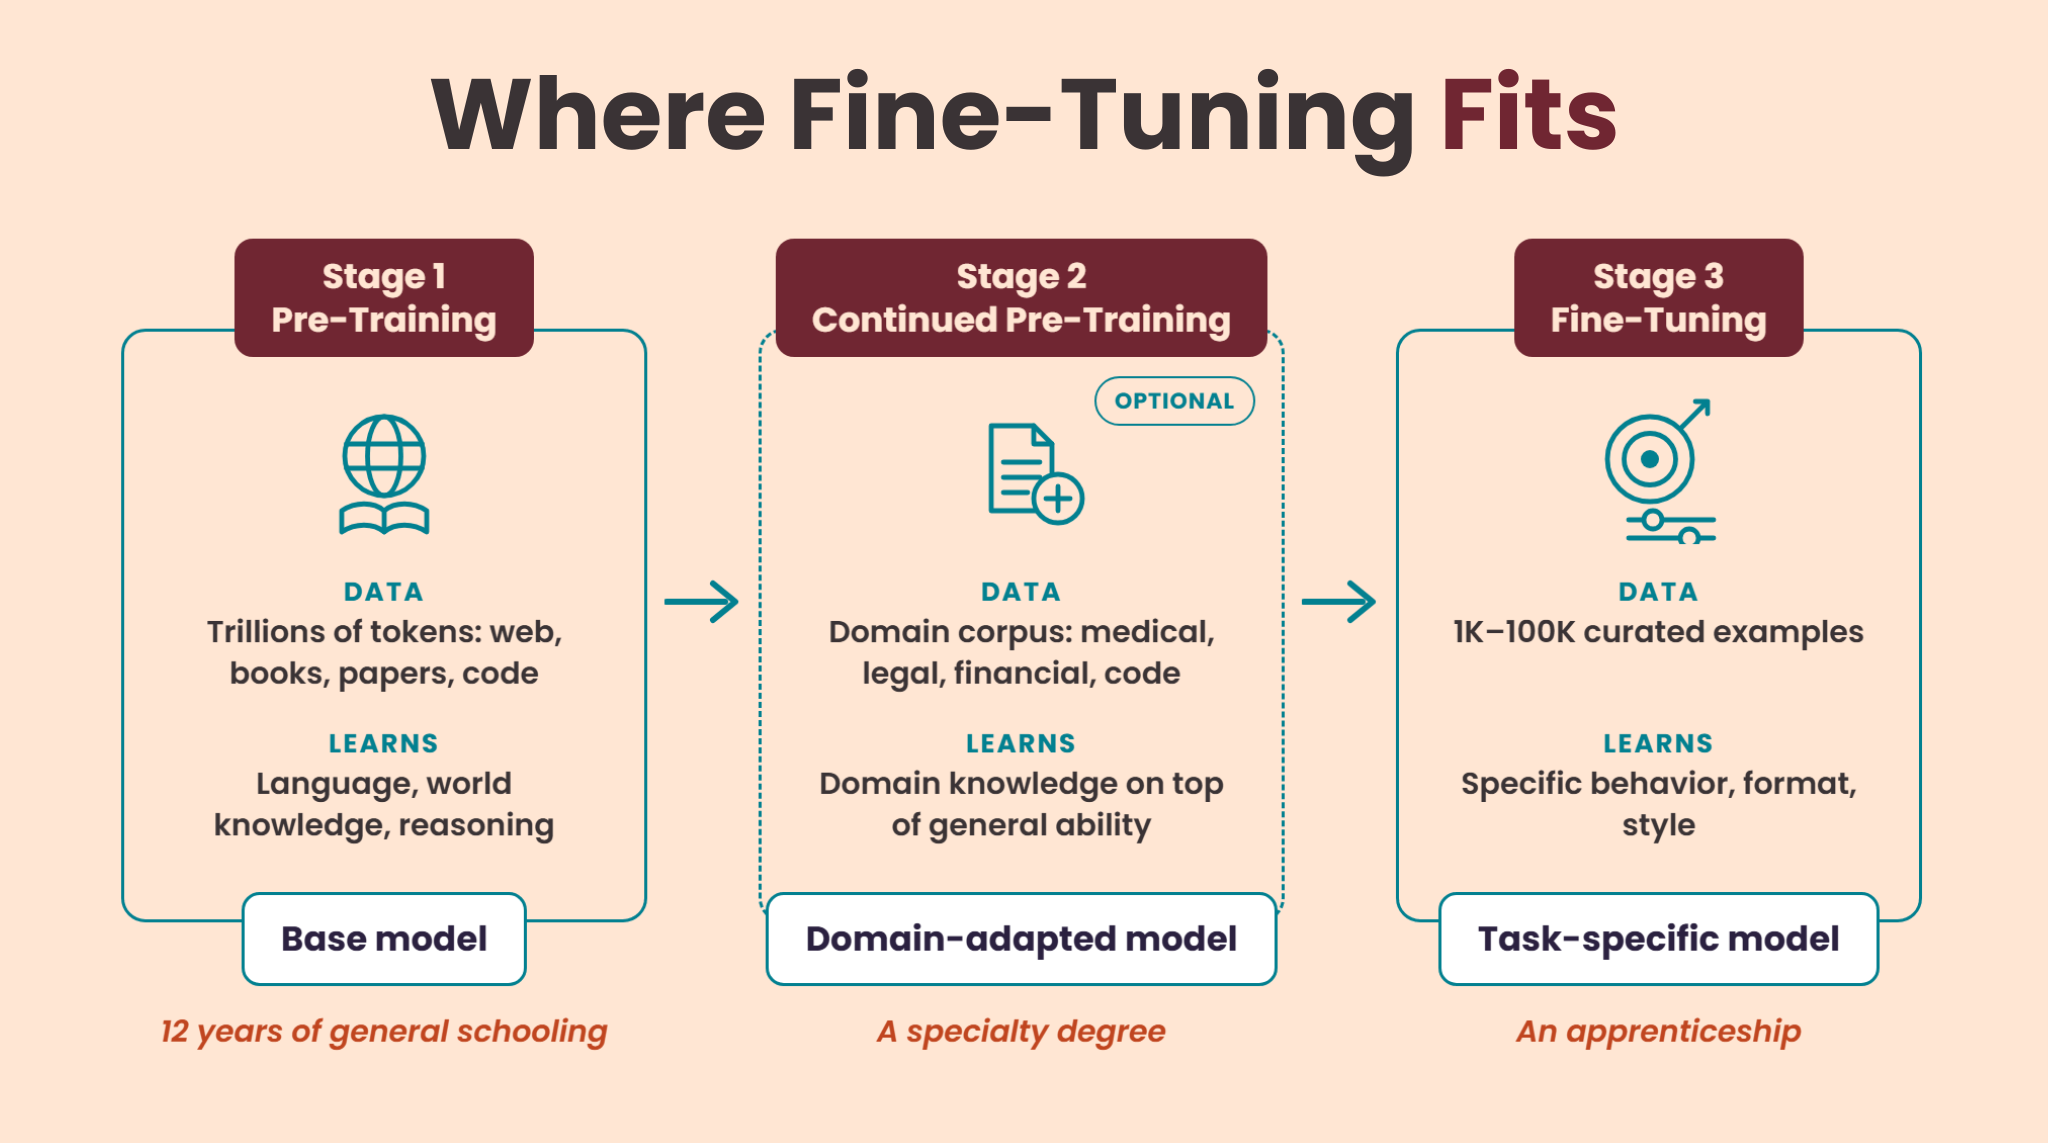
Think of it as three stages of education:
Pre-training is twelve years of general schooling: trillions of tokens, language, reasoning.
Continued Pre-Training (CPT) is a specialty degree: more training on a domain corpus when the base model needs it.
Fine-tuning is an apprenticeship: a curated dataset teaching the model exactly how to behave in your context.
Each stage builds on the previous one.
Here’s how to think about CPT & fine-tuning:
CPT is for knowing your domain: raw text at scale, absorbed into the weights.
Fine-tuning is for acting in your domain: labeled examples teaching specific task behavior, format & style.
CPT demands far more data & compute; fine-tuning is cheaper & faster.
Strong domain systems often sequence both.
Before you fine-tune, pick the right starting point…
Base model is a raw next-token predictor: it has read everything but held no job. Ask it a question, and it would continue writing the question.
Chat model (aka instruct) is a base plus supervised fine-tuning (SFT) and alignment. It knows how to respond, follow instructions & converse.
So start from base for full control; and start from chat to preserve instruction-following & specialize on top.
Chat models carry one piece of hidden structure: a chat template.
These models are built around a specific conversation format: control tokens marking the system, user, and assistant roles. The format varies by model family: Llama 3, Mistral, and Gemma each use different tokens.
Use the wrong template & the model loses track of who’s speaking…and responses degrade without warning7.
So how’s it actually done?…
Reminder: this is a teaser of the subscriber-only newsletter series, exclusive to my golden members.
When you upgrade, you’ll get:
Simple breakdown of real-world architectures
Frameworks you can plug into your work/business
Proven systems behind ChatGPT, Perplexity & Copilot
Ready for the best part?
此内容由惯性聚合(RSS阅读器)自动聚合整理,仅供阅读参考。 原文来自 — 版权归原作者所有。